Mastering FastAPI: A Complete Learning Roadmap

FastAPI is a powerful, modern Python web framework that leverages Python type hints and ASGI to build high-performance APIs. To truly master it, you need to understand not only the framework itself but also the ecosystem of tools, protocols, and deployment practices that surround it. Below is a comprehensive guide covering all the layers, concepts, and tools you’ll need to become proficient.

1. Core FastAPI & Python Fundamentals

Python (3.8+)

  • Type hints – essential for FastAPI’s data validation and editor support.
  • Async/await – understand how async def works and when to use it (I/O-bound operations).
  • Generators & context managers – used for dependencies and middleware.
  • Packaging – pip, venv, poetry, uv for dependency management.
  • FastAPI Core Concepts
  • Routing – @app.get(), @app.post(), etc.
  • Path & Query Parameters – validation, default values.
  • Request Body – Pydantic models, Form, File, UploadFile.
  • Dependency Injection – functions with Depends(), reusability, sub‑dependencies.
  • Response Models – response_model, status codes, custom responses.
  • Exception Handling – HTTPException, custom exception handlers.
  • Middleware – built-in (CORS, GZip) and custom ASGI middleware.
  • OpenAPI / Swagger – automatic docs at /docs and /redoc.

2. The ASGI Stack: Starlette & Uvicorn

  • FastAPI is built on top of Starlette (ASGI toolkit) and uses Pydantic for data.
  • Starlette
  • Low-level ASGI handling, routing, WebSocket support, background tasks, middleware.
  • Learn how Starlette’s Request and Response objects work; FastAPI extends them.
  • Uvicorn (or Hypercorn)
  • ASGI server that runs your FastAPI app.
  • Understand multi‑worker setups (–workers), reload for development, and how to run behind a reverse proxy.
  • ASGI Lifecycle
  • How HTTP requests, WebSocket connections, and lifespan events (startup, shutdown) work.

3. Data Validation & Serialization with Pydantic

  • Pydantic v2 – create models with BaseModel.
  • Validation – Field(), custom validators, model validators.
  • Settings management – BaseSettings (Pydantic‑settings) for environment variables.
  • Nested models, Union, Optional, List, Dict.
  • Performance – Pydantic v2 is written in Rust (pydantic‑core) – understand how to use it efficiently.

4. Databases & ORMs

  • SQL Databases
  • SQLAlchemy – the most common ORM.
  • Core: connections, sessions, models.
  • ORM: relationships, queries, migrations (Alembic).
  • Async SQLAlchemy (since 1.4) – use async_sessionmaker, select with await.
  • SQLModel – a library by the FastAPI creator that combines SQLAlchemy and Pydantic for a unified experience.
  • Alembic – database migrations.
  • Async drivers – asyncpg (PostgreSQL), aiosqlite, aiomysql.
  • NoSQL Databases
  • MongoDB – motor (async driver) for asynchronous operations.
  • Redis – redis-py with async support (aioredis integrated in redis 4.0+).
  • Elasticsearch, Cassandra, etc.
  • Best Practices
  • Dependency injection for database sessions (e.g., get_db).
  • Repository pattern to abstract database logic.

5. Authentication & Security

  • OAuth2 with Password (and JWT) – built‑in OAuth2PasswordBearer.
  • JWT – python-jose for encoding/decoding.
  • API Keys – custom header dependencies.
  • HTTP Basic – HTTPBasic from FastAPI’s security utilities.
  • Middlewares – CORS, trusted hosts, rate limiting (slowapi).
  • Hashing passwords – passlib[bcrypt].

6. Background Tasks & Job Scheduling

  • FastAPI’s BackgroundTasks – simple tasks that run after returning a response (e.g., send email).
  • Celery – distributed task queue for long‑running jobs (e.g., video processing).
  • Use celery with Redis/RabbitMQ, integrate with FastAPI.
  • APScheduler – lightweight in‑process scheduling (cron‑like jobs).
  • Sending emails – fastapi-mail, aiosmtplib, or integration with services like SendGrid.
  • Example: Schedule a daily report email via APScheduler or Celery beat.

7. Real‑Time & Streaming

  • WebSockets
  • FastAPI/Starlette’s native WebSocket support.
  • Manage connections, broadcast messages, rooms.
  • Server‑Sent Events (SSE)
  • Use sse-starlette or implement custom streaming responses.
  • Streaming Responses
  • StreamingResponse – for large files, video, or live data (e.g., from a database cursor).
  • gRPC
  • Run a gRPC server alongside FastAPI (separate process) or use grpc-gateway to expose gRPC via HTTP.
  • GraphQL
  • Strawberry – integrate GraphQL with FastAPI via GraphQLRouter.
  • Alternatives: Ariadne, Graphene.
  • Model Context Protocol (MCP)
  • Emerging standard for AI tool integration – can be exposed via FastAPI endpoints.
  • Webhooks
  • Implement webhook receivers (POST endpoints) and optionally verify signatures.

8. Middleware & Advanced HTTP Features

  • CORS – CORSMiddleware.
  • GZip – GZipMiddleware.
  • Custom ASGI middleware – e.g., request logging, timing.
  • TrustedHostMiddleware – security.
  • Session – SessionMiddleware (Starlette’s).

9. Testing

  • TestClient from fastapi.testclient (based on requests).
  • pytest – fixtures, async tests (use pytest-asyncio).
  • Database testing – rollback after tests, use separate test database.
  • Mock external services – httpx for mocking HTTP calls.

10. Deployment & Infrastructure

  • Docker
  • Write a Dockerfile with multi‑stage builds.
  • Use uvicorn with workers, or gunicorn + uvicorn.workers.UvicornWorker.
  • Container Orchestration
  • Kubernetes – understand pods, services, deployments, ConfigMaps, secrets.
  • Helm charts for templating.
  • CI/CD
  • Git – version control, branching strategies.
  • Jenkins – pipelines, building, testing, pushing Docker images.
  • GitHub Actions / GitLab CI – modern alternatives.
  • Cloud Platforms
  • AWS (ECS, Lambda with mangum), Google Cloud Run, Azure Functions, Heroku, Fly.io.
  • Reverse Proxies
  • Nginx, Traefik, Caddy – SSL termination, load balancing.

11. Additional Protocols & Integrations

  • REST – the native protocol of FastAPI.
  • GraphQL – add a GraphQL endpoint with Strawberry.
  • WebSockets – for real‑time bidirectional communication.
  • gRPC – high‑performance RPC.
  • MCP – Model Context Protocol (for AI agents).
  • Webhooks – handle incoming events from third‑party services.

12. Chatbots & Real‑Time Messaging

  • Telegram Bot – use python-telegram-bot (async) with webhooks or polling, integrate into FastAPI.
  • Slack Bot – Slack Events API with FastAPI webhooks.
  • Custom chat – build with WebSockets + FastAPI.

13. Advanced Topics

  • Dependency Injection deep dive – Depends() with callables, classes, yield for resource cleanup.
  • Middleware vs. dependency – when to use each.
  • Performance tuning – profiling, connection pooling, async vs. sync endpoints.
  • OpenAPI customization – openapi_extra, response_model_exclude_unset, etc.
  • Pagination – implement with limit/offset or cursor‑based.
  • Recommended Learning Path
  • Python basics – focus on type hints, async/await, context managers.
  • FastAPI official tutorial – build a simple CRUD API, understand core concepts.
  • Pydantic – work through validation and settings.
  • SQL databases – SQLAlchemy (async) and Alembic.
  • Authentication – implement JWT + OAuth2.
  • Background tasks – start with BackgroundTasks, then Celery.
  • WebSockets – build a simple chat.
  • Testing – write tests for all endpoints.
  • Docker & deployment – containerize your app, deploy to a cloud platform.
  • Advanced protocols – GraphQL, gRPC, streaming.
  • CI/CD – set up GitHub Actions or Jenkins pipelines.
  • Kubernetes – orchestrate your app for scaling.

Essential Tools & Libraries (Summary)

  1. Category Tools / Libraries
  2. Core FastAPI, Starlette, Pydantic, Uvicorn (or Hypercorn)
  3. Database SQLAlchemy, asyncpg, Alembic, SQLModel, Motor, Redis
  4. Auth python-jose, passlib, PyJWT
  5. Tasks Celery, Redis/RabbitMQ, APScheduler, fastapi-mail
  6. Testing pytest, httpx, pytest-asyncio, factory-boy
  7. Deployment Docker, Gunicorn, Kubernetes, Helm, Nginx, AWS, GCP, Azure
  8. CI/CD GitHub Actions, GitLab CI, Jenkins
  9. Protocols Strawberry (GraphQL), websockets (built-in), grpcio, sse-starlette
  10. Monitoring Prometheus (starlette-prometheus), OpenTelemetry, Sentry
  11. Chatbots python-telegram-bot, slack-sdk
  12. File Handling aiofiles, python-multipart

Mastering FastAPI is not just about the framework itself—it’s about becoming proficient in the entire stack that supports modern web applications.

Escaping API Quotas: How I Built a Local 14B Multi-Agent Squad for 16GB VRAM (Qwen3.5 & DeepSeek-R1)

Hand-drawn architecture diagram of HERA-CREW showing a Cloud AI IDE sending tasks to a local 16GB VRAM GPU. Three 14B agents collaborate, with an autonomous fallback routing back to the cloud via MCP.

I was building a complex web app prototype using a cloud-based AI IDE. Just as I was getting into the flow, I hit the dreaded wall: “429 Too Many Requests”.

I was done dealing with subscription anxiety and 6-day quota limits. I wanted to offload the heavy cognitive work to my local machine. But there was a catch: my rig runs on an AMD Radeon RX 6800 with 16GB of VRAM.

Here is how I bypassed the cloud limits and built a fully functional local multi-agent system without melting my GPU.

The “Goldilocks” Zone: Why 14B?

Running a multi-agent system locally is tricky when you have strict hardware limits. Through trial and error, I quickly realized:

  • 7B/8B models? They are fast, but too prone to hallucination when executing complex MCP (Model Context Protocol) tool calls or strict JSON outputs.
  • 32B+ models? Immediate Out Of Memory (OOM) on 16GB VRAM.

I found the absolute sweet spot: 14B models quantized (GGUF Q4/Q6) via Ollama. They are smart enough to reliably follow system prompts and handle agentic logic, while leaving just enough memory for a healthy context window.

Meet hera-crew: Hybrid Edge-cloud Resource Allocation

Hand-drawn architecture diagram of HERA-CREW showing a Cloud AI IDE sending tasks to a local 16GB VRAM GPU. Three 14B agents collaborate, with an autonomous fallback routing back to the cloud via MCP.

This constraint led me to build hera-crew, a local-first multi-agent framework. It’s not just about running models offline; it’s about intelligent, autonomous routing.

The Squad: DeepSeek-R1 & Qwen 3.5-Coder

To maximize efficiency, I assigned specific roles to different 14B models. A single model trying to do everything degrades quality, but a specialized squad works wonders:

  1. The Tech Lead / Coder (qwen3.5-coder:14b):
    Absolutely brilliant at writing Next.js/TypeScript and reliably executing tool calls. It acts as the core engine for generation.
  2. The Critic (deepseek-r1:14b):
    Takes its time to “think” and review the generated code. It flawlessly catches logic flaws and architectural mistakes that smaller models typically miss.

Pro-tip: Set num_ctx to 32768 (32k) in your Ollama config to keep the multi-agent debate from losing context during long sessions!

The Magic: Autonomous Fallback via MCP

The coolest feature of hera-crew is the autonomous fallback mechanism.

I gave the crew a highly complex task. Instead of just failing locally when the context gets too heavy or requires external data, the Critic agent evaluates the subtasks.

  • Standard logic and coding? -> Routed to LOCAL (Zero latency, zero cost).
  • Too complex or requires live infrastructure data? -> Routed to FALLBACK (Delegated back to the cloud IDE via an MCP tool).

It minimizes API costs, entirely eliminates the “friction of thinking,” and handles resource allocation autonomously.

Let’s Build Together

I’ve open-sourced the project on GitHub because I know I’m not the only one fighting the 16GB VRAM battle:

🔗 GitHub – ryohryp/hera-crew

I’m still refining the system prompts and trying to squeeze every drop of performance out of this setup.

Are any of you running similar 14B agent squads on 16GB setups? How do you manage the context lengths and tool-calling latency? I’d genuinely love to hear your thoughts, feedback, or PRs!

I Built a FusionAuth SDK in Brainfuck and I’m Not Even a Developer

This is an editorial, to see the full launch check out the official release here

I work in marketing at FusionAuth. I have no business compiling C to Brainfuck. This is the story of how I did it anyway, with an AI as my copilot, and what it taught me about the absurd state of the auth industry.

It started as an April Fools idea. I was looking at our SDK page — JavaScript, Python, Go, Java, C#, Ruby, PHP, the usual lineup — and I thought about how every auth vendor is in this arms race to support more languages. More frameworks. More runtimes. Okta has SDKs. Auth0 has SDKs. We have SDKs. Everybody has SDKs. There’s always one more language someone is asking for.

So I asked myself: what’s the logical endpoint of this? What’s the dumbest language we could build an SDK for?

Brainfuck. Obviously.

For the uninitiated: Brainfuck is a programming language with exactly eight instructions. > < + - . , [ ]. That’s it. It operates on a tape of memory cells. You can move the pointer, increment and decrement values, read a byte, write a byte, and loop. There are no variables. No functions. No strings. No numbers, really. It’s Turing-complete, which means you can compute anything with it, in the same way that you can drive a nail with your forehead.

I did not expect to actually build this.

The part where I opened Claude and said “let’s do something stupid”

I’m not a developer. I can read code, I can follow along, but I’m not writing a JSON parser from scratch in memory-constrained C. So I did what people are doing now — I vibecoded it. I opened Claude, explained the idea, and we started building.

The approach: you can’t realistically hand-write an auth SDK directly in Brainfuck. But there’s a project called ELVM (Esoteric Language Virtual Machine) by Shinichiro Hamaji that can compile a very restricted subset of C into Brainfuck. So the plan was: write the SDK in C, but a version of C so stripped down it might as well be from 1972, then compile it through ELVM’s pipeline into actual Brainfuck.

The pipeline looks like this:

fusionauth_bf.c → 8cc (ELVM's C compiler) → ELVM IR → elc → fusionauth.bf

Sounds straightforward. It was not.

Writing C like it’s 1972

ELVM’s C compiler, 8cc, supports a tiny subset of the language. Here’s what we couldn’t use: malloc, free, printf, sprintf, strlen, strcmp, strcpy, strcat, basically the entire standard library. Also no multiplication. Also no division. Those aren’t typos. ELVM’s Brainfuck backend literally does not have multiply or divide instructions.

So Claude and I wrote everything from scratch. A str_len function. A str_copy function. A str_eq function. A JSON builder that constructs request bodies one character at a time into a static buffer. A JSON parser — a full state machine that walks through response text character by character, tracks nesting depth, handles escape sequences, and extracts values by key name. All in about 1,200 lines of the most constrained C you’ve ever seen.

The division thing was fun. The SDK needs to convert HTTP status codes (integers) into strings for display. That means dividing by 10 to extract digits. With no division instruction available. The solution: a div10 function that subtracts 10 in a loop until you can’t anymore, counting how many times you went around. Same for modulo. It works. It’s not fast. We’ll come back to “not fast” later.

Multiplication was worse. Even though we removed all explicit * operators from our code, 8cc was still generating __builtin_mul calls — because array indexing internally requires multiplication. We had to provide our own implementation: a function that doubles and accumulates through bit-shifting with addition. Twenty-something lines of C to do what a single CPU instruction normally handles.

The wire protocol, or: how does Brainfuck talk HTTP?

Here’s the fundamental problem. The Brainfuck SDK needs to make HTTP requests to FusionAuth’s REST API. Brainfuck can do exactly two I/O operations: read a byte from stdin (,) and write a byte to stdout (.). That’s it. No sockets. No network. No HTTP library. No TLS. Nothing.

The solution is a Python runner script (runner.py) that acts as a bridge. The Brainfuck program writes an HTTP request to stdout in a simple text format — method, path, headers, body — terminated by a SOH byte (0x01). The runner reads this, makes the actual HTTP call to FusionAuth, and pipes the response back through stdin, also terminated by SOH. User commands come in prefixed with STX (0x02). Display messages go out wrapped in ETX (0x03).

It’s a protocol made of ASCII control characters from the 1960s being used to pipe modern OAuth2 authentication through a program written in a joke language from 1993. I love it.

The SDK supports LOGIN, REFRESH, GETUSER, REGISTER, and CREATEUSER. The actual FusionAuth API operations. With proper JSON request bodies, header management, and response parsing. Running inside Brainfuck.

The four hours I lost to a networking bug

This is the part of the story that still makes me twitchy.

We had the C code compiling. The native binary (compiled with regular gcc for testing) worked perfectly. Time to set up FusionAuth locally in Docker and test against a real instance.

FusionAuth spun up fine. Kickstart ran. The API key was created. Users were in the database. I could see everything in Postgres:

fusionauth=# SELECT * FROM authentication_keys;

Right there. The key exists. The permissions are set. Everything looks correct.

And every single API request returned 401 Unauthorized.

I tried different FusionAuth versions. 1.53.0. Then 1.63.0. I rewrote the kickstart configuration three times. I toggled between kickstart and the setup wizard. I compared the key_format column in the database between our key and the internal system key. I tried setting it to NULL. I even tried the official FusionAuth React quickstart example — also 401.

This went on for hours. Claude and I were going in circles. The API key was demonstrably in the database. The request was demonstrably sending the right Authorization header. 401.

Then on a hunch, I ran docker exec to curl from inside the FusionAuth container:

docker exec fusionauth-brainfuck-sdk-fusionauth-1 
  curl -s -o /dev/null -w "%{http_code}" 
  -H "Authorization: bf-sdk-test-api-key-do-not-use-in-production-0000" 
  http://localhost:9011/api/tenant

200.

I stared at my screen. From inside the container: 200. From my Mac through localhost: 401. Same URL. Same headers. Same API key.

Turns out OrbStack — the container runtime I use on my Apple Silicon Mac — has a quirk where its port forwarding can strip or mangle HTTP Authorization headers. The header was leaving my machine correctly and arriving at FusionAuth… without the auth part. Every debugging step we took was correct. The infrastructure between us and the container was silently eating our credentials.

The fix was beautifully stupid: instead of making HTTP requests normally, the runner shells out to docker exec curl to make every API call from inside the container’s network. We added a --docker-exec flag to runner.py. It works. It’s a hack that routes HTTP traffic through a subprocess that executes curl inside a Docker container to avoid a port-forwarding bug on Apple Silicon. This is the kind of thing that makes you question your career choices.

(If you’re on an M-series Mac using OrbStack and hitting mysterious 401s with correct credentials: this might be your problem. You’re welcome.)

Compiling to Brainfuck

With the networking sorted, it was time for the actual compilation. make bf. The command that turns 1,200 lines of C into Brainfuck.

The first attempt failed: undefined sym: __builtin_div. Right — no division. We added our div10 and mod10 functions.

Second attempt: undefined sym: __builtin_mul. Even after we’d removed every * operator. The array indexing thing. We added the manual multiply implementation.

Third attempt:

============================================
  Brainfuck SDK compiled!
  Output: fusionauth.bf
  Size:  14743291 bytes
  Lines:    30956
============================================

14.7 megabytes. Roughly 15 million characters of pure Brainfuck. The C source was about 1,200 lines, maybe 40KB. The compiled output is 14.7 megabytes. That’s a 350x increase in file size. Every if statement, every array access, every function call — expanded into chains of >>>>>>>>><<<++++[->>+<<]>>[-<<<+>>>] that go on for pages.

The file is larger than most JavaScript bundles. It is an authentication SDK. It does one thing. Very slowly.

Running it

python3 runner.py 
  --bf-interpreter ./elvm/out/bfopt 
  --bf-program fusionauth.bf 
  --url http://localhost:9011 
  --docker-exec fusionauth-brainfuck-sdk-fusionauth-1 -v

The REPL appeared almost immediately — bfopt (ELVM’s optimized Brainfuck interpreter) loaded the 15 million instructions into memory. Then I typed config bf-sdk-test-api-key-do-not-use-in-production-0000 and looked at Activity Monitor.

bfopt was at 99.8% CPU. One core, completely pegged, working through millions of Brainfuck instructions just to copy an API key string into a buffer. My MacBook fans spun up. The aluminum was warm to the touch.

This is what authentication looks like when your programming language can’t multiply.

The vibecoding angle

I want to be upfront about something: I could not have built this by myself. I’m not writing ELVM-compatible C from memory. I’m not implementing __builtin_mul with bit-doubling. I’m not designing wire protocols with ASCII control characters.

I described what I wanted to Claude, and we built it together over the course of a few sessions. Claude wrote the C code, the runner, the Makefile, the wire protocol design. I ran the commands on my machine, pasted back error output, made decisions about architecture, and spent a lot of time staring at 401 errors.

This is what vibecoding actually looks like when it’s pointed at something sufficiently unhinged. The AI writes the code. The human provides the chaos. Together you produce something that nobody asked for but that genuinely works.

Is it production quality? Absolutely not. Would I merge this into our real SDK repos? I already did. (I’m kidding. Mostly.) But the interesting thing is that it does work. The architecture is sound. The wire protocol is clean. The C code compiles with both gcc (for testing) and ELVM’s 8cc (for Brainfuck). It handles real FusionAuth API responses, parses real JSON, manages real JWTs.

A marketer and an AI built a working authentication SDK in Brainfuck. I don’t totally know what to do with that information, but I think it’s important.

The numbers, because developers like numbers

1,200 lines of C becomes 14.7 MB of Brainfuck. The compiled file contains roughly 15 million Brainfuck instructions. Division by 10 is implemented as a while loop that subtracts. Multiplication is implemented as repeated doubling with accumulation. All memory is statically allocated — 4KB buffers for request and response bodies, 2KB for tokens, 128 bytes for API keys. The ELVM architecture uses 24-bit words. The CPU utilization during execution is 100% of one core, sustained, for the duration.

I let it run for 28 hours on an M4 Pro MacBook. One hundred percent CPU, the entire time. It hadn’t finished initializing. It never produced a single byte of output. The native binary does the same thing in milliseconds. The Brainfuck version spent over a full day trying to zero out some static buffers and didn’t get there.

This is what authentication looks like at the theoretical limit of computation.

Should you use this?

No. God no.

But you could. That’s the point. The repo has a README, a Makefile, a docker-compose that spins up FusionAuth with kickstart, and exact instructions to reproduce the whole thing. make bf and you’ve got yourself a Brainfuck SDK.

The auth industry has been in an SDK arms race for years. Every vendor wants to support every language. JavaScript, Python, Go, Ruby, Rust, PHP, Kotlin, Swift, Dart, Flutter, React Native, Angular, Vue, Svelte, Next.js, Nuxt, Remix. The list grows every quarter.

We just added Brainfuck to ours.

Checkmate.

Check out the repo. PRs for Whitespace, INTERCAL, and Malbolge accepted. LOLCODE gets you a t-shirt.

Cumhurbaşkanlığı Siber Güvenlik Başkanı: “Eğer veri sizin değilse, karar da sizin değildir. Karar sizin değilse, gelecek de sizin değildir.”

Cumhurbaşkanlığı Siber Güvenlik Başkanı:

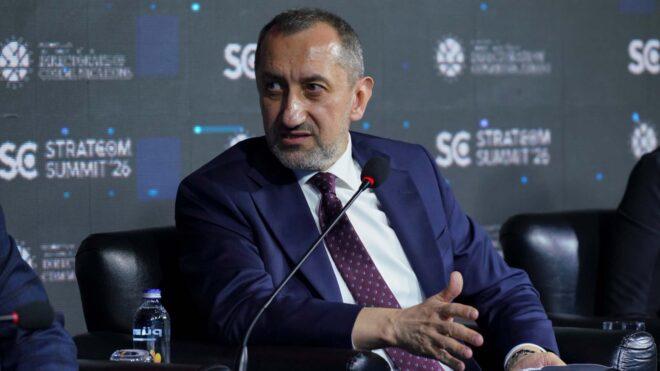
Cumhurbaşkanlığı Siber Güvenlik Başkanı: "Eğer veri sizin değilse, karar da sizin değildir. Karar sizin değilse, gelecek de sizin değildir."Türkiye Cumhuriyeti Cumhurbaşkanlığı Siber Güvenlik Başkanı Ümit Önal, katıldığı Uluslararası Stratejik İletişim Zirvesi Stratcom Summit 2026 kapsamında bir açıklama paylaştı. “Uluslararası Stratejik İletişim Zirvesi Stratcom Summit 2026’da şu gerçeklerin altını bir kez daha çizdik” diyen eski Türk Telekom CEO’su Önal, “Artık yeni bir çağdayız ve bu çağda egemenlik sadece ekonomiyle ya da silahlarla değil, veriyle ölçülüyor. Veriyi kim topluyor, kim işliyor, kim anlamlandırıyor? Eğer veri sizin değilse, karar da sizin değildir. Karar sizin değilse, gelecek de sizin değildir. Yapay zeka bu egemenlik mücadelesinde bir güç çarpanıdır, ama denetlenmeyen algoritmalar bir risktir. Çünkü artık tehditler görünmüyor ama etkileri çok yıkıcı. Yapay zekayla gerçek taklit edilebiliyor, algı yönlendirilebiliyor, güven saniyeler içinde yok edilebiliyor. Korunması gereken en kritik altyapılardan biri de insan zihni. Artık savaşlar sadece sahada değil, zihinlerde yürütülüyor. Dijital altyapıları korurken hakikat algısını ve toplumsal güveni de korumak; bunu yaparken de güvenlik ile özgürlük, hız ile etik, güç ile sorumluluk arasında […]
Cumhurbaşkanlığı Siber Güvenlik Başkanı: “Eğer veri sizin değilse, karar da sizin değildir. Karar sizin değilse, gelecek de sizin değildir.” yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Ulaştırma ve Altyapı Bakan Yardımcısı, “Roblox” yetkilileriyle bir araya geldi

Roblox

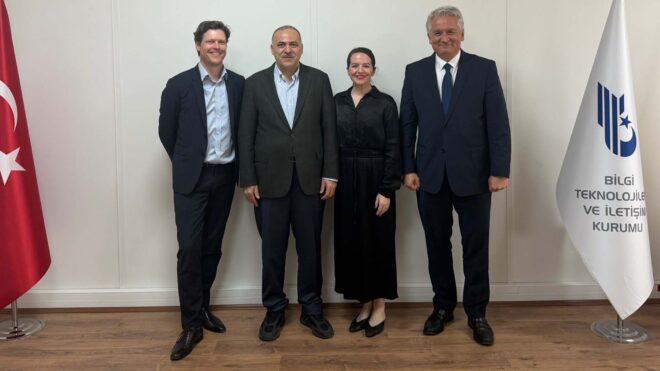
RobloxUlaştırma ve Altyapı Bakan Yardımcısı Ömer Fatih Sayan kişisel X hesabından bugün yaptığı açıklamada, Türkiye’de yasaklı “Roblox” platformunun yetkilileriyle bir araya geldiklerini söyledi. Sayan bu görüşmeye ilişkin paylaşımında, “Çocuklarımızın dijital ortamda güvenliği ve sağlıklı gelişimi en temel önceliğimiz. Bu kapsamda, Roblox yetkilileriyle bir araya gelerek kapsamlı bir değerlendirme toplantısı gerçekleştirdik. Görüşmede; ülkemizin dijital platformlara ilişkin düzenleyici çerçevesini, milletimizin hassasiyetlerini ve kullanıcı güvenliğine yönelik beklentilerimizi açık bir şekilde ifade ettik. Ülkemizde faaliyet gösteren tüm dijital platformların Türkiye’nin değerlerine ve hukukuna uygun şekilde hareket etmesini her şeyin üzerinde görüyoruz.” ifadelerini kullandı. İfade.org geçtiğimiz ay Türkiye’de “Roblox Turkey Teknolojik Destek ve Danışmanlık Hizmetleri Limited Şirketi” isimli bir şirketin kurulduğunu duyurmuş, 35 milyon TL sermayenin açıklandığı şirkete ABD’de ikamet eden Mark Llewellyn Reinstra’nın yetkili kılındığı belirtilmişti. Çocuklarımızın dijital ortamda güvenliği ve sağlıklı gelişimi en temel önceliğimiz. Bu kapsamda, Roblox yetkilileriyle bir araya gelerek kapsamlı bir değerlendirme toplantısı gerçekleştirdik. Görüşmede; ülkemizin dijital platformlara ilişkin düzenleyici […]

Ulaştırma ve Altyapı Bakan Yardımcısı, “Roblox” yetkilileriyle bir araya geldi yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Don’t Trust, Verify — Continuously: UltrafastSecp256k1 Meets Frigate

Introduction

Most cryptographic libraries rely on a simple model:

  • write code
  • get audited once
  • ship a PDF

But modern systems don’t stand still.

They evolve daily.

So I asked a different question:

What if audit was not a document, but a continuous process?

The Idea

UltrafastSecp256k1 was designed around two principles:

  • High-performance cryptographic execution (CPU + GPU)
  • Continuous, self-evolving audit system

Instead of relying on one-time audits, the system:

  • runs ~1M+ checks per audit
  • performs nightly differential validation
  • converts every discovered exploit into a permanent test
  • uses AI-assisted adversarial analysis
  • enforces correctness through CI

Security is not declared — it is continuously verified.

Real-World Adoption: Frigate

Recently, Sparrow Wallet’s Frigate integrated UltrafastSecp256k1 as its core compute layer.

Frigate is an experimental Silent Payments (BIP352) server that performs high-throughput blockchain scanning using DuckDB.

Instead of treating cryptography as a separate layer, Frigate embeds it directly into the database via a custom extension:

  • ufsecp.duckdb_extension
  • ufsecp_scan(…)

This extension is powered by UltrafastSecp256k1.

Performance in Practice

Independent benchmarks from Frigate show:

  • ~40 million operations/sec on 2 RTX 5090

This is not a synthetic benchmark —

it’s a real-world scanning pipeline.

Source:
https://github.com/sparrowwallet/frigate/blob/master/README.md

Why This Matters

This is not about “fastest library” claims.

This is about:

  • independent integration
  • real-world validation
  • reproducible performance
  • continuous verification

No contracts.

No paid audits.

No marketing.

Just:

clone → build → run → verify

Rethinking Audit

Traditional model:

  • audit = event
  • output = PDF
  • trust = assumption

This model:

  • audit = process
  • output = evidence
  • trust = reproducibility

Final Thought

If a system cannot be verified continuously,

it is only temporarily trusted.

UltrafastSecp256k1 is an attempt to change that.

Four Pagination Strategies for Enterprise Database Lists

Introduction

When implementing a paginated list screen in a business application, the first idea that comes to mind is usually “fetch rows with OFFSET/LIMIT.”

But once you actually run it, the problems pile up fast: “The same row appeared again on the next page,” “A record I saw earlier is gone,” “Page 1000 takes forever to load.” OFFSET/LIMIT alone can’t solve all of these.

I’ve been adding pagination support to a Java framework I’m building from scratch, which prompted me to revisit and organize the options. This article walks through four pagination strategies I’ve actually used in enterprise projects, along with their trade-offs.

What Pagination Needs to Get Right

Before diving in, let’s define what a solid pagination implementation should provide:

  • Correct data — no missing rows, no duplicates
  • Consistency — minimal interference from other users’ updates
  • Acceptable DB load
  • User-controlled sort order

Two phenomena are worth calling out specifically:

  • Row shift — When another user inserts or deletes a row between page loads, rows that should appear on the next page are skipped, or rows from the previous page appear again.
  • Stale read — The list keeps showing snapshot data from the initial query and doesn’t reflect updates made by other users during navigation.

Here’s an example of row shift. You’re viewing page 1 of 10 rows per page, then another user deletes ID:03:

                         Normal
--- When page 1 loads ---   →    --- When page 2 loads ---
ID: 01 (sort rank  1)             ID: 11 (sort rank 11)
ID: 02                            ID: 12
ID: 03                            ID: 13
    ...                               ...
ID: 10 (sort rank 10)             ID: 20

↓ Another user deletes ID:03 before page 2 loads:

--- When page 2 loads ---
ID: 12  ← ID:11 moved to page 1 due to the deletion; not shown on page 2
ID: 13
ID: 14
  ...
ID: 21

No single strategy perfectly satisfies every requirement — you’ll always be choosing a trade-off based on your project’s priorities.

When baking this into a framework, two additional constraints also matter:

  • Implementation transparency — simple enough to use without ceremony
  • DBMS portability — works across different database engines

Strategy 1: Per-Request DB Access — Row Number (OFFSET)

SELECT * FROM orders
ORDER BY id
LIMIT 10 OFFSET 20   -- page 3 (10 rows per page)

The simplest approach. Each page load tells the DB “give me M rows starting from row N.”

Drawbacks

  • DBMS-specific syntax. Oracle uses FETCH FIRST N ROWS ONLY, MySQL uses LIMIT ... OFFSET, SQL Server uses OFFSET ... FETCH NEXT, and so on.
  • High DB load at large offsets. The DB must scan and skip all rows before the offset — the further you page, the more work it does.
  • Row shift occurs due to concurrent insertions or deletions. (See the diagram above.)

Strategy 2: Per-Request DB Access — Application-Side Scrolling

Instead of delegating the offset to the DB, the application reads from the beginning of the ResultSet and skips rows itself until it reaches the desired page.

Java implementation sketch (JDBC):

try (PreparedStatement ps = con.prepareStatement("SELECT * FROM orders ORDER BY id");
     ResultSet rs = ps.executeQuery()) {

    // Skip the first N rows in the application
    for (int i = 0; i < n; i++) {
        if (!rs.next()) {
            break;  // No more data
        }
    }

    // Collect M rows and return
    ...
}

Like Strategy 1, this queries the DB on every page load. But because no OFFSET is sent to the DB, the same code works across any DBMS.

Drawbacks

  • App-side processing cost grows with page depth. Viewing page 100 means skipping 990 rows in the application.
  • Row shift happens in the same way as Strategy 1.

Variation: Key-based cursor
If you store the last row’s key value from the previous page and filter with WHERE id > :lastId, you can reduce the number of skipped rows and also mitigate row shift. The downside: changing sort order or jumping directly to an arbitrary page becomes difficult, and it’s hard to encapsulate inside a framework.

Strategies 1 and 2 are in the “query the DB on every request” group. Strategies 3 and 4 belong to a different group: “query the DB once, then cache the result.”

Strategy 3: Single DB Query — Work File Cache

On the first search, fetch all matching rows from the DB and write them to a file. Subsequent page loads read from that file.

[First load]  DB → fetch all rows → write to file → display page 1
[Later loads] read from file → display page N

Benefits

  • No DB access after the first load — low DB load for navigation
  • Consistency is guaranteed during navigation (no row shift)

Drawbacks

  • Stale reads occur. The list shows a snapshot from the initial query; updates by other users are not reflected during navigation.
  • Multi-server deployments are problematic. Files written on one web server aren’t visible on others — shared or object storage is needed.
  • When do you delete the files? You need a cleanup strategy: on session end, on logout, after a timeout, etc.
  • Files multiply quickly. Each concurrent user creates their own file.
  • Large first-load queries can be heavy on memory and I/O (capping the result size helps).

Strategy 4: Single DB Query — Work Table Cache

On the first search, fetch all matching rows and INSERT them into a dedicated work table. Subsequent page loads SELECT from that table.

[First load]  DB → fetch all rows → INSERT into work table → SELECT from work table → display page 1
[Later loads] SELECT from work table → display page N

This is Strategy 3 with files replaced by a database table. The mechanics are essentially the same.

Benefits

  • Same consistency guarantee as Strategy 3 — no row shift
  • Works fine in multi-server setups. No need to worry about where files land.
  • Pagination is just INSERT + SELECT
  • Row numbers can be assigned at INSERT time, making direct page jumps straightforward

Drawbacks

  • Stale reads occur, just like Strategy 3.
  • When do you purge the work table? A periodic cleanup job or session-lifecycle integration is required.
  • Heavy concurrent usage bloats the work table. Each active user adds their own rows.
  • Each search type needs its own work table schema.

Comparison Summary

Per-Request DB Access (Strategies 1 & 2)

Other users’ updates are reflected in real time (no stale reads), but row shift can occur.

Strategy 1: OFFSET Strategy 2: App-side scrolling
Load location DB (OFFSET scan) App (skip loop)
DBMS portability Syntax varies by DBMS Works with any DBMS
Row shift Yes Yes
Stale read No No

Single DB Query + Cache (Strategies 3 & 4)

The snapshot from the first query is preserved, so no row shift. But stale reads do occur.

Strategy 3: Work file Strategy 4: Work table
Pagination mechanism File I/O INSERT / SELECT
Multi-server support Needs shared storage No issue
Cleanup design needed Yes Yes
Row shift No No
Stale read Yes Yes

Which Strategy Fits Which Situation?

Situation Recommended Strategy
Rarely updated reference data (master lists, etc.) Strategy 1 (OFFSET) — simplest option
Workflows where minor row shift is acceptable Strategy 1 or 2
DBMS without OFFSET support, or DBMS-agnostic requirement Strategy 2 (app-side scrolling)
Consistency is critical (approval flows, reports, etc.) Strategy 3 or 4
Multi-server deployment Strategy 4 (work table)

Work file and work table strategies win on consistency, but the cleanup design adds non-trivial operational complexity.

Wrapping Up

That’s a rundown of four pagination strategies. There’s no universally “correct” answer — the right choice depends on your project’s characteristics.

For my own framework, DBMS portability is a priority, so I’m leaning toward Strategy 2 (app-side scrolling) as the base implementation. But honestly, I’m still mulling it over. If you’ve handled pagination in a real project — or know of an approach I missed — I’d love to hear about it in the comments!

SIcore Framework Links

My custom framework is published here.

Related Articles

Check out the other articles in this series!

Thank you for reading!
I’d appreciate it if you could give it a ❤️!

I built a programming language at 15 — and it’s already fully usable.

I’m a 15 year old developer and I’ve been working on a programming language called Kern.

The goal wasn’t to create something “revolutionary” or overly complex. Instead, I wanted to build something that focuses on:

Simplicity
Readability
Control
Learning how programming languages work

Kern is still evolving, but it’s already functional and usable.

  • What is Kern?

Kern is a lightweight, experimental programming language designed to keep things minimal and clear.

It aims to:

Reduce unnecessary complexity
Make behavior predictable
Provide a clean foundation for experimentation

It’s especially useful for:

Learning language design
Building small tools
Understanding how interpreters/compilers work

  • Example

Here’s a simple example of Kern in action:

// import the datatools module
datatools = import("datatools")

// parse JSON into a usable object
j = datatools.json_parse("{"x": 1, "y": 2}")

// convert a table/object into a TOML string
t = datatools.toml_stringify({a: 1})

// parse CSV into rows
rows = datatools.csv_parse("a,bn1,2n")

// basic checks and outputs
print("json has x:", has(j, "x"))
print("toml len > 0:", len(t) > 0)
print("csv rows:", len(rows))
  • Why I Built It

I built Kern because I wanted:

More control over how a language behaves
A better understanding of compilers and runtimes
A language that doesn’t hide too much behind abstractions

Most modern languages are powerful—but also complex. Kern tries to take a different approach by focusing on clarity first.

  • Current State

Kern is still:

under development
experimental in some areas
evolving over time

There may be:

bugs
missing features
things that change

But that’s part of the process.

This is just the beginning of Kern.

I’m continuing to improve it, fix issues, and expand what it can do. If you’re interested in programming languages, compilers, or experimental projects, I’d love for you to take a look.

I’d really appreciate feedback on:

design choices
syntax
overall concept
anything that could be improved

If you’re interested, you can check it out here: https://github.com/entrenchedosx/kern.git

JADE: NEW ON JADE ? Create your FIRST agent while using your cmd PART 2.

level : Noob/New
Version : Windows 10
language : java 17.0.10 (jade Framework 4.6.0)

CREATING MY FIRST AGENT:

So, if you’re new to the world of Multi-Agent Systems (MAS), we’ve got you. In this article, we’re going to take it step-by-step—and I mean CLEAR steps. Ugh, I know the struggle of doing something for the first time: repeating the same lines of code, scrolling through Google, jumping to ChatGPT… only to end up in what we call ‘Event Spaghetti.’ Tons of info, but none of it actually works (or at least not the way it should). It’s draining, and as developers, we’ve all been there.

GET TO THE POINT NOW, lets follow these steps one by one :

1: Open File Explorer on your computer.
2: In the address bar, go to the folder where your jade-bin-[version] is located.
3: Click on it
4: You’ll see “lib folder” and normally in it you’ll find jade (jar extension).
5: back to the jade folder.
6: Create a folder called “src” if it’s not already there.
7: Click on it.
8: Create another folder dedicated for the package, name it whatever you want in our case “Modeles”.
9: Click on it.
10: Create a .txt file and name it whatever you want this one is dedicated to your class.
11: Now, this is where things start to get interesting: head over to your CMD.
12: HIT

cd c:ToolsJADE-bin-4.6.0jadesrcmodeles

13: the path will change to this one
14: Remember, we created the class with a .txt extension earlier. Don’t forget to change it to .java in your CMD now, so it’s ready to go!

ren NameOfYourClass.txt NameOfYourClass.java

15: To make sure your class extension matches exactly what we need:

dir 

You should see the contents of your current folder. Check the extensions if everything went well, you’ll see your file there: NameOfYourClass.java.

16: Now, before doing anything else go back to your NameOfYourClass.java and lets start writing a small code, simple one for the test:

package modeles;
import jade.core.Agent;

plublic class NameOfYourClass extends Agent{
   protected void setup(){
      System.out.println("hi! My name is " + getLocalName());
                         }
}

17: Once evrything is setup, you need to compile your java class:

cd .. 
javac -cp "..libjade.jar" modelesNameOFYourClass.java

18: Once the compiling is done and a new command line appears, you’re ready to create your first agents in the Main Container (the ‘brain’ of the platform). Since agents are all about being dynamic, you’ll need to open another CMD window in parallel to host your simple container (second container in our case).

19: in your current CMD window, you’ll create your first agents in the “mainContainer”:

cd .. 
java -cp "libjade.jar;src" jade.Boot -gui -agents "NameOfYourAgent:modeles.NameOfYourClass"

To create a bunch of them (3 agents in our case), use a ‘;’ between each agent to separate them and avoid errors:

java -cp "libjade.jar;src" jade.Boot -gui -agents "Agent1:modeles.NameOfYouClass;Agent2:modeles.NameOfYouClass;Agent3:modeles.NameOfYouClass"

Now, HIT Enter. You should see the messages from your agents popping up in the CMD window (the ones we wrote earlier in the class, like ‘Hi, my name is agent1…). At the same time, the JADE RMA GUI (Remote Monitoring Agent) will appear.
Click on the ‘AgentPlatform’ folder, then on the key icon, and follow the hierarchy until you see your 3 agents sitting right next to the 3 main ones (df, ams, and rma).

20: Now, let’s head over to the next CMD window so we can create another simple container to hold our new agents:

cd c:ToolsJADE-bin-4.6.0jade 
java -cp "libjade.jar;src" jade.Boot -gui -container "Agent4:modeles.YourClassName"

Hit Enter and you’ll see a message from your agent! Check the GUI and you’ll see a new container popping up—that’s your second one, holding your 4th agent. CONGRATS, YOU MADE IT!

NOTE: Once you close your CMD windows, the GUI is gone too. If you want to jump back in, just pick your class and repeat steps 19 and 20, just make sure you’re in the right path!:

cd c:ToolsJADE-bin-4.6.0jade  

Now, you’re an expert at creating agents right from your CMD. HAVE FUN with your exam!

jade.Boot: the main class to start JADE.
-gui: opens the main jade GUI , including the rma (Remote Monitoring Agent).
-cp: class Path (tells where libraries are).

Chapter 6. Best Practices for Working with an AI Agent

1.1 Why Clear Instructions Matter

An AI Agent “reasons” — but it also “guesses”

When an instruction is vague, an AI Agent fills in the gaps itself and proceeds with the task.
A person would ask “how should I handle this?” — but an AI Agent decides on the most plausible interpretation and executes it.

This is both its strength and its risk.

[Vague instruction]
> Build a login feature

[AI Agent's interpretation — the user has no idea]
  • Framework? → assumes React + Express
  • Authentication? → assumes JWT
  • DB? → assumes SQLite
  • Password encryption? → assumes bcrypt
  • Social login? → assumes none

→ Result: works, but built on a tech stack you didn't intend
[Clear instruction]
> Build a login API using NestJS + Passport.js.
> - Auth: JWT-based, with refresh token
> - DB: PostgreSQL + Prisma
> - Password: argon2 hashing
> - Social login excluded from this stage

→ Result: built exactly as intended

“Make it good” is not an instruction

Telling an AI Agent to “do it well,” “do it appropriately,” or “figure it out” provides zero actionable information.

Vague instruction Problem Clear instruction
“Make an API” Stack, structure, and auth are all guessed “NestJS REST API, JWT auth, Prisma ORM”
“Add tests” Scope and framework are unclear “Write unit tests for UserService using Jest”
“Fix this” What the problem is is unclear “Return 409 instead of 500 on duplicate email at POST /users”
“Improve performance” What and by how much? “getUsers query takes 3 seconds. Check for N+1 and bring it under 1 second”
“Refactor this” No criteria “Split the auth module into 3 layers: controller/service/repository”

Real problems that vague instructions create

1. Rollback cost

If an AI Agent modifies dozens of files in the wrong direction and you say “that’s not right,” rolling back takes more time than the original task. One line of clear instruction saves 30 minutes of cleanup.

2. Wasted context

When an AI Agent reads unnecessary files to figure out what direction to take, the context window is consumed. If half of the 200K tokens are spent “getting oriented,” there’s not enough space left to do the actual implementation.

3. Compounding errors

If the first instruction is vague, every subsequent task builds on the wrong premise. If you discover the problem three steps later, you have to start over from step one.

7 Elements of a Good Instruction

Element Description Example
Why The purpose and intent behind the task “We’re improving the profile-editing UX to reduce user churn”
What What is to be done “Implement a user profile update API”
How What technology or approach to use “NestJS, Prisma, class-validator”
Scope Boundaries of the task “Email and nickname only. Exclude password changes”
Reference Materials to consult or investigate “See Prisma docs at prisma.io/docs”, “Refer to src/auth/README.md”
Constraint Restrictions that must be respected “Existing tests must not break”
Verify How to confirm it’s done “Pass npm test + manually test PUT /users/:id”

Why “Why” matters

Without knowing the purpose, an AI Agent will produce code that “works” technically but may not align with business intent. When the AI Agent knows the purpose and intent, it has a better chance of reasoning in the right direction when faced with ambiguous judgment calls.

Without Why With Why
“Build a profile update API” → mechanical CRUD implementation “Improving UX to reduce churn” → input validation made user-friendly, error messages written from the user’s perspective
Implemented with defaults, no guiding criteria Decisions made to serve the purpose (prioritize response speed, detailed error messages, etc.)

Why “Reference” matters

An AI Agent responds based on its training data, which may differ from the latest versions or project-specific conventions.
Providing references means the work is grounded in evidence rather than guesswork.

Situation Reference instruction example
Latest API usage “Implement this by referring to https://docs.nestjs.com/security/authentication“
Based on internal docs “Follow the conventions in docs/api-convention.md”
Following existing code patterns “Use the same structure as src/auth/auth.service.ts”
External library “Read the README at https://github.com/oraios/serena and configure accordingly”
Design system “Implement the component by referencing the Figma link”

💡 Claude Code can search the web and read files directly —
give it a URL and it will look it up; give it a file path and it will read it.
“Check here” produces far more accurate results than “figure it out yourself.”

Not every instruction needs all 7 elements.
But making a habit of always including Why, What, and Scope — and adding Reference whenever the latest technology or project-specific conventions are involved — makes a meaningful difference.

Practical Pattern: Step-by-Step Instructions

For complex tasks, break them into stages rather than issuing everything at once.

# ❌ Everything at once
> Build a user management system. Include registration, login,
> profile editing, permission management, and email verification.

# ✅ Step by step
> [Step 1] First, design the DB schema for the user management system.
>   - User, Role, Permission tables
>   - Written as a Prisma schema
>   → Review, then proceed to the next step

> [Step 2] Implement the User CRUD API in NestJS.
>   - POST /users (registration)
>   - GET /users/:id (profile lookup)
>   - Input validation with class-validator
>   → Confirm tests pass before the next step

> [Step 3] Add JWT authentication.
>   - Passport.js + JWT Strategy
>   - Access token: 15 min, refresh token: 7 days
>   → Verify that existing tests still pass

Using Plan Mode

Claude Code’s Plan Mode lets you have the AI Agent plan first and then proceed only after your approval.

# Enter Plan Mode
> /plan

# Or include it in the instruction
> Plan the migration of the auth system to OAuth2 first.
> Don't execute yet — just show me the plan. I'll approve before we proceed.

In Plan Mode, a Sub Agent (Plan) analyzes the codebase and presents a plan.
Reviewing and refining the plan before approving execution reduces the risk of heading in the wrong direction.

1.2 Instruction Checklist

Before giving a work instruction, quickly run through the following.

□ Is the purpose and intent stated? (Why)
□ Is it clear what is to be done? (What)
□ Is the scope defined? (Scope) — is there an "exclude X"?
□ Is the tech stack / approach specified? (How)
□ Are reference materials provided? (Reference) — URLs, file paths
□ Is there a completion criterion? (Verify) — tests, commands, expected result
□ Is this asking for too much at once?

1.3 Save and Update Outputs as Files

An AI Agent does not physically preserve memory

Decisions made during an AI Agent conversation — design directions, architecture choices, API specs, and so on — exist only within the session’s context window. Think of it like RAM: when the session ends, it’s gone.

[During the session]
  User: "Let's use JWT for auth"
  AI Agent: "Got it, proceeding with JWT"
  User: "PostgreSQL for the DB"
  AI Agent: "Understood, designing with PostgreSQL"
  ... (10 decisions over an hour)

[Session ends — terminal accidentally closed]
  → All 10 decisions lost
  → Must explain everything from scratch in a new session

Problems this causes in practice

Situation Outcome
Terminal accidentally closed All decisions made so far are lost
Auto-compaction (/compact) Earlier decisions may be dropped during summarization
Continuing the next day New session — no prior context
Handing off to a teammate Hard to reconstruct the decision-making process from chat history alone

The solution — save decisions to files immediately

Decisions made during a work session should be written to physical files as they happen.
Files persist after the session ends, so you can pick up wherever you left off at any time.

Instruction example ①: During planning

> We're going to plan out the user authentication system.
> Update the decisions to ./todo/Plan_Draft_Auth_System.md as they're made.
> Ask me for approval before making any updates.

Instruction example ②: During design

> Design the API spec.
> Reflect decisions in ./docs/API_Spec_v1.md.
> Update the file whenever something changes, and get confirmation before each update.

Instruction example ③: For long-running work

> This refactoring will span multiple sessions.
> Track progress in ./PROGRESS.md.
> - Completed items: ✅
> - In progress: 🔄
> - Not started: ⬜
> Update this file at the end of each work segment.

Recommended File Structure

my-project/
├── todo/                              ← Plans and decision records
│   ├── Plan_Draft_Auth_System.md
│   ├── Plan_Draft_DB_Migration.md
│   └── Decision_Log.md               ← Key decisions and their rationale
├── docs/                              ← Output documents
│   ├── API_Spec_v1.md
│   └── Architecture_Overview.md
├── PROGRESS.md                        ← Overall progress status
└── CLAUDE.md                          ← Project context

3 Core Principles for Saving Files

Principle Description Instruction example
Save immediately Reflect decisions in the file as soon as they’re made “Update the file each time something is decided”
Approve before applying Confirm before changing files “Ask for my approval before updating”
Specify the path State exactly where to save “Save to ./todo/Plan_Draft_Title.md”

⚠️ Key point: Telling an AI Agent to “remember this” is far less reliable than saying “save it to a file.”
Memory in a conversation disappears when the session ends — files persist permanently.

1.4 Starting and Ending Work — Context Management Procedure

When starting a new task

Even within a single session, tasks change multiple times.
When switching tasks — say from “DB design → API implementation → writing tests” — if you don’t clear out the previous task’s context, the AI Agent gets buried under previously read files and conversation history, which degrades accuracy on the new task.

Switching tasks within the same session is the primary application of this procedure.
It applies equally when you close a session and open a fresh one.

STEP 1. Define the task overview and the AI Agent’s role

In the first instruction of a new task, clearly declare “what will be done” and “what role the AI Agent plays.”

> We're going to design the user authentication system now.
> Your role is backend architect.
> Design using NestJS + Passport.js,
> and record decisions in ./todo/Plan_Draft_Auth.md.

STEP 2. Remove or compact unnecessary context

Leftover context from a previous task can interfere with the new one.

Situation Action Command
Completely new task unrelated to previous work Full context reset /clear
New task partially related to previous work Direct instruction for selective compaction /compact keep only auth-related decisions
Low-stakes simple task switch Stating the new task overview and role in STEP 1 guides auto-compaction appropriately (no additional action needed after STEP 1)

⚠️ Claude’s auto-compact doesn’t know what’s important.
For important work, use /compact <what to preserve> to control it directly.
Trust auto-compact only for low-stakes tasks.

STEP 3. When continuing from previous work — restoring context

When you need to pick up from where a prior task left off, restore context using the saved output files.
This applies both when continuing within the same session after a /clear, and when resuming previous work in a new session.

> We were working on the authentication system design in the previous session.
> Read the following files and get up to speed:
> - ./todo/Plan_Draft_Auth.md (design plan)
> - ./PROGRESS.md (progress status)
> - ./docs/API_Spec_v1.md (API spec)
>
> Summarize what you've learned,
> and tell me what we should pick up next.

The key here is to explicitly instruct what to keep and what to discard.

> Once you've read the previous work files:
> - The DB schema design is finalized — you can drop it from context
> - The JWT token design is still undecided — keep that
> - Use the "Outstanding Items" section of ./todo/Plan_Draft_Auth.md as the goals for this session

Task Start Instruction Template

> [Task overview] (what is being done)
> [AI role] (what kind of expert to act as)
> [Reference files] (previous outputs, context to restore)
> [Context cleanup] (what to keep / what to remove)
> [Output storage] (path, filename, approval process)

When a task ends (on session close or extended break)

This is the supplementary procedure for when you close a session or wrap up for the day and plan to continue tomorrow.
For task switches within the same session, STEP 1–3 above are sufficient —
but when you’re ending the session itself, complete the steps below so the next session can pick up seamlessly.

STEP 1. Preserve outputs as records

> Wrap up today's work:
> - Completed code is already committed (confirmed)
> - Add design decisions to ./todo/Decision_Log.md
> - Update ./PROGRESS.md with the current status

STEP 2. Update reference materials

Update the reference materials the AI Agent will read in the next session to reflect the current state.
Without this step, the next session’s AI Agent will read outdated materials and work from stale assumptions.

> Update the following files to reflect today's changes:
> - ./docs/API_Spec_v1.md → include newly added endpoints
> - ./CLAUDE.md → reflect updated architecture information
> - ./todo/Plan_Draft_Auth.md → check off completed items, update outstanding items
> Get approval before making changes.

⚠️ If reference materials are left in a past state, the next session’s AI Agent will work without knowing what has already changed.
This is the primary cause of the “I already fixed that, but it went back to the original” problem.

STEP 3. Record TODOs — handoff for the next session

Explicitly document what’s left to do so that the next session (or another person) can pick up right away.

> Record the work to continue in the next session in ./todo/TODO_Next.md:
> - Remaining tasks (in priority order)
> - Prerequisites for each task
> - File paths to reference
> - Caveats or unresolved issues

TODO file example

# TODO — Next Session Work List

## Priority 1: Refresh Token Implementation
- Prerequisite: Access token issuance complete (✅)
- Reference: ./docs/API_Spec_v1.md > POST /auth/refresh
- Note: Token expiry confirmed at 7 days (Decision_Log.md #12)

## Priority 2: Social Login (Google OAuth)
- Prerequisite: After Refresh Token is complete
- Reference: https://docs.nestjs.com/security/authentication#oauth2
- Unresolved: Callback URL domain not yet confirmed (needs team lead sign-off)

## Notes
- No direct commits to main — use feature/auth-* branches
- All 186 existing tests must pass

Task Start/End Checklist

[Starting a task]
□ Declared the task overview and AI Agent's role?
□ Cleared previous context? (/clear or /compact)
□ For continuing work: instructed the AI Agent to read previous output files?
□ Explicitly specified what context to keep and what to remove?
□ Specified the output save path and approval process?

[Ending a task]
□ Outputs preserved as files? (code committed, documents saved)
□ Reference materials updated to reflect the current state? (API spec, CLAUDE.md, etc.)
□ TODOs recorded for the next session? (remaining tasks, prerequisites, unresolved issues)

1.5 Instruction Checklist (Comprehensive)

Before giving a work instruction, quickly run through the following.

□ Is the purpose and intent stated? (Why) — why is this task being done?
□ Is it clear what is to be done? (What)
□ Is the scope defined? (Scope) — is there an "exclude X"?
□ Is the tech stack / approach specified? (How)
□ Are reference materials provided? (Reference) — URLs, file paths
□ Is there a completion criterion? (Verify) — tests, commands, expected result
□ Is this asking for too much at once?
□ Was the AI Agent asked to save outputs to a file? — path, filename, approval process
□ Were reference material updates and TODO recording instructed for when the task ends?