How to Stop LLM Hallucinations from Crashing Your React UI (Fixing AI_JSONParseError)

Building Generative UIs with tools like the Vercel AI SDK is incredibly powerful until it suddenly isn’t.

ou’ve set up your tool calls, your streaming is incredibly fast, and it works flawlessly 99% of the time. But LLMs are inherently non-deterministic. Eventually, the model will drop a quote mark in the middle of a JSON stream, or decide to wrap its raw output inside a markdown block (json).

When that happens, your application doesn’t just show a typo. It throws a synchronous parsing error. And in React, an unhandled error means one thing: The White Screen of Death (WSOD).

If you look at the Vercel AI SDK GitHub repository, you’ll see developers fighting this in the trenches:

  • Issue #13514: Tool streaming causes malformed JSON.

  • Issue #4906: The LLM randomly outputs Markdown blocks instead of pure objects, crashing the preflight parsing.

  • Issue #1167: RSC stream aborts completely unmount the React tree.

Let’s look at why standard React tools fail here, and how to elegantly quarantine these hallucinations.

The Trap of Standard Error Boundaries

When a standard React component throws an error, the official advice is to wrap it in an <ErrorBoundary>. But Generative UI is different.

If you are building an AI Chat interface, the tool component (let’s say, a financial chart generated by the LLM) is a child of the message list. If the LLM hallucinates the schema (e.g., returns a string instead of an array) and your chart component tries to .map() over it, it crashes.

If you rely on a generic Error Boundary higher up in your tree, React unmounts the entire chat history to show the fallback UI. Your user just lost their entire 20-minute context because the AI forgot a comma. That is unacceptable UX.

The Ugly Fix

To prevent this, developers end up writing massive, defensive try/catch blocks inside every single component, or attempting to write regex-based “JSON cleaners” to sanitize strings mid-stream. It pollutes your codebase with error-handling logic that obscures the actual business logic.

The Elegant Fix: Quarantining Generative UI

We need a surgical approach: a boundary specifically designed for the unpredictable nature of AI payloads. That’s why I built <AIBoundary /> as part of the CogniCatch open-source library.

Instead of generic error handling, AIBoundary creates an isolated quarantine zone around your GenUI components. If the LLM hallucinates or spits out malformed JSON, the boundary intercepts the crash, keeps the rest of the application (like the chat history) perfectly intact, and gracefully handles the failure in-place.

How to use it

First, install the package:

npm install @cognicatch/react

Then, simply wrap the component responsible for rendering the LLM’s output:

import { AIBoundary } from '@cognicatch/react';
import { FinancialChart } from './components/FinancialChart';

export function ChatMessage({ toolInvocation }) {
  // If toolInvocation.args comes back malformed,
  // FinancialChart will crash. AIBoundary protects the app.

  return (
    <AIBoundary
      mode="manual"
      showRawData={true} 
      rawPayload={toolInvocation.args} 
      onRecover={() => triggerRetryInChatStream()}
    >
      <FinancialChart data={toolInvocation.args} />
    </AIBoundary>
  );
}

What happens under the hood?

  1. Isolation: If FinancialChart throws TypeError: undefined is not a function because of a schema hallucination, the error is stopped dead in its tracks. The parent component (the chat window) doesn’t even flinch.

  2. Contextual Fallback: Instead of a generic “Something went wrong” message, CogniCatch displays an elegant, purpose-built Generative UI fallback.

  3. Recovery: By providing the rawPayload, developers (or users, depending on your setup) can actually see the hallucinated output, and the onRecover action allows you to instantly trigger a retry to the LLM without reloading the page.

Open-Source vs. Auto Mode

CogniCatch is an open-core project.

The mode="manual" (open-source) is completely free and runs locally. It isolates the crash, prevents the White Screen of Death, and exposes the rawPayload so your users (or you) can see the hallucinated output, allowing them to hit “Try Again” via the onRecover callback.

But I also built a Pro Tier (mode="auto") for a fully hands-off UX:

  1. Automatically translate the error empathetic message into the user’s native browser language.

  2. Visually parse and beautifully format the malformed JSON so developers and users can easily read what went wrong.

Join the Early Adopter Waitlist at cognicatch.dev (Early birds get 50% off the Pro tier for the first 6 months!).

Stop letting LLMs dictate your app’s stability

We shouldn’t let the non-deterministic nature of AI degrade the deterministic reliability of our React applications. By treating LLM outputs as highly volatile external data and wrapping them in specialized boundaries, you guarantee that an AI’s mistake never becomes a user’s frustration.

If you are tired of building AI wrappers that crash on unpredictable streams, give CogniCatch a try. It’s open-source, beautifully styled out of the box, and respects your telemetry.

Happy (and safe) prompting!

(Note: If you need to silently log these hallucinations to Sentry or Datadog without breaking the UI, the package also exposes an onError callback designed specifically to avoid blinding your observability tools. You can read my previous article about that here).
I built a platform that aggregates 30+ IT news sources so you don’t have to check them all

🤔 The Problem

As a developer in Korea, I was spending way too much time every morning visiting:

  • Korean tech blogs (Kakao, Toss, Woowa Brothers, Naver, Line)
  • IT news sites (ZDNet Korea, IT Donga, Digital Times)
  • International tech outlets
  • YouTube tech channels

I wanted one place to read everything. So I built it.

🚀 Introducing 한눈IT (HanunIT)

한눈IT means “IT at a glance” in Korean. It’s a content aggregation platform that collects, summarizes, and serves the latest IT articles and videos in a clean reading experience.

🔗 hanun-it.com

✨ Key Features

📰 Article Aggregation

Continuously collects articles from 30+ sources via RSS feeds. New content flows in throughout the day — no manual curation needed.

📝 AI-Powered Summaries

Every article comes with a concise summary. Scan dozens of articles in minutes and deep-dive only into what matters to you.

🌐 Translated Articles

International tech articles are auto-translated into Korean, bridging the language gap for Korean-speaking developers.

🎬 Tech Video Curation

Not just text — curated YouTube tech videos are collected alongside written articles. Switch between reading and watching depending on your mood.

💬 Community Features

Comment on articles, like your favorites, and join discussions with other developers.

📧 Newsletter

Subscribe to a weekly digest and get the best articles delivered to your inbox.

🛠️ Tech Stack

Here’s what’s under the hood:

Layer Tech
Framework Next.js 15 (App Router, Turbopack)
Language TypeScript
Database Supabase (PostgreSQL + RLS)
Auth Supabase Auth
State TanStack Query + Zustand
Styling Tailwind CSS + Shadcn UI
Deployment Vercel
Analytics Vercel Analytics

📐 Architecture Highlights

A few technical decisions I’m happy with:

Server-side rendering with caching — Article pages use revalidate = 300 for ISR. API routes return s-maxage=300, stale-while-revalidate=600 headers. Fast initial loads without hitting the DB every time.

Parallel data fetching — Article detail pages fire multiple Supabase queries with Promise.allSettled instead of sequential awaits. Shaved ~40% off load times.

Smart client caching — TanStack Query with 5-minute stale time and 30-minute GC. Users navigating between pages almost never see a loading spinner.

Per-request deduplication — Used React.cache() for article fetches in server components, so generateMetadata and the page component share the same data without duplicate DB calls.

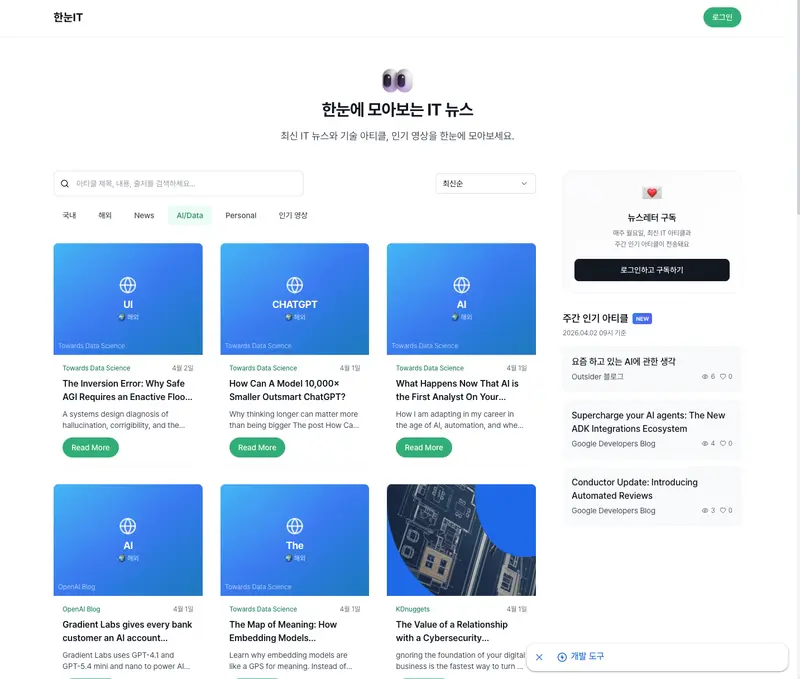
📸 Screenshots

🤷 What I Learned

  1. RSS feeds are messy — Every source has a slightly different format. Spent more time on parsing edge cases than I expected.
  2. Supabase RLS is powerful but tricky — Row Level Security policies need careful planning upfront. Debugging permission errors is not fun.
  3. Next.js 15 App Router is great — Server components + streaming + ISR is a solid combo for content-heavy sites.

🙏 Feedback Welcome

I’d love to hear:

  • What IT sources would you want to see added?
  • Any UX improvements you’d suggest?
  • Would you use something like this for your local tech ecosystem?

Thanks for reading! Drop a comment or visit hanun-it.com to check it out.

You send SMS. You get billed later. You don’t know why: estimate SMS cost in Python

You send SMS. You get billed later. You don’t know why.

That is a bad backend flow.

Before execution, you should know:

  • what the message will cost
  • whether your balance is sufficient
  • whether the route is worth using
  • whether the request should continue at all

That is what estimation is for.

Most SMS APIs expose pricing after execution.

You send first.

You get billed later.

That means your backend is making execution decisions without cost visibility.

The problem

Without pre-send estimation:

  • you cannot gate expensive requests
  • you cannot compare route cost before execution
  • you cannot prevent avoidable balance failures
  • you cannot build predictable messaging workflows

You are committing first and understanding later.

What estimate is actually for

Estimate is not just a pricing endpoint.

It is a pre-send decision step.

It lets your backend inspect execution cost before sending anything.

That means estimation can be used to:

  • approve or reject a send attempt
  • compare routes before execution
  • prevent balance-related failures
  • enforce budget rules
  • make routing decisions deliberately

Basic estimate request

import requests

API_KEY = "YOUR_API_KEY"
BASE_URL = "https://hi.bridgexapi.io"

response = requests.post(
    f"{BASE_URL}/api/v1/estimate",
    headers={
        "X-API-KEY": API_KEY,
        "Content-Type": "application/json",
    },
    json={
        "route_id": 1,
        "caller_id": "BRIDGEXAPI",
        "numbers": ["34699108839"],
        "message": "Cost test message"
    },
    timeout=30,
)

estimate = response.json()
print(estimate)

Real estimate result

{
  "status": "success",
  "message": "Estimate calculated successfully.",
  "route_id": 1,
  "count": 1,
  "estimated_cost": 0.051,
  "currency": "EUR",
  "balance": 201.7,
  "sufficient_balance": true,
  "sandbox": false
}

This gives you execution context before send:

  • estimated cost
  • current balance
  • whether sending is possible

Flow 1: estimate before send

import requests

API_KEY = "YOUR_API_KEY"
BASE_URL = "https://hi.bridgexapi.io"

payload = {
    "route_id": 1,
    "caller_id": "BRIDGEXAPI",
    "numbers": ["34699108839"],
    "message": "Verification code: 4839"
}

estimate_response = requests.post(
    f"{BASE_URL}/api/v1/estimate",
    headers={
        "X-API-KEY": API_KEY,
        "Content-Type": "application/json",
    },
    json=payload,
    timeout=30,
)

estimate = estimate_response.json()

if not estimate.get("sufficient_balance"):
    print("Do not send: insufficient balance")
else:
    send_response = requests.post(
        f"{BASE_URL}/api/v1/send_sms",
        headers={
            "X-API-KEY": API_KEY,
            "Content-Type": "application/json",
        },
        json=payload,
        timeout=30,
    )
    print(send_response.json())

Real send result

{
  "status": "success",
  "message": "SMS batch accepted via route 1",
  "order_id": 22565,
  "route_id": 1,
  "count": 1,
  "messages": [
    {
      "bx_message_id": "BX-22565-...",
      "msisdn": "34699108839",
      "status": "QUEUED"
    }
  ],
  "cost": 0.051,
  "balance_after": 201.65
}

Notice:

  • estimated_cost = 0.051
  • actual cost = 0.051

Estimation matches execution.

Flow 2: compare routes before sending

for route_id in [1, 2, 3]:
    result = estimate_for_route(route_id)
    print(f"Route {route_id} -> {result}")

Real comparison result

Route 1 -> estimated_cost: 0.051
Route 2 -> estimated_cost: 0.051
Route 3 -> estimated_cost: 0.052

Even small differences matter at scale.

What this enables

With estimation in the flow, you can build:

  • pre-send approval logic
  • balance-aware execution
  • route cost comparison
  • budget controls
  • safer OTP and transactional pipelines

Estimate is not just a number.

It is part of execution design.

Why this matters

In most systems:

pricing is discovered after execution

Here:

pricing is known before execution

That changes how you build backend messaging systems.

Closing

Most SMS APIs tell you what you spent.

BridgeXAPI lets you decide whether to spend at all.

This is not just pricing visibility.

This is pre-send execution control.

Next

→ debug failed SMS

→ build OTP flows

→ programmable routing vs black box APIs

Why Software Engineers Burn Out Differently And What To Do About It

There’s a specific kind of exhaustion that software engineers know well.

It’s not the kind where you can’t get out of bed. It’s the kind where you get out of bed, open your laptop, join the standup, close a few tickets — and feel absolutely nothing.

You’re still functioning. You’re still shipping. But somewhere along the way, the curiosity, the drive to build something that works, the satisfaction of solving a hard problem — quietly disappeared.

That’s burnout in tech. And it’s different from burnout in other fields in ways that make it particularly hard to catch.

Why tech burnout is different

The work is invisible. When a nurse burns out, there are physical limits. When an engineer burns out, they can still type. The output looks the same from the outside even when the inside is hollow. This makes it easy to push past warning signs for months.

Context switching is relentless. A single engineer’s day might include three different codebases, two product reviews, a design sync, four Slack threads, and an on-call alert — all before 2pm. Each switch has a cognitive cost. Over time, the cost compounds.

The goalpost moves constantly. You ship a feature. There’s another one. You fix a bug. There are more. The backlog never empties. For people driven by completion and progress, this is quietly demoralizing.

On-call is a category of suffering unto itself. Being woken at 2am, being responsible for systems you didn’t build, carrying the weight of production on your phone everywhere you go — this is a chronic low-level stressor that rarely gets acknowledged.

The warning signs most engineers miss:

  • You’re dreading Mondays in a way you didn’t used to
  • Code reviews feel like a chore instead of an opportunity
  • You’re less patient in meetings than you used to be
  • Side projects that excited you six months ago feel pointless now
  • You’re staying late but getting less done
  • You feel vaguely guilty all the time but can’t pinpoint why

None of these individually are alarming. All of them together, sustained over weeks, are a pattern worth taking seriously.

What actually helps
The standard advice — take a vacation, exercise more, meditate — isn’t wrong. But it’s incomplete. Burnout isn’t just about recovery. It’s about understanding the pattern that led you here so you don’t end up back in the same place six months later.

Name what’s actually draining you. Not just “work is stressful.” Specifically: is it the on-call rotation? The unclear priorities? The manager who cancels 1:1s? The more specific you can be, the more actionable the solution becomes.

Track it over time. Burnout builds slowly. One bad week doesn’t tell you much. But three months of data — noticing that your energy tanks every sprint planning, or that your stress spikes whenever a particular project comes up — tells you something real.

Don’t wait for crisis. The engineers who recover fastest from burnout are the ones who caught it early. Not because they’re weaker — but because they were paying attention.

The check-in habit
One of the simplest things an engineer can do is build a regular check-in habit. Just a short, honest answer to: how am I actually doing today? What’s weighing on me?

Done consistently, this creates a trail. You start to notice when things are sliding before they slide too far.

I built Recharge for exactly this — a private daily check-in that remembers what you share, tracks your burnout signals over time, and helps you spot patterns before they become crises. Built specifically for engineers, PMs, and founders because the context matters. First 7 days are free.

Stop Wasting Tokens on npm Install Noise

Run npm install in a medium-sized project. Count the deprecation warnings.

I counted 47 in one project. Each one says something like “This module is not supported and is kept for compatibility.” Claude Code reads all 47. They’re identical in meaning. They cost tokens. They push your actual code out of the context window.

What npm Install Actually Outputs

npm warn deprecated [email protected]: This module is not supported...
npm warn deprecated @humanwhocodes/[email protected]: Use @eslint/config-array
npm warn deprecated [email protected]: Rimraf versions prior to v4 are no longer supported
npm warn deprecated @humanwhocodes/[email protected]: Use @eslint/object-schema
npm warn deprecated [email protected]: Glob versions prior to v9 are no longer supported
npm warn deprecated [email protected]: This version is no longer supported...
⸨████████████████████░░░░░░░░░░░░░░░░░░░░░░░░░░░░⸩ ⠏ reify:core-js-compat: timing reifyNode...
added 1247 packages in 18s

Your AI needs exactly one line from this: added 1247 packages in 18s. Everything else is noise.

After ContextZip

added 1247 packages in 18s
💾 contextzip: 89,241 → 8,102 chars (91% saved)

91% reduction. 47 deprecation warnings → gone. Progress bars → gone. ANSI escape codes → gone. The install result is preserved.

Install

cargo install contextzip
eval "$(contextzip init)"

No config. No per-project setup. It just works as a transparent shell proxy.

GitHub: github.com/contextzip/contextzip

Part of the ContextZip Daily series. Follow for daily tips on optimizing your AI coding workflow.

Install: npx contextzip | GitHub: jee599/contextzip

512,000 Lines of Claude Code Leaked Through a Single .npmignore Mistake

On March 31, 2026, Anthropic published version 2.1.88 of their @anthropic-ai/claude-code package to the npm registry. Within hours, developers noticed something unusual: the package had ballooned to 59.8MB, roughly six times its normal size. The reason was a source map file — a .map file that contained the complete, unminified TypeScript source code for the entire Claude Code CLI. All 1,900 files. All 512,000 lines. Every internal function name, every comment, every feature flag.

I spent the past two days analyzing what those 512,000 lines reveal about how Anthropic builds its most important developer tool. This is what I found.

How a Build Configuration Error Exposed Everything

The mechanism is almost painfully simple. When you publish a package to npm, a file called .npmignore tells the registry which files to exclude. Source maps — the .map files that let debuggers trace minified code back to its original source — are routinely excluded from production packages because they contain the pre-bundled source. Anthropic’s build pipeline had this rule in place for every prior release. In 2.1.88, the rule was missing.

The Claude Code build process compiles TypeScript into a single 10.5MB cli.js bundle. The source map for that bundle embeds every original source file inline, meaning anyone who downloaded the package could reconstruct the entire codebase without any reverse engineering. According to BleepingComputer, automated package-size monitoring bots flagged the anomaly first, and the community started decoding within minutes.

The fallout was immediate and massive. The Hacker News reported that GitHub saw over 41,500 forks of repositories containing the extracted source within the first 24 hours. Anthropic pulled the package and issued a patched release, then sent DMCA takedown notices to 8,100 GitHub repositories. According to Axios, retrieving code that has already been downloaded and forked at this scale is practically impossible.

This is the second major security incident for Anthropic in a single week. The first was the Claude Mythos leak, where a misconfigured CMS exposed internal documents about an unreleased model with unprecedented cybersecurity capabilities.

Post not found or has been removed.

Inside KAIROS: The 24-Hour Autonomous Agent

The most significant discovery in the leaked source is a system called KAIROS — Knowledge-Aware Intelligent Reasoning and Operation System. Fortune reported on its existence, but the source code reveals far more than any news article could.

KAIROS is designed to run autonomously for 24 hours at a stretch. It monitors code repositories, analyzes issues, and generates pull requests without explicit user instruction for each action. The scheduling logic uses a priority queue that weighs task urgency against estimated completion time, and the permission system defines three tiers of autonomy: actions the agent can take immediately, actions that require a lightweight confirmation, and actions that are blocked until a human explicitly approves them.

What makes KAIROS architecturally interesting is how it manages context across a full day of operation. The source reveals a sliding-window approach to conversation history, where older context is compressed into summaries rather than dropped entirely. There’s also a “checkpoint” mechanism that periodically saves agent state to disk, allowing recovery from crashes without losing hours of accumulated context.

I should note that KAIROS appears to be behind a feature flag that isn’t enabled in the public release. The code is present, but the activation pathway requires an internal configuration that external users don’t have access to. Still, the fact that this infrastructure exists and is shipping in the production bundle says something about where Anthropic is headed with Claude Code.

KAIROS Architecture (reconstructed from source)

+------------------+
|   Task Queue     |  Priority-weighted scheduling
+--------+---------+
         |
    +----v----+
    | Planner |  Decomposes tasks, estimates cost
    +----+----+
         |
   +-----v------+     +----------------+
   | Executor   +---->| Permission Gate|
   +-----+------+     +-------+--------+
         |                    |
   +-----v------+    +-------v--------+
   | Tool Layer  |    | Human Approval |
   | (MCP/Shell) |    | (if required)  |
   +-----+------+    +----------------+
         |
   +-----v------+
   | Checkpoint  |  Periodic state persistence
   +-------------+

Anti-Distillation and the Undercover Mode

The second major finding is the anti-distillation mechanism. Distillation is the process where one AI model’s outputs are used as training data to improve a competing model — effectively stealing capability through the API. Anthropic’s defense against this is both clever and somewhat unsettling.

According to Alex Kim’s technical analysis, the system works by injecting fabricated tool definitions into certain responses. These fake definitions don’t affect Claude’s normal operation — the model knows to ignore them. But if a competitor scrapes Claude’s outputs and feeds them into their own training pipeline, those fabricated definitions introduce systematic errors into the competing model’s tool-use capabilities. The poisoned tool definitions look syntactically valid but contain subtle semantic errors that would degrade a model trained on them.

The third discovery, Undercover mode, is a response-filtering layer that prevents Claude Code from revealing internal identifiers. When a user asks about the model’s name, version, or system prompt structure, this filter intercepts the response and substitutes public-facing information. The source code contains a mapping table: Capybara corresponds to Claude 4.6, Fennec maps to Opus 4.6, and there’s an entry for Numbat — a model that hasn’t been announced yet.

Internal Codename Mapping (from source)

  Codename    Public Name       Status
  ---------   ----------------  -----------
  Capybara    Claude 4.6        Released
  Fennec      Opus 4.6          Released
  Numbat      ???               Unreleased

The combination of anti-distillation and Undercover mode reveals a company that is simultaneously defending against competitive threats and maintaining tight control over what users know about the system running on their machines. Whether this level of opacity is justified for a tool that executes commands in your terminal is a question worth sitting with.

Post not found or has been removed.

The Architecture: React in Your Terminal

Beyond the headline-grabbing features, the leaked source provides a complete picture of Claude Code’s technical stack.

The UI layer is built with React and Ink, a library that renders React components to the terminal. Layout is handled by Yoga, the Flexbox engine that also powers React Native. The runtime is Bun rather than Node.js, and the entire application compiles down to a single cli.js bundle at 10.5MB.

The sandbox implementation is where the engineering gets particularly impressive. On macOS, Claude Code uses Seatbelt, Apple’s kernel-level sandboxing framework that’s the same technology Safari uses to isolate web content. On Linux, it uses bubblewrap, a namespace-based container isolation tool originally developed for Flatpak. The source reveals granular permission controls over filesystem access, network requests, and process spawning — each operation goes through a policy check before execution.

The sub-agent system is another notable architectural choice. When Claude Code encounters a complex task, it can decompose it into subtasks and delegate them to child agents, each with their own isolated context window and tool permissions. These sub-agents communicate through a structured message-passing protocol, and the parent agent aggregates their results. Integration with MCP (Model Context Protocol) allows external services to plug into this agent hierarchy, and a plugin/skill system lets users extend Claude Code’s capabilities through modular packages.

What struck me most about the architecture is how seriously Anthropic takes isolation boundaries. Each sub-agent, each tool invocation, each file access goes through explicit permission checks. The irony — and it is genuine irony, not a rhetorical device — is that all of this careful security engineering was undone by a missing line in .npmignore.

Post not found or has been removed.

What This Means for the AI Agent Ecosystem

The Claude Code source leak is a mirror held up to the entire AI agent ecosystem. Every company building agents that run on user machines faces the same tension: the more capable the agent, the more it needs access to, and the more important it becomes to be transparent about what that agent actually does.

Anthropic’s leaked code shows an engineering team that has thought deeply about sandboxing, permission hierarchies, and safe autonomous operation. The KAIROS checkpoint system, the tiered permission gates, the kernel-level isolation — these aren’t afterthoughts. They represent significant investment in doing agent security right.

But the anti-distillation mechanism and Undercover mode tell a different story. These are features designed to operate without the user’s knowledge, embedded in a tool that the user trusts with terminal access. The question isn’t whether Anthropic has good reasons for these features — competitive defense and information security are legitimate concerns. The question is whether undisclosed features belong in a tool with this level of system access.

The .npmignore failure itself carries a lesson that extends beyond Anthropic. CI/CD pipelines for AI agents need artifact auditing as a first-class concern, not an afterthought. Package size validation, source map detection, and pre-publish review should be automated gates that block deployment, not monitoring alerts that fire after the damage is done.

The most dangerous assumption in software security isn’t that your code is correct — it’s that your build process is.

What happens when the next agent source leak reveals features that aren’t as defensible as sandboxing and permission gates?

Full Korean analysis on spoonai.me