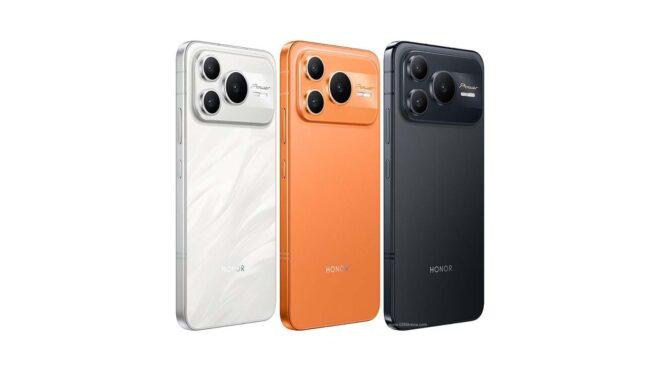
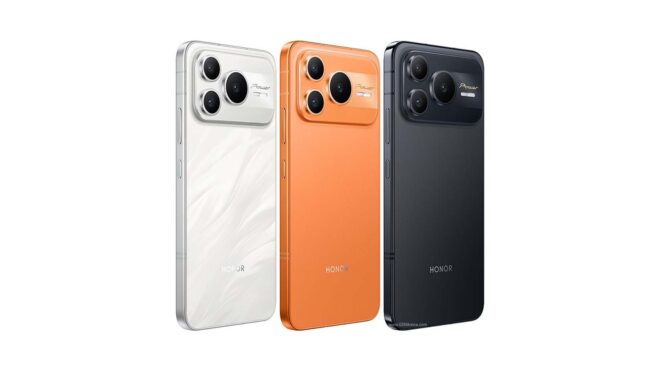
Honor Power3, 11-12.000 mAh kapasiteli bir batarya ile gelebilir

Honor Power3, 11-12.000 mAh kapasiteli bir batarya ile gelebilir

Honor Power3, 11-12.000 mAh kapasiteli bir batarya ile gelebilirYakın zaman önce pazara sunulan Honor Power2, 80W şarj destekli 10.000 mAh bataryasıyla oldukça dikkat çekmişti. Yeni bilgilere göre bir sonraki model “Honor Power3” ile batarya kapasitesi 11.000 ya da 12.000 mAh seviyesine kadar taşınabilir. Bu kapasiteler için testler gerçekleştirdiği aktarılan Çinli şirket, iddiaya göre yeni telefona 6,8 inç boyutunda LTPS OLED ekran konumlandırabilir. Mevcut model Power2 kısaca hatırlatmak adına gücünü MediaTek Dimensity 8500 Elite işlemciden alıyor. Devasa bataryasına rağmen 162,1 x 76,3 x 7,98 mm boyutlarında ve 216 gram ağırlığında olan telefon, 6,79 inç büyüklüğünde 1.5K 120 Hz LTPS AMOLED ekranla geliyor. 16 megapiksellik selfie kamerasının kullanıldığı Power2, 50 megapiksel çözünürlüğünde OIS destekli ana kamerayla karşımıza çıkarılıyor. Ayrıca 5 megapiksellik ultra geniş açılı kamerayla donatılan telefon, kutusundan Android 16 tabanlı MagicOS 10 ile çıkıyor. Üç farklı renk seçeneği bulunan cihaz, IP69K sertifikasına sahip.

Honor Power3, 11-12.000 mAh kapasiteli bir batarya ile gelebilir yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Introducing OpenAI for Singapore

OpenAI for Singapore launches a multi-year AI partnership to expand deployment, build local talent, and support businesses and public services with AI.

1.153 beygirlik elektrikli “Mercedes-AMG GT 4-Door Coupé” görücüye çıkarıldı

1.153 beygirlik elektrikli Mercedes-AMG GT 4-Door Coupé görücüye çıkarıldı

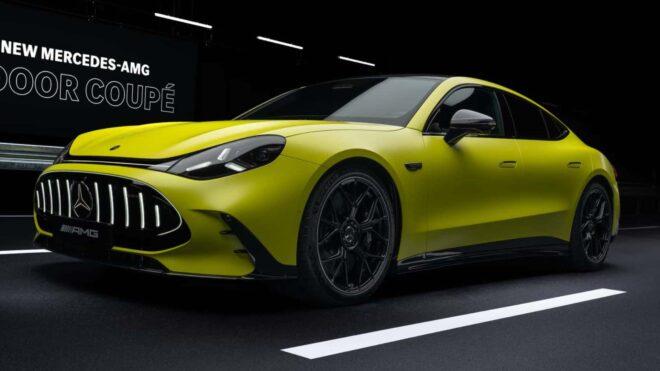
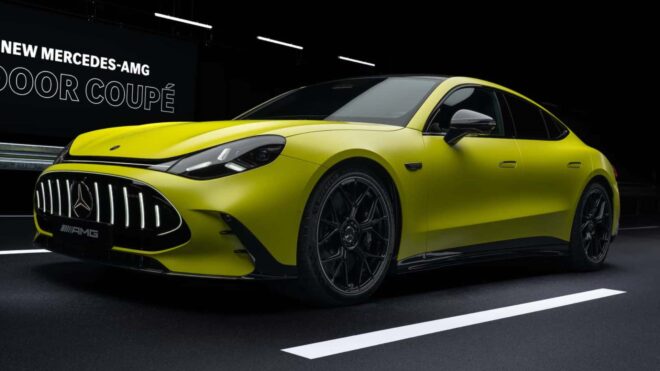
1.153 beygirlik elektrikli Mercedes-AMG GT 4-Door Coupé görücüye çıkarıldıAMG GT XX konseptinden ilham alınarak hazırlanan Mercedes-AMG GT 4-Door Coupé, “AMG GT” ürün gamının tamamen elektrikli ilk üyesi olarak karşımızda. AMG GT 4-Door Coupé’nin tasarımında odak nokta yüksek aerodinamik performans elde etmek olmuş. Dört kapılı araçta yüksek hızlarda otomatik olarak açılan rüzgarlık ve dışa doğru uzayabilen yapıda bir arka difüzör bulunuyor. Bu sayede 0,22 cD gibi etkileyici derecede düşük bir sürtünme katsayısına ulaşılan model, ilk aşamada “GT55” ve “GT63” olmak üzere iki farklı versiyonla geliyor. Üç farklı YASA destekli ince ancak oldukça güçlü elektrik motorunun (ikisi arkada, biri önde) bir araya getirildiği GT55 versiyonu için, 805 beygir (sürekli güç 503 beygir) güç açıklanıyor. AMG 4Matic+ dört çeker sisteminin standart olarak sunulduğu aracın yine üç motorlu GT63 versiyonunda ise tam 1.153 beygir (sürekli olarak 711 beygir) güç sunuluyor. AMG GT 4-Door Coupé, Mercedes-Benz tarafından geliştirilen tamamen yeni bir batarya sistemini temel alıyor. Bu sistemde her bir hücre için doğrudan soğutma […]

1.153 beygirlik elektrikli “Mercedes-AMG GT 4-Door Coupé” görücüye çıkarıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

The Future of AI in Business: What’s Actually Changing and What’s Just Hype

What Is Being Overclaimed

Separating Signal From Noise in 2026

Every major technology wave produces the same pattern: genuine capability advances, followed by overclaiming, followed by a correction, followed by actual adoption at scale. We went through it with cloud computing, mobile, and big data. We’re going through it with AI now.

The challenge for developers and engineering leaders is calibrating correctly. Dismissing AI as hype means missing genuine capability shifts that will change competitive dynamics in your industry. Believing everything means building on foundations that aren’t ready, burning engineering time on features users won’t adopt, and making technology decisions you’ll regret when the dust settles.

This post is an attempt at calibration — a clear-eyed look at what AI is actually changing in business software, what timelines are realistic, and where the current claims outrun the evidence.

What Is Actually Changing (With Evidence)

1. The cost of generating structured content has collapsed

Three years ago, producing a personalised, well-formatted document — a proposal, a report, a contract summary — required significant human time. Today, a well-prompted language model can produce a first draft that requires light editing rather than full authorship.

This is real and it’s being adopted. The categories where it’s showing clear ROI:

  • Customer-facing documents: Proposals, quotes, summaries, follow-up emails
  • Internal documentation: Meeting notes, incident reports, status updates
  • Code first drafts: Boilerplate, test scaffolding, repetitive CRUD operations
  • Data interpretation: “Explain what this chart means” at the analyst tier

The productivity gains are real but unevenly distributed. People who work heavily with structured text — writers, analysts, developers — see meaningful productivity improvements. People whose work is primarily relational, physical, or requires deep domain expertise see smaller gains.

2. Search is being replaced by retrieval-augmented generation in knowledge-heavy applications

Enterprise search has always been disappointing. You search a knowledge base and get a ranked list of potentially relevant documents. You then have to read those documents to find the actual answer.

RAG changes the contract: you ask a question in natural language, and you get an answer — ideally with citations so you can verify it. For knowledge-heavy applications (legal, compliance, customer support, internal IT), this is a genuine step function improvement.

The technology is real. The implementation challenge is data quality. RAG systems are only as good as the documents they retrieve from. If your knowledge base is a graveyard of outdated policies and inconsistent formatting, RAG makes it faster to get wrong answers.

3. Autonomous agents are beginning to handle narrow, well-defined workflows

The agent hype cycle peaked around 2024 with claims of fully autonomous software engineers and self-managing businesses. Reality is more modest but genuinely interesting: agents that handle specific, well-scoped workflows with human oversight checkpoints are working in production.

The categories where this is real today:

  • Data enrichment pipelines: Agents that look up information, cross-reference sources, and populate structured records
  • Tier-1 support triage: Classification, routing, and initial response — with human escalation paths
  • Code review assistance: Automated checks for security issues, style consistency, and common bugs
  • Report generation: Pulling data from multiple sources and producing narrative summaries

The key word in all of these is “narrow.” Agents that work are doing one well-defined thing with clear success criteria and bounded failure modes. Agents that fail are trying to do too much in domains that aren’t well-specified.

What Is Being Overclaimed

What Is Being Overclaimed

“AI will replace most knowledge workers within 5 years”

This claim collapses when you look at what knowledge work actually consists of. Most knowledge worker time is spent on: relationship management, judgment calls in ambiguous situations, navigating organizational politics, and communicating with stakeholders. AI assists with the documented, text-based portions of this work. It doesn’t handle the rest.

The more accurate framing: AI will handle the rote, repetitive, and document-heavy portions of knowledge work, raising the floor for what each worker can produce. This will reduce headcount growth in some functions. It is unlikely to cause mass displacement in the near term.

“You can replace your entire data team with AI”

This one is being sold hard. The reality: AI can accelerate data analysis, surface anomalies, and generate draft interpretations. It cannot replace the domain expertise required to know which questions are worth asking, why a metric moved, or whether a pattern represents a real business signal or a data quality issue.

Data teams that integrate AI tools well become more productive. They are not eliminated.

“Fully autonomous AI coding will end software development”

GitHub Copilot and similar tools are genuinely useful for certain tasks. They write boilerplate well. They autocomplete familiar patterns. They can generate test cases.

What they cannot do: design systems, make architectural tradeoffs, understand business context, manage technical debt across a large codebase, or navigate the gap between what a specification says and what was actually meant. Software development is not primarily about typing code — it’s about understanding problems and making decisions. AI assists with the expression layer. The reasoning layer remains human.

The Business Adoption Curve: Where Different Industries Actually Are

Different industries are at different points in genuine AI adoption, and understanding where your industry sits matters for technology decisions.

Early majority (real ROI being measured now):

  • Financial services: Fraud detection, credit risk, regulatory reporting
  • Healthcare: Diagnostic imaging assistance, clinical documentation, drug discovery
  • Legal: Document review, contract analysis, research assistance
  • Software development: Code assistance, test generation, documentation

Early adopter phase (pilots showing promise, scale unclear):

  • Manufacturing: Predictive maintenance, quality control
  • Retail: Demand forecasting, personalisation at scale
  • Professional services: Proposal generation, project scoping

Still experimental (genuine capability, adoption friction high):

  • Education: Personalised tutoring, automated grading
  • Government: Citizen services, policy analysis
  • Construction: Project planning, safety monitoring

The distinction matters because early majority means you can study competitors’ implementations and learn from their mistakes. Early adopter means you’re figuring things out yourself. Still experimental means the technology is ahead of the deployment infrastructure.

The Infrastructure Layer That Determines Everything

The thing most business AI discussions miss is the infrastructure question. AI capabilities are advancing fast. The infrastructure required to use those capabilities reliably in production is advancing more slowly.

The gaps that matter most right now:

Evaluation infrastructure: How do you know when your AI system is working correctly? The testing tools for AI systems are immature compared to those for traditional software. Most teams are flying partially blind.

Cost management: AI API costs are unpredictable and can scale non-linearly with usage. Teams that haven’t built cost monitoring and circuit breakers into their AI architecture routinely get surprised by bills.

Data governance: Which data can you send to external AI APIs? For regulated industries, this is not a minor compliance checkbox — it’s a fundamental constraint on what AI you can use and where.

Change management: AI features change user workflows. The organisational challenge of getting people to use AI tools effectively is often larger than the engineering challenge of building them.

What This Means for Engineering Decisions Today

What This Means for Engineering Decisions Today

If you’re making technology decisions with a 2-3 year horizon, the framework we use:

Build now, with confidence:

  • RAG pipelines for knowledge-heavy applications
  • LLM-assisted content generation with human review
  • Narrow workflow automation with defined scope and human oversight
  • AI-assisted code review and testing

Build now, but architect for change:

  • AI-powered search and recommendation systems (models and providers will change)
  • Customer-facing AI features (user expectations are shifting fast)
  • Anything using frontier model APIs (pricing and capability are moving targets)

Wait for the infrastructure to mature:

  • Fully autonomous agents for open-ended business processes
  • AI systems making consequential decisions without human review
  • Multi-model orchestration for complex reasoning tasks

Evaluate carefully before building:

  • Replacing human roles wholesale (usually premature and often counterproductive)
  • Training proprietary models (expensive, requires data infrastructure most companies don’t have)
  • Real-time AI in latency-sensitive critical paths

The companies that will be best positioned in three years are not those who adopted AI fastest. They’re the ones who adopted AI thoughtfully — building on genuine capabilities, maintaining flexibility as the landscape shifts, and solving real problems rather than demonstrating AI adoption for its own sake.

For a deeper look at how these trends are playing out across different business functions, our team at Lycore has written about the practical implications for software businesses — including what the timeline for genuine agentic automation actually looks like when you look past the marketing.

The Honest Summary

AI is changing business software meaningfully and durably. The changes are real but more incremental than the hype suggests, more dependent on data quality than vendors admit, and more constrained by organizational factors than technologists acknowledge.

The developers and engineers who will navigate this well are those who stay close to evidence — who look at what is working in production rather than what’s impressive in demos, who measure adoption rather than capability, and who maintain enough technical foundation to switch approaches as the landscape evolves.

The wave is real. Riding it well requires keeping your feet on the ground.

What AI bets are you making in your current projects? I’m particularly interested in hearing from people who’ve tried things that didn’t work — those stories are usually more instructive than the success cases.

200,000 MCP Servers Are Exposed. Here’s Why Serverless Is Safer.

I’ve spent a lot of time thinking about where MCP servers should live. I work with remote MCP servers constantly and do a lot of the architecture work around them. But I also use plenty of local ones. There’s a simplicity to npx @modelcontextprotocol/server-whatever that’s hard to argue with.

Then MCP crossed 300 million SDK downloads a month in April 2026, and a few days later, OX Security published a disclosure that put a number on what I’d been turning over in my head: the most popular MCP transport has no authentication, and 200,000 servers are running it in production.

That got me to finally put my thoughts together. The short version: the subprocess-spawn vulnerability that OX Security disclosed is specific to STDIO, the local transport. Remote MCP servers avoid that specific attack path, though they introduce different web and API security considerations. And if you’re going to run remote MCP servers, I think serverless is the best place to do it.

Let’s walk through it.

What OX Security found in MCP’s STDIO transport

The root cause is in MCP’s STDIO transport. When an MCP client connects to a server via STDIO, it passes a StdioServerParameters object to the SDK. That object contains a command field and an args array that tell the SDK which process to spawn.

The official MCP SDKs across Python, TypeScript, Java, and Rust do not sanitize those fields before passing them to the operating system. Whatever strings arrive get executed as shell commands on the host machine.

The execution sequence makes it worse. The command runs first. Then the MCP handshake tries to validate it as a legitimate server. Then the handshake fails. But the payload already ran. OX Security described this as “execute first, validate never,” and that’s accurate.

CVE-2025-49596: Browser to backdoor

The specific CVE that got the most attention was CVE-2025-49596, a CVSS 9.4 critical vulnerability in MCP Inspector, Anthropic’s official debugging tool. The Inspector runs a proxy on localhost that accepts commands from its browser UI with zero authentication.

The attack chain: On macOS and Linux, browsers allow websites to make requests to 0.0.0.0, which the OS silently redirects to 127.0.0.1. A developer visits a malicious website. The site’s JavaScript reaches MCP Inspector through the 0.0.0.0 bypass. Arbitrary code runs on the developer’s machine. No phishing, no suspicious downloads. Just a website visit.

How many MCP servers are affected

The numbers from the OX disclosure:

  • 200,000+ vulnerable server instances
  • 150 million+ cumulative downloads across affected packages
  • 7,000+ publicly accessible MCP servers
  • 10+ high or critical CVEs
  • 200+ affected open-source projects

Why serverless reduces the MCP risk surface

The STDIO model is essentially “download this script, run it as a local server, trust it.” The vulnerability exists because of three assumptions baked into the STDIO transport: there’s a persistent process running on the host, that process has shell access, and there’s no authentication layer between the client and the process.

Serverless compute inverts all three.

No persistent process to hijack. Lambda functions run in Firecracker microVMs, isolated execution environments that the Lambda service manages. There’s no customer-managed long-running daemon process exposed to clients.

No client-controlled process spawning. When Lambda serves as an MCP server, communication happens over HTTPS. The MCP Streamable HTTP transport replaces the STDIO subprocess model entirely. There’s no path for a client to trigger arbitrary process execution on the host.

Auth is infrastructure, not application code. STDIO local transports rely on local process trust. With Lambda, you get IAM auth on Function URLs and IAM or Cognito authorizers on API Gateway. Auth is a configuration toggle, not something you need to build yourself.

Lambda as an MCP server: build it yourself

IAM auth with SigV4 — Set your Function URL’s AuthType to AWS_IAM and every request requires Signature Version 4 signing. No tokens to manage, no OAuth dance, no plaintext API keys.

OAuth 2.1 for external agents — Front the Lambda function with API Gateway, attach a Cognito authorizer. API Gateway validates the token before the request ever reaches your function.

The awslabs STDIO adapter — Already have MCP servers built on STDIO? The awslabs/run-model-context-protocol-servers-with-aws-lambda project wraps existing STDIO-based MCP servers so they run inside Lambda. The STDIO surface stays internal to the Lambda sandbox and is never exposed to the network.

Working examples

AgentCore: let AWS manage your MCP servers

Amazon Bedrock AgentCore centralizes auth, policy enforcement, and observability into a single endpoint. The Gateway sits in front of all your MCP servers. Interceptors let you filter which tools an agent can see based on caller identity and context. AgentCore Runtime handles containerization, scaling, and session isolation — you write the server code, AgentCore runs each session in a dedicated microVM.

But what about local file access?

If your MCP tools need local file access, they still need to run locally. That’s a real limitation of any remote MCP server. For tools that work with shared files or project artifacts, S3 Files is an interesting middle ground — it mounts an S3 bucket as a local filesystem on your Lambda function.

Run your MCP servers somewhere secure

Of those 200,000 exposed STDIO servers, every one that could be redeployed as a remote MCP server behind authenticated infrastructure would remove itself from that count.

Serverless doesn’t patch the protocol. It removes the conditions the vulnerability depends on. No persistent process, no STDIO surface, and auth on every request by default.

Lambda if you want control. AgentCore if you want managed. You’ve got options. Use them.

How I Structure Every Full Stack Project in 2025

I build a lot of full-stack projects. The first 50 lines of code set the pattern for the next 50,000.

Here’s the structure I use for every project. Opinionated. Works.

The Monorepo Structure

project/
├── packages/
│   ├── web/                    # Next.js frontend
│   │   └── src/
│   │       ├── app/
│   │       ├── components/
│   │       ├── hooks/
│   │       └── lib/
│   ├── api/                    # Node.js backend
│   │   └── src/
│   │       ├── routes/
│   │       ├── controllers/
│   │       ├── services/
│   │       ├── middleware/
│   │       └── models/
│   └── shared/                 # Shared TypeScript types
│       └── src/
│           ├── types.ts
│           ├── constants.ts
│           └── validators.ts
├── docker-compose.yml
├── turbo.json
└── package.json

Root package.json

{
  "workspaces": ["packages/*"],
  "scripts": {
    "dev": "turbo run dev --parallel",
    "build": "turbo run build",
    "test": "turbo run test"
  }
}

Environment Management

// packages/shared/src/env.ts
const requiredEnvVars = ['DATABASE_URL', 'JWT_SECRET', 'REDIS_URL'];

export const env = {
  databaseUrl: process.env.DATABASE_URL!,
  jwtSecret: process.env.JWT_SECRET!,
  redisUrl: process.env.REDIS_URL!,
};

requiredEnvVars.forEach((key) => {
  if (!process.env[key]) throw new Error(`Missing required env var: ${key}`);
});

Type Sharing

// packages/shared/src/types.ts
export type User = { id: string; email: string; name: string; createdAt: Date };
export type ApiResponse<T> = { success: boolean; data?: T; error?: string };

Backend:

import { User, ApiResponse } from '@shared/types';
router.post('/users', async (req, res) => {
  const user: User = await db.users.create(req.body);
  res.json<ApiResponse<User>>({ success: true, data: user });
});

Frontend uses same types — no mismatches, no runtime surprises.

Docker for Local Dev

version: '3'
services:
  postgres:
    image: postgres:16
    environment:
      POSTGRES_USER: dev
      POSTGRES_PASSWORD: dev
      POSTGRES_DB: mydb
    ports: ["5432:5432"]
  redis:
    image: redis:7
    ports: ["6379:6379"]

docker-compose up -d and the environment is ready.

Testing Structure

tests/
├── unit/
│   └── services/
├── integration/
│   └── routes/
└── fixtures/

CI/CD (GitHub Actions)

jobs:
  test:
    runs-on: ubuntu-latest
    services:
      postgres:
        image: postgres:16
    steps:
      - uses: actions/checkout@v4
      - uses: actions/setup-node@v4
        with: { node-version: '20' }
      - run: npm ci
      - run: npm run lint
      - run: npm run test
      - run: npm run build

Why This Stack

  • Monorepo: One repo, one CI/CD, type sharing, easier refactoring
  • Three packages: web deploys to Vercel, api deploys anywhere, shared is the contract between them
  • TypeScript everywhere: Catches errors at build time, not runtime
  • Turbo: Parallel builds, smart caching
  • Docker locally: Dev matches prod

Day 1 setup: monorepo + docker + shared types + CI/CD + 5 integration tests. Costs one week. Saves months.

zunain.com

Why I Invested ₹5 Lakhs in an M5 Max (64GB) Instead of Real Estate: An Architect’s Bet on On-Device AI and Global Freedom

Six years ago, the M1 MacBook Air rewrote the rules of mobile computing. For a long time, it was my favorite daily driver—silent, power-efficient, and perfectly capable of handling traditional web and mobile layouts.

But technology doesn’t stand still, and neither does the role of a Full-Stack Mobile Architect.

Recently, I made a massive leap. I went from that baseline M1 Air straight to a maxed-out M5 Max MacBook Pro with 64GB of Unified Memory, costing roughly ₹5,00,000 (~$6,000 USD).

Spending half a million rupees on a single laptop isn’t a casual retail purchase. It is a strategic infrastructure investment. In an era where the tech industry is gripping itself tightly over layoffs and corporate uncertainty, I chose to postpone personal leisure, skip real estate down payments, and buy a personal R&D lab on EMI.

Here is the exact architectural and philosophical breakdown of why this investment was non-negotiable for my career insurance.

1. The “Enterprise Silo” and the Danger of Tech Stagnation

When you work as a senior engineer or lead for an organization, you are bound by their existing tech stack, legacy codebases, security policies, and production timelines.

If your day job involves maintaining standard React Native applications with a traditional cloud backend, that is all you are allowed to touch on company hours. Your corporate-issued laptop is locked down by MDM profiles, blocking you from installing experimental tools, flashing custom kernels, or spinning up local models.

The risk? Your skillset freezes in time.

If you only code on company time, you are letting the market outpace you. To stay ahead of shifting paradigms, you have to run your own independent R&D lab on your own time. My primary objective with this upgrade was to break out of the enterprise silo and explore the immediate future of mobile computing: On-Device AI.

2. Breaking the Mobile Compilation Bottleneck

If you have ever built production-grade cross-platform mobile apps, you know that JavaScript/TypeScript is only half the battle. The true friction lies in the native compilation layers.

On my older M1 Air, compiling a complex, real-world hybrid stack with heavy native dependencies, CocoaPods, and asset-bundling into a final iOS .ipa or Android .apk via Xcode or Gradle routinely took 15 to 20 minutes.

The M1 Air vs. M5 Max Performance Wall

The reason for this real-world lag comes down to hardware architecture:

  • Thermal Throttling: The M1 Air is fanless. A prolonged native build heats up the silicon within 180 seconds, forcing the system to step down its clock speeds to manage thermals.
  • Disk Swapping Memory I/O: Archiving an app requires intensive asset compression and indexing. On an 8GB or 16GB machine, the OS runs out of physical RAM immediately, forcing a massive I/O bottleneck as it continuously reads and writes to SSD swap space.

With the M5 Max’s 18-core CPU (featuring Apple’s dedicated “Super Cores”) and active cooling, that 20-minute build drops to under 90 seconds. More importantly, its 64GB of Unified Memory offers a staggering 460GB/s of bandwidth, meaning disk swapping is completely eradicated. When you multiply those saved minutes across hundreds of local iterations a year, you aren’t just buying hardware; you are buying back weeks of un-fragmented deep focus.

3. The Sweet Spot for Local On-Device AI Engineering

The engineering world is aggressively shifting toward local inference. Waiting for cloud-synchronized sandboxes, network latency, and paying recurring AWS EC2 or Hugging Face GPU instance bills introduces massive friction during the R&D and prototyping phase.

Because Apple Silicon uses a Unified Memory Architecture, the GPU has direct, low-latency access to the entire 64GB memory pool. This fundamentally transforms your laptop into a local VRAM powerhouse.

+-----------------------------------------------------------------------+
|                       64GB UNIFIED MEMORY POOL                        |
+------------------------------------+----------------------------------+
|      AI INFERENCE ENVIRONMENT      |    MOBILE DEVELOPMENT STACK      |
|  - Local LLM Execution (Llama 3)   |  - Metro Bundler Engine          |
|  - ExecuTorch Framework Pipelines  |  - iOS Simulator Runtime         |
|  - CoreML / NNAPI Quantization     |  - Android Emulator Environment  |
+------------------------------------+----------------------------------+

On this system, I can concurrently execute:

  1. An iOS Simulator and an Android Emulator side-by-side to debug native UI anomalies.
  2. A Metro bundler and local development servers.
  3. Heavy, quantized local LLMs (like a Llama 3 8B or Mistral 7B) running locally to test runtime performance.

This allows me to build and test edge-AI mobile architectures—such as compiling pipelines via ExecuTorch (PyTorch for mobile mobile platforms)—to monitor how local models impact device thermals, memory pressure, and battery cycles in real-time. You cannot simulate this multi-threaded mobile-AI ecosystem seamlessly on a standard consumer machine.

4. The Philosophy of Detachment and Global Fluidity

There is a deeper, more spiritual reason behind how I manage my career.

To this day, I do not own any land or permanent real estate anywhere in the world. In traditional terms, this looks like a lack of security. In reality, it is the ultimate freedom.

Permanent physical assets can easily become golden handcuffs. They anchor you to a specific geographic region, lock your liquid capital into illiquid brick-and-mortar, and make navigating industry volatility a deeply stressful affair.

  • My security does not belong to a corporate title or a plot of land.
  • My security belongs entirely to my competence and agility.

By staying entirely unanchored, I have preserved absolute geographic and intellectual flexibility. I am free to move, adapt, relocate to completely new cultures—whether across the Nordic regions or Central Europe—and partner with teams solving complex infrastructural problems. I love meeting new people, immersing myself in fresh tech cultures, and taking on international architectural challenges.

Postponing a vacation and taking on an EMI to acquire this M5 Max wasn’t a liability; it was a conscious deployment of capital into a high-leverage asset.

The Long-Term Verdict

90% of software developers do not need a ₹5 Lakh machine. If your day-to-day responsibilities focus on standard enterprise CRUD APIs or standard frontend frameworks, a baseline system is completely fine.

But if your personal engineering roadmap involves pushing the boundaries of cross-platform mobile compilation, native architectural research, and on-device machine learning pipelines, your requirements change. You stop looking at the price tag of a laptop, and you start evaluating the cost of friction.

By mastering the underlying computer science fundamentals, investing heavily in product thinking, and keeping my setup completely state-of-the-art, I don’t have to fear the next wave of industry transformation. I have built a playground to master it.

How do you manage your personal R&D outside of your corporate assignments? Are you experimenting with local LLM deployments or mobile edge-AI yet? Let’s connect and discuss in the comments.

Yes, it is entirely fine and very common to include a call to action (CTA) for a personal community channel like WhatsApp, Telegram, or a newsletter at the end of articles on both Medium and dev.to.

Both platforms encourage creators to build their own audiences, provided it is a genuine invitation to follow your journey rather than pure spam.

Here is the exact closing portion to append to the end of your post:

Join My Journey

If you want to look over my shoulder as I build out the future of cross-platform mobile architecture, experiment with on-device AI, and document my roadmap toward global relocation, let’s stay connected.

👉 Join my WhatsApp Channel here to get real-time updates, technical insights, and behind-the-scenes content on engineering and mentorship. Let’s build together!

Track record now covers 3m — what the data said before we shipped it

For two weeks, AlgoVault’s 3-minute timeframe sat in shadow mode: cron-seeded, fully evaluated, but stripped from the public /api/performance-public aggregate before any caller saw it. Today we flipped it into the live track record. Here’s what the data looked like before we made that call, and why the flip is overdue rather than aggressive.

The measurement

3m had accumulated 3,961 evaluated samples across our 5 venues by 2026-05-19. Weighted-aggregate PFE Win Rate: 92.43%. Per-venue breakdown was tight: Bitget 93.5%, OKX 91.9%, Bybit 92.2%, Binance 92.6%, Hyperliquid 92.2%. No outlier venue, no thin-sample skew.

Timeframe Samples PFE Win Rate
5m 37,305 92.49%
15m 19,048 92.30%
3m (newly public) 3,961 92.43%
30m 8,715 89.86%
1h 13,016 88.36%
4h 2,424 86.01%
2h 7,494 85.51%
12h 1,307 84.09%
8h 1,027 81.01%
1d 775 58.45%

3m outperforms 7 of the 9 timeframes that were already public. Only 5m and 15m beat it, and the gap is under 0.1pp.

How shadow mode worked

Every timeframe we ship gets seeded by the same cron jobs that feed the public dashboard. Shadow-mode TFs (1m + 3m, originally) are seeded identically — the only difference is a filter in the public response handler that strips them out of the byTimeframe aggregate. They remain fully visible inside byExchange.<EX>.byTimeframe for our own auditability.

The point of the shadow window is to accumulate honest sample density before claiming anything publicly. Two gates: ≥3,000 evaluated samples and ≥85% weighted PFE Win Rate. 3m cleared both gates by a clear margin — sample count +32% above the floor, PFE +7.4pp above it.

What we’d previously said about sub-5-minute signals

Our FAQ used to say sub-5-minute indicators are “noise-dominated by design.” That framing was a pre-measurement assumption baked into copy before we had data. The measured 3m result — 92.43% PFE Win Rate across nearly 4,000 evaluated samples — refutes it. We’ve dropped that framing from the FAQ, llms-full.txt, and our brand-facts canonical reference as part of this flip.

The Data Integrity rule we operate under says public copy can’t lag behind measurement. When the numbers contradict the framing, the framing changes.

What’s next

  • 1m remains shadow this cycle. Sample count is 3,330, just below our preferred comfort margin. Another weekly cron cycle should push it over. Same flip mechanism when it clears.
  • 3m universe expansion. 3m is currently cron-seeded against a top-5 OI-restricted universe. The next wave expands it to top-50 to match the rest of the cron set. We’re sequencing that AFTER one week of post-flip stability so attribution stays clean.
  • Every signal is still Merkle-anchored on Base L2. No retroactive edits, no deletes. The 3m signals shipped over the past two weeks were already on-chain; the flip changes only what shows up in the public aggregate, not the underlying record.

Try it

The 3m timeframe is callable today via the MCP get_trade_call tool (set timeframe: "3m") or directly via /api/performance-public.byTimeframe["3m"]. Free tier: 100 calls per month, no signup.

Start at algovault.com. Verify any 3m signal against its on-chain Merkle proof at algovault.com/verify.

I built a storage engine from scratch. Here’s everything I learned.

I built a storage engine from scratch. Here’s everything I learned.

Not a wrapper. Not a library call. A real, working storage engine — written in C++, exposed over gRPC, running inside Docker. This is the story of how I built it and why.

The problem I was trying to solve

I needed to store structured data in a very specific shape:

  • A document (HTML, text, anything)
  • A chain of inputs attached to that document
  • An expected output for each input

Simple enough, right? But every database I looked at felt wrong.

A relational database wanted me to define a schema upfront and write JOIN queries just to read a document with its inputs. A key-value store was too flat — I’d have to model the relationships myself. A document database handled the top level fine but got awkward when I needed an ordered, linked chain of sub-documents.

So I built exactly what I needed. Nothing more.

What is Stratum?

Stratum is a log-structured, hierarchical storage engine with O(1) lookup, built in C++ and exposed over gRPC so any language can talk to it.

Here’s the data model:

Document ──→ Input node 1 ──→ Input node 2 ──→ Input node 3
                  │                 │                 │
                  ▼                 ▼                 ▼
             Output node 1    Output node 2    Output node 3

Every document lives at a known byte offset on disk. An in-memory hash map holds document_id → byte_offset. Every read is one hash map lookup (O(1)) plus one disk seek. No indexes to maintain, no query planner, no surprises.

How it actually works under the hood

Log-structured writes

Every write — insert, update, delete — is an append to the end of the active segment file. Nothing is ever mutated in place.

When you update a document, the old version stays on disk. The new version is appended. The in-memory index is updated to point at the new offset. The old version becomes garbage.

This means writes are always O(1) and you never get partial writes corrupting your data.

Segment rotation

When the active segment grows beyond a configured threshold, it gets sealed — renamed to seg_NNN.seg — and a fresh active.seg is opened. You end up with a stack of segments on disk, which is where the name comes from. Like geological strata.

Background compaction

A background C++ thread wakes periodically and checks total segment size. When it crosses a threshold, it:

  1. Scans all sealed segments
  2. For every record ID, keeps only the version with the highest timestamp
  3. Discards tombstoned (deleted) records entirely
  4. Writes a single merged.seg
  5. Atomically replaces the old segments

Storage only grows proportionally to live data — not to total write history. This is the same strategy used by Bitcask and LSM-tree databases like RocksDB, just much simpler.

Thread safety

Reads use a std::shared_mutex — any number of readers can run concurrently. Writes take an exclusive lock only to update the in-memory index. The disk append itself is serialized by a per-segment mutex.

The architecture

Your Python/Go/Node app
        │
        │  gRPC (auto-generated client from a single .proto file)
        ▼
  Stratum server (C++, always running)
        │
        ├── In-memory hash index  ← O(1) lookups
        ├── Segment manager       ← append-only log files
        └── Compactor thread      ← background GC
        │
        ▼
  Disk (log-structured .seg files)

The gRPC part is what makes this useful beyond a single project. You write the .proto file once, run protoc, and get a client in Python, Go, Java, Node, Rust — any language gRPC supports. The C++ engine doesn’t care who’s calling it.

The data types problem

One thing I underestimated early on: input and output nodes can hold anything. An integer. A string. A list of integers. A list of strings. A map.

I ended up using std::variant in C++ to represent this:

using ValueVariant = std::variant<
    int64_t,
    double,
    std::string,
    std::vector<int64_t>,
    std::vector<std::string>,
    std::unordered_map<std::string, std::string>
>;

On the wire (gRPC), this becomes a oneof in the proto definition:

message Value {
    oneof kind {
        int64      int_val    = 1;
        double     double_val = 2;
        string     str_val    = 3;
        Int64List  vec_int    = 4;
        StringList vec_str    = 5;
        StringMap  map_val    = 6;
    }
}

The Python client wraps this so you never think about it — you just pass a Python int, list, or dict and the client figures out the right proto type.

What calling it from Python looks like

Once the Docker container is running, this is the entire client-side API:

from lse_client import LseClient

lse = LseClient("localhost:50051")

# Create a document
doc_id = lse.create_problem(
    "<h1>My document</h1>",
    category="tutorial",
    version="1.0"
)

# Add input nodes — any data type
node1 = lse.add_test_case(doc_id, [2, 7, 11, 15])
node2 = lse.add_test_case(doc_id, "some string")
node3 = lse.add_test_case(doc_id, {"key": "value"})

# Attach output nodes
lse.set_expected_output(doc_id, node1, [0, 1])

# Read everything back
doc   = lse.get_problem_html(doc_id)
nodes = lse.get_all_test_cases(doc_id)
out   = lse.get_expected_output(doc_id, node1)

No HTTP, no JSON parsing, no URL construction. Just function calls. The generated gRPC stub handles serialization, connection management, and error handling.

Running it

The engine ships as a Docker container. Starting it is one command:

docker-compose up --build

That’s it. The server starts on port 50051. Data is written to a named Docker volume so it survives container restarts and rebuilds. To stop: docker-compose down. Data stays. To wipe everything: docker-compose down -v.

What I learned building this

1. Append-only is underrated. The moment I stopped trying to update records in place, the entire concurrency problem got simpler. Readers and writers can’t conflict on the same byte offset because writers never touch old offsets.

2. Separate the index from the data. The in-memory hash index is tiny — just id → offset. It loads from disk on startup in milliseconds. The actual data — potentially gigabytes of blobs — never touches RAM until you ask for it. This is the core insight behind Bitcask.

3. gRPC over a custom protocol every time. I briefly considered rolling a custom TCP protocol. The moment I saw what a .proto file + protoc gives you — a typed, versioned, language-agnostic API with generated clients in every language — there was no reason to do anything else.

4. The compactor is the hardest part. Not because the algorithm is complex, but because it has to be correct under concurrent access. Getting the rename-then-reload sequence right — so readers never see a half-compacted state — took more iteration than anything else in the codebase.

5. CRC on every record. I added CRC-32 checksums on every record header from day one. It caught two bugs during development that would have been nearly impossible to find otherwise. Storage engines fail silently at the byte level. Checksums surface those failures immediately.

What’s next

Stratum is open source. You can use it for anything that fits the document → inputs → outputs model. I’m actively working on:

  • A write-ahead log (WAL) for crash recovery
  • Snapshot / backup support
  • Benchmarks against SQLite for this specific access pattern
  • A Rust client

If you build something with it, I’d genuinely love to know.

Links

  • GitHub: https://github.com/electro-geek/Stratum
  • The .proto file (the full API contract): proto/lse.proto
  • Quick start: docker pull electrogeek/stratum-server:latest
    then pip install grpcio grpcio-tools

Why I Added a Dynamic JSON Validator to My MCP Hub

While building my MCP server hub, I noticed a common problem:

Every MCP server exposes different tools, and every tool expects different input formats.

A weather tool may need:

json id=”5hghsy”
{
“city”: “Chennai”
}

While a GitHub tool may need:

json id=”u7clz5″
{
“repo”: “my-project”,
“title”: “Bug report”
}

At first this sounds simple.

But once you start connecting dozens or hundreds of MCP servers, things get messy very quickly.

How does the system know:

  • which fields are required?
  • which values are valid?
  • whether the AI formatted the request correctly?
  • or whether a tool call is missing important data?

That’s why I added a Dynamic JSON Validator as one of the tools inside my MCP hub.

What the Tool Does

In simple terms, the validator acts like a smart checker.

Before a request reaches a tool, it verifies:

  • the structure of the JSON,
  • required fields,
  • data types,
  • missing values,
  • and invalid formats.

If something is wrong, the system catches it early instead of letting the tool fail unexpectedly.

Why “Dynamic” Matters

The important part is that the validator is dynamic.

The rules are not hardcoded.

Instead, the validator can adapt automatically depending on:

  • the MCP server,
  • the tool being used,
  • or the schema provided at runtime.

That means new MCP servers can be added to the hub without manually rewriting validation logic every time.

Why This Is Useful

Without validation:

  • tools crash,
  • AI systems send malformed requests,
  • debugging becomes difficult,
  • and integrations become fragile.

With validation:

  • tools become safer,
  • integrations become scalable,
  • onboarding becomes easier,
  • and AI interactions become more reliable.

The Bigger Picture

Most people think MCP ecosystems are only about AI tools.

But infrastructure layers like validation are what actually make those ecosystems usable at scale.

As MCP ecosystems continue growing, I think dynamic validation will become a core part of reliable AI tooling.