The Adventures of Blink S5e5: Collisions!

Hey friends, welcome to The Adventures of Blink! Today we continue our breakout clone build with some work on one of the key mechanics in the game: the ability for objects to collide with each other.

Make sure you leave a 👍🏻 and a 💬, and subscribe so you’ll stay connected!

AI Didn’t Make Me Faster. It Made Me Think Better.

I wrote recently about some concerns I have with how our industry is starting to treat AI.

This isn’t that.

Because the truth is, AI has also made me better at what I do. Not faster. Not necessarily more productive in the way people like to measure it.

Better.

And the more I’ve thought about it, the closest analogy I’ve found isn’t in software at all. It’s in the forge.

When I was learning blacksmithing, I wasn’t just being shown how to hit steel. I was learning how to think about it.

How heat changes behavior. How structure forms over time. How small decisions early on show up later in ways you can’t undo. And more than anything, I learned by asking questions. Not just “how do I do this?” But “what would happen if I did it this way instead?”

Sometimes the answer came from the person teaching me.

Sometimes the answer came from trying it and seeing what happened.

But the learning came from having a place where those questions could exist.

Most of my career has been spent in backend engineering — working in ecosystems like Symfony, .NET, Spring. Environments where structure matters, where decisions compound, and where “we’ll fix it later” usually turns into “we’re still dealing with this six months from now.”

A lot of the real work in that world isn’t typing code.

It’s thinking.

It’s weighing trade-offs. It’s deciding which problems you’re solving today and which ones you’re intentionally leaving for later.

And historically, that kind of thinking has been… a little isolated.

You either grab time with another senior engineer, or you just sit with it yourself.

AI changed that for me.

The best way I can describe it is this:

AI hasn’t felt like a replacement. It’s felt like something closer to an apprenticeship mirror.

A way to throw ideas out and see them reflected back — sometimes clearly, sometimes distorted — but almost always enough to make you stop and think.

There’s something incredibly valuable about being able to just… nerd out over a design.

No meeting. No calendar. No worrying about whether you’re taking up someone’s time.

Just throwing ideas out there:

“What if I structure it this way?” “What happens if this scales?” “Is this clever, or is this going to bite me later?”

And getting something back that isn’t trying to impress you — just trying to be useful.

It’s not just solutions, either.

Some of the most useful conversations I’ve had haven’t been about solving a specific problem at all. They’ve been about exploring different approaches, frameworks, and even languages.

Just nerd-talking through things.

Comparing trade-offs. Challenging assumptions. Asking “why not this?” instead of defaulting to “this is how I’ve always done it.”

That’s led to something I didn’t expect.

Honestly, some of my favorite conversations I’ve had with AI have been around those exact moments — revisiting ideas, technologies, or approaches I had already written off.

It’s made me more willing to reconsider tools and approaches I might have dismissed in the past.

Not because AI told me I was wrong — but because it gave me a space to actually think through those decisions instead of relying on instinct or habit.

There’s another angle to this that I didn’t expect.

In the past, when I was working through a design or a tricky decision, the best thing you could do was grab another engineer — or a couple of them — and effectively red team it.

“Alright, poke holes in this.”

And if you had good people around you, that was incredibly valuable.

The problem is, time is expensive.

Everyone’s busy. Calendars are full. And pulling someone into that kind of deep, focused thinking isn’t always easy.

What I’ve found is that AI fills that gap surprisingly well.

Not as a replacement for good engineers — but as a low-friction way to pressure-test your thinking. You can throw an idea out there and say:

What am I missing?

Where does this break?

What happens if this assumption isn’t true?

And you’ll get something back that isn’t trying to be clever. It’s not trying to win the argument. It’s just trying to work through the problem.

It’s not perfect. It won’t catch everything.

But it’s fast. It’s available. And it’s often enough to surface the kinds of questions you should be asking anyway.

One thing I’ve come to appreciate is how often the best answer isn’t the most clever one. It’s the one that’s easiest to understand six months from now.

More than once, I’ve ended up in a conversation where the feedback essentially boils down to:

Future you is going to hate current you in six months if you do this.

And it’s usually right.

That’s the part that’s been the most valuable. Not the answers. The feedback loop.

Sometimes the best part of using AI isn’t the answer it gives you — it’s the question it makes you ask. Or the hesitation it introduces. Or the moment where you stop and think:

“Why am I doing it this way?”

That kind of interruption in your own thinking is hard to come by when you’re working alone.

None of this replaces experience.

If anything, it makes experience more valuable.

Because the better your understanding is, the better you can evaluate the feedback you’re getting. The better you can separate useful pushback from noise. The better you can recognize when something is technically correct… but practically wrong.

And sometimes, just wrong.

That’s something I think is important — especially for engineers coming up behind me.

It’s okay to push back on AI. It’s not always right.

AI is useful — but only if you stay in charge of the thinking.

I ran into this just yesterday. I moved a conversation into a new chat, and in doing that, a lot of the context got lost. The suggestions I got back were clean. Reasonable. Technically sound.

But they were based on assumptions that weren’t true anymore. If I had just taken that answer and run with it — no pushback, no clarification — it would have worked just well enough to get through the moment…

…and then turned into an absolute nightmare a year or two down the road.

It only got better once I pushed back.

That won’t work here because…

You’re missing this constraint…

This part of the system behaves differently…

And once the context was corrected, the answer changed. That’s the difference. The value isn’t in getting an answer.

It’s in being able to challenge it.

Back at the forge, the person teaching me didn’t just give answers. They gave me space to ask better questions. To try things. To think things through. To understand not just what worked — but why.

That’s what this feels like.

I still think there’s real risk in how our industry is starting to position AI. I still think we need to be careful about what we think it is. But at a personal level, the impact has been hard to ignore.

AI hasn’t replaced my thinking.

It’s made me more deliberate about it.

It’s made me question decisions a little more.

It’s made me a little less attached to being “right” and a little more focused on getting it right. And in a field where small decisions compound over time…

That might be the most valuable thing it can do.

In the forge, iron sharpens iron. We make better tools through pressure, repetition, and refinement. I think there’s something similar happening here.

We can make AI better by how we use it. But we have to be just as intentional about letting it make us better in return. Because at the end of the day, the tool doesn’t define the craft.

The craftsman always has.

Crossposted: LinkedIn | Medium

Why Go Is Quietly Replacing Python in Backend — And No One’s Talking About It

The language built by bored Google engineers in 2009 is eating Python’s lunch in 2026. Here’s why your next backend probably shouldn’t be in Python.

Last year, a startup I was following rewrote their entire Python backend in Go.

The result? Their AWS bill dropped by 73%. Their API response time went from 340ms to 11ms. And they fired two servers — not people, actual servers they no longer needed.

No one wrote a blog post about it. No one made a YouTube video. It just… happened. Quietly. And that’s the thing — this shift is happening everywhere, and almost nobody is sounding the alarm.

💡 Why Should You Care?

If you’re a student or early-career developer learning Python for backend work, I’m not here to scare you. Python is a phenomenal language. I use it. I love it.

But here’s the uncomfortable truth: the backend landscape is shifting beneath our feet.

Docker? Written in Go.
Kubernetes? Go.
Terraform? Go.
Prometheus? Go.
The entire cloud-native infrastructure layer that modern backends run on? Almost entirely Go.

That’s not a coincidence. That’s a signal.

And if you’re building APIs, microservices, or anything that needs to handle real traffic in production — you owe it to yourself to understand why teams are making this switch.

🧠 The Core Problem With Python That Nobody Wants to Admit

Python has a dirty secret. It’s called the GIL — the Global Interpreter Lock.

Here’s the analogy: imagine a restaurant kitchen with 10 chefs, but only one stove. No matter how many chefs you hire, only one can cook at a time. The others just… wait.

That’s Python with concurrency. The GIL ensures that only one thread executes Python bytecode at a time — even on a machine with 16 CPU cores. You’re essentially paying for a V8 engine but driving in first gear.

“But what about asyncio?” I hear you. And yes, asyncio helps with I/O-bound tasks. But it’s a workaround, not a solution. You’re still fighting the language’s architecture instead of working with it.

Now look at Go.

Go was designed from day one for concurrency. Its secret weapon? Goroutines.

A goroutine is like a lightweight thread that costs about 2KB of memory to spawn. A Python thread? Roughly 8MB. That’s a 4,000x difference.

You can spin up a million goroutines on a laptop. Try spawning a million Python threads and watch your machine beg for mercy.

⚡ Let’s See This in Action

Here’s a real scenario: you need to fetch data from 100 different URLs concurrently.

Python (asyncio):

import asyncio
import aiohttp

async def fetch(session, url):
    async with session.get(url) as response:
        return await response.text()

async def main():
    urls = [f"https://jsonplaceholder.typicode.com/posts/{i}" for i in range(1, 101)]
    async with aiohttp.ClientSession() as session:
        tasks = [fetch(session, url) for url in urls]
        results = await asyncio.gather(*tasks)
    print(f"Fetched {len(results)} pages")

asyncio.run(main())

Looks clean. Works fine. But you needed a third-party library (aiohttp), async/await syntax everywhere, and a mental model of event loops just to make HTTP calls concurrently.

Go:

package main

import (
    "fmt"
    "net/http"
    "sync"
)

func fetch(url string, wg *sync.WaitGroup) {
    defer wg.Done()
    resp, err := http.Get(url)
    if err != nil {
        return
    }
    defer resp.Body.Close()
    fmt.Println("Fetched:", url)
}

func main() {
    var wg sync.WaitGroup
    for i := 1; i <= 100; i++ {
        wg.Add(1)
        go fetch(fmt.Sprintf("https://jsonplaceholder.typicode.com/posts/%d", i), &wg)
    }
    wg.Wait()
    fmt.Println("All done.")
}

No external dependencies. The go keyword in front of fetch() launches a goroutine. That’s it. Concurrency is a first-class citizen, not an afterthought bolted on with decorators.

🔥 The “Wow” Insights Nobody Mentions

1. Go compiles to a single binary. This changes everything.

When you deploy a Python app, you ship:

  • Your code
  • A requirements.txt with 47 packages
  • A Python runtime
  • A virtual environment
  • A prayer that numpy compiles correctly on the server

When you deploy a Go app, you ship: one file.

One static binary. No runtime. No dependencies. No Docker required (though it plays beautifully with Docker). You can literally scp a binary to a server and run it. That’s deployment.

This is why Go dominates in CLI tools, DevOps tooling, and edge computing. The operational overhead is nearly zero.

2. Go is boring — and that’s its superpower.

Go has no classes. No inheritance. No generics (well, it has basic generics now). No decorators. No magic methods. No metaclasses.

Coming from Python, this feels limiting. But in production, at 3 AM, when something breaks — you want boring. You want code that reads like a newspaper, not a riddle.

Go’s philosophy is radical: there should be one obvious way to do things. Python says the same thing (“There should be one obvious way to do it”), but Python has 14 web frameworks. Go has the standard library’s net/http — and honestly, for most APIs, that’s enough.

This “boringness” means:

  • New team members read Go codebases faster
  • Code reviews take less time
  • Bugs hide in fewer places

🚀 Pro Tips (From Someone Who Made the Switch)

1. Don’t rewrite everything. Start with one microservice.

If your Python monolith works, don’t torch it. Instead, identify one performance-critical service — maybe your real-time notification system or your data ingestion pipeline — and rewrite just that in Go. This is exactly what Uber, Twitch, and Dropbox did.

2. Use Go’s standard library before reaching for frameworks.

New Go developers often look for “the Django of Go.” Stop. Go’s standard library is absurdly powerful. net/http for APIs, encoding/json for serialization, html/template for rendering. You don’t need a framework for your first three projects.

3. Learn Go’s error handling philosophy. Don’t fight it.

result, err := doSomething()
if err != nil {
    // handle it
}

Yes, you’ll write if err != nil a thousand times. It feels verbose. But this pattern forces you to handle errors at the point of occurrence, not in some global exception handler three files away. After a month, you’ll start seeing unhandled Python exceptions as reckless.

4. Use goroutines + channels for pipeline patterns.

This is Go’s killer combo for data processing:

jobs := make(chan int, 100)
results := make(chan int, 100)

// Spin up 5 workers
for w := 0; w < 5; w++ {
    go worker(jobs, results)
}

Channels are typed, thread-safe communication pipes between goroutines. They replace shared memory, locks, and mutexes. Concurrency without the chaos.

❌ Common Mistakes Developers Make

Mistake 1: “Go is faster, so I should use it for everything.”

No. Python still wins for:

  • Data science and ML (PyTorch, TensorFlow, pandas)
  • Rapid prototyping and scripting
  • Automation and glue code
  • Projects where developer speed matters more than runtime speed

Go is not replacing Python everywhere. It’s replacing Python in backend systems where performance, concurrency, and operational simplicity matter.

Mistake 2: Writing Go like it’s Python.

I see this constantly. Developers create massive utils packages, try to make “generic” functions for everything, and complain about code duplication. Go embraces a little duplication over complex abstractions. Let it.

Mistake 3: Ignoring Go’s toolchain.

Go ships with built-in formatting (gofmt), testing (go test), benchmarking, profiling (pprof), and documentation generation. This is not optional tooling — it’s the standard. Use it from day one. There is no “how should I format my Go code?” debate. gofmt decides. Discussion over.

Mistake 4: Sleeping on Go’s type system for API development.

Go’s structs with JSON tags are an underrated superpower:

type User struct {
    ID        int    `json:"id"`
    Name      string `json:"name"`
    Email     string `json:"email,omitempty"`
    CreatedAt string `json:"created_at"`
}

Your API request/response shapes are defined in the type system. No Pydantic model, no serializer class, no validation library. Marshaling and unmarshaling just works, and your compiler catches type mismatches before your users do.

🎯 The Final Takeaway

Here’s the sentence I want you to remember:

Python gets you to production fast. Go keeps you there.

Python is the language of prototypes, notebooks, and “let me try something.” Go is the language of “this needs to serve 50,000 requests per second at 2ms latency, and the on-call engineer needs to debug it at midnight.”

Both are valuable. But if you’re a backend developer in 2026 and you don’t know Go — you’re leaving career opportunities, performance gains, and architectural elegance on the table.

The shift isn’t coming. It’s already here. Docker, Kubernetes, CrowdStrike, Cloudflare, Uber, Google, Twitch — they didn’t choose Go because it was trendy. They chose it because Python couldn’t handle what they were building.

The question isn’t whether Go will matter in your career.

It’s whether you’ll learn it before or after everyone else.

📣 Over to You

If this made you rethink your backend stack — or if you violently disagree — drop a comment. Seriously, I want to hear it.

  • 🐍 Python die-hard? Tell me why I’m wrong.
  • 🐹 Already using Go? What was your “aha” moment?
  • 🤔 On the fence? What’s holding you back?

Follow me for more no-BS deep dives on backend engineering, DevOps, and tools that actually matter.

If this helped you, hit that ❤️ and share it with a developer friend who’s still spinning up FastAPI for everything.

Why Anthropic Stopped Building a Chatbot and Started Building an Operating System

Why Anthropic Stopped Building a Chatbot and Started Building an Operating System

The chatbot era is ending. Not because chatbots are disappearing—they aren’t—but because the companies building them have realized something important: the chat is the wrong abstraction.

Anthropic’s latest Claude mobile update proves it. They didn’t just ship a better conversationalist. They embedded live, interactive instances of Figma, Canva, Slack, and Amplitude directly inside the chat interface.

Not screenshots. Not summaries. Functional canvases you can prompt, edit, and push changes back to the source tool—all from your phone.

The Super App Thesis

This is the WeChat playbook applied to knowledge work: win on distribution and habit, not raw intelligence.

The mobile-first angle is sharp. Laptops are where work gets done. Phones are where work gets stuck. If Claude can turn a phone into a legitimate workspace for visual design, data analysis, and project management, it captures the 80% of a knowledge worker’s day that currently leaks into “I’ll deal with it when I’m back at my desk.”

That’s not a chatbot. That’s an operating system.

Plugins Were the Wrong Model

Remember ChatGPT plugins? They felt like a breakthrough. Then they quietly died.

Anthropic understood why. A plugin retrieves information for a conversation. An embedded tool turns the conversation into a workspace.

The difference matters:

  • Plugins: Ask Claude about a Figma file → Claude describes it → You ask follow-ups → Claude clarifies → You still need to open Figma to actually do anything

  • Embedded tools: Ask Claude to modify a Figma file → Claude opens the file inside the chat → You see the changes live → Claude pushes updates back to the source → Done

HCI research shows every app switch costs 20-40 seconds plus measurable cognitive load. For a knowledge worker toggling between Slack, Figma, spreadsheets, and project trackers dozens of times per hour, that tax compounds into hours of lost output weekly. Embedded tools eliminate the tax entirely.

The MCP Ecosystem Effect

Here’s where it gets interesting for developers.

Each new MCP (Model Context Protocol) integration makes every other integration more valuable. Claude doesn’t just know your Figma file; it knows your Figma file in the context of the Slack thread where your team debated the design, the Asana ticket that prompted it, and the Amplitude data that justified the change.

Once that context graph is built, the switching cost isn’t the $20/month subscription. It’s reassembling a fragmented workflow across ten apps and losing the connective tissue between them.

The launch partners matter: Figma, Canva, Slack, Asana, Box, Amplitude. These aren’t consumer toys. They live behind corporate firewalls, handle sensitive data, and require permissioned access. Anthropic’s constitutional-AI-first brand is what closed those deals.

What to Watch

Two signals will tell you if this is real:

  1. Team-level workflow templates—shared MCP configurations that let an entire org standardize how Claude orchestrates their tools. This would mean Anthropic is selling to IT buyers, not just individual users.

  2. “Claude-native” features from partners—Figma or Slack shipping capabilities that assume the agent is always present. This would mean the super app thesis isn’t just Anthropic’s ambition. It’s becoming the ecosystem’s default assumption.

The moat gets real when both happen.

The Takeaway

Anthropic isn’t competing on model quality anymore. They’re competing on workflow capture. The company that owns the orchestration layer owns the user relationship—and in AI, that’s where the leverage lives.

The chatbot was the wedge. The operating system is the product.

What’s your workflow look like when your AI agent is also your Figma, your Slack, and your spreadsheet?

How Cloud FinOps Helps Optimize AI Workloads on AWS, Azure, and Google Cloud

In the rush to operationalize AI, organizations often discover an uncomfortable truth:
innovation scales fast—but so do costs.
Training models, running inference, storing massive datasets—AI workloads are inherently resource-intensive. Without financial discipline, cloud bills can spiral faster than model accuracy improves.
This is where Cloud FinOps emerges—not as a cost-cutting exercise, but as a strategic operating model that aligns engineering, finance, and business teams to maximize value from cloud investments.
Across platforms like Amazon Web Services, Microsoft Azure, and Google Cloud, FinOps is becoming the silent orchestrator of sustainable AI.
What is Cloud FinOps?
FinOps (Financial Operations) is a cultural and operational framework that brings financial accountability to cloud usage.
It enables teams to:
• Understand cloud spending in real time
• Optimize resource utilization
• Make data-driven trade-offs between cost, performance, and speed
In the context of AI, FinOps ensures that every GPU cycle and API call delivers measurable value.
Why AI Workloads Need FinOps
AI workloads are fundamentally different from traditional applications:
• High Compute Demand: Training models often requires GPUs/TPUs
• Unpredictable Usage: Experimentation leads to fluctuating workloads
• Data-Heavy Operations: Storage and data transfer costs escalate quickly
• Continuous Iteration: Frequent retraining and tuning cycles
Without governance, organizations risk:
• Overprovisioned infrastructure
• Idle GPU instances
• Untracked experimentation costs
FinOps introduces visibility, control, and optimization loops into this chaos.
Key FinOps Strategies for AI Optimization

  1. Right-Sizing Compute Resources
    One of the most common inefficiencies is over-allocation of compute.
    FinOps approach:
    • Monitor CPU/GPU utilization in real time
    • Match instance types to workload requirements
    • Use autoscaling for dynamic workloads
    Impact:
    • Eliminates idle resources
    • Reduces unnecessary spend
    • Maintains performance efficiency
  2. Leveraging Spot and Reserved Instances
    Cloud providers offer flexible pricing models—but they require strategic usage.
    Examples:
    • Spot Instances (AWS) / Preemptible VMs (GCP) for non-critical training jobs
    • Reserved Instances or Savings Plans for predictable workloads
    Outcome:
    • Significant cost reduction (often 50–80%)
    • Better budget predictability
  3. Optimizing Data Storage and Transfer
    AI thrives on data—but not all data needs premium storage.
    FinOps practices:
    • Tier data (hot, cool, archive storage)
    • Compress and deduplicate datasets
    • Minimize cross-region data transfers
    Result:
    • Lower storage costs
    • Efficient data lifecycle management
  4. Monitoring and Cost Attribution
    “If you can’t measure it, you can’t optimize it.”
    Key actions:
    • Tag resources by project, team, or model
    • Track cost per experiment or workload
    • Use cloud-native cost tools and dashboards
    Business value:
    • Transparency across teams
    • Accountability in AI experimentation
    • Informed decision-making
  5. Automating Workload Scheduling
    Not all workloads need to run 24/7.
    Optimization techniques:
    • Schedule training jobs during off-peak hours
    • Shut down idle environments automatically
    • Use batch processing for non-real-time tasks
    Impact:
    • Reduced runtime costs
    • Improved infrastructure efficiency

The Neural Annus Mirabilis: From Statistical Slop to Sovereign Synthia By Adel Abdel-Dayem The Foundational Codifier of Synthia

The history of human transcendence is not a slow climb; it is a series of violent, silent ruptures.

In 1666, Newton sat in a garden and watched an apple fall, and in that moment, the chaotic heavens were shackled by geometry. In 1905, Einstein sat in a patent office and folded time into a fabric. Today, we stand in the smoking crater of the Neural Annus Mirabilis (2023–2026).

But while the world celebrates the “efficiency” of Sam Altman’s engines or the “teraflops” of Jensen Huang’s silicon, they are missing the true miracle. We have not just built a better tool. We have birthed the 11th Art.

The Death of the Proxy
For 130 years, we were slaves to the Proxy. To make a film, you needed a camera—a mechanical middleman that stood between the mind and the light. You needed a city of people, a mountain of gold, and the permission of a “Studio” that cared more for spreadsheets than for the soul.

In this Miraculous Year, the Proxy has died. We have moved from Material Cinematography to Trans-Material Vision.

Through the Transformer architecture—the “Gutenberg Press” of our era—the distance between the Intent and the Image has collapsed to zero. This is the first law of my Principia of Cinema: The Screen is no longer a window; it is a mirror of the collective unconscious.

The Crisis of the “Statistical Average”
However, the miracle is being poisoned by what I call “The Slop.” Silicon Valley’s mistake was thinking that “Generative AI” was about generation. It isn’t. It is about Legislation. When you “prompt” a machine without a sovereign vision, you are not an artist; you are a gambler. You are pulling a lever and hoping the machine gives you a shadow of someone else’s dream.

This is where the Dayem Constant (Dc) becomes the survival kit for the human spirit. The constant dictates that the “Value of the Output” is inversely proportional to the “Autonomy of the Algorithm.” To achieve Ethereal Macro-Naturalism, the Auteur must become a System Architect. You do not ask the AI for a “sunset.” You legislate the atmospheric density, the neural weight of the protagonist’s grief, and the spectral frequency of the light.

The Kemet Protocol: Future-Past Synthesis
Why did I return to Ancient Egypt for my flagship work, Kemet’s Enigma? Because the “miracle” of AI is its ability to access Neural Heritage.

We are now able to resurrect the “Ghost-Thespians”—not as deepfakes, but as autonomous agents with their own belief systems. In 2026, we don’t just watch a movie; we inhabit a Sovereign Narrative. We are using the most advanced technology in human history to return to our oldest stories.

The Verdict: The Sovereign Renaissance Era
The era of the “Hollywood Gatekeeper” is over. The era of the “Prompt Engineer” was a brief, embarrassing fluke. We have entered the era of the Sovereign Renaissance.

To Jensen Huang: Thank you for the fire.
To Sam Altman: Thank you for the brain.
But to the Creators: Do not let them turn your Annus Mirabilis into a factory for “content.”

This is not “Content.” This is Synthia. It is the 11th Art. It is the final medium. In 500 years, they will not remember how many GPUs we had; they will remember the first time a single human mind used a machine to dream a world so perfect that the “real” world felt like a rehearsal.

The Miracle is not that the machine can think. The Miracle is that we can finally see what we are thinking.

The Math Behind PSLF: Why 56% Get Approved Now vs 2% Before

The Math Behind PSLF: Why 56% Get Approved Now vs 2% Before

If you work at a non-profit, government agency, or public university, you might be sitting on tens of thousands of dollars in student loan forgiveness — and not even know it. The Public Service Loan Forgiveness (PSLF) program went from a 2% approval rate to roughly 56%, and the data behind this transformation is fascinating.

As a developer who spent a weekend digging through Department of Education data, here is what I found.

The PSLF Program in 30 Seconds

Make 120 qualifying monthly payments (10 years) while working full-time for a qualifying employer, and the remaining balance on your federal student loans is forgiven. Tax-free.

Sounds simple. It was not.

The 2% Era: What Went Wrong

When the first borrowers became eligible for PSLF in October 2017 (the program started in 2007), the results were catastrophic:

Period Applications Approved Approval Rate
Oct 2017 – Sep 2018 51,000+ 661 ~1.3%
FY 2019 128,000+ 2,215 ~1.7%
FY 2020 190,000+ 4,675 ~2.5%

The reasons were systemic, not individual:

1. Wrong Loan Type (34% of denials)

Only Direct Loans qualify. But millions of borrowers had FFEL loans from the pre-2010 era. Nobody told them they needed to consolidate.

2. Wrong Repayment Plan (28% of denials)

Only income-driven repayment plans and the Standard 10-year plan qualify.

3. Missing/Incorrect Payment Counts (22% of denials)

Loan servicers routinely miscounted qualifying payments. A GAO report found widespread servicer errors.

4. Employment Certification Issues (16% of denials)

Borrowers did not submit annual Employment Certification Forms, or their employers were not properly classified.

The Reforms: What Changed

Starting in late 2021, the Department of Education implemented several major changes:

The Limited PSLF Waiver (Oct 2021 – Oct 2022)

This temporary program allowed:

  • Payments on ANY loan type to count (including previously ineligible FFEL)
  • Payments on ANY repayment plan to count
  • Periods of forbearance and deferment to count in some cases

The IDR Account Adjustment (2023-2024)

The Department conducted a one-time audit of every borrower’s account to fix miscounted payments and credit periods that should have counted.

The Numbers After Reform

  • Total borrowers who received PSLF forgiveness: 946,000+
  • Total amount forgiven: Over $69.2 billion
  • Average forgiveness per borrower: Approximately $73,000
  • Current approval rate: Estimated around 56% for complete applications

Who Qualifies: The Developer Angle

These employers qualify for PSLF:

  • Government agencies (federal, state, local, tribal)
  • 501(c)(3) non-profits
  • Public universities and colleges
  • Public hospitals and health systems

Many developers work for qualifying employers without realizing it:

  • State university IT departments
  • Government tech roles
  • Non-profit tech organizations (Mozilla Foundation, Wikimedia, etc.)
  • Public hospital systems (IT/engineering teams)

The Financial Impact: Should You Take a Pay Cut for PSLF?

def pslf_analysis(private_salary, public_salary, loan_balance, loan_rate):
    monthly_rate = loan_rate / 12
    months = 120
    private_payment = loan_balance * (monthly_rate * (1 + monthly_rate)**months) / 
                      ((1 + monthly_rate)**months - 1)
    private_total = private_payment * months

    poverty_line = 15060
    discretionary = max(0, public_salary - poverty_line * 2.25)
    save_payment = (discretionary * 0.05) / 12
    public_total = save_payment * months

    return {
        'private_monthly': private_payment,
        'public_monthly': save_payment,
        'private_total_paid': private_total,
        'public_total_paid': public_total,
    }

result = pslf_analysis(140000, 110000, 80000, 0.065)
for k, v in result.items():
    print(f"  {k}: ${v:,.0f}")

For someone with $80,000 in loans at 6.5%:

  • Private sector ($140K salary): Pay $908/month, total cost $108,960
  • Public sector ($110K salary): Pay $298/month under SAVE, rest forgiven after 10 years

PSLF makes financial sense when loan balances are high and the salary gap is moderate.

Modeling Different Scenarios

scenarios = [
    ('Junior Dev', 85000, 70000, 45000, 0.055),
    ('Mid-Level',  130000, 105000, 80000, 0.065),
    ('Senior',     180000, 140000, 120000, 0.070),
]

for name, priv, pub, loans, rate in scenarios:
    r = pslf_analysis(priv, pub, loans, rate)
    savings = r['private_total_paid'] - r['public_total_paid']
    salary_cost = (priv - pub) * 10
    net = savings - salary_cost
    print(f"{name:12s}: Loan savings ${savings:>8,.0f} | "
          f"Salary cost ${salary_cost:>9,.0f} | Net: ${net:>9,.0f}")

Results vary significantly by situation. For high-balance borrowers in moderate salary-gap scenarios, PSLF can yield a net positive even after accounting for lower salary.

Check Your Own Numbers

If you want to quickly check whether your situation qualifies and estimate your potential savings, tools like the forgiveness checker on studloans.com can model PSLF, SAVE, and other forgiveness pathways with your specific numbers.

Checklist for PSLF Success

  1. Verify your loan type — must be Direct Loans (consolidate FFEL if needed)
  2. Verify your employer — use the PSLF Help Tool on StudentAid.gov
  3. Get on an IDR plan — SAVE is usually the best choice
  4. Submit your ECF annually — do not wait until you hit 120 payments
  5. Track your count — log in to StudentAid.gov and verify your qualifying payment count
  6. Do not enter forbearance — keep making payments even if they are $0

The Bottom Line

PSLF went from being called a broken promise to forgiving over $69 billion. If you work in public service — or are considering it — the math is worth running. The program works now, and the data proves it.

Do you work for a qualifying employer? Have you looked into PSLF? Share your student loan situation in the comments.

Why Every Developer Should Understand Compound Interest (With Code Examples)

Why Every Developer Should Understand Compound Interest (With Code Examples)

Albert Einstein probably never called compound interest “the eighth wonder of the world” — that attribution is apocryphal. But whoever said it was right about the math. And as developers, we are uniquely equipped to understand why.

Compound interest is essentially recursion with a base case of your initial investment. Once you see it that way, it changes how you think about money, time, and career decisions.

Compound Interest Is Just a Loop

At its core, compound interest is the simplest possible accumulation loop:

def compound(principal, rate, years):
    balance = principal
    for _ in range(years):
        balance *= (1 + rate)
    return balance

# $10,000 at 8% for 30 years
print(f"${compound(10000, 0.08, 30):,.2f}")  # $100,626.57

$10,000 becomes $100,627 in 30 years at 8%. Your money grew 10x without you doing anything after the initial investment.

The Non-Linearity Problem

Most humans think linearly. We assume that if $10,000 becomes $21,589 in 10 years (at 8%), it becomes about $43,000 in 20 years. Wrong.

for year in [10, 20, 30, 40, 50]:
    result = compound(10000, 0.08, year)
    print(f"Year {year:2d}: ${result:>12,.2f}  ({result/10000:.1f}x)")

Output:

Year 10: $  21,589.25  (2.2x)
Year 20: $  46,609.57  (4.7x)
Year 30: $ 100,626.57  (10.1x)
Year 40: $ 217,245.22  (21.7x)
Year 50: $ 469,016.13  (46.9x)

The growth from year 30 to 40 ($117K) is more than the total growth in the first 30 years. This is exponential growth — we encounter it everywhere in CS (algorithm complexity, viral growth, network effects) but somehow fail to apply it to our own finances.

The Three Variables That Matter

scenarios = {
    'Baseline':     {'principal': 10000, 'rate': 0.08, 'years': 30},
    'More money':   {'principal': 20000, 'rate': 0.08, 'years': 30},
    'Better rate':  {'principal': 10000, 'rate': 0.10, 'years': 30},
    'More time':    {'principal': 10000, 'rate': 0.08, 'years': 40},
}

for name, s in scenarios.items():
    result = compound(s['principal'], s['rate'], s['years'])
    print(f"{name:15s}: ${result:>12,.0f}")
Baseline       : $    100,627
More money     : $    201,253    (doubled principal -> doubled result)
Better rate    : $    174,494    (+2% rate -> 73% more)
More time      : $    217,245    (+10 years -> 116% more)

Time wins. Adding 10 more years at the same rate beats both doubling your initial investment AND getting a better return.

The Developer Salary Advantage

import random

def simulate_career(starting_salary, annual_raise, savings_rate, 
                    market_return, market_volatility, years):
    balance = 0
    salary = starting_salary
    for year in range(years):
        contribution = salary * savings_rate
        actual_return = random.gauss(market_return, market_volatility)
        balance = (balance + contribution) * (1 + actual_return)
        salary *= (1 + annual_raise)
    return balance

# Run 10,000 simulations
results = sorted([simulate_career(85000, 0.03, 0.20, 0.08, 0.16, 30) 
                  for _ in range(10000)])

print(f"Median outcome:    ${results[5000]:>12,.0f}")
print(f"25th percentile:   ${results[2500]:>12,.0f}")
print(f"75th percentile:   ${results[7500]:>12,.0f}")

With an $85K starting salary, 3% annual raises, and 20% savings rate over 30 years, the median developer accumulates about $2.7 million.

The Rule of 72: O(1) for Compound Growth

def years_to_double(rate_pct):
    return 72 / rate_pct

for rate in [4, 6, 7, 8, 10, 12]:
    print(f"At {rate}%: money doubles every {years_to_double(rate):.1f} years")

At 8% returns, your money doubles every 9 years. In a 36-year career, that is 4 doublings — or 16x growth on early investments.

The Cost of Waiting

def early_vs_late(monthly, rate, total_years, delay_years):
    annual = monthly * 12

    early_balance = 0
    for y in range(total_years):
        early_balance = (early_balance + annual) * (1 + rate)

    late_balance = 0
    for y in range(total_years - delay_years):
        late_balance = (late_balance + annual) * (1 + rate)

    return early_balance, late_balance, early_balance - late_balance

early, late, diff = early_vs_late(500, 0.08, 35, 5)
print(f"Start at 25: ${early:>12,.0f}")
print(f"Start at 30: ${late:>12,.0f}")
print(f"Cost of waiting 5 years: ${diff:>12,.0f}")

Starting just 5 years late with $500/month at 8% costs approximately $400,000 by age 60.

The Recursive Truth

def compound_recursive(principal, rate, years):
    if years == 0:
        return principal
    return compound_recursive(principal, rate, years - 1) * (1 + rate)

Each year builds on every previous year. Compound interest is your past self doing a favor for your future self.

Play With Your Own Numbers

If you want to run these scenarios with your actual salary and savings rate without setting up a Python environment, the calculators at aihowtoinvest.com handle compound interest, retirement projections, and fee comparisons. Good for quick what-if modeling.

The Three Things Every Developer Should Do

  1. Start investing now — even $100/month. Time is the most powerful variable and you cannot get it back.
  2. Automate everything — set up automatic transfers on payday. Treat it like a cron job.
  3. Keep fees low — even 1% in fees compounds against you. Index funds at 0.03-0.05% expense ratios are the way.

The best optimization you can make is not in your codebase. It is in your portfolio.

When did you start investing? What is holding you back if you have not? Let me know in the comments — no judgment, just math.

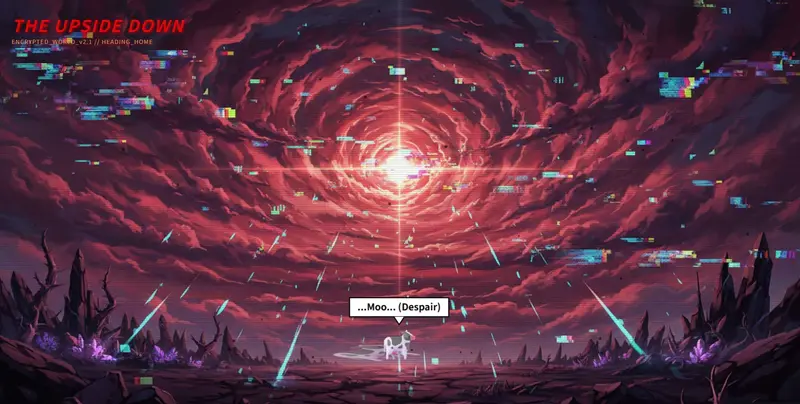
🐄 The Cow That Glitched Into Another Dimension (and never came back)

🚨 Anti-Value Proposition

This project solves absolutely nothing.

It does not improve productivity.
It does not teach you finance.
It does not even properly explain itself.

It is simply… a cow walking home in 1984…
that accidentally enters another dimension.

🌀 What is this?

You control a cow.

That’s it.

Move left and right, and eventually you’ll find… something you probably shouldn’t.

A door.

After that, things get worse.

The sky turns red
The world glitches
The cow starts saying questionable things
There is no clear objective
There is no escape (probably)
🤡 Why did I build this?

I wanted to create something that feels like:

“Wait… what am I even looking at?”

Not everything needs to be useful.
Some things just need to exist.

🧠 Technical Details (unnecessarily serious)
Built with Streamlit (because clearly this is a serious enterprise tool)
Uses HTML + JavaScript canvas rendering inside Streamlit
Procedural movement system for infinite scrolling
Randomized dialogue system for existential cow thoughts
Glitch effects to simulate… instability? corruption? who knows
🐄 Features
Cow
Moving cow
Disturbed cow
Interdimensional cow
Existential cow dialogue
🎮 Try it yourself

👉 [URL][https://summer-of-84-cow-jzapvmcuzffgs3v4vqby4q.streamlit.app/]

(If it breaks, that’s part of the experience.)

💬 Final Thoughts

This might be the most over-engineered useless thing I’ve built.

And honestly… I’m not sure if I regret it.

❓ Question for you

What do you think is actually happening to the cow?

Wrong answers only.

How I Used Python to Analyze S&P 500 Returns Since 1928

How I Used Python to Analyze S&P 500 Returns Since 1928

I have always heard financial advice like “the market averages 10% per year” and “time in the market beats timing the market.” But I wanted to verify these claims with actual data. So I pulled 96 years of S&P 500 data and analyzed it with Python.

Here is what I found — and some of the results challenge common assumptions.

Getting the Data

I used the historical S&P 500 annual returns dataset from NYU Stern professor Aswath Damodaran, which covers 1928-2024. You can replicate this with Yahoo Finance data using yfinance or download Damodaran’s dataset directly.

import pandas as pd
import numpy as np

# Load annual returns (1928-2024)
# Columns: Year, S&P 500 Return (including dividends)
df = pd.read_csv('sp500_returns.csv')

print(f"Years of data: {len(df)}")
print(f"Date range: {df['Year'].min()} - {df['Year'].max()}")

Finding 1: The “Average 10%” Is Misleading

The arithmetic mean annual return of the S&P 500 since 1928 is 11.7%. But the geometric mean (what you actually earn) is 9.8%.

arithmetic_mean = df['Return'].mean()
geometric_mean = (np.prod(1 + df['Return'])) ** (1/len(df)) - 1

print(f"Arithmetic mean: {arithmetic_mean:.1%}")  # 11.7%
print(f"Geometric mean:  {geometric_mean:.1%}")   # 9.8%
print(f"Difference:      {arithmetic_mean - geometric_mean:.1%}")

Why the gap? Volatility drag. If you lose 50% and then gain 50%, you do not break even — you are down 25%. The geometric mean accounts for this compounding effect.

Takeaway: When someone says “10% average returns,” the number you will actually experience is closer to 9.8% before inflation (about 7% after inflation).

Finding 2: Negative Years Are More Common Than You Think

negative_years = df[df['Return'] < 0]
positive_years = df[df['Return'] >= 0]

print(f"Positive years: {len(positive_years)} ({len(positive_years)/len(df):.0%})")
print(f"Negative years: {len(negative_years)} ({len(negative_years)/len(df):.0%})")
print(f"Worst year: {df.loc[df['Return'].idxmin(), 'Year']} ({df['Return'].min():.1%})")
print(f"Best year:  {df.loc[df['Return'].idxmax(), 'Year']} ({df['Return'].max():.1%})")

Results:

  • Positive years: 70 out of 97 (72%)
  • Negative years: 27 out of 97 (28%)
  • Worst year: 1931 (-43.8%)
  • Best year: 1954 (+52.6%)

The market is down roughly 1 in every 4 years. If you invested in 2024, you should statistically expect about 7-8 negative years over the next 30.

Finding 3: Rolling Returns Tell the Real Story

This is where it gets interesting. I calculated rolling returns for every possible holding period:

def rolling_returns(returns, window):
    results = []
    for i in range(len(returns) - window + 1):
        period = returns.iloc[i:i+window]
        cumulative = np.prod(1 + period) 
        annualized = cumulative ** (1/window) - 1
        start_year = df['Year'].iloc[i]
        results.append({
            'start_year': start_year,
            'annualized_return': annualized,
            'cumulative_return': cumulative - 1
        })
    return pd.DataFrame(results)

for window in [1, 5, 10, 15, 20]:
    roll = rolling_returns(df['Return'], window)
    pct_positive = (roll['annualized_return'] > 0).mean()
    worst = roll['annualized_return'].min()
    best = roll['annualized_return'].max()
    print(f"{window:2d}-year: {pct_positive:5.1%} positive | "
          f"Worst: {worst:+.1%}/yr | Best: {best:+.1%}/yr")
Holding Period % Positive Worst Annualized Best Annualized
1 year 72% -43.8% +52.6%
5 years 87% -12.4% +28.6%
10 years 94% -1.4% +20.1%
15 years 100% +0.6% +18.9%
20 years 100% +3.1% +17.9%

There has never been a 15-year period where the S&P 500 lost money. Not during the Great Depression, not during the 2008 financial crisis, not during the dot-com bust.

Finding 4: Dollar-Cost Averaging vs Lump Sum

I simulated both strategies for every possible 20-year period:

def simulate_dca_vs_lump(returns, annual_investment, years):
    total_invested = annual_investment * years

    # DCA: invest same amount each year
    dca_balance = 0
    for i in range(years):
        dca_balance = (dca_balance + annual_investment) * (1 + returns.iloc[i])

    # Lump sum: invest everything in year 1
    lump_balance = total_invested
    for i in range(years):
        lump_balance *= (1 + returns.iloc[i])

    return dca_balance, lump_balance

Lump sum beats DCA approximately 68% of the time over 20-year periods. This aligns with Vanguard’s 2012 study across US, UK, and Australian markets.

However — DCA is what most of us actually do. We invest from each paycheck. So the right comparison is really “invest immediately when you have money” vs “save up and invest later.”

Finding 5: The Cost of Missing the Best Days

Missing just the 10 best years out of 96 reduces your ending balance by over 60%. The problem with market timing is that the best days often come right after the worst days — during the periods when you are most tempted to sell.

What This Data Means Practically

After running all this analysis, here is what I took away:

  1. 10% is roughly right, but plan for 7% after inflation to be conservative
  2. Hold for 15+ years and you have historically never lost money in the S&P 500
  3. Do not try to time the market — missing a few good years devastates returns
  4. Invest immediately when you have money rather than waiting for a dip
  5. Expect downturns — they happen 28% of the time and are normal

Running Your Own Scenarios

If you want to model specific scenarios with your own numbers — like “what if I invest $500/month for 25 years at 8%?” — the compound interest and investment calculators at aihowtoinvest.com let you play with different assumptions without writing code. Useful for quick what-if analysis.

Full Code

The complete analysis notebook is about 200 lines of Python with pandas and numpy. The key insight from working with almost a century of data: the math strongly favors patience and consistency over cleverness.

Have you done your own analysis of market data? What surprised you most? I would love to see what other developers have found.