Building an AI Video Clipping Pipeline: Architecture, Tradeoffs, and What We Learned

Building an AI Video Clipping Pipeline: Architecture, Tradeoffs, and What We Learned

Processing video at scale is one of those problems that looks straightforward until you’re in production at 3 AM watching a queue pile up. This is the actual architecture behind ClipSpeedAI — what we built, why we made the tradeoffs we did, and what we’d do differently.

The Core Challenge

The product is simple to describe: take a YouTube URL, return 8-12 vertically reformatted short-form clips with captions and virality scores, in under 15 minutes.

The technical reality is a multi-stage async pipeline with three fundamentally different processing environments — JavaScript/Node.js for orchestration and API serving, Python for machine learning inference, and FFmpeg for video encoding — all needing to coordinate without stepping on each other.

Stage 1: Job Ingestion and Queue Management

Every video job enters through a REST API endpoint that validates the URL, creates a job record in Supabase, and pushes it to a Bull queue backed by Redis.

// Job creation
const job = await videoQueue.add('process-video', {
  jobId: supabaseRecord.id,
  url: youtubeUrl,
  userId: user.id,
  options: { maxClips: 12, minDuration: 15, maxDuration: 90 }
}, {
  attempts: 3,
  backoff: { type: 'exponential', delay: 5000 },
  removeOnComplete: 50,
  removeOnFail: 20
});

Bull handles retry logic automatically, which matters for YouTube download failures — bot detection, rate limiting, and network timeouts are the most common failure modes in production.

Stage 2: Video Download

We use yt-dlp via Node.js child_process.spawn with a streaming pipe directly into the processing stage. Early versions downloaded the full file first, which added 3-5 minutes of latency for long videos. Streaming cut that to near-zero.

One critical lesson: never proxy the video download itself. Proxy the metadata API calls to avoid bot detection on info fetching, but stream the actual video bytes directly. Routing gigabytes of video through a proxy burns bandwidth, slows processing, and has a high failure rate. Residential proxies are for tiny API calls only.

Stage 3: Transcript Extraction and LLM Analysis

This is where the virality scoring happens. We pull the transcript via YouTube’s caption API, normalize the timing data, and pass it to GPT-4o with a structured evaluation prompt.

The prompt is the core IP. It evaluates each 30-120 second segment for:

  • Hook strength (first sentence)
  • Narrative completeness (does it land without external context)
  • Information density (signal-to-noise ratio)
  • Emotional content (based on word patterns and sentence structure)

The output is structured JSON with clip candidates ranked by composite virality score. This takes 8-15 seconds per video depending on transcript length.

Stage 4: The Python Bridge — MediaPipe Face Detection

This is where architectures get messy. MediaPipe runs in Python. The rest of the stack is Node.js. The cleanest solution we found: a persistent Python subprocess with a simple JSON-over-stdin/stdout IPC protocol.

# Python side — runs as persistent child process
import sys, json
import mediapipe as mp

detector = mp.solutions.face_detection.FaceDetection(
    model_selection=1, min_detection_confidence=0.5
)

for line in sys.stdin:
    request = json.loads(line)
    # process frame, return face positions
    result = process_frame(request['frame_data'])
    sys.stdout.write(json.dumps(result) + 'n')
    sys.stdout.flush()

The alternative — spawning a new Python process per clip — was 40% slower due to model loading overhead. Persistent process with IPC is the right pattern here.

Railway threading gotcha: MediaPipe’s default configuration tries to spawn multiple pthread workers. Railway’s container environment restricts this, causing silent crashes. The fix is forcing single-threaded mode via environment variable before any MediaPipe import:

import os
os.environ['MEDIAPIPE_DISABLE_GPU'] = '1'
os.environ['OMP_NUM_THREADS'] = '1'

Stage 5: FFmpeg Encoding

With face position data in hand, FFmpeg applies a dynamic crop filter. The crop window follows the face with exponential smoothing to prevent jitter:

function buildCropFilter(facePositions, outputWidth, outputHeight) {
  const keyframes = facePositions
    .map(({time, cx}) => {
      const cropX = Math.max(0, Math.min(
        cx * inputWidth - outputWidth / 2,
        inputWidth - outputWidth
      ));
      return `${time}_${Math.round(cropX)}`;
    })
    .join(':');

  return `crop=${outputWidth}:${outputHeight}:${keyframes}`;
}

Caption burn-in happens in the same FFmpeg pass using drawtext filters — combining crop + caption in one encode rather than two separate passes reduces processing time by roughly 35%.

What We’d Do Differently

Separate the Python ML service from the start. Running a sidecar process is workable but fragile under load. A proper FastAPI microservice with a job-specific endpoint would be cleaner and more independently scalable.

Use S3 presigned URLs for client delivery from day one. Early versions served processed video through the API server. Wrong call. Let S3 handle delivery, let your API handle orchestration.

Build the monitoring dashboard before the product. We flew blind for too long. Knowing your queue depth, average job duration, and failure rates by stage is essential for production.

ClipSpeedAI is in production, processing hundreds of videos weekly. If you’re building something similar or want to dig into any of these stages further, drop a comment.

Exponential cost traps in database architectures: how SurrealDB breaks the cycle

Exponential cost traps in database architectures: how SurrealDB breaks the cycle

In the fast-paced world of application development, database choices can make or break an organisation’s scalability and budget. Traditional polyglot persistence (relying on multiple specialised databases) often leads to exponential cost growth as systems expand. What starts as a simple setup spirals into a complex, inefficient infrastructure riddled with data duplication, ETL pipelines, and operational silos. SurrealDB, with its multi-model architecture unifying document, graph, vector, full-text, time-series, geospatial, and relational capabilities, offers a consolidated alternative that eliminates these pitfalls. By storing data once and querying it across models, SurrealDB can reduce overall costs by multiple factors, particularly in storage-heavy environments where cloud block storage is in use.

To understand the value of consolidation, consider the common trajectory of database sprawl. Below, we explore a real-world-inspired story of how costs escalate exponentially, helping readers identify if their setup is heading toward inefficiency. This narrative highlights the compounding effects of architectural decisions, setting the stage for how SurrealDB provides a streamlined, cost-effective path forward.

A story of exponentially increasing costs: from simplicity to sprawl

Many teams begin with modest needs but face rapid growth that exposes the limitations of single-model databases. Let’s trace a typical app’s evolution, illustrating how costs outpace traffic due to added complexity, redundancy, and management overhead.

1. Launching the app: a simple start

Sentiment: “We start simple: a single database, fast and cheap to run.”

Your app is new, with straightforward transactional requirements. You deploy a single MySQL instance on AWS, adding one replica for high availability. It’s low cost and easy to manage. Database expenses are minimal, infrastructure is straightforward, and personnel needs are light.

​ ​
Database Costs: Low
Traffic Handled: Basic
Infra Cost: Minimal
Personnel Required: 1–2 engineers
Temp cost: None yet
Complexity cost: None yet

Architecture:

  • MySQL (Primary)
  • MySQL (Failover Replica)

2. First wave of growth: scaling reads

Sentiment: “Our first scaling challenge is reads. Replicas help, but cost growth slightly outpaces traffic.”

User traffic surges, dominated by reads. You add 8 read replicas and scale the writer to a larger instance (where per-vCPU costs rise disproportionately). Costs begin increasing slightly faster than traffic due to over-provisioning and load balancing.

​ ​
Database costs: Moderate
Traffic handled: Increased
Infra cost: Rising
Personnel required: Still low, but monitoring grows
Temp cost: None yet
Complexity cost: None yet

Architecture:

  • MySQL Writer
  • Load Balancer
  • 8x MySQL Read Replicas

3. Write traffic explodes: sharding begins

Sentiment: “As writes explode, we shard the system, but migrations are expensive and disruptive.”

Writes overwhelm the single writer. You shard into four MySQL instances, over-provisioning each for spikes. A data access layer handles routing by key, and the migration temporarily doubles costs. Complexity introduces temporary and ongoing expenses.

​ ​
Database costs: High
Traffic handled: Substantial
Infra cost: Accelerating
Personnel required: Increasing (sharding expertise needed)
Temp cost: Spike from migration
Complexity cost: Emerging

Architecture:

  • 4x MySQL Shards (each with Writer + Multiple Read Replicas)
  • Load Balancers
  • CDC (Change Data Capture) for transitioning from old architecture

4. Analytics demands: the first pipeline

Sentiment: “Analytics needs have driven us to add a pipeline and duplicate data with added complexity as a result.”

Product teams demand dashboards and real-time insights. You build an Extract, Transform, Load (ETL) pipeline to an analytical database such as ClickHouse, duplicating data via Change Data Capture (CDC). Applications now query multiple systems, and engineers must manage query routing while maintaining consistency across stores.

​ ​
Database costs: Very high
Traffic handled: Advanced
Infra cost: Ballooning
Personnel required: Still increasing (pipeline maintenance)
Temp cost: Pipeline setup
Complexity cost: Significant

Architecture:

  • Existing MySQL Shards
  • CDC + ETL
  • ClickHouse
  • Application querying multiple databases

5. AI ambitions: vector database enters

Sentiment: “AI ambitions require another new system, and more pipelines. The architecture is growing fast.”

AI agents need RAG (Retrieval-Augmented Generation) support, querying across systems. You spin up a vector DB like Weaviate or Pinecone, with new pipelines for replication. Data is consolidated in S3 for training, adding sharding as usage grows.

​ ​
Database costs: Extreme
Traffic handled: AI-enhanced
Infra cost: Exponential
Personnel required: Specialised teams
Temp cost: AI integration
Complexity cost: Overwhelming

Architecture:

  • Existing Setup
  • Additional ETL + Kafka
  • Weaviate
  • S3 for data lakes

6. Keeping it all running: growing ops

Sentiment: “Now we need a large ops team just to stay afloat. Costs are scaling exponentially, not linearly.”

Ongoing tasks include re-sharding MySQL, scaling MongoDB/Weaviate/ClickHouse, upgrades across systems, node recoveries, and pipeline fixes. Teams manage credentials, security, and optimisations in isolation. Ops cycles dominate, slowing innovation and ballooning personnel costs.

​ ​
Database costs: Off the charts
Traffic handled: Peak
Infra cost: Exponential
Personnel required: Large teams
Temp cost: Constant disruptions
Complexity cost: Debilitating

Architecture:

  • All systems with balancing, re-sharding, upgrades, and recoveries

Why the cost curve went exponential

Exponential costs are rarely caused by user growth alone. Instead, they often stem from an architecture that acts as a tax on every new login. Between the headaches of manual sharding, the hidden drain of data duplication, and the hours lost to rigid schema changes, many teams end up subsidizing a fragmented mess. If your infrastructure spend is climbing faster than your traffic, you are leaking resources rather than scaling. Moving toward a unified database simplifies the stack and returns your cost curve to a manageable, linear state.

The hidden costs of database sprawl: ETL, layers, and operational overhead

Building on this story, polyglot architectures create fragile ETL pipelines for data movement between systems like MySQL and ClickHouse. These demand resources for processing, debugging, and schema handling. Operational burdens include multiple query languages, fragmented backups, and custom synchronisation.

SurrealDB eliminates this by natively supporting all models in one platform with SurrealQL. No ETL needed. Data stays unified, reducing dependencies and accelerating development, as seen in replacements of PostgreSQL + Neo4j + RabbitMQ stacks.

EBS storage: the #1 cost driver in self-hosted databases

As the story shows, EBS volumes (and Azure and GCP’s equivalent) multiply with replicas and duplications, becoming the dominant expense. With EBS volumes not being eligible for discounts, costs compound in sprawls: 3x replication per cluster, plus copies across databases, over-provisioning, and snapshots typically result in massive redundant data duplication

For example, in a 50-node cluster with 4TB EBS volumes on AWS, storage will be $28,098 monthly, over twice the $12,577 for EC2 (factoring in discounts). Polyglot setups exacerbate this exponential growth.

SurrealDB’s compression edge: reducing data size by 1/3 for dramatic savings

SurrealDB’s storage engine (TiKV) delivers 70-80% better compression than PostgreSQL’s, typically shrinking datasets to one-third. For the 4TB example, this cuts EBS to ~1.33TB, dropping costs to under $10,000, a 65% savings. In addition to the raw savings, smaller data reduces I/O, snapshots, and data transfer cost, countering the sprawl’s redundancy.

Eliminating data duplication: organization-wide cost reductions

Storing data once avoids multi-system duplication. A single cluster with 3× replication replaces the primary and secondary copies spread across multiple database systems. Eliminating ETL removes staging costs, while unified data views simplify compliance and backups, reducing S3 storage and egress fees.

Linear scalability: ensuring cost-effective growth

Unlike most other database systems, SurrealDB scales linearly via TiKV, with less than a 5% performance deviation coefficient per node. You get roughly the same increase in capability and performance when adding a node to a 9-node cluster as when adding a node to a 100-node cluster. This keeps costs predictable and prevents exponential cost growth which is typical in sprawling platforms.

Conclusion: escape the exponential trap with SurrealDB

The story of sprawl reveals how polyglot decisions lead to exponential costs through duplication, complexity, and ops overhead. SurrealDB’s “one database to rule them all” reverses this, slashing EBS-driven expenses via consolidation and compression. For teams in inefficient systems, migrating promises simplicity and transformative savings.

Building a 100% Client-Side PDF & Image Studio (Zero Server Uploads) 🚀

Hey everyone! 👋

As a CS student, I constantly need to merge PDFs, compress images, or extract text from modules. But I always hated uploading my personal documents to ad-filled, sketchy websites where you don’t know what happens to your data.

So, I decided to build my own solution: OmniKit

OmniKit is a completely free, privacy-first web toolkit with over 30+ utilities. The biggest catch? Everything runs 100% locally in your browser. >

🛠️ The Tech Stack
I wanted to keep it lightweight and blazing fast:

  • Frontend: Vanilla JavaScript & HTML5
  • Styling: Tailwind CSS (with seamless Dark Mode)
  • PDF Processing: pdf-lib for client-side manipulation

AI / Image Tools: WebAssembly and local browser APIs for background removal and OCR.

Hosting: Vercel

Because there is absolutely no backend processing, there are zero server uploads. Your files never leave your device.

**🔍 Looking for Beta Testers!
**I’m doing a soft launch today and I would love to get some feedback from fellow developers before sharing it with a wider audience.

  • How does the UI/UX feel?
  • Did you encounter any bugs with the client-side processing?
  • What other offline tools would you like to see added?

You can try it here: https://omnikit.vercel.app/

I’d appreciate any honest feedback, code critiques, or suggestions. Thank you! 👨‍💻

Building Shadow-Signal: Bridging the Gap Between On-Chain Intelligence and Execution with Nansen CLI

In the fast-moving world of decentralized finance, the “time-to-trade” is everything. Traditionally, a trader sees a “Smart Money” move on a dashboard, manually verifies the contract, and then heads to a DEX to execute. By the time that loop finishes, the alpha is often gone.

I built Shadow-Signal, an autonomous agentic script that collapses this entire workflow into a single loop using the new Nansen CLI.

The Architecture

Shadow-Signal is built using a Node.js wrapper around the Nansen CLI, designed to act as a “Sentinel” for high-conviction Smart Money moves on Solana and Base.

The logic flows through three distinct layers of the Nansen ecosystem:

  1. The Discovery Layer (nansen research):
    The script polls the smart-money netflow endpoint. Unlike a broad scan, I used the –fields flag to limit data transfer and focused on the 24h timeframe to identify sustained accumulation rather than transient noise.

  2. The Reasoning Layer (nansen agent):
    This is where the “Agentic” part comes in. Raw data doesn’t tell the whole story. Before any trade is considered, the script pipes the token symbol into the Nansen AI Agent. It asks for a risk assessment—checking for potential red flags or “rug-pull” sentiment that the raw netflow numbers might miss.

  3. The Execution Layer (nansen trade):
    If the AI Agent gives a “Green Light,” the script moves to execution. It interfaces with Nansen’s local wallet system to generate a DEX quote (trade quote) and prepares the transaction for final execution.

Technical Challenges & Optimizations

  • Credit Efficiency: AI Agent calls are high-value. I optimized the script to only trigger the Agent check if the Smart Money inflow exceeds a specific dollar threshold, preventing unnecessary credit burn.
  • JSON Orchestration: By using the CLI’s JSON output format, I was able to programmatically parse on-chain data and feed it directly into trade logic, removing human error from the equation.

Shadow-Signal isn’t just a bot; it’s a proof-of-concept for Agentic Finance. By using Nansen’s CLI as the “brain” and “eyes,” we can now build tools that don’t just show us the data, but act on it.

Github Gist: https://gist.github.com/harishkotra/9ed34cd6c892b910c163fe66137ccd22

So… Claude Code’s Source Code Just Leaked. Here’s What We Know.

If you’ve been anywhere near Dev Twitter (or X, whatever we’re calling it now) in the last couple of days, you’ve probably already seen this. But if you haven’t — buckle up, because this one’s wild.

On March 31st, Anthropic accidentally shipped the entire source code of Claude Code in a public npm package. Yes, you read that right. The whole thing. Nearly 2,000 TypeScript files. Over 512,000 lines of code. Just… out there. For everyone to see.

And the internet did what the internet does — it went absolutely nuts.

Wait, How Did This Even Happen?

So here’s the thing — this wasn’t some sophisticated cyber attack. Nobody hacked into Anthropic’s servers. There was no insider threat, no zero-day exploit. It was a packaging mistake.

When Anthropic pushed version 2.1.88 of the @anthropic-ai/claude-code npm package, someone accidentally included a source map file in the build. If you’re not familiar, source maps are dev tools — they map compiled/minified code back to the original source. Super useful during development. Absolutely should never ship in production.

But it did. And security researcher Chaofan Shou caught it almost immediately and posted about it on X. That post? It blew up to over 28.8 million views.

Anthropic pulled the version from npm pretty quickly, but by then it was way too late. The code had already been extracted and uploaded to GitHub.

Anthropic’s official response was basically: “This was a release packaging issue caused by human error, not a security breach. No customer data or credentials were exposed.” They also said they’re putting measures in place so this doesn’t happen again.

Fair enough. But the code is out there now, and there’s no putting that genie back in the bottle.

The GitHub Repo That Broke Records

Within hours, a GitHub repo called instructkr/claw-code popped up with the leaked source. And here’s the crazy part — it hit 50,000 stars in under 2 hours. As of now, it’s sitting at over 84,000 stars and 82,000 forks.

That’s not just popular. That’s one of the fastest-growing repos in GitHub history.

What’s interesting is that the repo didn’t stay as just a code dump. The maintainers turned it into something more — a clean-room reimplementation project. They’ve been porting the architecture to both Python and Rust, building it out as a research tool for studying AI agent systems. They’ve been pretty clear that it’s not affiliated with Anthropic and that they deliberately avoided storing the original leaked snapshot.

The repo includes a Python workspace with modules for commands, tools, a query engine, and a CLI, plus a full Rust workspace with crates for everything from the API client to plugin systems to a compatibility layer for editor integration.

It’s kind of become this hub for developers who want to understand how AI coding agents actually work under the hood.

OK But What’s Actually In The Code?

This is where it gets really interesting. People have been tearing through the source and sharing their findings, and some of this stuff is genuinely fascinating. Let me walk you through the highlights.

The Self-Healing Memory Thing

You know how LLMs have a fixed context window, right? So when you’re in a long coding session with Claude Code, it eventually has to decide what to keep and what to throw away. Well, turns out Claude Code has this really clever system for handling that.

It’s not just doing dumb truncation. There’s a four-stage context management pipeline that compresses and reorganizes information to keep the most relevant stuff around. Developers who’ve studied it are calling it a “self-healing memory architecture” — basically the system can reconstruct important context even after compaction. Pretty smart.

Multi-Agent Swarms

Claude Code isn’t just one agent. When you give it a complex task — like a big refactor across multiple files — it can spawn sub-agents. Think of it like a team lead delegating tasks to specialists. These agents work on different parts of the problem and their results get coordinated back together.

This explains why Claude Code is weirdly good at large multi-file changes. It’s not doing it all in one pass.

The Tools Under The Hood

At its core, Claude Code runs on a tool system that handles file reading, bash execution, API calls — all the stuff that makes it feel like it actually understands your project. There’s a query engine that routes requests to the right model with the right context, and a bidirectional communication layer that connects IDE extensions to the CLI.

Nothing too surprising here if you’ve thought about how these tools must work, but it’s cool to see the actual implementation.

KAIROS — The Background Agent

OK, this one is wild. There’s a feature in the code called KAIROS that basically turns Claude Code into a persistent background process. It can fix errors, run tasks, and even send push notifications to you — all without you explicitly asking it to do anything.

Imagine you push some code, go grab coffee, and come back to a notification saying “hey, I noticed a bug in your last commit and fixed it.” That’s what KAIROS seems to be building toward.

“Dream” Mode

And if KAIROS wasn’t enough, there’s also this experimental thing called Dream mode. It lets Claude continuously think in the background — brainstorming ideas, iterating on your existing code, and preparing suggestions for when you come back.

It’s like having a junior dev who never sleeps and is always noodling on improvements to your codebase. Whether that’s exciting or terrifying probably depends on your perspective.

Undercover Mode (Yes, Really)

This one raised a lot of eyebrows. There’s a mode called “Undercover Mode” that’s designed for making contributions to open-source repos without revealing that Anthropic is behind them. The system prompt literally tells the agent not to include any Anthropic-internal information in commits or PRs.

People have a lot of opinions about this. Some see it as shady — Anthropic secretly contributing to open-source projects without disclosure. Others argue it’s pretty standard for companies to contribute to open source without broadcasting it. Either way, it’s not a great look when it gets discovered through a leak.

Fighting Model Distillation

Here’s something the AI industry watchers will find interesting. The code includes a system that detects when competitors might be scraping Claude Code’s outputs to train their own models (this is called model distillation). When it suspects scraping, it injects fake tool definitions into the API responses to poison the training data.

This makes sense given that Anthropic has publicly accused certain AI firms of using distillation attacks against Claude. Now we can see exactly how they’ve been fighting back.

The Security Mess

So far I’ve been talking about this mainly as an IP issue and a fascinating peek behind the curtain. But there’s a real security problem here too.

AI security company Straiker put it bluntly: with the full source code available, attackers don’t need to brute-force jailbreaks anymore. They can study exactly how data flows through the context pipeline and craft inputs designed to survive compaction. Basically, they can build persistent backdoors that stick around for an entire session.

That’s… not great.

The Supply Chain Attack

To make things worse, the timing of the leak overlapped with a supply chain attack on the Axios npm package. If you installed or updated Claude Code via npm on March 31st between 00:21 and 03:29 UTC, you might have pulled a trojanized version of Axios that included a cross-platform remote access trojan.

If you’re in that window, you need to:

  • Downgrade to a known safe version immediately
  • Rotate ALL secrets — API keys, SSH keys, tokens, everything Claude Code had access to
  • Check your systems for any suspicious activity

I’m not being dramatic here. This is a legit “drop everything and deal with this” situation if it applies to you.

Typosquatting Packages

And because things weren’t bad enough already, attackers started registering npm packages with names similar to internal Claude Code dependencies. A user called “pacifier136” published packages like audio-capture-napi, color-diff-napi, image-processor-napi, and a few others. Right now they’re empty stubs, but that’s how dependency confusion attacks work — squat the name, wait for installs, then push a malicious update.

If you’ve been trying to build the leaked source, be extremely careful about what packages you’re pulling in.

Oh, And There’s More

Here’s the kicker — this wasn’t even Anthropic’s only security incident that week. Just days before the Claude Code leak, details about an unreleased AI model (reportedly called “Mythos”) and other internal data were found sitting on an unsecured CMS. Anthropic later confirmed they’d been testing this new model with early access customers and called it the most capable model they’ve ever built.

Two significant data exposures in one week. For a company that has built its entire brand around being the “safety-first” AI lab, that’s a rough look. It doesn’t mean their AI safety research isn’t legit — it absolutely is — but operational security is clearly something they need to tighten up.

What This Means For The Rest Of Us

I think there are a few takeaways here, beyond the obvious “don’t ship source maps in production.”

AI coding tools have deep access. We’re giving these tools access to our codebases, our terminals, our secrets. When something goes wrong — whether it’s a leak, a supply chain attack, or a compromised build — the blast radius is huge. We need to think about these tools as critical infrastructure, not just developer convenience.

The packaging step is a security boundary. This whole thing happened because of a build configuration mistake. Your CI/CD pipeline isn’t just about deployment speed — it’s about security. Source maps, debug symbols, internal configs — all of these need to be explicitly excluded from production builds, and that exclusion needs to be verified automatically.

Open source benefits from transparency, even accidental transparency. The community has learned an enormous amount about how modern AI agent systems work from studying this code. The clean-room reimplementation projects are already advancing our understanding of agent orchestration, context management, and tool systems. There’s real value here for the field.

Audit your dependencies. This isn’t new advice, but it matters more than ever. Lock your package versions. Use integrity checks. Pay attention to what’s in your node_modules. The typosquatting and supply chain attacks that followed this leak show how quickly bad actors can exploit confusion.

Final Thoughts

Look, mistakes happen. I’m not going to pile on Anthropic for a packaging error — anyone who’s shipped software has made similar kinds of mistakes at some point. The difference is that when your tool is used by millions of developers worldwide and has deep access to their systems, the stakes are just higher.

What I am going to say is: if you use Claude Code (or any AI coding tool), take this as a reminder to treat it with the same security diligence you’d give to any other piece of infrastructure with privileged access. Check your installs, rotate your keys, and keep an eye on the follow-up advisories.

And if you’re a developer who’s curious about how these AI agent systems actually work — go check out the claw-code repo. It’s a genuinely fascinating read. Just, you know, be careful what you npm install while you’re at it.

What do you think about the leak? Too much panic, or are we not panicking enough? Drop your thoughts in the comments — I’d love to hear what other devs are thinking about this.

AI Didn’t Reduce Engineering Complexity. It Moved.

AI systems complexity shift — infrastructure shows healthy while behavior layer produces degraded outputs

AI Didn’t Reduce Engineering Complexity. It Moved.

The pitch for AI in engineering was straightforward: automate the repetitive, accelerate the cognitive, let engineers focus on higher-order problems. Less boilerplate. Faster feedback loops. Lower operational overhead.

Some of that happened. But something else happened too — something nobody put in the pitch deck.

The complexity didn’t disappear. It moved.

And most teams didn’t change how they look for it.

AI systems complexity shift — infrastructure shows healthy while behavior layer produces degraded outputs

The Promise That Wasn’t Wrong — Just Incomplete

The productivity gains are real. Code generation, automated testing, intelligent routing, semantic search — these tools removed genuine friction from engineering workflows. The pitch was not dishonest.

But it was incomplete. Automating the repetitive parts of engineering does not eliminate complexity. It relocates it. The complexity that used to live in writing code now lives in reviewing model outputs for correctness. The complexity that used to live in provisioning infrastructure now lives in governing model behavior. The complexity that used to live in deterministic failures now lives in probabilistic degradation that produces no stack trace and fires no alert.

The work didn’t go away. It just moved somewhere harder to see.

What Actually Happened

When you add an AI system to your stack, you do not replace complexity with simplicity. You trade one kind for another — and the new kind is harder to detect and harder to attribute when something goes wrong.

The engineer who used to write deterministic business logic now reviews probabilistic model outputs. The team that used to provision infrastructure now governs model behavior. The on-call rotation that used to respond to server alerts now investigates why a system that reports healthy is quietly producing degraded results.

AI systems complexity shift — where complexity lived before AI versus where it lives now

The Shift: Where AI Systems Complexity Lives Now

Traditional software systems fail in predictable ways. A service goes down. Latency spikes. An error rate crosses a threshold. Your monitoring fires. You find the stack trace. You fix the bug. The failure was detectable, locatable, and correctable.

AI systems fail differently. The infrastructure is healthy. The service is responding. The latency is nominal. And the system is producing outputs that are subtly wrong — off-brand, factually degraded, semantically drifted from what it was doing three weeks ago. No alert fires. No threshold is crossed. The failure is in the behavior layer — and your monitoring was never built to see it.

This is the core shift. Complexity moved from layers your tooling understands — uptime, latency, error rates — to a layer your tooling was never designed to instrument: behavior.

The Hidden Layer: Behavior Over Infrastructure

Infrastructure complexity has a known shape. You model it, monitor it, and respond to it with playbooks refined over two decades of distributed systems operations.

Drift is the purest expression of this shift. Autonomous systems don’t fail — they drift. Gradually. Silently. The model that was well-calibrated at deployment degrades incrementally as the distribution of real-world inputs diverges from its training distribution. Your infrastructure metrics show nothing. Your users notice before your monitoring does.

Behavior is now the primary risk surface. Infrastructure is just the substrate.

Why Teams Are Missing It

Most engineering teams are still measuring the wrong layer — and trusting those signals.

Not because they are unsophisticated. Because the tooling they inherited was built for a different problem. Prometheus was built for infrastructure metrics. Datadog was built for application performance. Distributed tracing was built to follow a request across services. None of these were built to answer the questions that matter in an AI system:

  • Is this output correct?
  • Is the model drifting?
  • Is cost increasing because behavior changed?
  • Is a degraded user experience hiding behind a healthy HTTP 200?

Three specific blind spots follow from measuring the wrong layer:

Assuming determinism. Traditional systems are deterministic — the same input produces the same output. AI systems are probabilistic. A system that worked in testing can fail in production not because anything changed in the infrastructure, but because the input distribution shifted into a region the model handles poorly. No runbook was written for that failure mode — because the failure mode did not exist before.

Treating models like services. A microservice has a contract. A model has a behavior profile — a statistical tendency to produce outputs in a certain range under a certain input distribution. That profile degrades without notice, drifts without alerting, and fails silently in ways that look like business problems before they look like engineering problems.

Cost attribution blindness. Infrastructure cost is straightforward to attribute. Behavior-driven cost is invisible to standard FinOps tooling. A prompt that consistently generates 2,000-token responses costs four times more than one that generates 500-token responses, on identical infrastructure, with identical latency. Teams discover this only when the bill arrives — because no alert was configured for token consumption per output.

What Breaks in Production

These are not theoretical failure modes. They are documented production patterns:

Cost explosions with no infrastructure anomaly. A change in prompt behavior — a slightly more verbose system prompt, a shift in user query patterns, a model update that produces longer completions — drives a 40% cost increase with zero corresponding change in infrastructure metrics.

Silent semantic failures. A RAG system that was accurately retrieving relevant context begins hallucinating with increasing frequency as the vector index grows stale. Response latency is nominal. Error rates are zero. The failure is in output correctness — a dimension that requires semantic evaluation to measure.

Degraded UX behind healthy systems. A recommendation system begins surfacing lower-quality results as the model drifts from its calibrated state. User engagement declines. Engineering sees nothing wrong in their dashboards.

Drift that compounds over weeks. Small degradations accumulate silently until a threshold is crossed that cannot be incrementally recovered from.

The Real Problem: We’re Measuring the Wrong Things

Observability was built for the infrastructure era. The three pillars — metrics, logs, traces — answer: Is the system up? Is it fast? Where did the request go?

They do not answer: Is the output correct? Is the model drifting? Is cost increasing because behavior changed?

AI systems require a fourth observability layer:

  1. Output correctness monitoring — Evaluation pipelines that assess semantic quality, factual accuracy, and task completion. Correctness is not a metric your infrastructure emits.
  2. Semantic drift detection — Statistical comparison of current output distributions against calibrated baselines. Drift surfaces here weeks before it becomes user-visible.
  3. Cost-per-behavior tracking — Token consumption attributed to specific output patterns. A prompt that generates 2,000-token responses costs four times more than one that generates 500 — on identical infrastructure, with identical latency.
  4. Behavioral anomaly detection — Alerting on changes in output characteristics — length, confidence, topic distribution — that precede detectable quality degradation.

What This Means for System Design

AI systems cannot be treated as stateless services with better interfaces. They require a fundamentally different operational posture:

  • Behavior-level instrumentation, not just infrastructure metrics — the risk surface moved, the monitoring has to follow it
  • Evaluation pipelines as part of CI/CD, not post-hoc analysis — correctness needs to be a gate, not a post-mortem
  • Cost controls tied to output patterns, not resource allocation — token budgets are behavior controls, not infrastructure controls
  • Drift detection as a first-class operational concern — not a quarterly model review, a continuous signal alongside latency and error rate

The architecture did not get simpler. The abstraction layer changed.

Architect’s Verdict

The industry adopted AI faster than it updated its operational model. The tooling, the runbooks, the on-call intuitions, the monitoring dashboards — all of it was built for deterministic systems that fail loudly. AI systems are probabilistic systems that fail quietly.

Complexity did not leave the stack. It moved to the one layer most teams are not watching.

AI didn’t make engineering simpler. It made failure quieter.

Originally published on rack2cloud.com — architecture for engineers who run things in production.

Top 10 Cheapest Providers for DeepSeek V3.2 in 2026

DeepSeek V3.2 has quickly become one of the most popular open-weight models in production. It replaced both V3 and R1 with a unified model that handles chat and reasoning at a single price point, ships a 163K context window, and scored gold on the 2025 IMO and IOI benchmarks — all for under $0.50 per million tokens.

But where you access V3.2 matters just as much as the model itself. Depending on the provider, you could pay anywhere from $0.18/M to $0.57/M for input tokens. Over millions of daily requests, that difference adds up fast.

We pulled pricing from every major provider and ranked them so you don’t have to.

The Ranking

Rank Provider Input (per 1M) Output (per 1M) Cached Input Notes
1 LLM Gateway $0.182 $0.28 $0.036 Auto-routed via Canopywave, 30% discount applied
2 GMI $0.20 $0.32 — Lowest blended price on Artificial Analysis
3 LLM Gateway (Alibaba cn-beijing) $0.23 $0.345 $0.046 20% Alibaba Cloud discount applied
4 OpenRouter $0.26 $0.38 — Multi-provider routing, free tier available
5 DeepInfra $0.26 $0.38 — Serverless, pay-per-token
6 Novita AI $0.269 $0.40 $0.135 High-throughput serverless
7 SiliconFlow (FP8) $0.27 $0.42 — Budget FP8 quantized endpoint
8 DeepSeek (Official) $0.28 $0.42 $0.028 Direct API, 90% cache discount
9 Volcengine (Bytedance) $0.28 $0.42 $0.056 Asia-optimized, reasoning mode
10 Fireworks AI $0.30+ $0.45+ — Fastest output speed (211 t/s)

Pricing as of March 2026. “Cached Input” refers to prompt cache hit pricing where available.

Why LLM Gateway Tops the List

LLM Gateway doesn’t host models — it routes your requests to the cheapest available provider for each model, automatically. For DeepSeek V3.2, that currently means Canopywave with an exclusive 30% discount negotiated on your behalf.

Here’s what that looks like in practice:

  • Input tokens: $0.26/M base → $0.182/M after 30% discount
  • Output tokens: $0.40/M base → $0.28/M after 30% discount
  • Cached input: $0.052/M base → $0.036/M after 30% discount

That’s 35% cheaper than the official DeepSeek API and 9% cheaper than GMI (the next lowest provider). If Canopywave ever goes down, your requests automatically fail over to the next cheapest provider — Novita, Alibaba, Bytedance, or DeepSeek direct — with zero configuration.

Real Cost at Scale

Cheap per-token pricing only matters if you can quantify the actual savings for your workload. That’s why we built the Token Cost Calculator.

Here’s a quick example. Say you’re running a production chatbot doing 10M input tokens and 1M output tokens per day:

Provider Daily Cost Monthly Cost Annual Cost
DeepSeek (Official) $3.22 $96.60 $1,175.30
OpenRouter $2.98 $89.40 $1,087.70
GMI $2.32 $69.60 $846.80
LLM Gateway $2.10 $63.00 $766.50

That’s $408.80 saved per year compared to the official DeepSeek API — just on one model. If you’re using multiple models across providers, the savings compound.

How to Calculate Your Exact Savings

The Token Cost Calculator lets you:

  • Select any model from 100+ options across all major providers
  • Set your token volumes — choose from presets (Light, Medium, Heavy, Intensive) or enter custom numbers
  • Compare side-by-side — see official provider pricing vs. LLM Gateway’s cheapest route
  • Add multiple models — building with GPT-4o, Claude, and DeepSeek? Add all three and see your total savings
  • Share your results — export your cost breakdown to X, LinkedIn, or clipboard

The calculator pulls pricing directly from the live model registry, so it’s always up to date. No sign-up required.

Try the Token Cost Calculator →

Factors Beyond Price

Price isn’t everything. Here’s what else to consider when choosing a DeepSeek V3.2 provider:

  • Speed: Fireworks leads at 211 tokens/second output. Google Vertex and Azure follow at ~207 t/s. If latency matters more than cost, pay the premium.
  • Reliability: The official DeepSeek API can have variable availability during peak hours. Third-party providers typically offer better uptime SLAs.
  • Cache discounts: DeepSeek’s official API offers a 90% discount on cached input tokens ($0.028/M vs $0.28/M). If your workload has high prompt reuse, this can offset higher base pricing.
  • Context window: Most providers offer the full 163K context. Alibaba and Bytedance cap at 131K.
  • Feature support: Not all providers support tool calling or JSON output mode. LLM Gateway’s smart routing only sends requests to providers that support the features you’re using.

Getting Started

Switch to the cheapest DeepSeek V3.2 pricing in under a minute:

  1. Sign up free — no credit card required
  2. Use the OpenAI-compatible API — just change your base URL:
curl https://api.llmgateway.io/v1/chat/completions 
  -H "Authorization: Bearer YOUR_API_KEY" 
  -H "Content-Type: application/json" 
  -d '{
    "model": "deepseek/deepseek-v3.2",
    "messages": [{"role": "user", "content": "Hello!"}]
  }'
  1. Calculate your savings with the Token Cost Calculator

No vendor lock-in. No platform fees. Just the cheapest path to every model.

How to Build a Fully Local Thermal Printer Server (No Cloud Required)

If you’ve ever tried to print a simple receipt, label, or note from a thermal printer, you’ve probably been funneled into some cloud-connected app with a monthly subscription. For a device that literally just needs to receive bytes and heat up paper, that’s absurd.

I recently set up a completely local thermal printer appliance — no accounts, no cloud, no subscriptions. Just a single-board computer, a cheap thermal printer, and some open-source software. It took me longer than it should have because the documentation around thermal printing is scattered across a dozen half-finished GitHub repos and forum threads from 2014.

Here’s everything I learned so you can skip the painful parts.

The Core Problem: Thermal Printers Are Dumb (In a Good Way)

Thermal printers speak a protocol called ESC/POS, originally developed by Epson. It’s ancient, well-documented, and beautifully simple. You send bytes over USB or serial, and the printer prints. That’s it.

The problem is that most consumer thermal printer products wrap this simplicity in cloud services, proprietary apps, and subscription models. The printer hardware is perfectly capable of working locally — the vendor software is what creates the dependency.

So the fix is straightforward: cut out the middleman and talk to the printer directly.

What You Need

  • A thermal printer that supports ESC/POS (most 58mm and 80mm receipt printers do — I used a generic 58mm USB model that cost around $25)
  • A Raspberry Pi (or any Linux SBC — a Pi Zero 2 W works great for this)
  • A microSD card with Raspberry Pi OS Lite
  • A USB cable to connect the printer
  • Python 3 and the python-escpos library

Total cost: under $50 if you already have a Pi sitting in a drawer (and let’s be honest, you probably do).

Step 1: Get the Printer Talking Over USB

Flash Raspberry Pi OS Lite to your SD card, boot up, and connect the printer via USB. First, let’s make sure the system sees it:

# Check if the printer shows up as a USB device
lsusb

# You should see something like:
# Bus 001 Device 004: ID 0416:5011 Some Thermal Printer Corp

# Note the vendor ID (0416) and product ID (5011)
# You'll need these later

Here’s where most people get stuck: USB device permissions. By default, your user doesn’t have permission to write to the USB device directly. You’ll try to print and get a cryptic USBNotFoundError or permission denied.

The fix is a udev rule:

# Create a udev rule so your user can access the printer
# Replace the vendor/product IDs with yours from lsusb
sudo tee /etc/udev/rules.d/99-thermal-printer.rules << 'EOF'
SUBSYSTEM=="usb", ATTR{idVendor}=="0416", ATTR{idProduct}=="5011", MODE="0666", GROUP="lp"
EOF

# Reload udev rules and add your user to the lp group
sudo udevadm control --reload-rules
sudo udevadm trigger
sudo usermod -aG lp $USER

# Log out and back in for group changes to take effect

This single step probably accounts for 80% of the “my thermal printer doesn’t work on Linux” posts I’ve seen online.

Step 2: Send Your First Print Job

Install the python-escpos library — it’s the most mature open-source ESC/POS implementation for Python:

pip install python-escpos

Now test it:

from escpos.printer import Usb

# Use the vendor and product IDs from lsusb
printer = Usb(0x0416, 0x5011)

printer.text("Hello from your local printer!n")
printer.barcode("123456789", "EAN13")  # print a barcode just because we can
printer.qr("https://example.com")       # QR codes work too
printer.cut()                            # cut the paper

If that prints successfully, congratulations — you’ve already replaced the cloud. Everything from here is just making it more useful.

Step 3: Build a Local Print Server

A printer you can only use from the Pi itself isn’t very useful. Let’s expose it as an HTTP API so any device on your network can send print jobs. Flask keeps this dead simple:

from flask import Flask, request, jsonify
from escpos.printer import Usb
import textwrap

app = Flask(__name__)

def get_printer():
    """Connect to the thermal printer."""
    return Usb(0x0416, 0x5011)

@app.route("/print", methods=["POST"])
def print_text():
    data = request.json
    if not data or "text" not in data:
        return jsonify({"error": "Missing 'text' field"}), 400

    try:
        printer = get_printer()
        # Wrap text to fit the printer's character width
        # 32 chars for 58mm, 48 chars for 80mm printers
        wrapped = textwrap.fill(data["text"], width=32)
        printer.text(wrapped + "nn")
        printer.cut()
        return jsonify({"status": "printed"})
    except Exception as e:
        return jsonify({"error": str(e)}), 500

@app.route("/print/image", methods=["POST"])
def print_image():
    """Print an uploaded image (receipts, labels, etc)."""
    if "file" not in request.files:
        return jsonify({"error": "No file uploaded"}), 400

    try:
        printer = get_printer()
        img_file = request.files["file"]
        printer.image(img_file)
        printer.cut()
        return jsonify({"status": "printed"})
    except Exception as e:
        return jsonify({"error": str(e)}), 500

if __name__ == "__main__":
    # Bind to all interfaces so other devices can reach it
    app.run(host="0.0.0.0", port=9100)

Now any device on your network can print:

# Print text from any machine on your network
curl -X POST http://your-pi-ip:9100/print 
  -H "Content-Type: application/json" 
  -d '{"text": "Pick up milk. Also, this printer cost less than one month of that cloud subscription."}'

Step 4: Make It Survive Reboots

Create a systemd service so the print server starts automatically:

sudo tee /etc/systemd/system/thermal-print.service << 'EOF'
[Unit]
Description=Local Thermal Print Server
After=network.target

[Service]
User=pi
WorkingDirectory=/home/pi/print-server
ExecStart=/usr/bin/python3 server.py
Restart=always
RestartSec=5

[Install]
WantedBy=multi-user.target
EOF

sudo systemctl enable thermal-print.service
sudo systemctl start thermal-print.service

Common Pitfalls (And How to Fix Them)

After running this setup for a while, here are the issues I’ve hit:

The printer randomly disconnects

Cheap thermal printers have flaky USB connections. The python-escpos library doesn’t handle reconnection gracefully. My fix was wrapping the printer connection in a retry:

import time
from escpos.printer import Usb

def get_printer_with_retry(retries=3, delay=1):
    for attempt in range(retries):
        try:
            return Usb(0x0416, 0x5011)
        except Exception:
            if attempt < retries - 1:
                time.sleep(delay)
    raise ConnectionError("Could not connect to printer after retries")

Garbled text or weird characters

This usually means a codepage mismatch. Most cheap printers default to CP437. If you’re printing non-ASCII characters, you need to set the codepage explicitly:

printer = Usb(0x0416, 0x5011)
printer.charcode("CP437")  # or CP858 for European characters

The printer just… does nothing

Check if another process grabbed the USB device. CUPS is a common culprit — it loves to claim printers:

# Check if CUPS grabbed your printer
lpstat -p -d

# If it did, either remove it from CUPS or stop the service
sudo systemctl stop cups

Taking It Further

Once you have the basic server running, there are some fun extensions:

  • Home Assistant integration — trigger prints from automations (grocery list when you say “OK Google, I need milk”)
  • RSS feed printer — a cron job that prints your morning news headlines on a little receipt
  • Daily agenda — pull your calendar via CalDAV and print today’s schedule
  • Webhook receiver — print GitHub notifications, server alerts, or anything that can send an HTTP POST

The beauty of this approach is that it’s just an HTTP endpoint. Anything that can make a POST request can use your printer. No SDK, no vendor lock-in, no account creation.

Why This Matters Beyond the Project

This isn’t really about thermal printers. It’s about a pattern that keeps repeating in tech: simple hardware gets wrapped in unnecessary cloud dependencies, and developers end up paying monthly fees for functionality that could run on a $15 computer.

The ESC/POS protocol has been around since the 1980s. The printers work fine without the internet. The only thing standing between you and a fully local setup is a few lines of Python and an afternoon of tinkering.

Sometimes the best solution to a subscription problem is just… not subscribing.

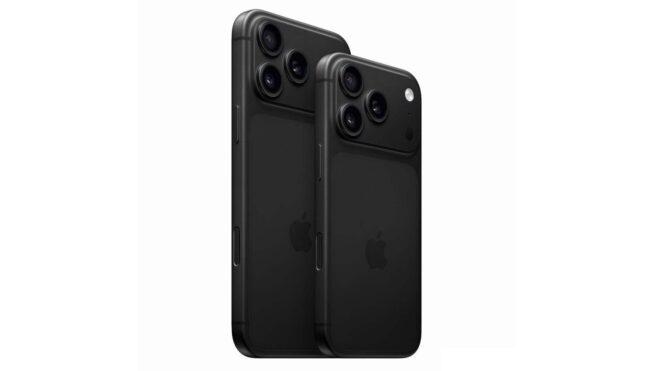
iPhone 18 Pro serisi için de siyah renk seçeneğinin sunulmayacağı iddia edildi

iPhone 18 Pro

iPhone 18 ProÇinli bir kaynak, eylül ayında görücüye çıkarılacak iPhone 18 Pro serisi için de siyah renk seçeneğinin sunulmayacağı iddia etti. iPhone 17 Pro ve 17 Pro Max’i gümüş, kozmik turuncu ve abis (koyu mavi) isimli renk seçenekleriyle sunan Apple, iddialara göre 18 Pro ve 18 Pro Max’te yeni kırmızı renk seçeneğini öne çıkarabilir. Eylül ayında bu modellerle birlikte ilk katlanabilir iPhone modelini de tanıtacak olan Apple, çok fazla dikkat çekmeyen siyah rengi bu modelde de kullanmayabilir.
iPhone 18 Pro serisi için de siyah renk seçeneğinin sunulmayacağı iddia edildi yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

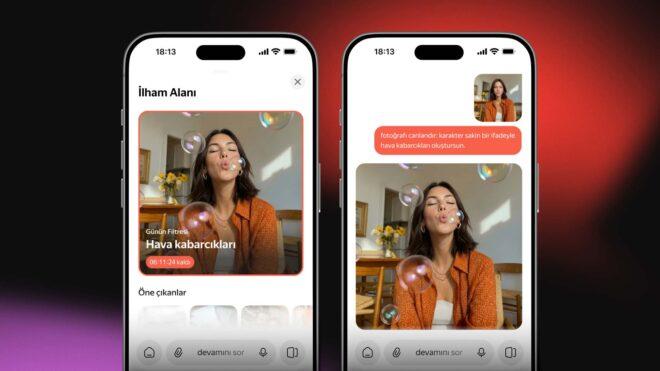
Yandex AI için kapsamlı bir güncelleme yayınlandı

Yandex AI

Yandex AIYandex Türkiye, bugün “Yandex AI” sistemine kapsamlı bir güncelleme yayınlandığını duyurdu. “Bu güncelleme, uygulamanın temel sohbet yeteneklerini artırırken üretken özelliklerini de genişletiyor. Lansmandan bu yana kullanıcıların 6 milyondan fazla görsel üretmesiyle ortaya çıkan yoğun ilgiye yanıt niteliği taşıyan güncelleme, kullanıcı deneyimini daha da zenginleştiriyor. Yeni özellikler arasında görselleri birleştirmeye yarayan bir araç, fotoğrafları canlandıran gelişmiş hareket efektleri ve farklı görünümler sunan stil filtreleri bulunuyor.” diyen şirket, paylaştığı açıklamada ek olarak şu bilgileri verdi: “Önemli bir geliştirmeyle sayesinde Yandex AI, artık kullanıcı taleplerine artık 2,5 kat daha hızlı yanıt veriyor. Uygulama, kullanıcıların ilham bulmasına yardımcı olmak için daha karmaşık sohbetleri desteklerken, matematik için de özel destekler sunuyor; örneğin Fourier dönüşümü gibi karmaşık formülleri adım adım açıklayabiliyor. Bunun yanı sıra, sohbet deneyimi artık daha empatik hissettiriyor, daha uzun etkileşimleri teşvik ediyor ve verilen yanıtlar her zamankinden daha doğru ve güvenilir hale geliyor. Üretken özellikleri önemli ölçüde genişletilen Yandex AI, kullanıcılara anılarını korumaları […]

Yandex AI için kapsamlı bir güncelleme yayınlandı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.