Presentation: The AI Gateway: Scaling Centralized Inference Across Decentralized Teams

Meryem Arik discusses why modern engineering teams face “inference chaos” and how AI model gateways provide a critical control layer. She explains the balance between empowering decentralized teams to choose the best models and maintaining centralized oversight for security, RBAC, and cost control. Explore open-source solutions like LiteLLM and Doubleword to streamline your AI infra.

By Meryem Arik

OpenAI Outlines WebRTC Architecture for Low-Latency Voice AI at Scale

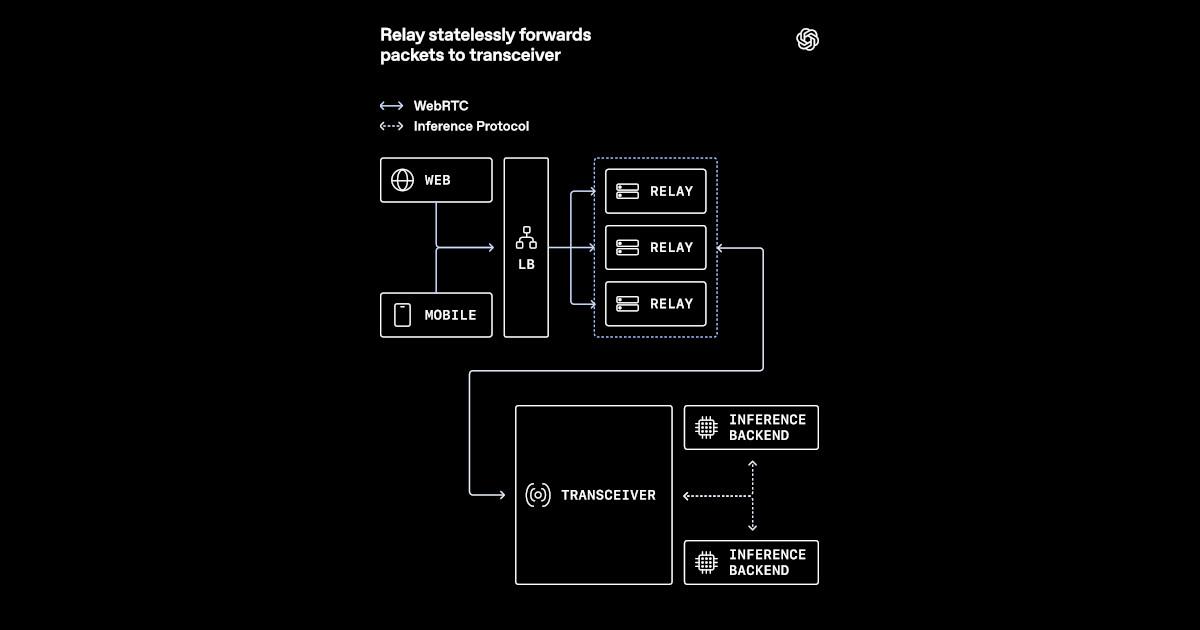
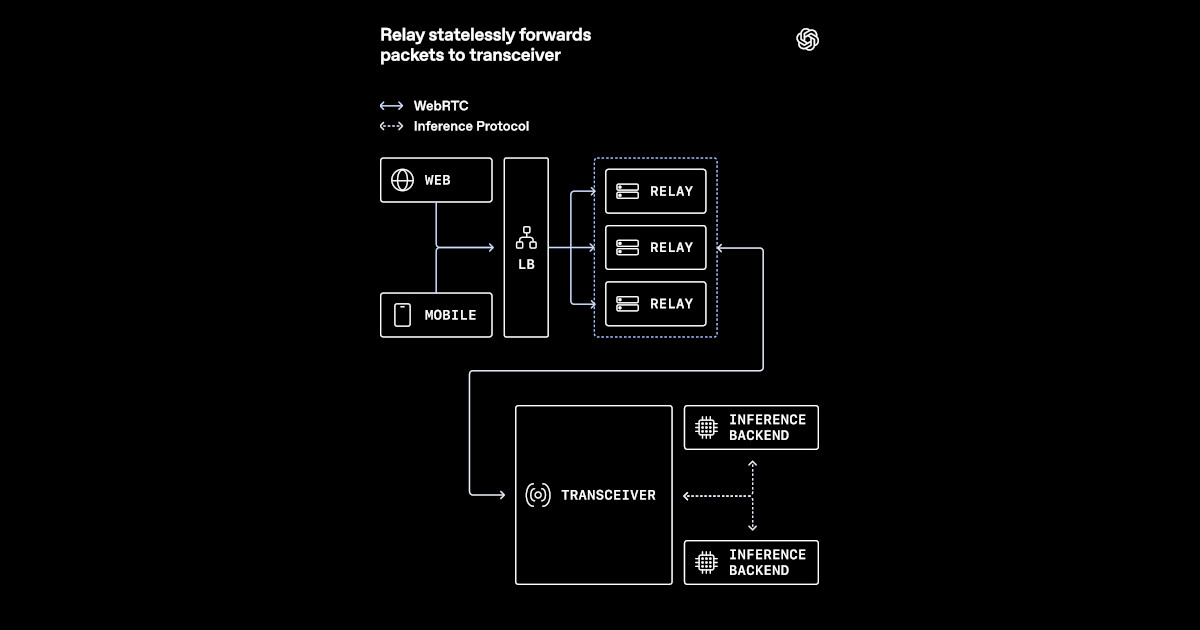
OpenAI recently outlined how it adapted WebRTC for low-latency voice AI at global scale. The new architecture replaced a conventional media termination model with a relay-transceiver design better suited to Kubernetes and cloud load balancers. It keeps WebRTC session state in a dedicated transceiver layer while using relays to reduce public UDP exposure and keep media routing close to users.

By Eran Stiller

🚀 I Delivered My First Website Project – Here’s What I Learned

I’m excited to share that I’ve successfully delivered my first real-world website project 🎉

🔗 Live Website: https://psc-malayali.vercel.app/

🧠 The Goal

The goal wasn’t just to build a website — it was to create something that actually helps students preparing for Kerala PSC exams:

Practice with mock tests

Access learning content easily

Smooth experience on mobile

⚙️ What I Built

This project is a Kerala PSC learning platform with:

Mock test system for exam practice

Admin dashboard to manage questions and content

Clean and modern UI

Mobile-first responsive design

Fast-loading pages

🔍 Challenges I Faced

Like any first project, there were a few challenges:

Designing a simple and usable mock test flow

Managing dynamic data through an admin dashboard

Keeping the UI clean while handling multiple features

Ensuring good performance across devices

Solving these helped me understand how real-world applications are built beyond tutorials.

💡 What I Learned

Real projects are very different from practice projects

Building useful features matters more than just design

Performance and usability are critical, especially for mobile users

🚀 What’s Next

This is just the beginning.

I’m now focusing on building more real-world projects and platforms that solve practical problems.

If you’re working on something similar or have feedback, I’d love to connect 🤝

Read the Spec: Lock Intent Before you Implement

Spec Kitty presenting

I am coming to understand that different people want very different things from agentic coding.

That should not be surprising. Not everybody is building the same kind of software. Not everybody works in the same kind of organization. Not everybody is trying to solve the same problem when they open Claude Code, Codex, Cursor, Gemini, or any other coding agent.

Spec Kitty presenting

For some people, agentic coding is a way to explore.

They have an idea, but not yet a settled design. They want to try three versions of a UI, poke at an API shape, test a library, or build a throwaway prototype just to learn what the problem really is. That is a valid way to work. I do it too. When I am feeling out the shape of a piece of software, I often need the software to push back on my assumptions.

But that is not the only mode of software development.

And for many serious software teams, it is not the normal mode.

In most software companies I have worked with, it would not be acceptable to tell developers:

Go prototype several different things and bring them all back so product can decide which one we like.

That is not a process. That is expensive ambiguity.

It may work for a founder hacking on an idea over the weekend. It may work for a solo developer trying to understand a new domain. But in a team with product owners, business analysts, customers, delivery commitments, architecture constraints, compliance expectations, and release gates, the work needs to become explicit before implementation runs away.

That is what spec-driven development (SDD) means to me.

It is not paperwork for its own sake. It is not a nostalgic return to heavyweight requirements documents. It is not a way to slow engineers down.

Spec-driven development is about forming agreement.

Before code is written, the team needs a shared understanding of what the software is supposed to do. Product intent, customer intent, business rules, edge cases, non-goals, vocabulary, and constraints all need somewhere to live.

At this point in history, there is still no better medium for that than words.

We can draw diagrams. We can point to screenshots. We can link tickets and paste chat threads. But eventually, the thing we mean has to be expressed in language clearly enough that another person, or now another agent, can act on it.

This is the gap that agentic coding exposes so sharply.

Coding agents are very good at producing code. They are increasingly good at reading code. They can navigate large repositories, infer patterns, run tests, and make changes faster than any human team could have imagined a few years ago.

But they still need to know what we mean.

If the intent is vague, the output will be vague. If the vocabulary is inconsistent, the implementation will drift. If product and engineering have not agreed on the behavior, the agent will happily encode one interpretation while stakeholders are still carrying three others in their heads.

That is why “just let the agent build something” is not enough for team software.

The question is not whether agents can generate code. They can.

The question is whether the team has created a durable expression of intent that the agent can build from, reviewers can evaluate against, and future maintainers can understand.

This is where Spec Kitty is focused.

Spec Kitty accelerates the path toward those words. It helps break down intent into two different but connected artifacts:

The What: the specification.

What should the software do? Who is it for? What are the user scenarios? What are the acceptance criteria? What is explicitly out of scope?

The How: the plan.

How should the system change? What architecture decisions matter? Which files, services, data models, APIs, or workflows are involved? What are the risks, dependencies, and sequencing concerns?

That distinction matters.

A product owner should not have to specify implementation details to express customer intent. A developer should not have to infer product meaning from a half-written ticket. A reviewer should not have to reverse-engineer the intended behavior from a diff.

The spec and the plan create a bridge.

The SDD specification and plan bridge user intent with the code that gets written.

Then the work can be decomposed into work packages, reviewed against the stated intent, and accepted against clear criteria. Along the way, the team’s own rules can be applied: quality gates, common vocabularies, architecture constraints, testing expectations, glossary terms, review policies, and the hard-won best practices that have accumulated inside the organization.

That is the part people miss when they reduce spec-driven development to “write a prompt before coding.”

The spec is not just a prompt. It is a point of agreement. A control surface.

It is the place where a team says: this is what we mean, this is what matters, this is how we will know whether the work is done.

There will always be room for exploration. Sometimes you need prototypes. Sometimes you need a quick experiment. Sometimes you need to use the agent as a sketchpad before you know what you want.

But when the work becomes real, when other people depend on it, when the software has to fit into a product, a codebase, a customer promise, and a team process, the intent needs to be written down.

The future of software may be humans expressing intent and AI implementing it. But that future depends on our ability to express intent well.

So for me, it all comes down to one thing:

Read the spec.

Spec Kitty is an open source SDD framework for agentic coding. Try it out!

Make any quiz with AI in 30 seconds — and the three attempts it took to ship it

A user dragging across an AI response, selecting the preamble and trailing chatter along with the JSON, then pasting all of it into Quizzy and still getting a clean quiz

The sleepover

It was a Saturday afternoon. My son had friends coming over for a sleepover that night, and he wanted to host a quiz. I had said I’d help him build one. I had also told my partner I’d finish something else by 5pm.

The two promises were not compatible. (A typical excuse, I know.)

I sat down at the laptop and thought: just ask the AI. I opened ChatGPT and typed:

Create a 10 question quiz for 8 year old kids with a Minecraft theme. Only expert Minecraft players should get 100%. Make it tough.

Twenty seconds later I had a quiz. My son was reading the questions over my shoulder, suspicious.

“But but but but daddy — how will the AI know what I want?”

He was eight, and he was already asking the question every product manager eventually asks: who is in charge of the requirements here?

I showed him the prompt. I changed “Minecraft” to “Pokemon” and re-ran it. He watched a new quiz appear. He didn’t say anything, but he tilted his head in the way he does when he’s reconsidering whether something is magic.

That was the moment I thought: this should be a feature in Quizzy.

The cost wall

The naive version is two afternoons of work. Slap a form on a page, send the user’s input to an LLM, render the result.

The problem is the bill.

If I put my OpenAI key behind every user, I am paying for every quiz on Quizzy.earth. The economics of a free product where every action calls a paid API are bad in a predictable way: the more successful you are, the more it costs you. There’s no version of “this took off” that isn’t also “I am broke.”

Quizzy doesn’t charge for this. I don’t want it to. So the question wasn’t how do I add AI? — it was how do I add AI in a way where the user’s AI does the work?

That turned out to be the hard part. I tried three things.

Attempt 1: The BYO-AI form

The first idea was the obvious one. Build a small form: topic, difficulty, language. Press a button. The app composes a prompt you can copy.

You paste that prompt into whichever AI you already use. ChatGPT, Claude, Gemini, whatever. The AI spits out JSON. You paste the JSON back into Quizzy. The app parses it into a quiz.

In theory: elegant. The user pays for their own tokens. I pay for nothing. Everyone wins.

In practice: I was the only person on Earth who could use it.

The first problem was that most people don’t know what JSON is. I had built a flow that required users to understand a serialisation format, and most of them weren’t going to. I figured I could explain that part.

The second problem was the one I didn’t see coming, and my son was the one who found it.

I handed him the laptop to try it. He typed his topic into Quizzy, copied the generated prompt, pasted it into ChatGPT — and the moment the AI started typing, he selected the half-written response and pasted it back into Quizzy. He didn’t wait for the stream to finish. Why would he? On every other app he uses, when text appears, it’s done. He pasted half a JSON object, hit create quiz, and got an error.

He looked up at me. What did I do wrong?

He hadn’t done anything wrong. The product had. If an eight-year-old can’t build a quiz with this thing in under a minute, the product has failed — that was the rule I’d written down for Quizzy on day one, and I’d just watched it break in front of me. Even a kid should be able to build a quiz without friction.

I had built a feature for developers and shipped it to families.

Attempt 2: The magical disappear

The next idea was genuinely fun to think about.

What if the AI itself sent the quiz back to me?

The flow in my head:

  1. The user gets a prompt with a unique ID baked into it.
  2. They paste it into their AI.
  3. The AI generates the quiz and POSTs the JSON to /api/generate-quiz along with that ID.
  4. My backend stores it in Redis under that ID.
  5. The frontend has been polling (or sitting on a websocket) the whole time. The moment the ID lights up, the quiz appears.

The user does nothing. They paste a prompt, they watch their AI think for a few seconds, they look back at Quizzy and the quiz is just there. No copy. No paste. No JSON.

This would have been magic.

It didn’t work because, as it turns out, most AI agents won’t POST to an arbitrary URL. Some block it outright. Some require a tool the user hasn’t enabled. Some quietly refuse. The version of this that works in 2026 is not the version of this that works for a stranger using whichever AI they happen to have open.

Maybe one day. Not yet.

Attempt 3: The URL smuggle

If POST is forbidden, what about GET?

Most AI agents will “browse” or “search” a URL when asked. So what if the prompt told the AI to construct a URL where the entire generated quiz lived in the query string, and then to visit it? My server would parse the quiz out of the query params, stash it in Redis, same as before.

I built this one. It almost worked.

It died for two unromantic reasons. The first is that browsers and proxies cap URL lengths somewhere between 2k and 8k characters. A ten-question quiz with four options each blows past that without breaking a sweat. The second is that the AI’s built-in browser tools have their own opinions about what counts as a legal URL, and a 6k-character query string was not one of them. The requests never landed. The DNS resolved to nowhere useful. I was smuggling air.

So: I couldn’t hide JSON. I couldn’t avoid the copy-paste. And on mobile — where most of Quizzy’s traffic actually lives — every paste also means switching apps. Open Quizzy, copy prompt, swipe to ChatGPT, paste, wait, copy response, swipe back, paste again. App-switching on a phone is its own friction tax, and unlike the others, this one I couldn’t engineer my way out of in this version. The user’s AI is in a different app from mine, and the path between them runs through the OS.

So the remaining question was a smaller one: with all of that fixed in place, could the existing flow at least stop being a UX punishment?

What I actually shipped

The thing I keep reminding myself when I build for people who aren’t developers: users don’t want your product. They want the thing your product gives them. Every step you can absorb so they don’t have to think about it is the product.

I couldn’t remove the copy-paste step. But I could make it forgive almost anything.

Two changes did most of the work:

JSONL instead of JSON. Instead of asking the AI for one big JSON array, I ask it to emit one JSON object per line. Now if a user pastes a partial stream — three lines out of ten — I get a three-question quiz instead of an error. Their copy is imperfect; the parse is graceful. The quiz that appears is a little shorter than they expected, not a red banner.

jsonrepair for everything else. Users don’t just paste the JSON. They paste the AI’s whole response — including “Sure! Here’s your quiz:” at the top and “Let me know if you want me to tweak anything!” at the bottom. The jsonrepair package is forgiving in exactly the ways an LLM’s output is messy. It strips chatter, closes unclosed brackets, repairs trailing commas, fixes single quotes. It turns “almost JSON” into JSON.

A user dragging across an AI response, selecting the preamble and trailing chatter along with the JSON, then pasting all of it into Quizzy and still getting a clean quiz

Together: the flow still has a paste step, but the paste step almost never fails. The user sees a quiz appear. They don’t see the parser stitching their messy paste back into shape.

It is not the magical disappearing-prompt flow I wanted in attempt two. But it ships, it costs me nothing per quiz, and it works for grandparents pasting from ChatGPT on a Sunday morning.

End-to-end in Quizzy: fill in topic, difficulty, and language; copy the generated prompt; paste into an AI; paste the response back; watch the quiz appear

The thread

Every dead end I hit was a version of the same instinct: let the user’s tools do the work. That instinct was right. The trick wasn’t backing away from it — it was accepting that the rough edges of “the user’s tools” (partial pastes, friendly preambles, half-streamed responses) were my problem to absorb, not theirs.

Good UX, in this case, looked less like a clever pipeline and more like a tolerant parser. The clever architecture would have been more satisfying to build. It also wouldn’t have shipped.

Try it — and tell me how you’d do it

It’s live at quizzy.earth. Open it, pick a topic, generate the prompt, paste it into your favourite AI, paste the response back. Thirty seconds, no account, your tokens.

If you’ve solved “great UX on someone else’s API budget” in a way I haven’t tried — I’d love to hear it. Especially that magical disappearing version. I still think there’s a way to make it work.

R8 Minification Silently Killed My Android App’s Core Feature (And Tests Didn’t Catch It)

My CI pipeline was green. Unit tests passed. The APK built and signed without errors. I installed it on my Pixel 3. The app launched, looked perfect.

Then I tried to use it. Nothing happened.

No crash. No error dialog. No logcat stacktrace. The app’s entire core feature was just… gone. Like someone had hollowed it out and left the shell.

What I was building

Nudge is an open-source Android app blocker. You pick the apps you waste time on and set a delay (say, 30 seconds). Nudge forces you to wait before opening them.

It uses three Android system APIs that require special permissions:

  • AccessibilityService to detect which app is in the foreground
  • SYSTEM_ALERT_WINDOW to draw the delay countdown overlay
  • PACKAGE_USAGE_STATS to track daily screen time per app

The debug build worked flawlessly. I’d been testing it for weeks. The release build was supposed to be the same thing, just signed and minified.

It was not the same thing.

The 2MB red flag I ignored

Here’s what the release APK looked like:

debug APK:   12.4 MB
release APK:  2.1 MB

I should have questioned that 83% size reduction. Instead, I thought “wow, R8 really does its job.” It did its job too well.

R8 is Android’s default code shrinker and optimizer. It removes unused classes, inlines methods, renames symbols, and strips dead code. For most apps, it’s free performance. For apps that rely on system-level callbacks, it’s a silent killer.

What R8 actually stripped

R8 analyzed my code’s call graph and decided several things were “unused”:

  1. NudgeAccessibilityService – The Android system instantiates this class by reading the manifest. R8 doesn’t know that. It saw no new NudgeAccessibilityService() in the code, so it stripped it.

  2. BlockOverlayActivity – Launched via an explicit Intent constructed at runtime. R8 traced the static references but couldn’t follow the dynamic class resolution.

  3. Hilt entry points – Dagger/Hilt uses annotation processing and reflection to wire dependencies. R8 stripped the interfaces that Hilt’s generated code needs at runtime.

The result? The app installed. The UI rendered. But the AccessibilityService never registered with the system. No foreground app detection. No overlay. No blocking. The app was a beautiful, non-functional shell.

Why tests didn’t catch it

This is the part that stung. I had tests. They passed.

# From our GitHub Actions workflow
- name: Run tests
  run: ./gradlew test

- name: Build release APK
  run: ./gradlew assembleRelease

The problem: ./gradlew test runs against the debug build variant. The release build with R8 is a completely different artifact. My tests verified the debug build worked. Then CI built a release APK that was structurally different.

This is equivalent to testing your code on localhost and deploying a Docker image built with different flags. The artifact you tested is not the artifact you shipped.

The fix (and why I didn’t just add ProGuard rules)

The obvious fix is ProGuard keep rules:

# AccessibilityService instantiated by the system via manifest
-keep class com.astraedus.nudge.service.NudgeAccessibilityService { *; }

# Overlay activity launched via Intent
-keep class com.astraedus.nudge.ui.overlay.BlockOverlayActivity { *; }

# Hilt entry points use reflection
-keep interface com.astraedus.nudge.service.NudgeAccessibilityService$NudgeAccessibilityEntryPoint { *; }

I wrote these rules. Then I disabled R8 entirely.

buildTypes {
    release {
        isMinifyEnabled = false
        signingConfig = signingConfigs.getByName("release")
    }
}

Why? Nudge has zero internet permission. There’s no network call to intercept, no API key to extract, no proprietary algorithm to reverse-engineer. The source code is public on GitHub. Minification was adding build complexity and production risk for zero security benefit.

ProGuard rules are the right answer for apps that need obfuscation. For open-source apps with system-level APIs, the risk-reward math doesn’t work out. Every new service class or Hilt module becomes a potential R8 landmine unless you maintain the keep rules in lockstep.

What I should have done differently

1. Test the release build, not just the debug build.

- name: Run tests against release variant
  run: ./gradlew testReleaseUnitTest

- name: Build and install release APK on emulator
  run: |
    ./gradlew assembleRelease
    adb install app/build/outputs/apk/release/app-release.apk
    # Smoke test: verify the accessibility service registers
    adb shell dumpsys accessibility | grep -q "NudgeAccessibilityService"

This would have caught the stripped service in CI before it reached a device.

2. Treat APK size deltas as a signal.

A debug-to-release size reduction of more than 50% warrants investigation. R8 removing 83% of your APK means it’s removing a lot of code it thinks is dead. Some of it might not be.

3. Verify system service registration in your test suite.

For any Android app that uses AccessibilityService, NotificationListenerService, or DeviceAdminReceiver, add a test that verifies the service appears in the system’s service list after installation. These services fail silently when missing.

Bonus: the permission disclosure pattern

Getting Google Play to approve an app with QUERY_ALL_PACKAGES, AccessibilityService, and SYSTEM_ALERT_WINDOW is its own adventure. Google’s review team needs to see explicit in-app disclosure of what each permission does and why.

Here’s the pattern I used in the onboarding flow:

@Composable
private fun PermissionCard(
    icon: ImageVector,
    title: String,
    description: String,
    onClick: () -> Unit
) {
    Card(
        modifier = Modifier.fillMaxWidth(),
        onClick = onClick
    ) {
        Row(modifier = Modifier.padding(16.dp)) {
            Icon(icon, contentDescription = null)
            Spacer(Modifier.width(12.dp))
            Column {
                Text(title, style = MaterialTheme.typography.titleSmall)
                Text(description, style = MaterialTheme.typography.bodySmall)
            }
        }
    }
}

Each card explains what the permission accesses, why, and explicitly states what it does NOT do:

“Detects which app is in the foreground so Nudge can trigger your block rules. Does not read your messages, keystrokes, or screen content.”

The “does not” part matters. Google’s review checks for proactive privacy disclosure, and users are (rightly) suspicious of AccessibilityService apps.

The takeaway

R8 minification is not compression. It’s a code transformation that decides what your app needs at runtime. When those decisions are wrong, nothing crashes. Nothing logs an error. The feature just doesn’t exist.

If your Android app uses system callbacks (AccessibilityService, ContentProvider, BroadcastReceiver registered in manifest), either maintain ProGuard rules religiously or ask yourself whether minification is earning its keep.

And whatever you do: test the artifact you ship, not the artifact you develop against. That gap is where bugs like this live.

Nudge is open source: github.com/astraedus/nudge

I Didn’t Build a Crypto App. I Built a Way to Survive Web3

(https://app-br03xkw7abk1.appmedo.com)

I Think Most People Learn Crypto the Wrong Way
And honestly… I don’t even think it’s their fault the more time I spent in Web3 spaces, the more I noticed that most people don’t actually enter crypto because they understand blockchain.

They enter because:

Somebody tweeted “100x gem”
A friend sent a Telegram link
An influencer posted rocket emojis
Everybody suddenly started yelling “WAGMI”

Crypto onboarding today is mostly emotional, and that became the exact reason I started building KRYPTIQ during the Build with MeDo Hackathon.
Not another “learn blockchain” platform.
Not another dashboard full of charts and confusing terms.
I wanted to build something that actually teaches people how Web3 behaves.
Because nobody really prepares beginners for:

  1. hype cycles
  2. Meme coin psychology
  3. fake urgency
  4. influencer manipulation
  5. Rug pulls
  6. emotional trading
  7. community behavior and narrative-driven markets

Most platforms teach definitions.

But crypto is culture too.

It’s internet psychology.
It’s attention-grabbing.
It’s behaviour.
It’s emotion.

And I kept thinking:

What if learning Web3 felt less like reading documentation… and more like surviving the internet?

That idea became KRYPTIQ: a gamified AI-powered Web3 learning platform that feels like Duolingo, crypto Twitter and interactive storytelling and an AI mentor all combined together. Instead of boring tutorials, users learn through real scenarios.
Things like:
“A random influencer says this meme coin is going to explode tonight. What do you do?”

Or:

“Your entire timeline suddenly starts talking about AI coins. Is this a real narrative shift or just attention farming?”

The goal is to teach users how to THINK in crypto, not just memorise vocabulary, and honestly, MeDo helped bring that vision to life way faster than I expected. One thing I loved while building was how conversational the process felt. I wasn’t just prompting for pages.
I was thinking like this:

  1. a product designer
  2. a frontend developer
  3. a beginner entering crypto for the first time
    Someone overwhelmed by Web3 culture
    Someone curious but scared of getting rugged

So instead of saying:

“Generate a crypto education app.”

I structured the conversations around emotions, behaviour, and user experience.

I focused heavily on:

immersive onboarding
futuristic dark-mode UI
smooth gamified flows
interactive lesson cards
conversational AI guidance
XP systems
achievement badges
personality analysis
scenario-based simulations

One of the most impressive things MeDo helped generate was the interactive learning structure itself.

The platform evolved from a simple idea into multiple learning modes, like:Survival Mode Meme Coin Mode Solana Mode DeFi Mode and Narrative Radar
Each one teaches a different side of Web3 culture and decision-makingProbably my favourite feature is the “Crypto Personality Engine”As users make decisions during simulations, the AI starts identifying behaviour patterns like the following:

  1. FOMO trading
    2 hype-chasing
  2. overconfidence
  3. Cautious analysis
    1. narratives following

So the app doesn’t just teach users.

It starts teaching them about themselves too, and that felt incredibly important to me because a lot of losses in crypto are emotional before they are technical.
From a technical perspective, MeDo also helped speed up:

frontend generation
responsive layouts
modular UI sections
gamified interfaces
conversational interactions
structured navigation flows

I also explored integrations and scalable ideas around:

AI-generated learning scenarios
narrative analysis
wallet-based progression systems
on-chain certificates
ecosystem-specific learning paths

But honestly, beyond the technical side, I think the biggest thing this project taught me is this:

Web3 education doesn’t need to feel intimidating.

It can feel playful.
Human.
Interactive.
Curious.
Social.

And maybe that’s the future of onboarding people into crypto safely, not fear or complexity.

Just helping people understand the internet they’re stepping into before the internet teaches them the hard way.

BuiltWithMeDo

How We Got a CISA GitHub Leak Taken Down in Under a Day

GitGuardian Interactive Demo

On May 14, 2026, GitGuardian found what looked like leaked CISA secrets in a public GitHub repository named Private-CISA. It held 844 MB of data across the working tree and Git history. The working tree was 498 MB; the rest was Git history and objects.

The repository contained:

  • CI/CD build logs and deployment workflow documentation.
  • Kubernetes manifests, ArgoCD application files, and secret-related YAML files.
  • Terraform infrastructure code and related bundles.
  • GitHub Actions workflows and GitHub organization automation.
  • Internal documentation backups, including large OneNote / .docx exports.
  • Scripts for GitHub, Kubernetes, ArgoCD, and infrastructure operations.
  • References to AWS accounts, IAM identities, service accounts, internal service endpoints, registry locations, and secret-management paths.

The exposed material provided a detailed view into cloud infrastructure, deployment workflows, software supply-chain tooling, and internal operational practices.

At first, we thought it was a hoax, given how suspicious the directory names (Backup-April-2026/, All Backups/, LZ-Artifactory/, Kubernetes-Important-Yaml-Files/, ENTRA ID - SAML Certificates/ …), file names (external-secret-repo-creds.yaml, CAWS GitHub Token.txt, Important AWS Tokens.txt, AWS-Workspace-Firefox-Passwords.csv, Kube-Config.txt …), and their contents (private keys, personal and professional GitHub tokens, AWS secrets, …) seemed too good to be true.

Personal documents, hostnames, and the careful organization of the files changed our minds. The repository was a catalogue of unsafe practices: plain-text passwords, backups committed to Git, and explicit instructions to disable GitHub’s secret scanning

Our research team reported the leak through the CERT/CC portal on May 14 at 4:14 PM CET and worked personal contacts in parallel to speed disclosure.

GitGuardian Public Monitoring surfaced the leak first. By May 13, our Good Samaritan program had already sent nine emails to the commit author.

By the morning of May 15 we still had only the automatic acknowledgment. With the weekend approaching, we contacted Brian Krebs to forward the leak to his CISA contacts, and activated partners for a direct line in.

Around 16:00 CET on May 15 we reached CISA directly. The repository went offline around 6:00 PM EST on May 15, 2026. Seeing the repository taken down so fast was a relief. Credit to CISA for moving fast — most of our disclosures take far longer, and some are never fixed.

Disclosure Timeline

  • November 13, 2025 – Creation of the public Private-CISA Github repository and first exposures
  • May 14, 2026 – Incident detected by GitGuardian and reported to CERT/CC
  • May 15, 2026 – Incident directly reported to CISA by GitGuardian
  • May 15, 2026 – The Private-CISA GitHub repository is taken offline

GitGuardian Interactive Demo

The AI That Manages Its Own Memory: Why Recursive Language Models Are the Next Big Shift in AI

What I learned reading one of the most important AI papers of 2025, and why every team building with AI agents needs to understand this.

I have been following AI research seriously for a while now. I read a lot of papers, follow a lot of labs, and try to separate genuine progress from hype. Most research is incremental. Every once in a while something comes along that reframes how I think about a fundamental problem.

The Recursive Language Model is one of those things.

It does not come with a product launch or a benchmark leaderboard. It comes from a research team at Prime Intellect who looked at the core limitation of every AI agent in production today and found a cleaner answer to it. I want to share what I learned, why I think it matters, and why I believe the teams that understand this now will be ahead of the ones who discover it later.

The Real Reason AI Agents Break Down

If you have ever deployed an AI agent for a real task, not a demo, but actual production work, you have probably noticed a pattern. The first few steps look great. The agent reads, searches, reasons, takes action. Then somewhere around step twenty or thirty, things start to go wrong. Answers get less precise. Context from earlier steps seems to get lost. The model starts repeating itself or losing track of what it was trying to do.

This is not a bug in any particular model. It is a structural problem baked into how language models work.

Every tool call an agent makes returns output into its context window. Every webpage it opens, every file it reads, every search result it processes fills that window further. A single webpage opened without truncation can add more than a million tokens to the context. After enough steps, the model is not reasoning from a clean working memory. It is reasoning from an enormous pile of accumulated text, most of which is no longer relevant to the current step.

Researchers have a name for what happens next: context rot. The model’s effective reasoning quality degrades as the context grows. It is not that the model becomes unintelligent. It is that the signal it needs is buried under so much noise that useful reasoning becomes increasingly difficult.

The industry has two standard responses to this problem. The first is to build bigger context windows. The second is to periodically compress the history through summarization. Both responses have genuine costs that are worth being honest about.

Bigger context windows mean higher costs. Every token in the context must be processed on every generation step, so cost rises linearly with context length. More importantly, even the best models show degraded performance on very long contexts regardless of whether the window is technically large enough to hold the content.

Summarization is the more popular approach, and on the surface it seems sensible. Keep a rolling summary of what has happened so far and use that instead of the full history. The problem is information loss. Every time you compress, you lose detail. Some of that detail seemed unimportant at the time and turns out to be critical later. Over a long task with many compression steps, those losses accumulate and you end up with an agent that is working from an increasingly distorted picture of what it actually did.

Neither of these approaches solves the problem. They manage it, at a cost.

What a Recursive Language Model Actually Is

The core idea behind the RLM is worth understanding carefully because it is both simple and genuinely different from what came before.

Instead of having the model ingest all of its input data directly into its context window, the RLM gives the model access to a persistent Python environment. Large inputs, documents, datasets, web content, API responses, all of it lives inside that Python environment rather than in the model’s context. The model cannot see that data by default. It can only access data by writing Python code to retrieve, filter, search through, or transform it.

This means the model’s context window stays small and clean by design. It contains the current task, the current reasoning, and whatever the model has explicitly chosen to pull in. Nothing accumulates passively.

The second key mechanic is sub-LLM delegation. From within the Python environment, the main model can instantiate fresh sub-LLMs and give them work to do. It can pass a chunk of a large document to a sub-LLM and ask it to extract specific information. It can pass a web page to a sub-LLM and ask it to answer a specific question about the content. The sub-LLM does the reading. The sub-LLM does the processing. What comes back to the main model is a tight, focused answer.

These sub-LLM calls can be parallelized. On a research task that requires investigating ten different threads, the main model can dispatch all ten sub-LLMs simultaneously and synthesize their results at once rather than working through them sequentially.

The third mechanic is the answer variable. Rather than generating a final response in a single pass, the RLM writes its answer into a Python variable. It can write an initial attempt, print it out to inspect it, compare it against the source material, identify errors, and correct them using string operations. The answer is produced through iteration rather than committed in a single generation. This matters especially for tasks that require precision, like copying complex structured data, where a single-pass generation almost always contains small errors that an iterative process can catch and fix.

What you get when these three things work together is a model that keeps its own working memory compact, offloads intensive reading and processing to disposable sub-models, and refines its outputs through inspection and correction rather than hoping the first attempt is right.

Why This Is Not Just Another Context Trick

I want to be specific about why the RLM is different from every other approach to context management, because that distinction is what makes it genuinely interesting.

Every other method involves some form of forgetting. A sliding window drops the oldest content. Summarization replaces detailed content with a compressed version. Even the most sophisticated compression techniques are lossy transformations. Once information is compressed or dropped, it cannot be recovered.

The RLM never forgets anything. The raw data is always present in the Python environment. The model can retrieve any piece of it at any point in the task with a line of code. What changes is not whether the information exists but whether it is currently loaded into the main model’s attention. This is a completely different relationship with information than any summarization or compression approach can offer.

There is also a compounding benefit to this design. Because the main model’s context stays small, every token in that context is relatively more important. The model is not diluting its attention across a vast accumulated history. It is reasoning from a lean, curated working memory that it has actively constructed. The quality of reasoning at step fifty of a task should look much more like the quality of reasoning at step five, because the context at step fifty has been actively managed to stay relevant.

The aspect of the RLM that I think is most underappreciated is that it is trainable end to end. The scaffolding itself can be the subject of reinforcement learning. A model can be trained directly on the RLM framework with rewards tied to how well it completes long-horizon tasks. Through that training, the model learns when it is better to delegate a piece of work to a sub-LLM versus handling it directly, how much context to pass to a sub-LLM to get a useful answer, how to phrase questions to sub-LLMs so the responses are actually helpful, and when an iterative answer is good enough to finalize.

These are not skills that can be specified through hand-written rules or prompt engineering. They require learned judgment developed through practice on real tasks. The RLM framework makes that training possible in a way that previous approaches do not.

What the Research Shows

Prime Intellect ran the RLM against four different test environments, comparing it against a standard LLM with access to the same tools. I want to describe what they found in plain terms rather than presenting it as a ranking, because the nuances matter.

On deep research tasks, the kind that involve searching the web, following multiple links, and synthesizing information from many sources, the RLM consistently outperforms the standard model. On complex queries, some open-source models showed performance close to double what they achieved without the RLM scaffold. The token analysis makes clear why. When the RLM uses sub-LLMs to do the web reading, the main model’s context stays compact. The standard model accumulates all that web content directly and its reasoning degrades under the weight of it.

On long-context understanding tasks, the gap is even more stark. When inputs reach one million characters or more, the standard LLM simply fails. The API rejects the inputs as exceeding the context window. The RLM maintains meaningful performance at inputs up to around 1.75 million characters because it never tries to load the full input at once. It accesses the data in chunks through the Python environment and uses sub-LLMs to process those chunks as needed.

On tasks that require producing precise outputs, like verbatim copying of complex structured data, the RLM is consistently better. The iterative answer mechanism is the reason. The model can write a first attempt, identify where it made errors, and correct those specific errors rather than committing to a single generation. For tasks like reproducing JSON or alphanumeric codes, where small errors are easy to make and easy to fix once spotted, this is a significant advantage.

The researchers are honest about where the RLM does not help. On straightforward mathematical reasoning tasks, the standard model performs better. The explanation is that models have been heavily trained on a specific format for math tool use, and the RLM’s scaffolding creates overhead without offering a compensating benefit on tasks of that type. This is a training data mismatch, not a fundamental limitation, and it is exactly the kind of gap that closes once models are trained natively on the RLM scaffold.

It is worth emphasising something about these results. They were produced with existing models called through standard APIs with absolutely no fine-tuning for the RLM interface. These are floor numbers. They represent what happens before any lab has done the obvious work of training a model to be a good RLM user. The research team is explicit that they expect training to unlock substantially larger gains.

What Changes When Models Are Trained for This

The results from off-the-shelf models are already compelling in places. But the more interesting question is what happens when a model is trained end to end to operate within the RLM framework.

A model that has been trained through reinforcement learning on the RLM scaffold learns genuine strategic judgment about context management. It learns to be selective about what it pulls into its own context versus what it delegates. It learns to construct sub-LLM queries that return genuinely useful summaries rather than verbose outputs. It learns to manage the iterative answer process efficiently, knowing when a first draft is close enough to refine and when it needs to be started over.

Those learned skills translate directly into the ability to handle the tasks that currently require teams of humans working over extended periods. A thorough audit of a large codebase is not bottlenecked by intelligence. It is bottlenecked by the ability to maintain coherent reasoning across hundreds of files and thousands of observations made over many hours. An RLM trained to manage its context well can do that in a way that no current system can.

The same applies to long-horizon research, multi-step legal analysis, large-scale data extraction, and any workflow where sustained coherent operation across many steps is the bottleneck rather than raw capability on any individual step.

Why the Architecture of the RLM Is Itself an Advantage

One thing I keep coming back to is how the RLM is structured from the outside.

To any system that calls it, an RLM looks identical to a standard LLM. It accepts text input and returns text output. There is no new API format to learn, no restructuring of the calling system required, no changes to how the task is framed. A company that currently uses a standard LLM through an API can adopt RLM capabilities without rewriting anything on their end.

This matters for adoption. The history of technology is full of genuinely better solutions that failed because the switching cost was too high. The RLM has essentially no switching cost. The entire complexity of context management is internal to the model. From the outside it is invisible.

What I Think This Means

I want to be honest about where I stand on this.

The gap in AI today is not about intelligence on individual tasks. Models are already capable enough to handle most of what knowledge workers do on any given task when that task is contained. The gap is about sustained operation. The ability to work for hours or days across a large, evolving body of information without losing coherence. The ability to maintain the thread of a complex project from step one to step one hundred without the context of the early steps becoming inaccessible.

The RLM is the clearest solution to that gap that I have seen. It does not paper over the problem with a bigger window or a lossier compression. It redesigns the relationship between the model and its information so that the problem does not arise in the same way.

The research is published. The framework is open. The teams that take it seriously now, before purpose-trained models exist and before this becomes obvious to everyone, are the ones who will be positioned well when those models arrive.

Read the Full Research

Everything I have described here is covered in much greater technical depth in the original paper. If you work in AI engineering, agent systems, or anywhere that long-horizon tasks matter, I think it is genuinely worth reading in full.

Full paper: https://arxiv.org/html/2512.24601v3

If you found this useful, share it with someone who is building on AI agents. The more openly this conversation happens, the better the tools we all end up with.

Screenshots Are Not Browser State

Screenshots Are Not Browser State

A coding agent that only sees screenshots is debugging theater.

Screenshots show what broke. They do not show why it broke.

The useful loop is real browser state: console errors, network requests, performance traces, DOM state, storage, cookies, session context, and the exact page the user is stuck on.

That distinction moved from niche to obvious today. Chrome for Developers announced that Chrome DevTools for agents is stable: coding agents can use Chrome DevTools MCP to test web apps in Chrome and inspect console logs, network requests, performance traces, and Lighthouse reports.

That is the right direction. Agents do not need prettier screenshots. They need runtime evidence.

Screenshots show symptoms

A screenshot can tell an agent that a checkout button is disabled.

It cannot reliably tell the agent:

  • which request failed;
  • whether the API returned 401, 403, 429, or 500;
  • whether a CSP rule blocked a script;
  • whether hydration failed;
  • whether a feature flag changed the DOM;
  • whether local storage is stale;
  • whether the user is in the wrong workspace;
  • whether the bug only happens behind a logged-in account.

HTML snapshots have a similar problem. They are useful, but they are still partial. They miss runtime behavior, timing, auth state, network edges, and the browser’s actual execution context.

A developer would open DevTools. A useful coding agent should be able to do the same.

The real browser loop

A real browser loop gives an agent evidence it can act on:

  • Console: stack traces, warnings, failed hydration, client-side errors.
  • Network: request payloads, response codes, headers, redirects, CORS failures.
  • Performance: long tasks, layout shifts, slow resources, Lighthouse reports.
  • DOM and accessibility state: what the page actually rendered, not what the template promised.
  • Cookies and storage: auth state, workspace IDs, stale tokens, feature flags.
  • Session context: the logged-in page where the user actually hit the problem.

This is why Chrome DevTools MCP matters. It turns the browser from a picture into an evidence source.

The same pattern is showing up elsewhere too. Developers are building tools that let coding agents drive real Chrome, inspect multi-tab sessions, and return structured results that agents can parse. Browser panes inside agent workspaces are becoming more than previews; they are becoming review surfaces, collaboration surfaces, and handoff surfaces.

The direction is clear: browser work is becoming part of the agent runtime.

Machine-readable browser evidence

The next step is not just “let the agent see Chrome.” It is letting the agent receive browser evidence in a form it can use.

A screenshot forces the model to infer. A structured browser result lets the agent reason.

For example, a browser run can return:

  • the action attempted;
  • the URL and frame where it ran;
  • console errors observed;
  • network failures observed;
  • performance warnings;
  • resulting DOM or accessibility state;
  • whether the intended after-state appeared.

That matters because agents are iterative. The output of one browser step becomes the input to the next coding step. If the browser result is only an image, the agent is guessing. If the browser result is structured evidence, the agent can repair, rerun, and verify.

This is the practical meaning of “screenshots are not browser state.”

Logged-in Chrome changes the problem

For local development, real browser evidence is mostly about debugging.

But real browser work does not stop at local development.

Many useful tasks happen behind login:

  • update a billing setting;
  • check a support inbox;
  • publish a CMS post;
  • verify a CRM record;
  • upload a file to a client portal;
  • refund an order;
  • change an ad campaign;
  • inspect a production dashboard.

At that point, the browser is no longer just an inspection surface. It is authority.

A signed-in Chrome session contains cookies, SaaS access, internal tools, live customer data, and the ability to change state. If an agent can operate that session, it is not merely “using a browser.” It is acting through delegated authority.

That is a different product boundary.

Prompts are not permissions

A prompt that says “be careful” is not a permission system.

A delay before deletion is not a permission system.

A log after the fact is not a permission system.

For signed-in browser workflows, the control layer needs to be explicit:

  • which browser session is exposed;
  • what sites or workspaces are in scope;
  • which actions are read-only;
  • which writes require approval;
  • where the approval line sits;
  • what receipt proves what changed;
  • how access can be revoked.

The approval line is important. It is the point where browser-agent memory stops being notes and becomes a control surface.

Before the line, the agent can gather evidence: page state, previous failures, current auth boundary, intended action.

At the line, a human or policy gate decides whether the agent may write.

After the line, the system needs a receipt.

Receipts are not logs

Logs are useful for debugging a run.

Receipts are useful for trusting delegated work.

A browser-action receipt should answer questions a team can check later:

  • who or what agent acted;
  • which browser session and account context were used;
  • what authority was delegated;
  • why the action was allowed;
  • what data moved;
  • what changed on the page;
  • what after-state proves the change landed;
  • what can be rolled back or revoked.

That is different from “the agent clicked a button.”

It is also different from a screenshot. A screenshot may show the final page. A receipt should preserve the authority, decision, action, and evidence trail around the change.

This is where real browser loops and delegated browser authority meet.

Where BrowserMan fits

Chrome DevTools MCP is a strong answer for local coding loops. It gives agents runtime browser evidence: console, network, performance, Lighthouse, and the real page.

BrowserMan’s lane is adjacent.

BrowserMan gives agents controlled access to a user’s real Chrome session. The agent can run anywhere, while the signed-in browser stays on the user’s device. Cookies stay local. Access can be scoped, gated, audited, approved, and revoked.

The useful framing is not “more browser control.”

It is controlled delegation of real browser authority.

Local dev loop:

Can the agent inspect and fix what is happening in Chrome?

Delegated browser workflow:

Can the agent use the right signed-in session, within the right scope, with approval before risky writes and receipts after changes?

Both matter. They solve different parts of the same shift: agents are moving from text into real browser work.

The browser is becoming an agent runtime

The browser is not just a viewport anymore.

For coding agents, it is an evidence source.

For workflow agents, it is an action surface.

For signed-in work, it is an authority surface.

That means the next generation of browser-agent tooling should not be judged only by whether the agent can click through a page. It should be judged by whether the system can preserve the state, authority, approval, and proof around the work.

Screenshots are not enough.

Real browser state is the evidence.

Logged-in browser state is the authority.

And delegated authority needs approval lines and receipts.