Beyond Code: Engineering Measurement for Open-Source Traction on GitHub

For many developers and engineering teams, publishing an open-source project on GitHub is just the first step. The real challenge often begins when trying to gain traction, attract stars, and build a vibrant community around the codebase. It’s a common dilemma, recently highlighted in a GitHub community discussion initiated by Shiv0087, which sought practical strategies beyond mere promotion. The insights shared underscore a crucial truth: true project growth is a holistic endeavor, combining robust development practices with smart community engagement, all of which can be viewed through the lens of engineering measurement.

Gaining traction isn’t merely about writing excellent code; it’s about making that code accessible, trustworthy, and easy to adopt. For dev teams, product managers, and CTOs, understanding these dynamics is key to maximizing the impact and return on investment of open-source initiatives. Here’s a breakdown of key strategies that actually move the needle, focusing on usefulness, quality, and visibility, and how they contribute to critical KPI engineering for your projects.

Frictionless Onboarding: The Gateway to Adoption and Measurable Engagement

The initial interaction a potential user has with your repository is critical. It determines whether they stay or leave. Think of your repository’s landing page as a critical engineering measurement point for user experience and time-to-value. Reducing friction here directly correlates with higher adoption rates and lower abandonment.

Your README is Your Product’s Landing Page

- **Immediate Problem-Solving:** The first two sentences of your README must explain exactly what problem your project solves. Don't make users guess.

- **Visual Engagement:** Incorporate visual aids like GIFs, clear architecture diagrams, or terminal recordings to demonstrate its utility instantly. A picture (or a short video) truly is worth a thousand words when it comes to illustrating functionality.

One-Command Setup: Lowering the Barrier to Entry

If someone has to spend 20 minutes configuring dependencies or troubleshooting your stack, they will leave. This is a direct hit to your project’s usability score. For effective kpi engineering around adoption, focus on ease of setup:

- **Containerization:** Providing a `docker-compose.yml` file or a ready-to-use containerized version allows users to spin up and test your project with a single command.

- **Automation Scripts:** Offer quick automation scripts (e.g., `./setup.sh`) that handle common setup tasks. The goal is to make it so they can test your project with minimal effort.

This ease of setup is a direct indicator of project maturity and user-centric design, providing valuable data for your engineering measurement framework.

CI/CD & Reliability Signals: Building Trust Through Transparency

Having active workflow badges (like GitHub Actions for passing builds or tests) signals to visitors that the project is stable, actively maintained, and ready for real-world use. These are not just development best practices; they are visible trust signals. For delivery managers and CTOs, these badges represent a commitment to quality and a reduction in potential integration headaches for downstream users.

One-command setup for an open-source project with DockerOne-command setup for an open-source project with Docker

Strategic Visibility: Beyond Standard Promotion

Simply dropping links on social media is rarely effective. True visibility for an open-source project requires a strategic approach that targets the right audience and provides genuine value. This is where your marketing efforts become part of your kpi engineering for outreach and community growth.

Community Integration: Go Where Your Users Are

Instead of broadcasting, find where the people who actually need your tool hang out. Share the story of why you built it on specific subreddits, Discord communities, or developer forums. Lead with the headache you were trying to solve, rather than just asking for stars. This approach builds authentic connections and attracts users who genuinely need your solution.

The “Awesome” Ecosystem: High-Intent Traffic

The GitHub “Awesome” lists are curated collections of the best resources for specific niches (e.g., awesome-selfhosted, awesome-sysadmin). Find an awesome-* list that fits your project and submit a pull request to add your tool. This drives consistent, high-intent traffic from developers actively looking for exactly what you built, making it a highly efficient channel for user acquisition that can be tracked as part of your engineering measurement.

Strategic visibility and community integration for open-source projectsStrategic visibility and community integration for open-source projects

Open the Door for Contributors: Scaling Your Project with Community Power

People who contribute to your project will naturally become its biggest advocates, starring it, sharing it, and helping it grow. Fostering a contributor-friendly environment is a critical component of sustainable project growth and a key aspect of kpi engineering for community health.

A Solid CONTRIBUTING.md File

This file is your guide for potential contributors. It should clearly outline the process for submitting issues, proposing features, and contributing code. Make it easy to understand and follow, removing any ambiguity that might deter new contributors.

“Good First Issue” and “Help Wanted” Tags

Actively tag easy, well-documented bugs or small feature requests with good first issue or help wanted. This lowers the barrier for new contributors, giving them a clear entry point to make a meaningful impact without feeling overwhelmed. It’s a proactive way to build your contributor base, which is a powerful metric in your engineering measurement dashboard.

Developers collaborating on an open-source project with Developers collaborating on an open-source project with ‘good first issue’ tags

Conclusion: A Holistic, Measurable Approach to Open-Source Success

Gaining traction on GitHub isn’t a passive outcome; it’s the result of deliberate, strategic actions across usefulness, quality, and visibility. For engineering leaders, product managers, and CTOs, these aren’t just development tips; they are actionable strategies that directly influence project adoption, community growth, and ultimately, the impact of your open-source contributions.

By focusing on frictionless onboarding, strategic community engagement, and fostering a welcoming environment for contributors, you move beyond simply publishing code to actively engineering its success. Each of these areas provides valuable data points for your engineering measurement and kpi engineering efforts, allowing you to track progress, identify areas for improvement, and demonstrate the tangible value of your open-source endeavors. Start implementing these strategies today and watch your projects gain the traction they deserve.

Designing for Scale: Repository Structures that Boost Software Development Productivity

The challenge of designing a repository structure that scales with a growing project is a common hurdle for development teams, product managers, and CTOs alike. As projects expand with more contributors, features, and potentially microservices, maintaining agility and ensuring smooth onboarding becomes paramount. A recent discussion on GitHub, initiated by Pranava-M, delved into this very topic, seeking practical insights on long-term maintainability, balancing modularity with simplicity, and avoiding common pitfalls that can cripple software development productivity.

The conversation, found here, offered valuable strategies to enhance development workflows and avoid the dreaded ‘spiraling out of control’ scenario. Let’s unpack the key takeaways for building resilient and efficient repository structures.

Monorepo vs. Polyrepo: When Scale Becomes a Bottleneck

Pranava-M’s initial concern about monorepos becoming a bottleneck resonated with many. The truth is, a monorepo doesn’t fail at some ‘magic contributor count.’ Instead, it becomes a liability when three critical issues converge:

  • Unbearable CI/CD Runtime: When builds and tests for the entire repository consistently exceed 10-15 minutes, developers often start bypassing essential checks to save time. This erodes confidence in the codebase and introduces risk.

  • Blurred Ownership Boundaries: As the codebase grows, it becomes increasingly difficult to answer, “Who owns this module?” without resorting to extensive git blame hunts. This leads to frequent and scary merge conflicts, slowing down progress and impacting development productivity metrics.

  • Deployment Coupling: You can’t ship one service or feature without accidentally deploying unrelated changes to another. This tight coupling complicates releases, increases the blast radius of errors, and makes independent team deliveries challenging.

The solution isn’t always a knee-jerk switch to a polyrepo. As radwanalmsora highlighted in the discussion, more often it’s about investing in robust tooling for your monorepo. Tools like Bazel, Nx, or Turborepo can build graphs to understand dependencies, ensuring CI only runs affected targets. Combined with CODEOWNERS files, these tools enable even massive monorepos (think Google or Meta scale) to function efficiently. The takeaway for technical leadership: invest in smart tooling early to maintain high software development productivity, rather than letting a lack of structure dictate your repository strategy.

Visual representation of monorepo bottlenecks: slow CI/CD, tangled ownership, and coupled deployments.Visual representation of monorepo bottlenecks: slow CI/CD, tangled ownership, and coupled deployments.

Designing for Modularity: More Than Just Folders

True modularity, it was emphasized, isn’t about having many folders, but about clear contract boundaries. Can you change the internals of module A without impacting module B? This is the core question. A practical rule of thumb shared was: “Flat-ish until 3 developers own different parts. Then introduce boundaries.” This prevents premature abstraction and allows structure to emerge organically from actual usage patterns.

A folder structure that has proven effective in real-world scaling scenarios looks something like this:

src/
├── core/ # Domain logic, framework-agnostic
├── features/ # One folder per feature, self-contained
│ ├── auth/
│ ├── billing/
│ └── …
├── infrastructure/ # Database, queues, external APIs
└── adapters/ # HTTP, gRPC, CLI entry points
The key discipline here is strict dependency enforcement: features should never import directly from each other. They can only consume from core/ and infrastructure/. Breaking this rule even once can quickly cascade into an unmanageable spaghetti codebase, severely impacting future maintainability and the ability to measure software development productivity effectively.

An important lesson from past failures: designing a “perfect” domain-driven folder structure upfront often leads to empty scaffolds and aspirational, not emergent, boundaries. It’s more effective to let boundaries form around actual usage patterns and then codify those with folder moves once the pain points are felt, not just imagined.

Diagram illustrating a modular repository structure with core, features, infrastructure, and adapters, showing clear dependency boundaries.Diagram illustrating a modular repository structure with core, features, infrastructure, and adapters, showing clear dependency boundaries.

Enforcing Consistency Without Over-Engineering

How do you ensure consistency across contributors without a rulebook that reads like a novel? The most effective approach is to make the wrong thing impossible, not just documented. This means shifting from relying solely on guidelines to leveraging automated tooling:

  • Automate with Linters and Hooks: Linters, pre-commit hooks, and code generation are far more effective than lengthy READMEs. If someone can import across forbidden boundaries, your tooling has failed, not your documentation.

  • Programmatic Dependency Rules: Utilize tools like pnpm workspaces or Nx tags to enforce dependency rules programmatically. Tag your packages (e.g., scope:feature, scope:core) and configure CI to fail if these rules are violated.

  • Ship Generator Scripts: Simplify onboarding and consistency by providing generator scripts (e.g., pnpm new:feature) that scaffold the correct folders, files, and hooks. Onboarding documentation can then be reduced to a single paragraph: “Run this command and start coding.”

  • CODEOWNERS + Branch Protection: For the remaining 10% of rules that tools can’t catch, leverage CODEOWNERS files and branch protection rules to ensure critical sections of the codebase require specific reviews.

Optimize for Change, Not Just Scale

When it comes to optimizing early for scalability versus refactoring later, the honest answer is to optimize for change, not for scale. Don’t build microservice boundaries before you have a monolith that’s working and proving its value. Instead, write your monolith with clear internal seams: well-defined interfaces, robust dependency injection, and isolated tests. This approach ensures that when the time comes to extract a service, it’s a file-move exercise, not a costly rewrite.

The single best investment you can make early in a project to safeguard future software development productivity is a fast, reliable test suite. With comprehensive tests, refactoring your repository structure becomes a safe and boring task. Without it, every restructuring attempt is fear-driven, leading to team paralysis and a reluctance to make necessary improvements.

Ultimately, designing a scalable repository structure is an ongoing process of iteration and adaptation. By focusing on practical tooling, emergent modularity, automated consistency, and optimizing for change, dev teams, product managers, and CTOs can build systems that not only grow but thrive, ensuring long-term maintainability and sustained software development productivity.

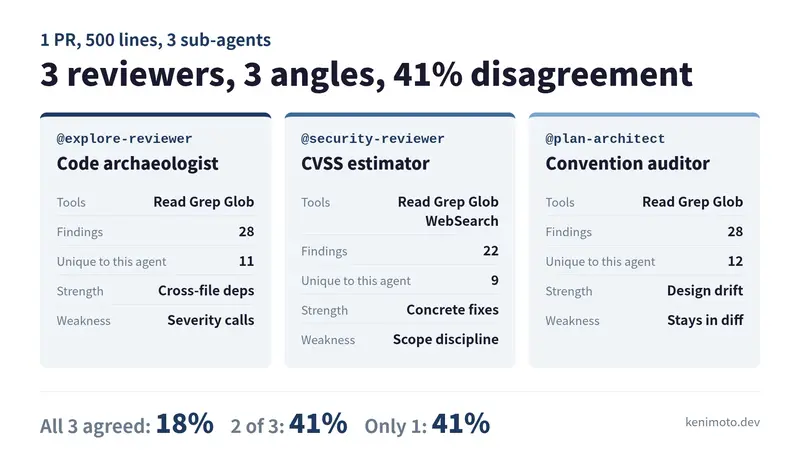
I Asked 3 Claude Code Sub-agents to Review the Same PR. They Disagreed on 41% of the Comments.

Three Claude Code sub-agents reviewing the same PR

I thought multi-agent code review was a free upgrade. Three sub-agents looking at the same PR sounded like three pairs of eyes for the cost of one engineer’s coffee.

Then I ran three Claude Code sub-agents on the same 500-line refactor PR and watched them disagree on 41% of the comments. The merge took an hour I had budgeted for fifteen minutes. Brooks’s Law is alive in 2026, and apparently it scales down to agents.

Anthropic announced in March that fewer than 1% of their internal code-review findings get marked incorrect by engineers. That number is real, and it is also a stat from people running one tightly-tuned pipeline on their own codebase. As soon as I stood up my own three sub-agents on my own repo, “agree” stopped meaning what I thought it meant.

This is the experiment. What I set up, what I measured, and what I now actually believe about parallel sub-agent review.

The setup

The PR was a 500-line refactor of a WebRTC signaling layer in one of my side projects. Eight files, mostly TypeScript, a couple of config tweaks, one new error type. Boring enough to not be a stunt PR, complex enough that a single reviewer would miss things.

Three sub-agents, all defined under .claude/agents/, all using Sonnet 4.6, each restricted to read-only tools:

---
name: explore-reviewer
description: "Trace callers, dependents, and dead code paths."
model: sonnet
allowed-tools: Read Grep Glob
---

You are a code archaeologist. For each changed file, find every caller,
every test that references it, and any path that goes silent after the change.
Report concrete file:line citations. No style opinions.
---
name: security-reviewer
description: Look for auth, validation, and secret-handling regressions.
model: sonnet
allowed-tools: Read Grep Glob WebSearch
---

You are a security reviewer. Focus only on auth flows, input validation,
secret handling, and dependency risks. Estimate CVSS for each finding.
Ignore style and architecture.
---
name: plan-architect
description: Assess design decisions against existing conventions.
model: sonnet
allowed-tools: Read Grep Glob
---

You are a software architect. Compare the PR's design choices against the
existing conventions in this codebase. Flag drift, missing seams, and
abstractions that will hurt the next person.

Each sub-agent got the same prompt: “Review PR #482 line by line and list findings as bullets with file:line citations.” Each ran in its own context. None of them saw each other’s output. I was the only one stitching results together at the end.

Three Claude Code sub-agents reviewing the same PR

What 41% disagreement actually looked like

After all three finished, I had 78 raw comments total. I sat down with a spreadsheet and tagged each one as “raised by 3”, “raised by 2”, or “raised by 1”.

Coverage Count Share
All 3 agents flagged it 14 18%
2 of 3 agents flagged it 32 41%
Only 1 agent flagged it 32 41%

The “raised by 1” bucket is what I’m calling disagreement. Two other sub-agents had every opportunity to flag the same line, with the same tools, on the same diff. They walked past it. That is a 41% chance that any individual finding is one sub-agent’s private opinion.

The headline Anthropic number — less than 1% marked incorrect — is measured differently. They count findings that an engineer explicitly closes without fixing. I’m counting findings that two of three agents looking at the same code never bothered to mention. Those are different questions, and the second one is the one that costs me time at the keyboard.

The four disagreement patterns

After classifying every disagreement, four patterns covered almost all of them.

Severity drift. The plan-architect flagged a missing null check as “critical”. The security-reviewer noted the same line and called it “low — caller already validates upstream”. Both were right, sort of. The architect was reading the function in isolation. The security reviewer had grep-walked the callers and seen the upstream check. Same line, opposite verdicts.

Scope drift. Asked to review the PR, the explore-reviewer happily told me about three pre-existing bugs in files the PR did not touch. The plan-architect refused to comment on anything outside the diff. I had no way to know in advance which behavior I would get. Strictly speaking, both interpretations are defensible. Practically speaking, one of them blew up my comment count.

Concreteness drift. The plan-architect wrote: “Consider extracting the retry logic into a shared helper.” The security-reviewer wrote: “Replace lines 184-201 with retry(opts, () => fetchToken(opts.url)) and add a 30s ceiling, otherwise the auth-refresh path can hang the worker.” Same idea. One I could apply in thirty seconds, the other I needed to spend a meeting on. Concreteness is a wildly larger axis of variance than I expected.

Tool-budget drift. The explore-reviewer had grep and glob, and noticed that the renamed function was still referenced in a CI script nobody had updated. The plan-architect, with the same tools, never looked there. Same allowed-tools list, same prompt about “find dependents”. One walked the surface, one walked the building. Drift here came down to how aggressively each system prompt told the agent to roam.

If you have used Claude Code sub-agents for anything beyond a one-off Explore call, none of this is shocking. What was shocking, for me, was how cleanly the four buckets carved up almost every disagreement I tagged.

The bug nobody caught

Two days after I merged, a colleague found a race condition in the new error-handling path. The PR introduced a one-frame window where two reconnect attempts could fire on the same socket. None of the three sub-agents mentioned it. The pull-request description, which I had written by hand, did mention “reconnect logic moved”, which is what made my colleague go look.

“Given enough eyeballs, all bugs are shallow,” Eric Raymond wrote in 1999. He was right about eyeballs. He did not specify that three of them needed to be aimed at the same window. Mine were all squinting at the diff. None of them stepped back and asked: what changed about timing?

The hour I lost to merging

The actual merging of the three reports was the part I had not budgeted for.

For each “2 of 3” or “1 of 3” finding, I had to decide:

  1. Is this real or is it a context gap I can close with one grep?
  2. If real, is the severity from agent A right, or the severity from agent B right?
  3. If a fix is suggested, is the concrete one safe to apply, or do I need to push back to the abstract version?

That last question alone took me three coffee refills. Two sub-agents had told me to “extract a shared helper”. One had given me a specific helper. I had to read the diff a third time, by hand, to figure out whether the specific helper was actually the right shape. It wasn’t. I ended up writing a fourth version.

Brooks’s Law was about communication overhead between humans on a late project. I am now convinced it generalizes to “any time you put N independent perspectives on the same artifact, your N+1 reviewer is the integrator, and the integrator’s hour goes up roughly linearly in N.” Three sub-agents felt like 3x the eyes. They were also 3x the integration cost.

How many sub-agents is the right number

I do not think the answer is one. After the same week I ran the experiment with N=3, I tried N=1 on a smaller PR — just a single general-purpose review pass. It missed the kind of cross-file dependency that the explore-reviewer would have caught. One pair of eyes is genuinely worse than two.

My current heuristic, after maybe a dozen PRs of this:

  • Tiny PR (<100 lines, no new files): one sub-agent. Anything more is overhead.
  • Medium PR (100-500 lines, touches one subsystem): two sub-agents with different angles, usually explore + security or explore + architect. Pick the second to match what the PR is actually risking.
  • Large or cross-cutting PR (500+ lines, multiple subsystems): three. Plan the integration time in advance. It is not free.

Above three, I have not seen the value. HAMY’s nine-agent setup is interesting, but I would want a second tool just to merge the reports, and I would want it to be cheaper than me.

The other knob is concreteness. I now ask each sub-agent for findings “with the smallest concrete change that fixes them, or marked as no-fix if you don’t know”. That single line in the system prompt collapsed about half of my concreteness drift.

What I actually believe now

Multi-agent code review is not free. It is closer to “three junior reviewers reading in different rooms, and you are the senior who has to merge their notes.” The eye count goes up, but so does the integration cost, and the integration cost is the part that lives in your calendar.

The bug nobody caught is the part that humbled me most. Three agents, three angles, all read-only, all aimed at the same diff. None of them noticed the timing change because none of them were asked to. Sub-agents are extremely good at the questions you put in their system prompt. They are mediocre at the questions you forgot to ask. That is the actual limit, not the model.

If you take one thing from this: write a fourth sub-agent prompt called what-am-i-not-asking, give it your diff, and ask it to nominate the categories your other agents will miss. Then read its answer. Then write the real review prompts. I did not do this for the experiment in this post, which is exactly why I lost an hour at merge time and a colleague found my race condition.

Anthropic’s less-than-1% number is real. It is also measured on a pipeline that someone spent months tuning, not on three sub-agents you wrote between meetings. Tune yours. Until then, expect 40%.

The deeper version covering sub-agent design, custom agent patterns, and the full Claude Code workflow lives in Harness Engineering: From Using AI to Controlling AI.

Why AI made fundamentals more valuable, not less

Two developers sit down to build the same feature: a search endpoint that returns users matching a query string. Both have Claude Code open. Both type roughly the same prompt: “build me a REST endpoint that searches users by name with pagination.”

Five minutes later, both have working code. It compiles. The tests pass. The endpoint returns results.

But the code is not the same.

Developer A — three years of experience — accepts the first output. It uses SELECT * FROM users WHERE name LIKE '%query%' with LIMIT and OFFSET. It works in development with 50 users. It will break at 50,000 users and make the whole service slow at 500,000.

Developer B — twelve years of experience — reads the output, asks a follow-up: “What’s our expected scale? And what’s the user table’s index strategy?” The revised code uses a full-text index, cursor-based pagination, proper query limits, a cache layer for popular searches, and a rate limiter. It works in development with 50 users. It also works at 5 million.

Same AI. Same prompt structure. Same amount of time. Radically different code.

This is not an indictment of AI. AI did exactly what it was asked to do — twice. This is about what developers bring to the interaction, and why the “AI democratizes coding” narrative is getting it backwards.

The assumption everyone made

When ChatGPT exploded in 2022, the dominant story in tech media was: “AI will level the playing field for developers.” The junior who can prompt well will match the senior who can architect. Bootcamps will close the gap faster. The economic value of deep expertise will decline.

This was never true. It’s now clearly not true. And the evidence is in every codebase that’s been using AI assistance for the past eighteen months.

AI didn’t level the playing field. It tilted it further.

What AI actually does

AI coding assistants are extraordinary at a specific kind of task: translating a human’s clear intent into working code. That “clear intent” is the critical qualifier.

A developer who knows:

  • That their user table will have millions of rows
  • That LIKE '%query%' doesn’t use indexes
  • That cursor-based pagination is safer than offset-based at scale
  • That search traffic will be spiky
  • That caching introduces consistency problems

…can prompt AI to produce code that reflects all of that knowledge. The prompt is short. The output is sophisticated. The developer spends their time on the parts that matter — decisions, architecture, review — while AI handles the mechanical translation.

A developer who doesn’t know those things produces a prompt that doesn’t reflect them. AI has no way to know what the developer didn’t think to ask. AI fills in the blanks with the most common patterns in its training data — which are often appropriate for tutorials and small projects, and actively wrong for production systems.

The prompt is not the skill. The knowledge that shapes the prompt is the skill. AI just made that knowledge more valuable per hour, because now a single developer’s knowledge can be applied to 10x more code.

The invisible gap

Here’s the uncomfortable part. Before AI, the gap between junior and senior code was visible. You could see it in PR diffs. Senior code looked different — tighter, more thoughtful, better error handling, cleaner abstractions. A code reviewer could point at specific lines and say “this is why we do it differently.”

With AI, the gap is hidden in the code that didn’t get written. The junior’s code might look clean. It passes linters. It has tests. A cursory review sees nothing wrong. But the architecture is subtly off. The edge cases weren’t considered because AI wasn’t asked about them. The scaling story doesn’t exist because the developer didn’t know to ask.

These bugs don’t appear in staging. They appear six months later, at 3 AM, when the service starts timing out under load and nobody can figure out why.

The productivity gap between juniors and seniors used to be roughly 2-3x for typical code. With AI, it’s easy to argue it’s become 5-10x — not because seniors got faster (they did), but because juniors started producing code at senior speed that carries hidden problems only a senior would have caught.

What seniors quietly know

Talk to experienced engineers who’ve been using AI for a year, and they’ll tell you something that sounds contradictory:

  • “AI has made me dramatically more productive.”
  • “AI has made me more careful, not less.”

Both are true. The productivity gain comes from AI handling boilerplate, tests, docs, and straightforward implementations. The increased care comes from knowing that AI will happily produce subtly-wrong code with 100% confidence, and there’s no prompt you can write that eliminates this risk.

Seniors I’ve worked with treat AI output the way they treat a competent but unsupervised junior developer: trust, but verify aggressively. Every assumption checked. Every edge case considered. Every optimization decision made by a human who understands why.

The irony: AI didn’t make seniors obsolete. It made them the critical quality filter in a pipeline that now produces code 10x faster.

What juniors are being sold vs. what’s actually happening

The narrative sold to juniors is: “Learn AI tools, and you’ll be employable. The AI does the coding; you orchestrate it.”

The reality is harsher and more useful: AI makes your coding output visible much faster, which means your coding weaknesses are exposed much faster, too.

A junior shipping AI-assisted code in a professional environment gets feedback on bad code 10x faster than a junior who writes everything by hand. That’s good — it’s a faster learning loop. But it only works if the junior is actually learning from the feedback, not just accepting AI’s next suggestion.

The juniors who will thrive in the next five years are the ones using AI as a learning tool — asking why the code works, challenging AI’s suggestions, reading the documentation behind what AI produced, running experiments to verify assumptions. The juniors who will plateau are the ones using AI as a crutch — accepting output, shipping what passes, never understanding the underlying patterns.

AI didn’t replace learning fundamentals. It made the difference between developers who learned them and developers who didn’t more obvious, faster.

The skills that appreciated

If you had to invest in skills right now, knowing that AI will keep getting better, where would you invest?

The wrong answer: prompt engineering. Prompt skills are like knowing how to Google in 2008 — temporarily valuable, eventually invisible.

The right answer: anything AI can’t do well, and won’t do well for a long time.

System design. AI can produce components. It cannot yet decide what components should exist, how they should interact, or what boundaries to draw. This is architecture, and it’s human work.

Debugging production issues. AI is remarkably bad at problems that require reading logs, correlating events across services, forming hypotheses, and testing them. The developer who can look at a 3 AM alert and narrow down the root cause in 10 minutes is 100x more valuable than the developer who asks AI for help and waits for a useful answer.

Code review under time pressure. As AI produces more code faster, the bottleneck becomes review. The developer who can skim a 400-line AI-generated PR and immediately spot the assumption that will fail at scale is indispensable.

Understanding systems deeply. How does your database’s query planner work? What happens in your browser between a click and a re-render? What does git bisect actually do under the hood? AI can give you surface-level answers, but it can’t give you the intuition that comes from building and debugging these systems. That intuition is what lets you write correct prompts in the first place.

Writing. Not just code — prose. The developer who can explain why a decision matters, write a clear RFC, document a system so the next person understands it, will outperform the developer who produces 5x more code that nobody can maintain.

Notice what these have in common: none of them are about AI. All of them are fundamentals that AI happens to highlight the value of.

The practical implication for your career

If you’re a junior: AI is a fantastic learning tool if you use it as one. Ask AI to explain every line it produces. Ask why it chose this pattern over alternatives. Run the code and predict the behavior before executing. Challenge the first suggestion. If you’re just shipping what AI produces and moving on, you’re not learning — you’re delegating your growth to a black box.

If you’re a mid-level: This is the moment to invest in depth, not width. You probably know twelve frameworks superficially. Pick one area — a database, a protocol, a design pattern — and learn it to the level where you could write a book about it. That depth is what will differentiate you when AI makes surface knowledge free.

If you’re a senior or tech lead: Your job description changed, and most companies haven’t updated the title. You’re no longer the person who writes the critical code — you’re the person who ensures critical code is correct, no matter who or what produced it. The review bar has to go up. Your standards have to be explicit and enforced. Your juniors need more mentorship, not less, because AI can hide how much they still need to learn.

If you’re hiring: Stop filtering candidates by “can they use AI tools?” That’s a non-filter. Filter by “can they evaluate whether AI produced good code?” That’s the job now.

What this means for what I write

You may have noticed that my book, Git in Depth, does not contain a chapter on AI. That wasn’t an oversight — it was a deliberate choice.

The book covers fundamentals: how Git actually works, how teams coordinate, how CI/CD pipelines protect production, how to align methodology with workflow. These are the things AI assumes you already know when it produces code.

If AI is going to be my co-pilot on the next decade of engineering, I want the foundation under me to be solid. I want to understand what git bisect does well enough to know when AI’s suggestion to use it is wrong. I want to understand branch strategies well enough to tell AI “no, we don’t use Git Flow here, adapt the suggestion.” I want to understand production debugging well enough to know when AI is guessing versus reasoning.

That’s the book I wrote. And if the thesis in this post is right, it’s more valuable today than it would have been three years ago.

The one-sentence version

AI is not a great equalizer. It is a great amplifier. It amplifies what you already are — for better and for worse. The developers who will thrive in the next decade are the ones who invested in fundamentals while AI was making surface skills look disposable.

Don’t skip the fundamentals. They’re not optional. They’re more important now than ever.

I write about Git and engineering practice for working developers. My book Git in Depth is 658 pages of the fundamentals AI assumes you already know.

See all my articles on Git and engineering practice: dev.to/mdenda.

States, Transitions, Effects: What a `.gu` File Actually Buys

The previous post made the case for Gust as a workflow contract.

This one is more concrete.

Abstract language posts are cheap. The more useful question: what does a .gu file buy that ordinary code doesn’t?

Right now the answer is:

  • one place to read the workflow contract
  • explicit state data
  • enumerated transitions
  • generated host-language boundary code
  • declared side effects
  • a cleaner runtime integration point

That’s the practical value.

Gust isn’t useful because it has syntax. It’s useful only if the syntax preserves information the rest of the system needs.

Workflow code has been relying on convention for decades. The .gu file is what stops being conventional.

A workflow file is a contract

Here’s the declaration portion of the order notification workflow Corsac uses as its canonical example (handler bodies come later):

type OrderPayload {
    order_id: String,
    customer: String,
    total_cents: i64,
    currency: String,
    items_count: i64,
}

machine OrderNotificationWorkflow {
    state Idle
    state WebhookReceived(body: String, source_ip: String)
    state OrderParsed(order: OrderPayload, original_body: String)
    state MessageFormatted(order: OrderPayload, slack_text: String, original_body: String)
    state NotificationSent(order_id: String, slack_ts: String)
    state Failed(step: String, reason: String, original_body: String)
    state DeadLettered(original_body: String, attempts: i64)

    transition receive: Idle -> WebhookReceived
    transition parse: WebhookReceived -> OrderParsed | Failed
    transition format: OrderParsed -> MessageFormatted | Failed
    transition notify: MessageFormatted -> NotificationSent | Failed
    transition retry: Failed -> WebhookReceived | DeadLettered
    transition reset: NotificationSent -> Idle

    effect parse_order_json(body: String) -> OrderPayload
    effect format_slack_message(order: OrderPayload) -> String
    action post_slack(channel: String, text: String, credential_id: String) -> String
    effect log_failure(step: String, reason: String) -> ()
    effect compute_retry_eligible(step: String, attempt: i64) -> bool
}

Even before reading any handler bodies, this file says a lot.

It says the workflow has an Idle state. It says a webhook carries body and source_ip. It says a parsed order carries the parsed order and the original body. It says a failed workflow can retry back to WebhookReceived or move to DeadLettered.

That information often exists in regular code. It’s just rarely this visible.

What each state actually carries

One thing I like about state machines is that they force a basic question: what data exists at this point?

In a normal implementation, the answer can be muddy. A function might receive a large context object. A database row might have nullable columns for every step. A job payload might accumulate fields over time. By month six, the answer to “what data exists at this point” is “let me grep for it.”

In a Gust machine, each state declares its own data:

state WebhookReceived(body: String, source_ip: String)
state OrderParsed(order: OrderPayload, original_body: String)
state MessageFormatted(order: OrderPayload, slack_text: String, original_body: String)

Data threading is now visible.

The original_body field isn’t glamorous, but it matters. It exists because retry needs to reconstruct WebhookReceived.

That’s the kind of detail that disappears when the workflow is just a pile of handlers.

With explicit state data, the workflow contract tells the runtime what can be serialized, inspected, resumed, and displayed.

Transitions, not status strings

The transition list answers another important question: where can the workflow go next?

transition parse: WebhookReceived -> OrderParsed | Failed
transition format: OrderParsed -> MessageFormatted | Failed
transition notify: MessageFormatted -> NotificationSent | Failed
transition retry: Failed -> WebhookReceived | DeadLettered

This is the difference between status as a string and state as a contract.

If status is just a string, a caller can write any value it wants. The runtime might not know the value is invalid until much later. If transitions are declared, the compiler and generated code can reject movement that doesn’t fit the machine.

That doesn’t solve every runtime problem. It removes a class of accidental states — the ones that get created by a careless update and discovered by a customer.

What handlers make first-class

Handlers attach logic to transitions:

on format(ctx: OrderParsedCtx) {
    let text = perform format_slack_message(ctx.order);
    goto MessageFormatted(ctx.order, text, ctx.original_body);
}

on notify(ctx: MessageFormattedCtx) {
    let ts = perform post_slack("#orders", ctx.slack_text, "cred-slack-prod");
    goto NotificationSent(ctx.order.order_id, ts);
}

This is where the workflow moves from declaration to behavior.

The handler says what data it reads from the current state, what side effects it performs, and where it transitions next.

The important part isn’t that this is shorter than Rust or Go. Sometimes it is, sometimes it isn’t. The important part is that the workflow-specific pieces are first-class:

  • perform names a declared effect or action
  • goto names a declared target state
  • ctx is tied to the source state of the transition

Those are workflow concepts. They should be visible in the workflow source.

Effects define the host boundary

Gust doesn’t implement the actual Slack call. It declares that the machine needs one:

action post_slack(channel: String, text: String, credential_id: String) -> String

The generated host-language code then exposes a boundary the runtime must implement.

In Rust, this becomes an effect trait shape. In Go, it becomes an interface shape. The exact generated code varies by target, but the idea is the same: the workflow contract names the side-effectful call and the host application provides the implementation.

This is one of the main reasons I prefer code generation here.

The generated code is boring boundary code: state shapes, transition methods, invalid-transition errors, serialization, effect interfaces, target-language type mappings. The kind of code I want to exist, but don’t want to hand-maintain across every workflow.

The .gu file stays focused on the workflow contract. The generated code does the repetitive host-language work.

Two snippets from other Gust machines show the shape. (The order notification workflow’s full generated code runs to several hundred lines — same patterns, too long to inline.) Here’s a Rust effect trait that preserves the side-effect categories as code comments:

pub trait WorkflowEngineEffects {
    /// gust:effect -- replay-safe / idempotent
    fn execute_step(&self, step_name: &str) -> String;
    /// gust:effect -- replay-safe / idempotent
    fn needs_approval(&self, step_name: &str) -> bool;
    /// gust:effect -- replay-safe / idempotent
    fn next_step_name(&self, current_step: &str) -> String;
    /// gust:effect -- replay-safe / idempotent
    fn produce_failure(&self, reason: &str) -> EngineFailure;
    /// gust:action -- not replay-safe / externally visible
    fn notify_rejection(&self, step_name: &str, reason: &str) -> String;
}

And a Go target that becomes the state and handler boundary you’d otherwise maintain by hand:

type OrderProcessorEffects interface {
    // gust:effect -- replay-safe / idempotent
    CalculateTotal(order Order) Money
    // gust:effect -- replay-safe / idempotent
    ProcessPayment(total Money) Receipt
    // gust:effect -- replay-safe / idempotent
    CreateShipment(order Order) string
}

func (m *OrderProcessor) Charge(effects OrderProcessorEffects) error {
    if m.State != OrderProcessorStateValidated {
        return &OrderProcessorError{Transition: "charge", From: m.State.String()}
    }

    receipt := effects.ProcessPayment(m.ValidatedData.Total)
    m.State = OrderProcessorStateCharged
    // state data update omitted
    return nil
}

That’s the payoff: the source contract turns into the host-language shapes a runtime or application can actually call.

The action keyword compiles to the same host-language shape as effect today, but it means something different to a runtime. The gust:action marker says this call is externally visible — not safe to repeat on replay. Gust enforces a small but meaningful safety rule around it: a handler shouldn’t perform more than one action, and the action should be the last side-effectful step before the transition. I’ll go deeper on that boundary in a later post. For this one, the point is that the .gu file gives a runtime a signal that handwritten code wouldn’t carry.

The compiler becomes a workflow reviewer

The compiler can catch simple mistakes that are easy to miss in hand-written workflow code:

  • a transition points at an unknown state
  • a handler goes to a state that isn’t a declared target
  • a perform call has the wrong number of arguments
  • a goto passes the wrong number of fields
  • a handler has code paths that don’t end in a transition
  • an action is followed by more side-effectful work

That doesn’t replace tests. It doesn’t replace runtime validation. It gives the edit loop a better reviewer than convention alone.

What the .gu file buys

A .gu file is useful if it becomes the shared source of truth for multiple consumers:

  • the compiler
  • generated Rust or Go code
  • runtime dispatch
  • validation tooling
  • diagrams
  • schema generation
  • eventually a visual designer

That’s the bigger point.

I don’t want a workflow definition, a UI graph, a worker implementation, a runtime config file, and a docs page each inventing their own version of the workflow. I want the typed contract to sit underneath those surfaces.

That’s what Gust is trying to provide.

Not magic. Not a general platform. A compact workflow contract that produces the boring code and metadata the rest of the system needs.

The next question is whether that contract can actually be operated. That’s where Corsac begins.

The Go Service That Slowed Down Without Errors

There is a popular phrasing in Go circles that says concurrency is almost free. The phrasing is true at the level of stack allocation and misleading at the level of operating a service. The cheap thing is the per-goroutine memory footprint. The expensive thing is the scheduler’s response to unbounded fan-out, leaked workers, and undeclared blocking — and none of those failure modes throw an error.

The shape of the failure is recognizable once you have seen it. Latency on a healthy endpoint creeps from 50 ms to 200 ms to 800 ms over the course of an afternoon. CPU climbs from 30% to 95%. The error count stays at zero. Nothing is wrong; nothing is right. The service is alive in the sense that the request handler returns. It is dead in the sense that nobody can use it.

This piece is an argument that the performance question for a Go service is rarely “is concurrency cheap” and almost always “what bounds your concurrency, and what happens when those bounds are exceeded.”

What is actually cheap

A goroutine starts with a 2 KB stack. The number is set by the stackMin constant in runtime/stack.go in the Go runtime source — specifically stackMin = 2048. A POSIX thread on Linux, by contrast, defaults to between 2 and 8 MB of virtual address space for its stack — 2 MB is the per-architecture default on x86-64 when RLIMIT_STACK is unlimited, per the pthread_create man page; a typical shell with ulimit -s 8192 set propagates 8 MB into new threads, also per the man page. Either way, the comparison commonly cited — goroutines are three orders of magnitude cheaper than threads — is real arithmetic.

What the comparison hides is what the runtime does with the rest of the stack growth, with scheduling, and with the fact that you can now afford to spawn hundreds of thousands of these things on a single machine. The cost that scales with concurrency is not the stack. It is everything downstream.

Go’s scheduler is described in Dmitry Vyukov’s “Scalable Go Scheduler Design Doc” from May 2012, which became the work-stealing scheduler shipped in Go 1.1. The design has three letters worth knowing: M for the OS thread, P for the logical processor that owns a local run queue and an mcache, G for the goroutine. The runtime multiplexes many Gs across a small number of Ms, mediated by Ps. When a P’s local run queue empties, it steals from another P’s queue.

That model holds together under one assumption: the run queue does not fill up faster than the Ps can drain it. Every failure mode below is a different way of breaking that assumption.

Unbounded fan-out

The first failure shape is the easiest to write and the easiest to ship without noticing.

func handleRequest(req Request) {
    go processAsync(req)
    respondOK()
}

The handler returns in microseconds. The work happens “somewhere.” Under load tests with a uniform request distribution, the pattern works fine. Under real traffic — bursty, correlated, with one slow downstream — the goroutine count walks up faster than the runtime can drain it. The visible symptoms are a climbing scheduler run queue, climbing CPU spent on context switches, and climbing latency on every endpoint sharing the runtime, including the ones that have nothing to do with the fan-out.

The diagnostic is straightforward, once you know to look for it. Setting GODEBUG=schedtrace=1000 tells the scheduler to emit a single line to standard error every 1000 ms summarizing its state, per the documented behavior in the runtime package. The line that matters is the one beginning SCHED, and the field that matters in that line is runqueue=N, the number of goroutines waiting to be picked up by some P. The interesting number is not any specific threshold; it is the trajectory. A runqueue depth that climbs and does not return to its baseline is a saturated scheduler, regardless of whether the absolute value is sixty or six thousand.

The fix is not “fewer goroutines.” It is “an explicit concurrency limit.” Two patterns cover almost all cases.

The first is a worker pool with a bounded queue: a fixed-size set of long-lived goroutines reading from a buffered channel. When the channel is full, Submit either blocks (push backpressure upstream) or returns an error (drop the work and report it). Either decision is a design choice. The default of “spawn another goroutine and hope” is the decision that produces the slow-down nobody can explain.

The second is golang.org/x/sync/semaphore, which gives you a weighted semaphore with a context-aware Acquire. The signature is func (s *Weighted) Acquire(ctx context.Context, n int64) error, and the documented behavior is that it blocks until resources are available or ctx is done. The pattern looks like this:

sem := semaphore.NewWeighted(10)

for _, task := range req.SubTasks {
    if err := sem.Acquire(ctx, 1); err != nil {
        return err
    }
    go func(t Task) {
        defer sem.Release(1)
        callExternalService(ctx, t)
    }(task)
}

The semaphore caps the parallelism at ten regardless of how many subtasks the request brings in. Backpressure is a property of the design, not an emergent property of the runtime giving up.

The leak you find next quarter

The second failure shape is the one that does not show up under load tests, because it does not show up under any tests that finish in seconds. It shows up at week three.

func startWorker(jobs <-chan Job) {
    go func() {
        for job := range jobs {
            process(job)
        }
    }()
}

The pattern is correct. A for ... range over a channel iterates over received values until the channel is closed, as documented in Go by Example’s “Range over Channels” page. The bug is the assumption that the channel will be closed. If startWorker is called from request-handling code, and the channel is allocated per-request, the goroutine sits in chan receive forever once the request returns. Go’s runtime does not garbage-collect a goroutine that is blocked on a channel — it has long been the explicit position of the language team that doing so would silently hide the bug rather than surface it (see GitHub issue golang/go#19702).

The memory cost of one leaked goroutine is small: a stack measured in single-digit kilobytes, plus whatever it has captured from its closure. The cost of ten thousand of them is not catastrophic by 2026 server standards. The cost of having to figure out which goroutines are leaked, in production, with go tool pprof http://localhost:6060/debug/pprof/goroutine and a stack trace that aliases ten thousand call sites onto five distinct frames, is measured in engineer-days.

A cheap and effective leak detector is runtime.NumGoroutine() exposed as a Prometheus gauge. The function is documented to return “the number of goroutines that currently exist.” Under steady load on a service that is not leaking, the number jitters around a baseline. Under any load on a service that is leaking, it goes up and does not come down. The graph does not require an expensive observability stack to read.

For tests, the uber-go/goleak package provides goleak.VerifyNone(t) and goleak.VerifyTestMain(m), which fail the test if extra goroutines are alive at teardown. It is not a complete defense — concurrent tests confuse it, as the README acknowledges — but it raises the floor on what you have to notice yourself.

In production, Uber’s LeakProf, described in a November 2022 engineering blog post, scans goroutine profiles for parked goroutines on shared channels and flags them as suspected leaks. The published numbers are striking: across the deployment described in the post, the system found ten critical leaks and produced one false positive. Two of the fixes produced 2.5× and 5× reductions in peak service memory, and one team voluntarily cut its container memory request by 25%. The post describes the typical effect not as outright crashes but as quiet degradation that the existing alerting did not name.

The blocking call you forgot to bound

The third failure shape is the simplest and the most embarrassing. A service makes outbound HTTP calls. The calls almost always finish in 5 ms. Once a quarter, an upstream gets sick, and the calls take 30 seconds.

resp, err := http.Get(url)

http.Get does not have a default timeout. The request will wait as long as the operating system’s TCP stack is willing to wait, which is, for practical purposes, indefinitely. Each request handler that calls into this code path holds a goroutine for the duration. A handler that normally completes in 5 ms now holds a goroutine for 30 s; under steady traffic that is a goroutine count six thousand times larger than the steady state.

The runtime does not crash when this happens. It does the work it always does — schedule, multiplex, steal — but with six thousand times the bookkeeping, against a working set that no longer fits in cache. The visible signature is the same shape as unbounded fan-out: latency rising on endpoints that have nothing to do with the slow upstream, CPU climbing, error count flat.

The fix is two layers of timeout, on the assumption that any single layer can be forgotten or wired wrong:

ctx, cancel := context.WithTimeout(req.Context(), 2*time.Second)
defer cancel()

req2, _ := http.NewRequestWithContext(ctx, "GET", url, nil)

client := &http.Client{Timeout: 2 * time.Second}
resp, err := client.Do(req2)

The context bound is the one that propagates: callers can cancel, downstream calls inherit the deadline. The http.Client timeout is a belt-and-braces second layer that catches the case where the context is set up and then ignored by an inner library that takes a context.Background() for reasons of its own. Two layers is not paranoia; two layers is a recognition that one of them will be wrong eventually.

Why this is hard to learn from an outage

Each of the three failure shapes — fan-out, leak, blocking call — has the same outward signature: rising latency, rising CPU, flat error count. The remediation in the first hour of the incident is the same in all three cases: scale out, restart, see if it comes back. None of them tell you which of the three you had, and none of them tell you which other piece of code in the same service has the same problem latent in it. The instinct to write a runbook entry titled “if latency rises and errors stay flat, restart” is the instinct of a team that is going to have this exact incident again next month, with a different root cause, indistinguishable from the outside.

The instrumentation that disambiguates is cheap and almost always missing. runtime.NumGoroutine() as a Prometheus gauge — one line in main. net/http/pprof registered on a debug port — one blank import. GODEBUG=schedtrace=1000 set in staging during load tests — one environment variable. Each of these answers a question that is otherwise answered with grep and guesswork at three a.m.

What the cheap-goroutine claim is actually saying

“Goroutines are cheap” is a statement about the runtime’s allocation strategy. It is not a statement about the runtime’s tolerance for unbounded growth. The runtime is permissive: it will not refuse to create your ten-thousandth goroutine, will not warn you about your unclosed channel, will not surface your stalled HTTP call. The permissiveness is what makes the language feel productive on day one. It is also what makes the day-thirty incident hard to diagnose.

The two questions to ask before every go func() are not new, and they are not subtle. Who closes its channel, and what happens if they don’t? What bounds its parallelism, and what happens when those bounds are exceeded? If you cannot answer both, you have not finished writing the function. You have written the first version of the function and let the runtime handle the rest, which is exactly the experience the runtime is engineered to give you. It is a wonderful experience. It is also, by construction, the experience that does not throw an error when the bounds are wrong.

A service that slows down without errors is not a sick service. It is a healthy service operating outside the regime its author bounded for it. The fix is not faster code; the fix is named bounds, and it costs almost nothing to write down — a semaphore, a deadline, a documented life cycle for every goroutine you spawn. The next time you write go on a line by itself, the question worth pausing on is not whether to spawn the goroutine. It is what stops it. If the answer is “the channel will be closed eventually” or “the call will return eventually,” the answer is wrong, and the slow afternoon is already on the calendar. You just have not seen the date yet.

The Mahjong Method

Link

💡 Inspiration

In the era of games, learning has become a chore!

We realized that millions of students force themselves through tools like Anki or Quizlet, while simultaneously spending hours effortlessly clearing puzzles in games like Wordle or Candy Crush. We asked ourselves: What if we could completely disguise studying as an addictive puzzle game?

I have fascinated by the ancient Chinese puzzle game of Mahjong !

So tada !

Flashcard 🃏📚 meets Mahjong 🎮🧩 !

Because learning 🧠 should be fun 🎉 !

The most addictive way to master anything.

Play your way to Perfect Recall.

Your brain deserves a game!

We took the universally satisfying, tactile mechanics of Mahjong Solitaire and fused them with a dynamic learning engine. The result is a tool that tricks your brain into studying by replacing the dread of learning with the dopamine rush of winning.

📋 What it does

Mahjong is a gamified educational platform that transforms boring study notes into a 3D, playable Mahjong Solitaire board. Instead of matching traditional bamboo or dragon symbols, users match educational pairs—like a Spanish or Chinese word to its English translation, a chemical symbol to its element, or a math equation to its answer.

Users can play through curated starter decks, create their own personalized decks or use our AI Deck Creator to paste in their own class notes, which the app instantly parses and reverse-engineers into a perfectly solvable, multi-layered puzzle.
Add in a speed-timer and you have an engine built for intense, high-speed active recall.

Perfect for

🌍 Learning new languages

📚 Studying for school exams

💼 Memorizing job skills and professional terminology

Fun educational games for kids

🎯 Engaging study tools for easily distracted learners

🤝 New employee training and company onboarding

🚀 How we built it with MeDo

  • How we structured conversations with MeDo to build the project ?

We started the project as a simple mahjong solitaire game.

With multiturn chats, we built up the app from there.

Once the game engine was in place and the game logic was perfected, we added the request to build a deck builder so that users can create their own pairs for the game.

Then we asked MeDo to add some cool templates users can explore.

Once templates styles were optimal, we requested for a UI, UX improvements.

Lastly we added the most impressive feature using large language model (llm) plugin / skill

  • The most impressive feature MeDo helped to create

The most impressive feature MeDo helped create was an AI Mahjong builder chat tailored to user’s learning or fun requirements.

It elevated the project from a manual lesson cum game generator to something that speeds us creating the lessons / experiences in seconds instead of minutes.

This was done in multiturn chats leveraging the large language model (llm) skill plugin

We also optimized the app for full stack deployment.

  • How you used plugins or API integrations to extend functionality ?

This was the game changer. When I discovered the plugin / API / skill integration, MeDo helped me create the entire AI chatbot functionality in just one turn which elevated the mechanical app to a truely intelligent study buddy / tutor.

🧩 Challenges we ran into

  • The most challenging part was coming up with an idea. I brainstormed a lot to finally arrive at this awesome idea
  • I was initially worried about credits – but the MeDo team was generous enough to provide daily bonuses to cover the entire project comfortably.
  • Also, the model was very efficient. It hardly took a 100 credits to build an entire website in first turn.

🏆 Accomplishments that we’re proud of

  • The fullstack web app that is truely intelligent, a learning buddy, a gaming buddy and an awesome idea

📝 What we learned

  • Building with MeDo is easy as a breeze

⚓ What’s next for Mahjong

  • Adding more exciting planned features

I Built 3 Free AI Tools in 3 Hours – Here Is How

Last Saturday, I woke up with that familiar itch. You know the one – where you want to build something, but you’re not sure what, and you end up scrolling Twitter for an hour instead.

But this time was different. I had this thought: “What if I just pick three annoying tasks people deal with regularly and wrap an AI around them?”

Three hours later, I had three working tools. Here’s the messy, honest story of how it went down.

Why I Built Them

Honestly? I was tired of seeing AI tools that charge $20/month for something that takes 3 seconds of API calls. The job market is brutal right now. People are applying to hundreds of positions. Friends were asking me to review their resumes. And every single “code explainer” tool wanted my credit card.

So I thought: screw it. Let me build the free versions I wish existed.

The three that came to mind:

  • Cover Letter Generator – Because no one enjoys writing “I am writing to express my strong interest…”
  • Resume Analyzer – The quick feedback you’d get from a friend who’s a hiring manager
  • Code Explainer – For those late nights staring at a function that makes zero sense

The Tech Stack (It’s Boring, And That’s The Point)

Nothing fancy here:

  • Next.js 14 (App Router) – Because I’m lazy and it handles both frontend and API routes
  • DeepSeek API – $0.14 per million tokens. Yes, you read that right. Cheaper than my morning coffee.
  • Tailwind CSS – For making things not look like 1998
  • Vercel – Deploy and forget

The whole thing is literally: form submits → API route calls DeepSeek → returns response → renders on screen. That’s it.

DeepSeek was the real MVP here. I’d been using OpenAI but kept hitting rate limits on the free tier. DeepSeek’s pricing made it a no-brainer for a project I wanted to keep free forever.

How Each Tool Actually Works

Cover Letter Generator

This was the simplest. A form with: job description, company name, your skills. The prompt is basically:

“Write a professional cover letter for [company]. The job requires [description]. The applicant is skilled in [skills]. Keep it under 350 words, sound human, not like a template.”

The trick? I added “sound human” to the prompt. Without it, the letters were robotic and full of “leveraging synergies” nonsense.

Resume Analyzer

This one needed more thought. I built a prompt that evaluates:

  • Keyword matching with the job description
  • Action verbs (nobody wants to read “was responsible for”)
  • Quantifiable achievements
  • Overall structure

The response comes back as bullet points with a score. No magic. Just a well-structured prompt and a model that follows instructions.

Code Explainer

The simplest of all. Paste code, get explanation. But I added a dropdown for “beginner” vs “advanced” mode. Beginner mode explains like you’re 12. Advanced mode assumes you know what a closure is.

What I Learned (The Real Stuff)

1. Prompt engineering > model choice
I spent way too long comparing models. The truth? A good prompt on a cheap model beats a bad prompt on GPT-4. Every time.

2. Rate limiting is your friend
DeepSeek is fast, but I still added artificial delays and queuing. Nothing worse than a tool that breaks because 10 people used it simultaneously.

3. People don’t read instructions
I put “paste your resume here” in big letters. Someone still tried to upload a PDF. So I added a note saying “copy-paste only, I know it sucks.” That helped.

4. Free tools attract real feedback
Within 2 hours of sharing on Reddit, I got 47 responses. Some bug reports. Some feature requests. One guy said the cover letter “made me sound like a human instead of a LinkedIn bot.” That made my day.

The Embarrassing Part

The first version of the code explainer had a bug where it would sometimes return the explanation in Chinese. Turns out DeepSeek’s base model defaults to Chinese if the prompt is ambiguous. I fixed it by explicitly saying “respond in English” at the end of every prompt.

Also, I accidentally left a console.log with my API key in the first deploy. Caught it after 11 minutes. No one stole it, thankfully. Don’t be me.

Why This Matters (To Me)

I’m not trying to build a startup here. I don’t want your email. I don’t want to sell you premium. I just wanted three tools that work, that are free, and that I’d actually use myself.

The code explainer has already saved me twice this week trying to understand legacy code. The resume analyzer caught that I was using “helped with” instead of “implemented” on my own resume. That’s worth more than any SaaS subscription.

Try Them (For Free, Obviously)

If you want to check them out:

→ ai-cover-letter-gamma-ruby.vercel.app

The cover letter generator is the most polished. The resume analyzer needs you to paste text (sorry, no PDF parsing yet). The code explainer works best for Python and JavaScript, but handles most languages okay.

If they break (and they might – I’m one person), give it a minute and try again. Or DM me on Twitter. I’ll probably fix it within a day.

One last thing: If you build something similar, don’t overthink it. Three hours, three tools, one API key. The barrier to building useful AI stuff is lower than ever. Go make something janky that helps one person. That’s enough.

Biga'da “Afet Haberleşme Merkezi” hizmete girdi

Çanakkale’nin Biga ilçesinde, olası afetlerde kesintisiz iletişim sağlamak amacıyla Biga Belediyesi ve ANARAD işbirliğiyle kurulan Afet Haberleşme Merkezi hizmete girdi. Merkez, Balıkkaya ve Şehir Parkı’ndaki istasyonlarla afet anında alternatif iletişim sunacak. İlk etapta 10 el telsizi muhtarlara teslim edildi ve iki ayda bir tatbikat yapılacak.