Albüm: 2026 Çin İnternet Medeniyeti Konferansı Çin'in Nanning Kentinde Gerçekleştirildi
2026 Çin İnternet Medeniyeti Konferansı, salı günü Çin’in güneyindeki Guangxi Zhuang Özerk Bölgesi’nin merkezi Nanning’de gerçekleştirildi.

 Mert
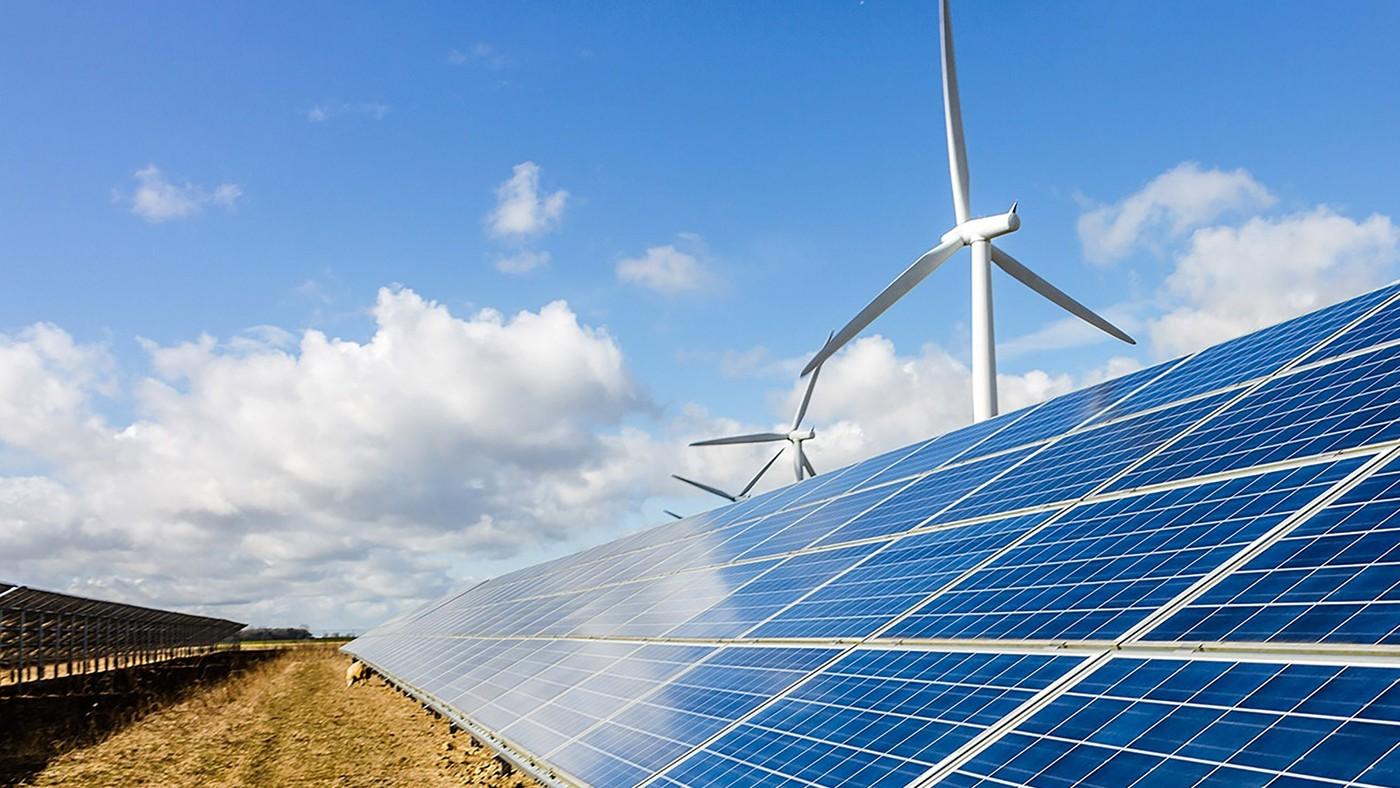
 Türkiye’de güneş ve rüzgar enerjisinden üretilen elektrik, Nisan 2026’da ilk kez kömür santrallerini geçti. Yenilenebilir enerjinin toplam üretimdeki payı yüzde 71’e ulaştı.
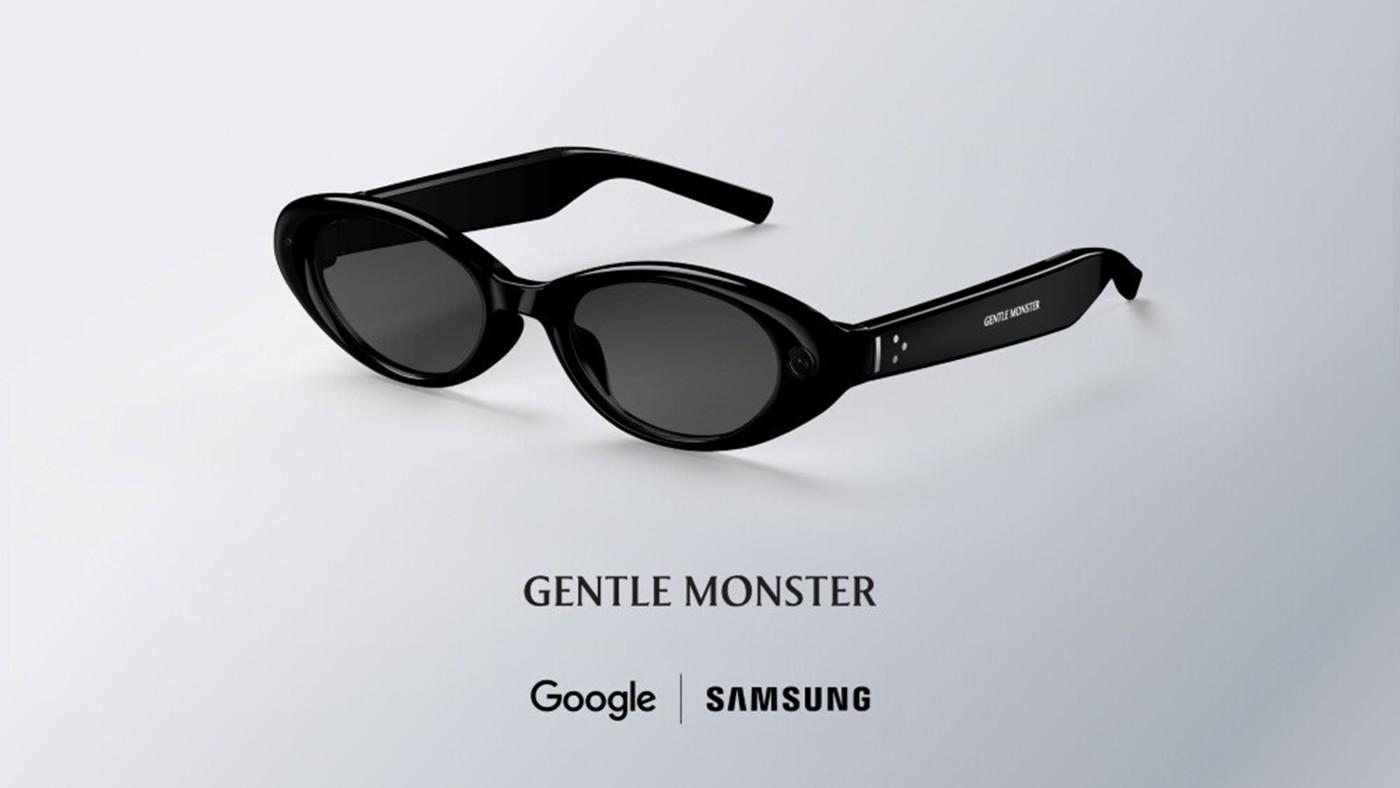
 Samsung ve Google, Gemini destekli yeni akıllı gözlüklerini ilk kez gösterdi. Yeni model, canlı çeviri, navigasyon ve sesli yapay zekâ özellikleriyle geliyor. İşte detaylar…
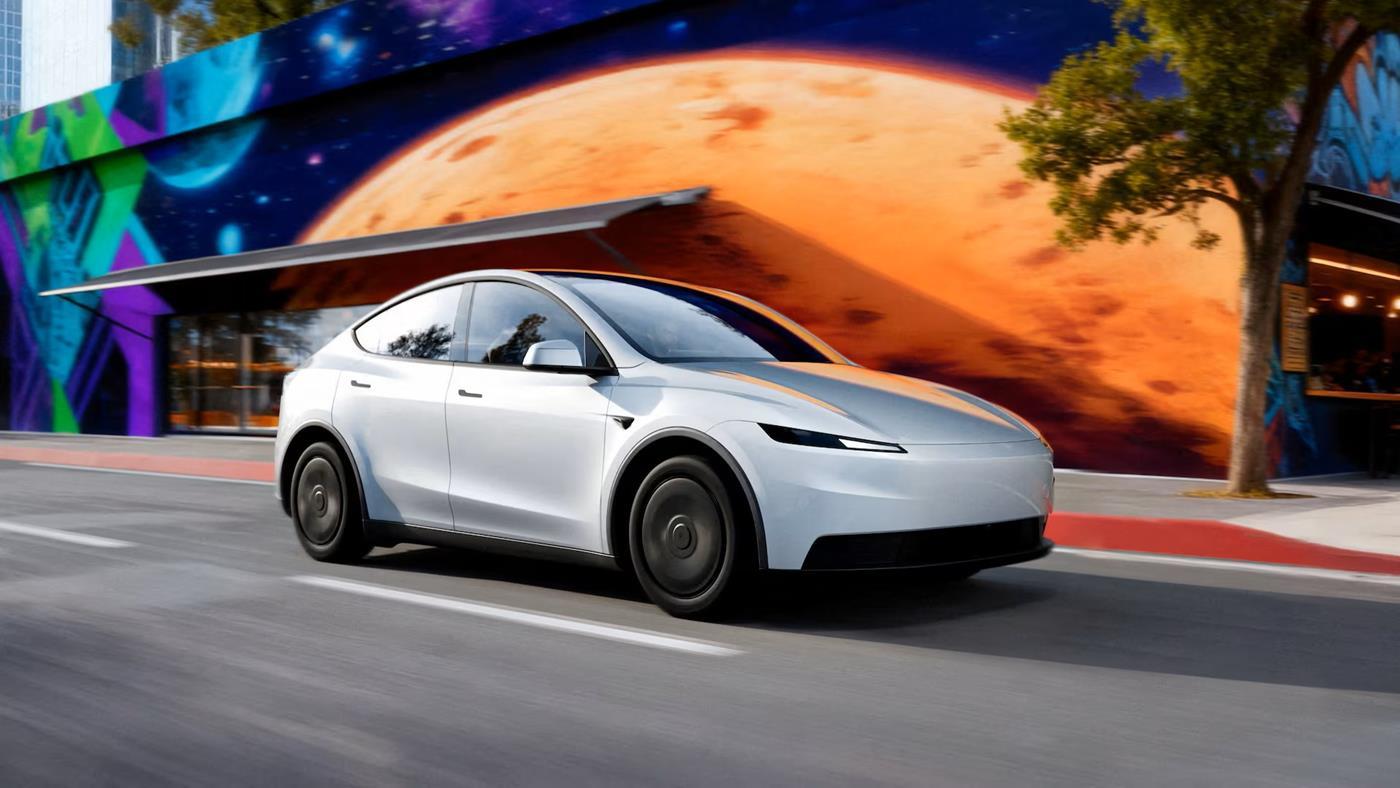
 Tesla’nın Full Self-Driving (FSD) sürüş sistemi Litvanya’da resmen kullanıma sunuldu. Ülke, Hollanda’nın ardından Avrupa’da FSD’yi onaylayan ikinci devlet oldu.

The problem nobody talks about
You have a payment gateway. It fails sometimes. So you add a retry.
Now you have a worse problem: a customer clicks “Pay”, the request reaches Stripe, the charge goes through, but the response never comes back. Your retry fires. Stripe charges them again.
That’s not a hypothetical. It’s the default behavior of any naive retry implementation, and it happens in production every day.
This post is about how we built a checkout system that handles this correctly — with retry that never double-charges, a circuit breaker that protects the service when the gateway is degraded, and a feedback loop that adjusts its own configuration under load.
Then we stress-tested it with k6 and measured everything.
The code is in the backendkit-monorepo shopify-backend example
(https://github.com/BackendKit-labs/backendkit-monorepo/tree/master/examples/shopify-backend).
The architecture
The order flow is a typed pipeline of four steps:
POST /orders
→ ValidateInventoryStep checks stock, reserves units
→ CalculatePricingStep applies discounts, computes total
→ ChargePaymentStep calls payment gateway with retry + idempotency
→ CreateOrderStep persists order, emits events
Each step receives a typed OrderContext, returns Result, and the pipeline stops at the first failure. No exceptions, no try/catch chains — errors are values.
The payment step is where the interesting work happens:

Three things to notice:
The idempotency.key is charge:${ctx.orderId} — unique per order, not per request. If the first attempt charges successfully but the response is lost, the retry hits the idempotency cache and returns the stored result. Stripe is never called again.
retryIf only retries on 500/503 — not on 400/422/404. Business errors don’t retry.
3. jitter: ‘full’ randomizes the backoff delay to prevent thundering herd when multiple orders fail simultaneously.
Test 1: The baseline — normal traffic
Script: order-flow.k6.js — ramps to 50 VUs over 2 minutes, full pipeline per iteration.
✓ success rate: 96.58%
✓ p95 latency: 2.03s
avg latency: 1.17s
throughput: 13.5 orders/second
fail rate: 3.42% (simulated gateway noise)
Under 50 concurrent users, the full pipeline — inventory check, pricing, payment, order creation — completes in 1.17 seconds on average. The 3.42% failure rate is the configured background noise of the payment simulator, not application errors.
This is the baseline. Every number that follows is measured against this.
Test 2: What happens when the gateway degrades
Script: circuit-breaker.k6.js — sets PAYMENT_FAILURE_RATE=0.8, ramps to 30 VUs.
Without a circuit breaker, 80% failure rate means 80% of requests wait for the full gateway timeout before failing.
With 30 VUs × 1-2 second timeout = threads exhaust,
queue backs up, the entire service starts degrading — not just payments.
With a circuit breaker:
health endpoint: 100% reachable throughout
avg response time: 5.05ms
fast-fail response: ~5ms (vs 1.17s baseline)
http_req_failed: 49.99%
The 49.99% failure rate splits exactly in half: health check requests (all succeed) and payment requests (circuit open, fast-fail).
When the breaker trips, payment failures come back in 5 milliseconds instead of waiting 1-2 seconds for a gateway that’s known to be down.
The service never stopped responding. Health endpoints stayed at 100% throughout. The circuit breaker isolated the payment failure from the rest of the system.
Test 3: Retry + idempotency under 60% failure rate
Script: retry-idempotency.k6.js — three concurrent scenarios, 60% gateway failure rate.
This is the scenario that matters most for e-commerce. A gateway failing 60% of the time is a degraded but not dead dependency — exactly when retry is most valuable and most dangerous.
[retry_resilience] success rate: 78.2%
[retry_resilience] retried requests: 825 with latency >500ms
[idempotency_replay] replay rate: 100.0%
[lifecycle] correct cycles: 4/4
p95 latency (with retries): 1345ms
The math checks out. With 60% failure per attempt and 3 max attempts, probability of all three failing = 0.6³ = 21.6%. Actual failure rate: 21.8%. The retry is working exactly as the probability model predicts.
Those 825 requests with latency >500ms are orders that failed on the first attempt but succeeded on retry. Without retry, they’re lost sales. With retry, they’re completed transactions — and none of them charged the customer twice.
Idempotency replay: 100%. Every duplicate request — simulating the “response lost in transit” scenario — returned the cached result without executing the payment handler. The 100% rate held across both this test and the dedicated idempotency test run independently.
Lifecycle test: 4/4. This validates the subtle but critical behavior:
A naive idempotency implementation that caches failures would block legitimate retries. This one doesn’t.
Test 4: The idempotency contract
Script: idempotency.k6.js — four parallel scenarios, 1383 total iterations.
replay success rate: 100%
missing Idempotency-Key → 422: 30/30
invalid key format → 422: 30/30
overall fail rate: 3.3% (same as baseline)
p95 latency: 1322ms
The contract is enforced at the boundary. A client that forgets to send an Idempotency-Key header gets a 422 — not a silent pass-through that bypasses the protection. Invalid key formats are rejected before touching any business logic.
The 3.3% overall failure rate is statistically identical to the baseline 3.42%. The idempotency layer adds zero latency and zero failures to the normal flow.
Test 5: The system that tunes itself
Script: auto-learning.k6.js — three phases over 160 seconds.
This is the part that has no equivalent in the NestJS ecosystem.
Phase 1 — Baseline (t=0s): 5 VUs, 5% failure, 100ms delay
Phase 2 — Stress (t=50s): 25 VUs, 85% failure, 1000ms delay
Phase 3 — Recovery (t=110s): 5 VUs, 2% failure, 80ms delay
The auto-learning module observes every request, runs z-score analysis on latency and error distributions, and adjusts configuration on a 30-second feedback cycle.
Here’s what the logs showed:
t=0s Initial config:
timeoutMs=2804ms maxRetries=2 cbFailureThreshold=10
[t=50s to t=100s — stress is running, system is collecting data]
t=105s AUTO-LEARNING ADJUSTS:
timeoutMs: 2804ms → 3916ms (+40%)
maxRetries: 2 → 3 (+1)
cbFailureThreshold: unchanged
t=110s Recovery phase begins
Config maintained — insufficient recovery data for next cycle
55 seconds from stress beginning to autonomous configuration change. Two decisions made without human intervention:
The cbFailureThreshold stayed at 10. The system identified that the circuit breaker configuration was already correct for the observed pattern and left it alone.
The config did not revert during recovery. This is intentional — the system is conservative. It needs sustained evidence of healthy traffic before relaxing thresholds, to avoid oscillating between states. In production, that’s the right behavior.
The health check on the auto-learning endpoint: 100% throughout all 160 seconds.
What the numbers say together

What this is and what it isn’t
This is a reference implementation built on BackendKit Labs (https://github.com/BackendKit-labs/backendkit-monorepo) — a suite o resilience and observability packages for NestJS we’re building and validating publicly. The shopify-backend example exists specifically to test these patterns under realistic conditions and share the results.
The suite is young. These tests are part of the validation process, not proof of production hardening. If you run similar patterns in your own codebase and find edge cases, open an issue (https://github.com/BackendKit-labs/backendkit-monorepo/issues) — that’s exactly the feedback that matters at this stage.
The full example, all k6 scripts, and the source are in the monorepo
(https://github.com/BackendKit-labs/backendkit monorepo/tree/master/examples/shopify-backend).
Written by Mairon Cuello (https://www.linkedin.com/in/maironcuellomartinez/) — Building open source resilience tooling for NestJS backends.
GitHub: BackendKit-labs/backendkit-monorepo (https://github.com/BackendKit-labs/backendkit-monorepo)


I started building the thing I actually wanted to deploy. It’s on GitHub now, AGPL-3.0. This is a write-up of the architecture and, more usefully, the bugs that cost me real sleep.
The stack, and why
secsipid for STIR/SHAKENbgapi originate, mod_avmd, ESL, a Lua script per callSELECT FOR UPDATE SKIP LOCKED, a per-call state machine driven off ESL eventsWHERE tenant_id =
The split that people question most is Kamailio-in-front-of-FreeSWITCH. At small scale it’s arguably overkill, but Kamailio is the right tool for SIP routing and CPS, and FreeSWITCH is the right tool for media — keeping them separate means I can scale the media tier without touching the edge.
Multi-tenancy I actually trust
Every business row carries a tenant_id, and Postgres RLS policies key off a session variable the API sets per request. Even a buggy query physically can’t read another tenant’s rows, because the database refuses. After years of seeing tenant isolation implemented as “we’re careful with our WHERE clauses,” letting the DB enforce it was the part I felt best about.
The bugs that ate my nights
Press-1 never dialed. I’d pivoted to bridging to external agents, and ripped out the internal-agent concept — but the press-1 pacing still gated on “available agents,” which was now always zero. So a press-1 campaign would go live and do nothing. Fix was making press-1 fill to capacity like broadcast and letting the operator cap concurrency.
MP3 greetings played as silence. FreeSWITCH can’t decode MP3 without mod_shout, which wasn’t loaded. Loaded it — and the audio sounded terrible, because it was resampling a 44.1kHz stereo file down to 8kHz telephony on every single call. The real fix was transcoding uploads to 8kHz mono PCM WAV with ffmpeg at upload time, so mod_sndfile just plays them natively. Obvious in hindsight; not obvious at midnight.
“Press 1 does nothing” — a full night gone. In Lua, session:execute("playback", file) eats DTMF digits. My greeting playback was swallowing the keypress before the read after it ever listened. The call would fall straight through to the no-input hangup, so from the outside it looked like pressing 1 hung up the call. The fix is the canonical primitive — session:playAndGetDigits() — which plays the prompt and collects the digit in one step without eating it.
Answering-machine detection without paying for it. The old mod_amd isn’t in current builds and the maintained mod_com_amd went commercial. So I built voicemail-drop on mod_avmd (beep detection): the broadcast Lua starts avmd, plays the message, and on the beep event replays it after the tone so a clean copy lands on the voicemail. It’s a little hacky, but it’s free and it works.
Where it is now
Pre-release, honestly. The press-1 and broadcast flows work end to end — originate, AMD, greeting, keypress, bridge, recording — but there’s no production carrier wired up yet (I’ve been testing over a Linphone gateway, which has its own DTMF adventures), STIR/SHAKEN signing is configured in Kamailio but unproven against a real carrier, and there’s no agent softphone app.
If you’ve shipped real outbound telephony, I’d genuinely like to know what I got wrong before I point real traffic at it.
Repo: https://github.com/dev0miky/Outbound-calling-system-P1-Broadcast
It’s AGPL and self-hostable. Not selling anything — I just wanted the dialer I couldn’t find.
Why AI Coding Agents Fail Senior Engineers (And What I Built to Fix It)
AI coding agents are impressive. They write syntax-correct code. They know a thousand libraries.
They can implement anything you describe in seconds.
And that’s exactly the problem.
The Speed Trap
You describe a feature. The agent produces code. You ship it. It works.
For a while.
Then the requirements change. The team grows. The system scales. The codebase becomes
unmaintainable in ways that feel mysterious but are entirely predictable.
The code worked. The architecture was never designed.
I’ve been there. I gave Claude a task, it jumped to code, I shipped it, and three months later I was completely rewriting it because there was no architecture.
What Senior Engineers Actually Do
Watch a Staff Engineer approach a new task. They don’t open their editor.
They ask questions. They read existing code. They draw diagrams. They think about what happens in eighteen months when someone else maintains this. They document decisions — not to cover themselves, but because they know that future context is as valuable as present code.
By the time they write the first line of implementation, they know:
AI agents, left ungoverned, skip all of this. They optimize for the immediate request, not for the long-term health of the system.
The Gap
This isn’t a tool problem. It’s a process problem.
I built Kavro to close that gap.
Kavro is an open-source framework that enforces a 7-phase Staff-level engineering
workflow on top of any AI coding agent.
The 7 Phases (No Shortcuts)
Phase 1: Deep Research & Understanding
Understand the business goal, technical context, domain patterns, and risks.
Produce a Research Summary.
Code? No.
Phase 2: System Design & Architecture
Produce a complete Technical Blueprint with API contracts, data design, error handling
strategy, and a decision log for every major choice.
Code? No.
Phase 3: Task Decomposition
Break the project into atomic, independently-verifiable tasks with explicit dependencies,
scope, and validation steps.
Code? No.
Phase 4: Documentation
Establish the documentation baseline before implementation.
Code? No.
Phase 5: Prompt Orchestration
Generate precise, context-injected prompts for each task based on Phases 1-4.
Code? No.
Phase 6: Agent Selection
Decide which agent (or model tier) handles each task based on complexity.
Code? Not yet.
Phase 7: Governance
Execute continuously while validating output against the blueprint. Catch drift.
NOW code can be written. And it’s good code.
Why This Works
The best engineers don’t jump to solutions. They understand the problem deeply.
Kavro automates that discipline. The AI agent can’t skip ahead. Can’t vibe-code.
Can’t punt decisions to later. The workflow is enforced.
What It Looks Like
You: “Build me a notification service”
Without Kavro:
→ Claude writes code immediately
With Kavro:
→ Phase 1: Asks about business goals, risks, technical context
→ Produces Research Summary
→ Phase 2: Technical Blueprint with full decision documentation
→ Phase 3: Task decomposition with dependencies
→ Phase 4: Documentation structure
→ Phase 5-7: Orchestrated execution with continuous validation
→ Result: Ship with confidence
Open Source
Kavro is MIT licensed and works on:
Built on the agentskills.io open standard so it travels with developers, not with tools.
GitHub: https://github.com/a7medalyapany/kavro
Installation
git clone https://github.com/a7medalyapany/kavro.git
cd kavro
bash scripts/install.sh
For Claude.ai upload:
bash scripts/build.sh --claude
# Upload dist/kavro-claude.zip → Settings → Skills
The Long Vision
Kavro v1.0 is a skill — instructions that wrap around an AI agent.
The longer vision is a governance service that tracks architectural decisions across
sessions, detects drift over time, and gives engineering teams visibility into how
their AI agents are building systems.
Not surveillance. Accountability.
For Teams
If your team uses different AI tools (some use Claude, some use Cursor, some use Codex),
Kavro enforces the same discipline across all of them. One framework. Multiple agents.
The core belief behind Kavro is simple: A problem understood deeply is already half-solved.
Code written without architecture is technical debt by design.
Kavro makes AI agents think like senior engineers. It’s the difference between
“works now” and “works forever.”
If you’ve ever had to rewrite AI-generated code, give it a star.
Think before you build.