Mert
Google AI Studio yerleşik Android uygulaması geliştirebiliyor, mağazaya gönderebiliyor
Mobil uygulama geliştirenler için Google AI Studio önemli bir yenilik sunmaya başladı. Artık kütüphane indirmeye gerek kalmadan mobil uygulama geliştirip test edebilirsiniz.BMW’nin yeni konsept motosikleti Vision K18, bir savaş uçağını andırıyor
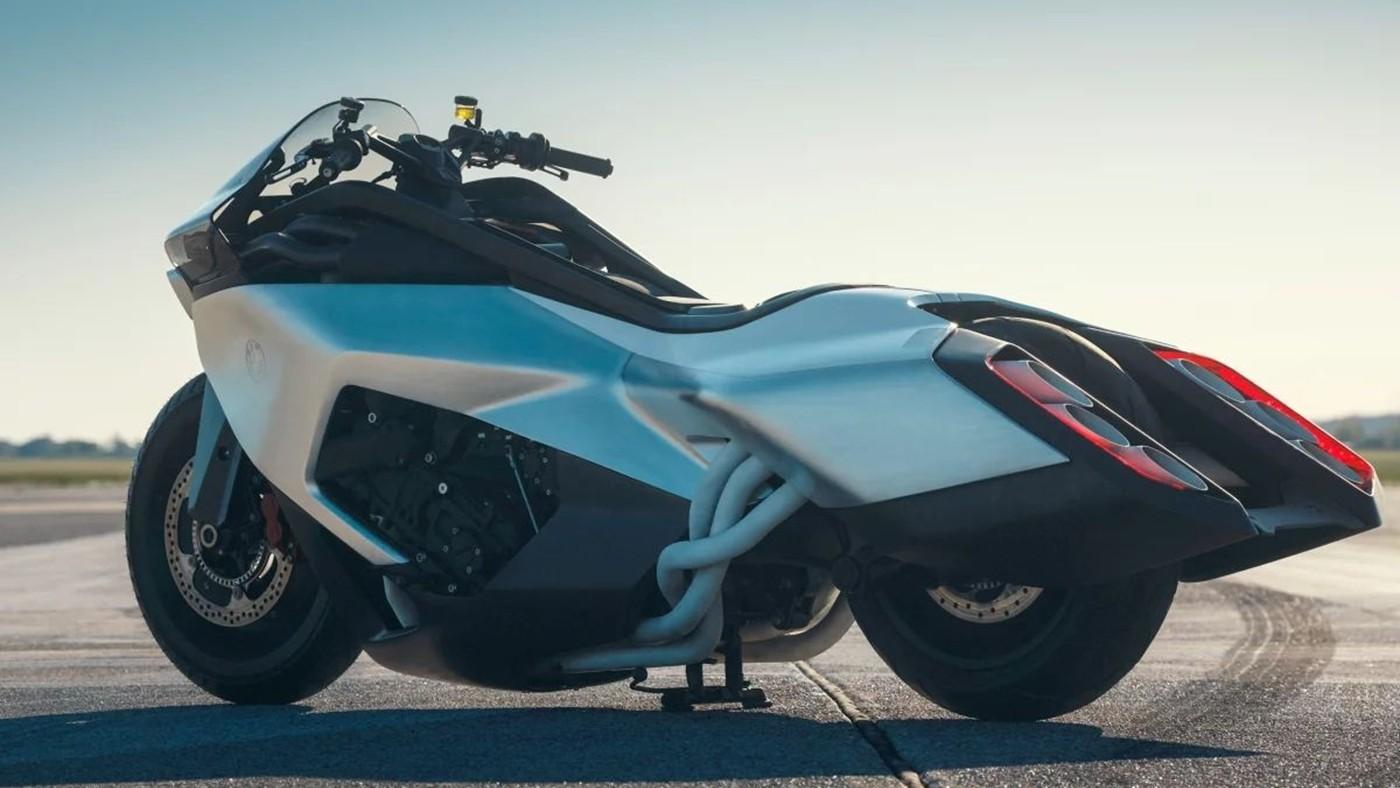
BMW Motorrad, Vision K18 adını verdiği yeni konsept motosikletini tanıttı. Uçaklardan ilham alan tasarımı, altı egzozu ve 1.800 cc motoruyla dikkat çeken model geleceğe göz kırpıyor.Legal Buddy 🚀 — AI-Powered Legal Chat, Document Review & Drafting with Gemma 4
This is a submission for the Gemma 4 Challenge: Build with Gemma 4
Legal Buddy ⚖️
A Local-First AI Legal Assistant for Indian Laws powered by Gemma 4
Most people blindly accept privacy policies, contracts, rental agreements, and legal terms without truly understanding what they are agreeing to. Legal language is often complex, inaccessible, and intimidating.
I built Legal Buddy to make legal understanding more accessible while keeping user privacy fully intact.
Legal Buddy is a local-first AI legal assistant designed specifically for the Indian legal ecosystem. It helps users:
- Understand legal concepts through conversational Q&A
- Analyze legal documents and detect risky clauses
- Generate legal document drafts instantly
And the most important part:
Everything runs locally through Ollama. No sensitive legal data leaves the user’s machine.
What I Built
Legal Buddy combines:
- ⚖️ Legal Q&A with Retrieval-Augmented Generation (RAG)
- 📄 AI-powered legal document analysis
- 📝 Legal document drafting
- 🔒 Fully local inference using Gemma 4 + Ollama
The application is designed for students, freelancers, employees, tenants, startups, and anyone who regularly encounters legal documents but may not have immediate access to legal expertise.
Core Features
💬 Legal Chat
Users can ask questions related to Indian laws in natural language.
The system uses:
- FastAPI backend
- FAISS vector search
- Local RAG pipeline
- Gemma 4 through Ollama
This allows responses to stay grounded in actual Indian legal references instead of generic AI-generated answers.
Examples:
- “What are tenant rights in India?”
- “Can an employer terminate without notice?”
- “What does an indemnity clause mean?”
📑 Document Scanner
Users can upload:
- PDFs
- Scanned contracts
- Images of agreements
The system performs:
- OCR extraction
- Clause analysis
- Risk detection
- Obligation summaries
- Highlighting unusual legal terms
Legal Buddy uses a map-reduce style document review pipeline, where sections are analyzed independently before generating a consolidated legal review report.
This is especially useful for:
- Rental agreements
- Employment contracts
- NDAs
- Service agreements
- Privacy policies
🖊️ Document Drafting
Users can instantly generate:
- NDAs
- Rental agreements
- Employment contracts
- Basic legal templates
The user simply provides:
- Party names
- Key conditions
- Agreement details
Gemma then generates structured draft documents tailored for Indian legal context.
Demo
Code
🔗 GitHub Repository:
https://github.com/SaiPavankumar22/Legal_Buddy
Architecture
The project follows a decoupled architecture:
Backend
- FastAPI
- OCR processing
- FAISS vector search
- Ollama orchestration
- Local document analysis pipeline
Frontend
- Vanilla JavaScript
- HTML/CSS
- Lightweight and fast UI
How I Used Gemma 4
I used Gemma 4 E2B for this project.
Why Gemma 4 E2B?
I specifically chose Gemma 4 E2B because it offers the right balance between:
- Performance
- Multimodal capability
- Local deployment practicality
- Privacy-focused inference
For a legal assistant, privacy is critical.
Users should not have to upload:
- contracts
- agreements
- legal disputes
- identity-related documents
to external servers just to get AI assistance.
Running Gemma locally through Ollama made this possible.
How Gemma Powers the Project
⚖️ Legal RAG Assistant
Gemma answers legal questions using:
- Local FAISS indices
- Indian legal corpus
- Retrieval-Augmented Generation
This grounds responses in actual legal material instead of relying purely on pretrained knowledge.
📄 Multimodal Document Analysis
Gemma analyzes uploaded:
- PDFs
- scanned pages
- images
It identifies:
- risky clauses
- hidden obligations
- liability-heavy sections
- suspicious wording
The multimodal capabilities were especially useful for layout-heavy legal documents.
📝 AI Legal Drafting
Gemma generates structured legal drafts using user-provided information.
This allows users to quickly create:
- NDAs
- rental agreements
- employment agreements
- legal templates
while still keeping the workflow local and private.
Privacy First 🔒
One of the biggest goals of Legal Buddy was ensuring that users retain ownership of their sensitive legal data.
With Ollama + Gemma:
- Documents stay local
- Queries stay local
- Analysis stays local
No cloud APIs are required.
Challenges Faced
Some of the biggest technical challenges were:
- OCR quality on scanned documents
- Chunking legal documents effectively for RAG
- Preventing hallucinations in legal responses
- Structuring long-form document analysis outputs
- Keeping inference efficient on consumer hardware
Balancing accuracy, privacy, and performance was one of the most interesting parts of building this project.
Future Improvements
Planned improvements include:
- Clause highlighting directly inside PDFs
- Citation-aware legal responses
- Support for regional Indian languages
- Voice-based legal assistance
- Fine-tuned legal adapters
- Legal risk scoring dashboards
Building Legal Buddy was an exciting experience because it showed how powerful local AI systems can become when combined with strong open models like Gemma 4.
Huge thanks to Google and the Gemma team for organizing this challenge 🙌
I replaced nginx with a reverse proxy I wrote in Go
I was learning Go and needed a project that wasn’t a todo app or a REST API.
I was already running nginx on my VPS to proxy my site. So I thought: what if I just… wrote that myself?
Spoiler: it’s now running in production at niixlabs.com.
Why nginx gets annoying
nginx works. It’s been working for 20 years. But every time I touch it I have to re-read docs to remember why proxy_set_header Connection 'upgrade' is needed and where it goes. The config syntax feels like a language you only half-know.
I wanted something where the config looked like what it was doing.
What I built
Apex Proxy – a reverse proxy and load balancer written in Go.
Install:
go install github.com/niix-dan/apexproxy@latest
Config:
server:
http_port: 80
https_port: 443
auto_tls: true # Let's Encrypt, handled automatically
routing:
- host: niixlabs.com
path: /
strategy: single
priority: 20
targets:
- url: "http://127.0.0.1:3000"
That’s it. apex start --config ./apex.yaml and it’s running.
What it can do right now
- Host and path-based routing with priority ordering
- Wildcard subdomain matching (
*.domain.com) - Load balancing: weighted round-robin, ip-hash, single
- Automatic TLS via Let’s Encrypt (no certbot needed)
- Per-route TLS cert support
- Real-time TUI dashboard –
apex statusshows live traffic, latency, bandwidth per route
The dashboard was actually the part I’m most happy about. nginx has no native equivalent. You either parse logs or set up a whole Grafana stack.
What it can’t do yet (honest list)
- Hot-reload without dropping connections
- Rate limiting (token bucket, it’s next)
- Response compression
- Dynamic backend lookup via Redis
- Health checks that actively probe backends
It’s a WIP. The core proxy engine works, TLS works, routing works. The rest is on the roadmap.
The part that surprised me
Writing a reverse proxy in Go is not that hard. net/http/httputil does the heavy lifting. The tricky parts were:
- TLS cert selection per hostname (SNI)
- Let’s Encrypt not issuing certs for localhost (had to add a self-signed fallback for dev)
- Weighted round-robin needing a flattened target slice to work correctly with atomic counters
None of these were impossible. They just needed actual thinking.
Running it as a service
sudo nano /etc/systemd/system/apexproxy.service
[Unit]
Description=ApexProxy
After=network.target
[Service]
ExecStart=/home/ubuntu/go/bin/apexproxy start --config /home/ubuntu/go/bin/apex.yaml
Restart=always
RestartSec=5
[Install]
WantedBy=multi-user.target
sudo systemctl enable apexproxy
sudo systemctl start apexproxy
Done.
If you want to contribute
The codebase is small and readable. If you know Go and want to work on hot-reload, rate limiting, or the Redis dynamic lookup strategy – open an issue or a PR.
I’m still learning Go. Code review is welcome too.
How to Stop Leaking AWS Keys to GitHub (And What to Do When You Already Did)
The 2 AM Phone Call Nobody Wants
Last year I got pulled into an incident at a previous gig. A junior engineer had pushed a .env file to a public repo. Within 11 minutes, automated scanners had grabbed the AWS access keys and started spinning up GPU instances for crypto mining. By the time we rotated credentials, the bill was already four figures.
This stuff happens constantly. The recent news cycle around government cloud keys ending up in public GitHub repos isn’t unique — it’s just the latest reminder that credential leaks remain one of the most boring, preventable, and absolutely catastrophic failures in our industry.
Let’s talk about why this keeps happening, how to fix it when it does, and how to make it nearly impossible to happen on your team.
Why Smart People Leak Credentials
The root cause is almost never “the developer was careless.” It’s usually one of these:
-
Local-only files drift into commits. Someone adds a config file to test something, forgets to gitignore it, and
git add .sweeps it up. - Credentials hardcoded “temporarily.” A quick test that becomes permanent. We’ve all done it.
- History contamination. Someone removes the secret in a follow-up commit, thinking that’s enough. It isn’t — the secret lives forever in git history.
- Wrong repo, wrong remote. Pushing a private fork’s contents to a public mirror by mistake.
The automated scanning bots that watch GitHub’s public event stream are fast. Research from various security teams has shown leaked AWS keys can be exploited within minutes of being pushed. You don’t have time to react manually.
Step 1: Detect Before You Push
The single most effective layer of defense is a pre-commit hook that scans for secrets. I’ve been using gitleaks across three projects this year and it has caught two genuine near-misses.
Install it locally:
# macOS
brew install gitleaks
# Or grab a release binary from the official repo:
# https://github.com/gitleaks/gitleaks/releases
Then wire it into a pre-commit hook. If you’re using the pre-commit framework (https://pre-commit.com/), drop this into .pre-commit-config.yaml:
repos:
- repo: https://github.com/gitleaks/gitleaks
rev: v8.18.0 # pin to a real release tag
hooks:
- id: gitleaks
# runs on every staged file before commit completes
Then:
pre-commit install
# verify it works by trying to commit a fake AWS key in a test file
If you don’t want a framework, a raw git hook works too. Create .git/hooks/pre-commit:
#!/usr/bin/env bash
# Block commits that contain detected secrets.
# Exits non-zero on a finding, which aborts the commit.
if ! gitleaks protect --staged --redact --verbose; then
echo "Secrets detected. Commit aborted."
echo "If this is a false positive, add it to .gitleaksignore"
exit 1
fi
Make it executable with chmod +x .git/hooks/pre-commit and you’re done.
Step 2: Detect Things That Already Slipped Through
Local hooks help, but they only protect commits made on machines where the hook is installed. You also need server-side scanning.
GitHub has built-in secret scanning, and it’s free for public repos. For private repos you’ll need to check the current pricing on their docs (https://docs.github.com/en/code-security/secret-scanning). If you can’t or won’t use that, a GitHub Action running on every push works fine:
name: secret-scan
on: [push, pull_request]
jobs:
gitleaks:
runs-on: ubuntu-latest
steps:
- uses: actions/checkout@v4
with:
fetch-depth: 0 # need full history for scanning
- uses: gitleaks/gitleaks-action@v2
env:
GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }}
The fetch-depth: 0 is important — without it you only get the latest commit, which means a sneaky push that hides a secret behind an innocent-looking final commit will slip past you.
Step 3: When You’ve Already Leaked
Okay, the worst happened. Here’s the order of operations, and the order matters:
1. Rotate the credential immediately. Not after you clean up the repo. Right now. Assume the credential is compromised the moment it touches a public commit, even for one second.
For AWS specifically:
# Deactivate the leaked key first (faster than deletion, reversible)
aws iam update-access-key
--user-name <username>
--access-key-id AKIA...
--status Inactive
# Then create a replacement
aws iam create-access-key --user-name <username>
# Once everything is migrated, delete the old key entirely
aws iam delete-access-key
--user-name <username>
--access-key-id AKIA...
2. Audit what the key did. Check CloudTrail for any API calls made by that access key ID since the leak. Look for unusual regions, unfamiliar resource creation, or IAM changes (attackers love adding their own users).
3. Purge the secret from git history. Just deleting the file in a new commit is not enough. You need to rewrite history with git filter-repo (the modern replacement for filter-branch):
# Install: pip install git-filter-repo
git filter-repo --invert-paths --path config/secrets.env
# Or to scrub a specific string across all history:
git filter-repo --replace-text <(echo 'AKIAIOSFODNN7EXAMPLE==>REDACTED')
Then force-push (after coordinating with your team — this rewrites shared history):
git push origin --force --all
git push origin --force --tags
4. Tell your security team. If this is a regulated environment, there are likely disclosure obligations. Don’t try to bury it.
Prevention That Actually Sticks
A few habits that have served me well:
- Use short-lived credentials wherever possible. For AWS, that means IAM Roles, IAM Identity Center, or OIDC federation from your CI provider. A leaked role assumption token that expires in an hour is dramatically less dangerous than a permanent access key.
-
Keep a strict
.gitignorefrom day one. Add*.env,*.pem,*.key,credentials,.aws/, and any framework-specific secret paths. Commit the.gitignorebefore you commit anything else. - Separate dev and prod credentials physically. Different accounts, different IAM principals, different machines if possible. Blast radius matters.
- Run scans against history periodically. New patterns get added to scanners all the time. Re-scanning old repos occasionally surfaces things that weren’t detectable when they were committed.
The Boring Truth
Credential hygiene isn’t glamorous and nobody gets promoted for it. But the cost of getting it wrong scales from “embarrassing Slack message” to “front page of Krebs” depending on what leaked and who you work for.
Set up the hooks. Use short-lived credentials. Assume any string that looks like a secret in your codebase has already been exfiltrated, and act accordingly. Future-you, woken up at 2 AM, will be grateful.
Warp Updates Oz to Help Enterprises Orchestrate Coding Agents Across Any Model or Harness
NEW YORK — Warp today announced major updates to Oz, its cloud agent orchestration platform, making it the first control plane that runs Claude Code, Codex, and Warp Agent side by side. The release adds cross-harness persistent memory, automatic multi-agent orchestration, and deeper enterprise controls, giving engineering teams the infrastructure to manage coding agents at scale … continue reading
The post Warp Updates Oz to Help Enterprises Orchestrate Coding Agents Across Any Model or Harness appeared first on SD Times.
JavaScript Number Tricks Every Developer Should Know (2026)
Numbers in JavaScript are weirder than you think. Here are the tricks that save me from bugs.
The Big Gotcha: Floating Point
0.1 + 0.2 === 0.3 // false!
0.1 + 0.2 // 0.30000000000000004
This isn’t a JavaScript bug — it’s how IEEE 754 floating point works.
Fix #1: Comparing Numbers
// ❌ Never use == or === for floats
if (a === b) { ... } // Dangerous!
// ✅ Use epsilon comparison
function approxEqual(a, b, epsilon = Number.EPSILON) {
return Math.abs(a - b) < epsilon;
}
approxEqual(0.1 + 0.2, 0.3) // true
Fix #2: Currency (Never Use Floats!)
// ❌ WRONG
const price = 19.99;
const tax = price * 0.088; // 1.7591200000000002
const total = price + tax; // 21.7491200000000002
// ✅ Option A: Work in cents (integers)
const priceCents = 1999;
const taxCents = Math.round(priceCents * 88 / 1000); // 176
const totalCents = priceCents + taxCents; // 2175
console.log((totalCents / 100).toFixed(2)); // "21.75"
// ✅ Option B: Round at display time
const total = parseFloat((price * 1.088).toFixed(2)); // "21.75"
// ✅ Option C: Use a library (for serious financial apps)
// intl-numberformat, currency.js, or dinero.js
Useful Number Methods
Rounding Done Right
const num = 42.6789;
Math.round(num); // 43 (rounds to nearest)
Math.floor(num); // 42 (always down)
Math.ceil(num); // 43 (always up)
Math.trunc(num); // 42 (removes decimal)
num.toFixed(2); // "42.68" (returns STRING, not number!)
num.toPrecision(4); // "42.68" (significant digits)
// ⚠️ toFixed returns a string! Don't do math with it:
parseFloat(num.toFixed(2)) + 1; // 43.68 ✓
num.toFixed(2) + 1; // "42.681" ✗ (string concat!)
Clamping Values
// Keep number between min and max
function clamp(value, min, max) {
return Math.min(Math.max(value, min), max);
}
clamp(-5, 0, 100); // 0
clamp(50, 0, 100); // 50
clamp(150, 0, 100); // 100
// Or with Math.clamp (newer browsers/Node)
Math.clamp(-5, 0, 100); // 0
Random Numbers
// Basic random
Math.random(); // 0.123... (0 ≤ x < 1)
// Random integer between min and max (inclusive)
function randomInt(min, max) {
min = Math.ceil(min);
max = Math.floor(max);
return Math.floor(Math.random() * (max - min + 1)) + min;
}
randomInt(1, 10); // 1-10 inclusive
randomInt(0, 1); // 0 or 1 (coin flip)
// Random element from array
const items = ['rock', 'paper', 'scissors'];
items[Math.floor(Math.random() * items.length)];
// Shuffle array (Fisher-Yates)
function shuffle(arr) {
const result = [...arr];
for (let i = result.length - 1; i > 0; i--) {
const j = Math.floor(Math.random() * (i + 1));
[result[i], result[j]] = [result[j], result[i]];
}
return result;
}
shuffle([1, 2, 3, 4, 5]); // [3, 1, 5, 2, 4] (random order)
// Random hex color
'#' + Math.floor(Math.random()*16777215).toString(16).padStart(6, '0');
// "#a3f2c1"
// Random ID generator
Math.random().toString(36).substring(2, 10);
// "x7k2m9np"
Number Formatting
// Add commas to large numbers
function formatNumber(num) {
return num.toLocaleString('en-US');
}
formatNumber(1000000); // "1,000,000"
formatNumber(1234567.89); // "1,234,567.89"
formatNumber(0.9876); // "0.988" (auto rounds)
// Currency formatting
function formatCurrency(amount, currency = 'USD') {
return new Intl.NumberFormat('en-US', {
style: 'currency',
currency,
}).format(amount);
}
formatCurrency(1234.56); // "$1,234.56"
formatCurrency(1234.56, 'EUR'); // "€1,234.56"
formatCurrency(1234.56, 'JPY'); // "¥1,235" (no decimals for JPY)
// Percentage
function formatPercent(num, decimals = 1) {
return new Intl.NumberFormat('en-US', {
style: 'percent',
minimumFractionDigits: decimals,
maximumFractionDigits: decimals,
}).format(num);
}
formatPercent(0.867); // "86.7%"
formatPercent(0.05); // "5.0%"
// Compact notation (1.2K, 3.4M)
function formatCompact(num) {
return new Intl.NumberFormat('en-US', {
notation: 'compact',
compactDisplay: 'short',
}).format(num);
}
formatCompact(1500); // "1.5K"
formatCompact(2500000); // "2.5M"
formatCompact(999500); // "1M" (not 999K)
// Bytes to human readable
function formatBytes(bytes, decimals = 2) {
if (bytes === 0) return '0 Bytes';
const k = 1024;
const sizes = ['Bytes', 'KB', 'MB', 'GB', 'TB'];
const i = Math.floor(Math.log(bytes) / Math.log(k));
return parseFloat((bytes / Math.pow(k, i)).toFixed(decimals)) + ' ' + sizes[i];
}
formatBytes(1024); // "1 KB"
formatBytes(1048576); // "1 MB"
formatBytes(1073741824); // "1 GB"
formatBytes(15360000); // "14.65 MB"
Parsing Numbers Safely
// ❌ Dangerous
parseInt('123abc'); // 123 (silently ignores non-numbers!)
parseInt(''); // NaN
parseInt(null); // NaN
parseInt(true); // NaN
parseInt('0x10'); // 16 (hex! might not be what you want)
parseFloat(' 42.5 '); // 42.5 (trims whitespace)
// ✅ Safe parsing
function safeParseInt(val, fallback = 0) {
const parsed = parseInt(val, 10);
return isNaN(parsed) ? fallback : parsed;
}
function safeParseFloat(val, fallback = 0) {
const parsed = parseFloat(val);
return isNaN(parsed) ? fallback : parsed;
}
safeParseInt('123abc', 0); // 123 (still accepts this)
safeParseInt('abc', 0); // 0 ← fallback
safeParseInt('', -1); // -1 ← fallback
// ✅ Even safer: validate first
function isNumeric(str) {
if (typeof str === 'number') return !isNaN(str);
if (typeof str !== 'string') return false;
return !isNaN(str) && !isNaN(parseFloat(str)) && isFinite(str);
}
isNumeric('42'); // true
isNumeric('42px'); // false
isNumeric(''); // false
isNumeric(null); // false
isNumeric(Infinity); // false
Math Tricks That Save Time
// Min/Max without Math.min/max (for small arrays)
const min = [3, 1, 4, 1, 5].sort((a,b)=>a-b)[0]; // 1
const max = [...[3, 1, 4, 1, 5]].sort((a,b)=>b-a)[0]; // 5
// But Math is faster for large arrays:
Math.min(...[3, 1, 4, 1, 5]); // 1
Math.max(...[3, 1, 4, 1, 5]); // 5
// ⚠️ Math.max/min spread can overflow the stack for huge arrays (>~65K elements)
// Power of 2 check
function isPowerOf2(n) {
return n > 0 && (n & (n - 1)) === 0;
}
isPowerOf2(8); // true
isPowerOf2(7); // false
isPowerOf2(1024); // true
// Between two numbers
function between(n, min, max) {
return n >= min && n <= max;
}
// Or clamp it: Math.min(max, Math.max(min, n))
// Distance between two numbers
function distance(a, b) {
return Math.abs(a - b);
}
// Linear interpolation (lerp)
function lerp(start, end, t) {
return start + (end - start) * t;
}
lerp(0, 100, 0.5); // 50
lerp(0, 100, 0.25); // 25
// Map value from one range to another
function mapRange(value, inMin, inMax, outMin, outMax) {
return outMin + ((outMax - outMin) * (value - inMin)) / (inMax - inMin);
}
mapRange(5, 0, 10, 0, 100); // 50
mapRange(7, 0, 10, 0, 1); // 0.7
// Average
function average(...nums) {
return nums.reduce((a, b) => a + b, 0) / nums.length;
}
average(1, 2, 3, 4, 5); // 3
// Median
function median(nums) {
const sorted = [...nums].sort((a, b) => a - b);
const mid = Math.floor(sorted.length / 2);
return sorted.length % 2 !== 0
? sorted[mid]
: (sorted[mid - 1] + sorted[mid]) / 2;
}
median([1, 2, 3, 4, 5]); // 3
median([1, 2, 3, 4]); // 2.5
// Sum
function sum(nums) {
return nums.reduce((a, b) => a + b, 0);
}
sum([1, 2, 3, 4, 5]); // 15
// Percent change
function percentChange(oldVal, newVal) {
if (oldVal === 0) return newVal > 0 ? Infinity : 0;
return ((newVal - oldVal) / Math.abs(oldVal)) * 100;
}
percentChange(100, 150); // 50 (% increase)
percentChange(100, 50); // -50 (% decrease)
percentChange(0, 50); // Infinity (from zero)
Weird JavaScript Number Facts
// These are all TRUE in JavaScript:
typeof NaN === 'number' // NaN IS a number type!
NaN === NaN // false (NaN is never equal to itself)
Number.isNaN(NaN) // true (correct way to check)
Infinity === 1/0 // true
-Infinity === -1/0 // true
1 / 0 === Infinity // true
0 / 0 === NaN // true
Number.MAX_VALUE + 1 === Number.MAX_VALUE // true (overflow stays at MAX)
Number.MIN_VALUE > 0 // true (smallest positive fraction)
Number.MAX_SAFE_INTEGER === 9007199254740991 // 2^53 - 1
Number.MAX_SAFE_INTEGER + 1 === Number.MAX_SAFE_INTEGER + 2 // true (precision lost!)
Number.isInteger(42) // true
Number.isInteger(42.0) // true
Number.isSafeInteger(Number.MAX_SAFE_INTEGER + 1) // false
// ParseInt quirks:
parseInt(1e21); // 1 (too big for int)
parseInt('1e21'); // 1 (same)
parseInt('0x10'); // 16 (hex detected)
parseInt('010'); // 10 (old behavior was octal, now decimal)
parseInt(''); // NaN
parseInt(null); // NaN
parseInt([]); // 0 (!!! coerces to "")
parseInt([5]); // 5 (!!! coerces to "5")
// Bitwise operators truncate to 32-bit integers:
| 0; // 0 (fast floor for positive numbers)
~~1.9; // 1 (double tilde = fast Math.floor for positives)
1.9 | 0; // 1
Quick Reference Card
| Task | Code |
|---|---|
| Round to 2 decimals |
+(n.toFixed(2)) or Math.round(n*100)/100
|
| Integer from float |
Math.trunc(n) or `n |
| Clamp | {% raw %}Math.min(max, Math.max(min, n))
|
| Random int 1-10 | Math.floor(Math.random() * 10) + 1 |
| Is integer? | Number.isInteger(n) |
| Is safe int? | Number.isSafeInteger(n) |
| Is NaN? |
Number.isNaN(n) (NOT global isNaN!) |
| Format as $ | n.toLocaleString('en-US',{style:'currency'}) |
| Parse safely |
parseInt(str, 10) always specify radix! |
| Sum array | arr.reduce((a,b)=>a+b, 0) |
| Unique random IDs | Math.random().toString(36).slice(2) |
What’s your favorite number trick?
Follow @armorbreak for more practical JS guides.
Talki vs Intercom: An Honest Comparison for B2B Startups in 2026
Intercom has been the default answer to “what should we use for customer support?” for over a decade.
But default answer and right answer aren’t the same thing — especially if you’re a B2B startup with a small team and real customers who expect fast, contextual support without the enterprise overhead.
Here’s an honest side-by-side. Not a takedown of Intercom — it’s a great product. But a genuine look at where each tool fits, and where it doesn’t.
Pricing
Intercom: Starts at $74/seat/month. A 3-person support team costs $222–$417/month before add-ons. Fin AI agent is billed at ~$0.99 per resolved ticket on top of that.
Talki: Free tier (1 agent, 100 conversations/month). Growth at $9/seat/month. Pro Max at $19/seat/month. Same 3-person team: $27–$57/month.
For an early-stage startup, Intercom’s pricing assumes a level of revenue and team size that most companies don’t have in their first year.
✅ Winner: Talki — not close.
AI Cost Per Resolution
This one surprised me most.
Intercom Fin: ~$0.99 per resolved ticket. For a team resolving 500 tickets/month via AI — that’s $495 extra on top of your seat fees.
Talki: AI resolutions included in the plan. Effective cost works out to ~$0.15 per resolved ticket — 6x cheaper than Intercom Fin.
The tradeoff: Fin handles more complex multi-step queries. Talki’s AI is faster to deploy (just point it at your website URL — it builds the knowledge base automatically) and dramatically cheaper at scale.
✅ Winner: Talki on cost; Intercom on sophistication.
Setup Time
Intercom: Custom bots, routing rules, inbox views, AI training — each requires deliberate configuration. Plan for days, not minutes.
Talki: Point the AI at your domain → knowledge base builds automatically → first auto-reply live in minutes. No FAQ writing, no bot flow builder.
For developers and technical founders who want something running today, this matters.
✅ Winner: Talki for speed.
Agent Experience
Intercom: Desktop-first. Solid inbox, good keyboard shortcuts. Not built for mobile workflows.
Talki: Agents respond to tickets directly from Telegram on their phone. No separate app required. For a technical founder doing support between PRs — this is the difference between a 5-minute and a 5-hour response time.
✅ Winner: Talki for small teams and mobile; Intercom for desk-based support orgs.
Customer Context (the Backend Connect feature)
This is where Talki gets interesting from a technical standpoint.
Intercom: Shows contact history and basic data. Custom backend data requires manual API integration per data type.
Talki: Send a signed webhook from your backend → live customer data appears directly in the ticket panel. Subscription plan, payment status, recent orders, any custom fields. No per-data-type integration needed.
POST /api/backend-connect
{
"customer_id": "usr_123",
"plan": "Pro",
"mrr": 49,
"last_payment": "2026-05-01",
"custom": { "games_played": 42 }
}
For B2B SaaS where the support question is almost always account-related — this cuts handle time significantly.
✅ Winner: Talki for B2B context out of the box.
Widget Customization
Intercom: Standard customization — colors, positioning, launcher style.
Talki: Extensive customization — colors, fonts, positioning, custom launcher icons, welcome messages, and behavior rules. The widget looks native to your product rather than a third-party tool dropped on the page.
✅ Winner: Talki for customization depth.
Multichannel & Integrations
Intercom: Email, live chat, in-app, WhatsApp, SMS. 300+ integrations. A decade of ecosystem building.
Talki: Telegram + web widget today. More channels on the roadmap. Smaller integration ecosystem.
Being honest: if your customers are spread across email, WhatsApp, and SMS — Intercom’s breadth is a real advantage.
✅ Winner: Intercom — clearly.
Quick Comparison Table
| Talki | Intercom | |
|---|---|---|
| Starting price | Free / $9/seat | $74/seat |
| 3-agent team/month | $27–$57 | $222–$417 |
| AI cost per resolution | ~$0.15 (included) | ~$0.99 (extra) |
| Mobile agent (Telegram) | ✓ | ✗ |
| Backend data in ticket | ✓ native webhook | Manual API |
| Widget customization | Extensive | Standard |
| Channels | Telegram + web | Email, chat, WhatsApp, SMS |
| Integrations | Focused | 300+ |
| Setup time | Minutes | Days |
Who Should Use Intercom
- You need marketing, sales, and support in one platform
- Customers are spread across multiple channels
- You have a dedicated support team with defined processes
- Series A+ with budget to match
- You need deep third-party integrations
Who Should Use Talki
- B2B startup with 1–5 people doing support
- You want live customer data (account, payments, custom fields) in every ticket — without building integrations
- Agents need to respond from a phone
- You want AI auto-replies live in minutes, at 6x lower cost than Intercom Fin
- You want a fully branded widget that looks native
- You’re not ready to spend $200+/month on support tooling
Bottom Line
Intercom is the right answer — eventually. When you have a dedicated team, defined processes, enterprise budget, and customers across 10 channels, it earns its price.
For most B2B startups in 2026, that moment hasn’t arrived yet.
Talki is built for the gap between “forwarding to email” and “we need enterprise support tooling.” If you’re in that gap, it’s worth a look.
talki.tech — free tier, no credit card required.
Building something similar or have questions about the comparison? Happy to discuss in the comments.