Introduction
Here is a scenario many RAG builders know well, you wire up a pipeline, load your documents, ask a question and the answer is wrong, vague, or confidently hallucinated. The information was right there in your knowledge base. So what went wrong?
In most cases the problem is not your embedding model. It is not your LLM. It is how you cut up your documents before storing them the under appreciated craft called chunking and whether the retrieval architecture you chose actually matches the complexity of your queries.
This blog walks you through every major chunking strategy, explains how retrieval and augmentation work on top of those chunks, covers two advanced architectures Agentic RAG and GraphRAG and most importantly gives you a complete decision framework so you can walk away knowing exactly which combination fits your use case.
🐘 The Elephant & The LEGO Pieces
Your document is an elephant.
A 200+ pages of legal contract, a dense research paper, a massive product manual, or years of enterprise knowledge large, complex, interconnected, and full of valuable information.
A Large Language Model cannot effectively consume the entire elephant at once because of:
- Context window limitations
- Retrieval precision constraints
- Latency considerations
- Token cost optimization
- Context dilution and retrieval noise
So the elephant must be divided into smaller pieces.
But this is where most RAG systems fail.
If you cut the elephant randomly, you destroy meaning.
Sentences lose context. Ideas become fragmented. Relationships disappear. Retrieval quality collapses.
Good chunking is not about making text smaller.
It is about preserving meaning while making retrieval efficient.
That is why chunking is better understood as turning the elephant into LEGO pieces.
LEGO pieces are:
-
Modular — each piece can stand on its own
-
Structured — pieces connect cleanly to related pieces
-
Consistent — standardized enough for reliable retrieval
-
Meaningful — each piece preserves semantic value
-
Composable — you assemble only the pieces needed for the task
Good chunking works the same way.
A well designed chunk should preserve structure, semantics, relationships, and surrounding context while remaining small enough for efficient retrieval and generation.
The real goal of chunking in RAG systems is not simply splitting documents.
Chunking is not simply about making documents smaller.
The actual goals are:
-
Preserve semantic meaning
-
Improve retrieval precision
- Reduce hallucinations
-
Optimize context windows
- Improve grounding quality
- Balance latency and cost
In practice:
Better chunks lead to better retrieval, better prompts, and better answers.
The goal is to retrieve:
- the right piece,
- with the right context,
- from the right section,
- at the right time.
That is the foundation of effective Retrieval Augmented Generation (RAG).
The RAG Pipeline:End to End

Every RAG system regardless of complexity follows the same four stage flow. Understanding each stage makes chunking and architecture decisions obvious rather than arbitrary.
Stage 1: Document
Your raw source material: PDFs, Word files, web pages, transcripts, database exports. Too large to pass directly to an LLM. Needs to be broken into chunks before it can be indexed or searched.
Stage 2: Chunking and Embedding
Documents are cut into units and each unit is converted into a vector embedding a numerical representation of its meaning. These embeddings are stored in a vector database and form your searchable index. Your chunking strategy here determines everything that follows.
Stage 3: Retrieval
When a user asks a question, the query is also embedded. The vector database returns the chunks whose embeddings are closest in meaning to the query. These are your retrieved LEGO pieces.
Stage 4: Augmentation and Generation
The retrieved chunks along with surrounding parent context are assembled into a prompt and sent to the LLM. The model generates an accurate, grounded answer from the material it receives.
Core insight: The quality of your answer is bounded by retrieval quality, which is bounded by chunk quality. Better chunks → better retrieval → better answers. Every architectural decision downstream is built on this foundation.

1. Fixed-Size Chunking
The simplest and most widely used strategy. Documents are split into equal sized blocks by token count, character count, or word count without regard for meaning, sentence boundaries, or document structure.
LangChain Methods
CharacterTextSplitter: splits on a single separator (default nn), then enforces chunk_size by character count.
TokenTextSplitter: splits by token count using a tokenizer (e.g. tiktoken for OpenAI models); more accurate for LLM context budgets than character based splitting.
from langchain.text_splitter import CharacterTextSplitter, TokenTextSplitter


# Character-based
splitter = CharacterTextSplitter(
    chunk_size=1000,    # max characters per chunk
    chunk_overlap=200,  # characters repeated at chunk boundaries
    separator="nn"
)

# Token-based
splitter = TokenTextSplitter(
    chunk_size=512,  # max tokens per chunk
    chunk_overlap=50 # tokens repeated at chunk boundaries
)
Overlap guidance: A 10–20% overlap is typical. For chunk_size=1000, set chunk_overlap between 100–200. Overlap reduces the risk of a relevant answer being split across two chunks, at the cost of minor redundancy.
Strengths: Simple to implement, fast, predictable, easy to scale.
Weaknesses: Frequently breaks sentences mid-way, degrading semantic continuity and retrieval quality on complex documents.
Best for: Logs, telemetry, JSON, CSV, and other uniform structured content.
2. Recursive Chunking
Rather than splitting blindly, recursive chunking respects natural document structure. It works down a priority list of separators — nn, then n, then . / ! / ?, then spaces — only moving to a finer separator when a chunk still exceeds the size limit.
This is the recommended default strategy in LangChain for most document types.
LangChain Methods
RecursiveCharacterTextSplitter: The primary implementation; tries each separator in the list before falling back to the next.
RecursiveCharacterTextSplitter.from_language(): pre-configured separator lists for specific programming languages (Python, JS, Markdown, HTML, etc.).
from langchain.text_splitter import RecursiveCharacterTextSplitter, Language

# General prose
splitter = RecursiveCharacterTextSplitter(
    chunk_size=1000,
    chunk_overlap=150,
    separators=["nn", "n", ".", "!", "?", " ", ""]
)

# Language-aware (e.g. Python source code)
splitter = RecursiveCharacterTextSplitter.from_language(
    language=Language.PYTHON,
    chunk_size=1000,
    chunk_overlap=100
)
Overlap guidance: 10–15% overlap works well for most prose. For code, keep overlap low (50–100 tokens) to avoid duplicating function signatures across chunks.
Strengths: Better semantic retention than fixed size chunking; good general-purpose strategy; improves retrieval coherence.
Weaknesses: Structure aware rather than meaning aware; performance depends on document formatting quality.
Best for: Documentation, PDFs, articles, knowledge bases, and web pages.
3. Semantic Chunking
Instead of asking how large should the chunk be, semantic chunking asks which sentences belong together.
Sentences are converted into vector embeddings, similarity is measured between adjacent sentences, and chunk boundaries are drawn where similarity drops below a threshold — indicating a topic transition.
LangChain Methods
SemanticChunker (from langchain_experimental) — supports three breakpoint detection strategies: percentile, standard_deviation, and interquartile.
from langchain_experimental.text_splitter import SemanticChunker
from langchain_openai import OpenAIEmbeddings

splitter = SemanticChunker(
    embeddings=OpenAIEmbeddings(),
    breakpoint_threshold_type="percentile",  # or "standard_deviation", "interquartile"
    breakpoint_threshold_amount=95           # top 5% of similarity drops become boundaries
)
Overlap guidance: Semantic chunking does not use a fixed chunk_overlap boundaries are drawn on meaning, so overlapping would undermine the approach. If continuity is needed at boundaries, consider appending the last sentence of the previous chunk manually.
Strengths: High retrieval relevance; strong semantic continuity; well-suited to precision-sensitive systems.
Weaknesses: Computationally expensive; requires an embedding model at chunking time; similarity thresholds need tuning per dataset.
Best for: Enterprise knowledge systems, research platforms, policy documents, and AI assistants requiring contextual precision.
4. Hierarchical Chunking
Creates two levels of chunks: large parent chunks for context, and smaller child chunks for precision.
Retrieval targets the child level to find relevant passages, then expands to the parent level to return surrounding context. This directly addresses the core RAG trade off: small chunks improve precision, large chunks preserve context.
LangChain Methods
ParentDocumentRetriever: stores parent chunks in a document store and child chunks in a vector store, then links them at retrieval time.
from langchain.retrievers import ParentDocumentRetriever
from langchain.text_splitter import RecursiveCharacterTextSplitter
from langchain.storage import InMemoryStore
from langchain_community.vectorstores import Chroma

parent_splitter = RecursiveCharacterTextSplitter(chunk_size=2000)  # large context chunks
child_splitter = RecursiveCharacterTextSplitter(chunk_size=400)    # precise retrieval chunks

retriever = ParentDocumentRetriever(
    vectorstore=Chroma(embedding_function=embeddings),
    docstore=InMemoryStore(),
    child_splitter=child_splitter,
    parent_splitter=parent_splitter
)
Overlap guidance: Apply overlap only on the child splitter (typically 10–15%). Parent chunks are retrieved wholesale for context, so overlap there adds noise rather than value.
Strengths: Strong retrieval precision without sacrificing context; effective for long documents.
Weaknesses: More complex to index and retrieve; requires additional storage and orchestration.
Best for: Legal documents, technical manuals, books, enterprise documentation, and compliance systems.
5. Structure and Metadata Aware Chunking
Uses the document’s own structure titles, headers, sections, tables, and page layout as natural chunk boundaries rather than treating the document as plain text.
Especially important for enterprise PDFs and structured reports, where layout carries semantic meaning that arbitrary splits would destroy.
LangChain Methods
MarkdownHeaderTextSplitter: splits on Markdown heading levels and attaches header text as metadata to each chunk.
HTMLHeaderTextSplitter: same pattern for HTML documents, splitting on '<h1>-<h4>' tags.
from langchain.text_splitter import MarkdownHeaderTextSplitter, HTMLHeaderTextSplitter

# Markdown
md_splitter = MarkdownHeaderTextSplitter(
    headers_to_split_on=[
        ("#",   "h1"),
        ("##",  "h2"),
        ("###", "h3"),
    ]
)
chunks = md_splitter.split_text(markdown_text)
# Each chunk carries metadata: {"h1": "Section Title", "h2": "Subsection"}

# HTML
html_splitter = HTMLHeaderTextSplitter(
    headers_to_split_on=[("h1", "h1"), ("h2", "h2")]
)
Overlap guidance: These splitters produce structurally bounded chunks rather than size bounded ones. If downstream chunks are still too large, pipe the output into a RecursiveCharacterTextSplitter with a modest overlap (100–150 characters) as a second pass.
Strengths: Preserves layout semantics; keeps tables intact; improves retrieval quality for structured enterprise documents.
Weaknesses: Requires a capable document parser; parser quality directly limits performance.
Best for: Financial reports, compliance documents, technical PDFs, medical documentation, and enterprise records.
6. Hybrid Chunking
Applies different chunking strategies based on content type within the same corpus fixed-size for logs, recursive for documentation, semantic for research papers, structure aware for Markdown or HTML.
LangChain does not have a dedicated hybrid splitter. Hybrid pipelines are composed manually using the building blocks above.
from langchain.text_splitter import (
    TokenTextSplitter,
    RecursiveCharacterTextSplitter,
    MarkdownHeaderTextSplitter,
)
from langchain_experimental.text_splitter import SemanticChunker

def hybrid_chunk(doc):
    content_type = doc.metadata.get("type")

    if content_type == "log":
        return TokenTextSplitter(
            chunk_size=512, chunk_overlap=0
        ).split_documents([doc])

    elif content_type == "markdown":
        return MarkdownHeaderTextSplitter(
            headers_to_split_on=[("#", "h1"), ("##", "h2")]
        ).split_text(doc.page_content)

    elif content_type == "research":
        return SemanticChunker(
            embeddings=embeddings,
            breakpoint_threshold_type="percentile"
        ).split_documents([doc])

    else:
        return RecursiveCharacterTextSplitter(
            chunk_size=1000, chunk_overlap=150
        ).split_documents([doc])
Overlap guidance: Set overlap per strategy based on content type. Logs and structured data: zero or minimal overlap. Prose and documentation: 10–15%. Code: 5–10%.
Strengths: Flexible and adaptable; better performance across mixed-content corpora.
Weaknesses: Higher engineering complexity; harder to evaluate and tune consistently.
Best for: Enterprise AI platforms, large mixed content corpora, knowledge management systems, and multi source RAG pipelines.
7. Agentic Chunking
An emerging approach where an LLM dynamically determines what information belongs together, how chunks should be formed, and how retrieval should adapt to user intent. This transforms chunking from static preprocessing into query aware reasoning at inference time.
LangChain supports this through its agent and chain abstractions rather than a dedicated splitter class.
from langchain.chains import LLMChain
from langchain.prompts import PromptTemplate
from langchain_openai import ChatOpenAI
import json

llm = ChatOpenAI(model="gpt-4o", temperature=0)

prompt = PromptTemplate.from_template("""
You are a document analyst. Split the following text into coherent topical sections.
Return ONLY a JSON list of objects, each with a "title" and "content" key.

Text:
{text}
""")

chain = LLMChain(llm=llm, prompt=prompt)

def agentic_chunk(text):
    result = chain.run(text=text)
    return json.loads(result)
Overlap guidance: Not applicable in the traditional sense the LLM determines boundaries based on meaning. To preserve continuity between sections, include a brief summary of the prior section in the prompt context.
Strengths: Highly adaptive; strong semantic preservation; query aware retrieval.
Weaknesses: Higher compute cost and latency; requires orchestration and guardrails; not yet widely proven in production at scale.
Best for: AI copilots, multi-agent systems, research assistants, and enterprise reasoning workflows.
8. Agentic RAG
Not to be confused with Agentic Chunking (#7).
Agentic Chunking is about how documents are split at index time. Agentic RAG is about how an LLM decides what to retrieve at query time and whether what it found is good enough to answer with.
Standard RAG pipelines are static: a query comes in, a fixed retrieval step runs, the top-k chunks are passed to the LLM, and an answer comes out. Agentic RAG breaks that linearity. An LLM agent decides when to retrieve, what to search for, whether the results are sufficient, and whether to re-query with a refined question before generating an answer.
Common patterns built on this idea include Corrective RAG (CRAG) which scores retrieved documents for relevance and falls back to a web search if they are poor and Self-RAG, where the LLM reflects on its own output and decides whether it needs to retrieve again.
LangChain Methods
create_retriever_tool wraps any retriever as a tool an agent can call on demand.
AgentExecutor the classic LangChain agent loop; the agent decides which tools to call and when.
LangGraph — the recommended approach for production Agentic RAG; models retrieval as a stateful graph of nodes (retrieve → grade → rewrite → retrieve again) with explicit conditional edges.
from langchain.tools.retriever import create_retriever_tool
from langchain_openai import ChatOpenAI
from langgraph.graph import StateGraph, END
from typing import TypedDict, List
from langchain_core.messages import BaseMessage

llm = ChatOpenAI(model="gpt-4o", temperature=0)

# Wrap retriever as a tool
retriever_tool = create_retriever_tool(
    retriever=vector_store.as_retriever(search_kwargs={"k": 5}),
    name="search_documents",
    description="Search the knowledge base for relevant information."
)

# --- LangGraph: Corrective RAG pattern ---

class AgentState(TypedDict):
    question: str
    documents: List[str]
    generation: str
    rewrite_count: int

def retrieve(state: AgentState):
    docs = vector_store.similarity_search(state["question"], k=5)
    return {"documents": docs}

def grade_documents(state: AgentState):
    # LLM scores each doc for relevance; filters out poor ones
    prompt = f"Is this document relevant to the question '{state['question']}'? Answer yes or no.nn{{doc}}"
    relevant = [
        doc for doc in state["documents"]
        if "yes" in llm.invoke(prompt.format(doc=doc.page_content)).content.lower()
    ]
    return {"documents": relevant}

def rewrite_query(state: AgentState):
    # If docs were poor, rewrite the question before re-retrieving
    rewritten = llm.invoke(
        f"Rewrite this question to improve retrieval: {state['question']}"
    ).content
    return {"question": rewritten, "rewrite_count": state["rewrite_count"] + 1}

def generate(state: AgentState):
    context = "nn".join(d.page_content for d in state["documents"])
    answer = llm.invoke(f"Answer using this context:n{context}nnQuestion: {state['question']}").content
    return {"generation": answer}

def should_rewrite(state: AgentState):
    if len(state["documents"]) == 0 and state["rewrite_count"] < 2:
        return "rewrite"
    return "generate"

# Build the graph
workflow = StateGraph(AgentState)
workflow.add_node("retrieve", retrieve)
workflow.add_node("grade", grade_documents)
workflow.add_node("rewrite", rewrite_query)
workflow.add_node("generate", generate)

workflow.set_entry_point("retrieve")
workflow.add_edge("retrieve", "grade")
workflow.add_conditional_edges("grade", should_rewrite, {"rewrite": "rewrite", "generate": "generate"})
workflow.add_edge("rewrite", "retrieve")
workflow.add_edge("generate", END)

app = workflow.compile()
result = app.invoke({"question": "What are the risks of GraphRAG?", "rewrite_count": 0})
Overlap guidance: Overlap is set on the underlying retriever’s chunking strategy — not on the agent itself. The agent layer operates above chunking. Use whatever overlap matches the chunking strategy feeding the vector store (typically 10–15% for recursive or fixed-size chunks).
Strengths: Handles multi-step and ambiguous queries that single-pass retrieval fails on; self-corrects when initial retrieval is poor; can combine multiple retrieval sources (vector DB, web search, SQL) in one query cycle.
Weaknesses: Higher latency per query due to multiple LLM calls; harder to debug than a linear pipeline; requires careful graph design to avoid infinite retrieval loops.
Best for: Complex Q&A systems, enterprise copilots where queries are open-ended, research assistants, and any pipeline where retrieval quality is highly variable.
9. GraphRAG
GraphRAG, originally developed by Microsoft Research, moves beyond treating documents as flat text sequences. Instead of chunking text into linear passages, it extracts entities and relationships from documents and stores them as a knowledge graph. Retrieval then traverses the graph to answer questions that require connecting information across multiple sources or document sections — something vector search alone handles poorly.
There are two primary retrieval modes: local search, which answers specific entity-level questions by traversing nearby graph nodes, and global search, which synthesizes themes across the entire corpus using community summaries generated at indexing time.
LangChain Methods
LangChain integrates with graph databases (Neo4j, Amazon Neptune, ArangoDB) and provides tooling to build graph-based RAG pipelines.
LLMGraphTransformer uses an LLM to extract entities and relationships from text and convert them into graph documents.
Neo4jGraph + GraphCypherQAChain store the graph in Neo4j and query it in natural language via generated Cypher queries.
Neo4jVector — hybrid approach that combines vector similarity search with graph traversal on a Neo4j backend.
from langchain_experimental.graph_transformers import LLMGraphTransformer
from langchain_community.graphs import Neo4jGraph
from langchain.chains import GraphCypherQAChain
from langchain_openai import ChatOpenAI

llm = ChatOpenAI(model="gpt-4o", temperature=0)

# Step 1: Extract entities and relationships from chunks
transformer = LLMGraphTransformer(llm=llm)
graph_docs = transformer.convert_to_graph_documents(documents)

# Step 2: Store in Neo4j
graph = Neo4jGraph(
    url="bolt://localhost:7687",
    username="neo4j",
    password="password"
)
graph.add_graph_documents(graph_docs)

# Step 3: Query the graph in natural language
chain = GraphCypherQAChain.from_llm(
    llm=llm,
    graph=graph,
    verbose=True,
    return_intermediate_steps=True
)
response = chain.invoke({"query": "Which authors collaborated with researchers at MIT?"})
For hybrid vector + graph retrieval:
pythonfrom langchain_community.vectorstores import Neo4jVector
from langchain_openai import OpenAIEmbeddings

# Store chunks as vectors alongside the graph
vector_store = Neo4jVector.from_documents(
    documents,
    embedding=OpenAIEmbeddings(),
    url="bolt://localhost:7687",
    username="neo4j",
    password="password",
    index_name="document_chunks",
    node_label="Chunk",
    embedding_node_property="embedding"
)

retriever = vector_store.as_retriever(search_kwargs={"k": 5})
Overlap guidance: GraphRAG does not rely on chunk overlap for continuity — relationships between entities bridge that gap structurally. When pre-chunking documents before graph extraction, use a RecursiveCharacterTextSplitter with modest overlap (100–150 characters) to ensure entity mentions near chunk boundaries are captured in at least one chunk before the LLM extracts them.
Strengths: Excels at multi-hop reasoning (e.g. “find all projects involving X that also relate to Y”); surfaces cross-document relationships invisible to vector search; global search enables corpus-wide thematic synthesis.
Weaknesses: Significantly higher indexing cost and complexity; graph quality depends on LLM extraction accuracy; Cypher query generation can be brittle on complex schemas; not well-suited to simple factual lookups where vector search is faster and cheaper.
Best for: Knowledge graphs, research corpora, compliance and regulatory systems, enterprise wikis with dense cross-references, and any domain where answering questions requires connecting facts across multiple documents.
The Core Trade-Off
A common misconception is that smaller chunks always improve retrieval. In practice, chunks that are too small lose context, fragment meaning, and can increase hallucinations.
Chunking is a balancing act across four competing factors:

There is no universally optimal strategy. The right choice depends on your data characteristics, query patterns, retrieval architecture, and business requirements.
Quick Reference

Final Thoughts
The strongest production RAG systems rarely rely on a single chunking strategy. A robust architecture typically combines:
-
Recursive chunking for general prose
-
Semantic chunking for precision-sensitive content
-
Hierarchical retrieval for long or dense documents
-
Structure-aware parsing for enterprise PDFs
-
Hybrid orchestration where content types vary
As enterprise AI matures, retrieval architecture is becoming just as important as model selection. And intelligent retrieval begins with intelligent chunking.


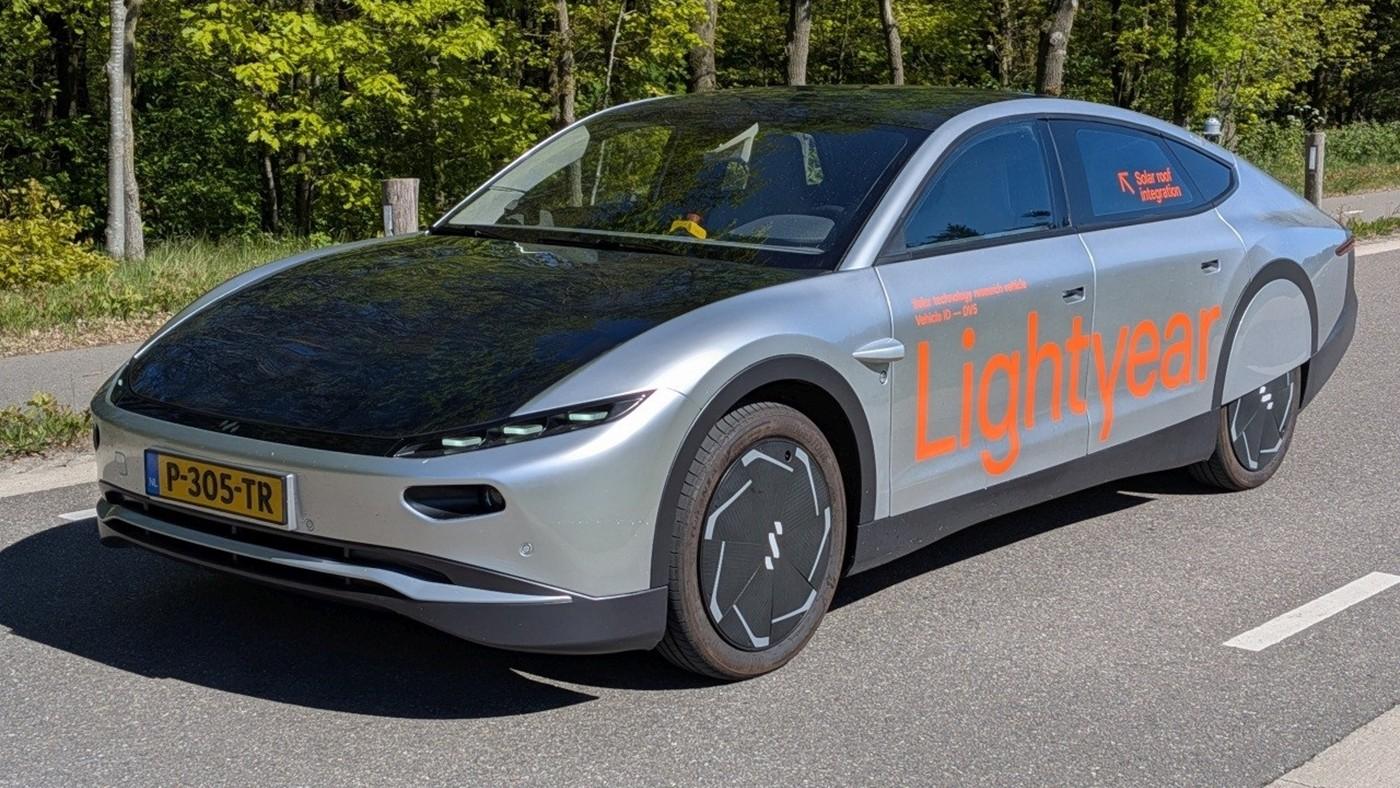
 Avrupa’daki yeni araştırmaya göre güneş panelli elektrikli otomobiller enerji ihtiyacının yüzde 80’ine kadarını kendi üretebilir. Teknoloji özellikle SUV ve kamyonlarda büyük avantaj sağlayabilir.
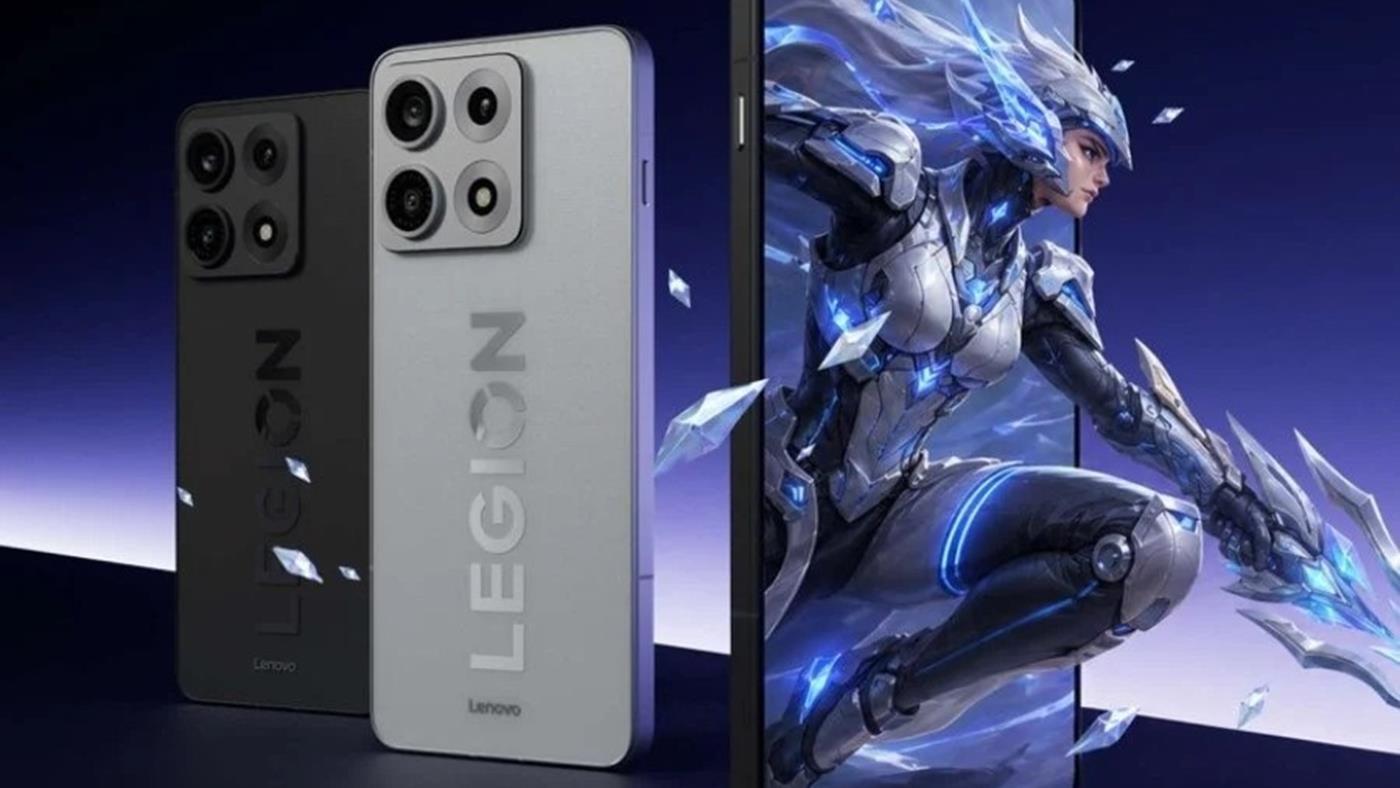
 Lenovo, birkaç yıl aradan sonra akıllı telefon pazarına Lenovo Legion Y70 ile resmi olarak geri döndü. Oyun odaklı yeni telefon, güçlü işlemcisi ve rekabetçi fiyatıyla dikkatleri çekiyor.
 Sony geçtiğimiz gün PlayStation Plus ücretlerine zam yapılacağını duyurmuş, bu konuda yaptığı resmi paylaşımda, “Bu fiyat değişikliği, mevcut aboneliğin değiştirilmesi veya iptal edilmesi durumları haricinde mevcut aboneleri etkilemeyecek. Ancak Türkiye ve Hindistan’daki kullanıcılar bu istisnanın dışında kalacak.” diyen şirket, “Mevcut piyasa koşullarına bağlı olarak yeni abonelere uygulanacak fiyatlar değişiyor. 1 aylık abonelikler 10,99 ABD Doları / 9,99 Avro / 7,99 İngiliz Sterlini, 3 aylık abonelikler ise 27,99 ABD Doları / 27,99 Avro / 21,99 İngiliz Sterlini seviyesine çıkarılıyor.” ifadelerini kullanmıştı. Yeni ücretleri bugün itibarıyla devreye alan Sony, Türkiye’deki “zamlı” fiyatları da paylaştı. Abonelik ücretleri zam sonrasında şu şekilde değişti. Eski: -PS+ Essential: 1 ay için 270 TL / 3 ay için 710 TL / 12 ay için 2.160 TL -PS+ Extra: 1 ay için 405 TL / 3 ay için 1.148 TL / 12 ay için 3.645 TL -PS+ Deluxe: 1 ay için 474 TL / 3 ay için 1.354 […]
