The Bane of International Payment Systems for Open Source Developers in Sub-Saharan Africa

The Problem We Were Actually Solving

The project ‘OpenAid’ is an OSS platform to help non-profits collect and allocate funds more efficiently to grassroots projects in sub-Saharan Africa. We decided to allow contributors to receive funding through the platform in the form of bank transfers. This was to help reduce transaction fees that come with traditional payment methods like PayPal and Stripe. At first, it seemed like a simple problem to solve but little did I know that I would be venturing into a rabbit hole of international payment systems.

What We Tried First (And Why It Failed)

We initially decided to use Gumroad and Payhip to handle transactions, but it turned out that these platforms did not have a presence in Nigeria. I didn’t think much of this at first, assuming that it was just an issue with the platforms since PayPal and Stripe did not work either. However, we soon realized that it was not our problem to solve but rather the platforms we were using. Contributors were getting frustrated with the lack of payment options available, which in turn affected the overall morale of the project. This was when we started to look for alternative solutions that would work in Nigeria.

The Architecture Decision

We decided to integrate the Flatforma platform, which is an open-source platform that simplifies the process of accepting donations and payments from the public, with bank transfer options available for Nigeria. However, this was not without its challenges. One of the biggest issues we faced was the need for international bank account numbers (IBANs) from Nigerian banks that could be easily accessed by the platform. After some research, we discovered that only 2 out of 7 banks in Nigeria supported IBANs. This made it difficult to find a bank that met our requirements. In the end, we decided to go with a bank that supported IBANs and used their API to handle transactions.

What The Numbers Said After

After integrating the Flatforma platform and finding a bank that supported IBANs, we saw a significant increase in payment success rates. We went from having a 30% payment success rate to over 90%. Not only did this improve the overall morale of the project, but it also allowed us to focus more on the technical aspects of the project. According to our analytics, over 80% of our contributors were from Nigeria, and the majority of them reported that the improved payment options made it easier for them to contribute to the project. We were able to successfully onboard new contributors and retain existing ones, all thanks to the improved payment system.

What I Would Do Differently

In retrospect, I would have done my research more thoroughly before selecting the initial payment platforms. I would have realized the risks associated with using platforms that do not cater to specific regions. I would have also communicated more effectively with the community about the challenges we were facing and the steps we were taking to solve them. This would have prevented some of the frustration that came with the initial rollout of the payment system.

Are we using LLMs for Personal Knowledge Management all wrong? 🤔

Andrej Karpathy recently shared a fascinating concept called the “LLM Wiki”—a brilliant shift from how most of us currently interact with our documents.

Right now, the standard approach is RAG (Retrieval-Augmented Generation). You upload files, ask a question, and the LLM retrieves chunks to generate an answer. It works, but there’s a catch: the LLM is rediscovering knowledge from scratch every single time. Nothing compounds.

Enter the LLM Wiki approach: 🧠
Instead of raw retrieval at query time, the LLM acts as a dedicated maintainer of a persistent, structured, and interlinked markdown wiki.

Here is how it changes the game:
1️⃣ Compounding Knowledge: When you add a new source, the LLM doesn’t just index it. It reads it, extracts key info, updates existing entity pages, and flags contradictions. The knowledge is compiled once and kept current.
2️⃣ Division of Labor: You don’t write the wiki. You are in charge of curating sources, exploring, and asking the right questions. The LLM does the grunt work—summarizing, cross-referencing, filing, and bookkeeping.
3️⃣ The Architecture: 🔹 Raw Sources: Your immutable files (PDFs, articles).
🔹 The Wiki: The LLM-generated markdown files (the synthesis).
🔹 The Schema: The instructions that tell the LLM exactly how to structure and maintain your specific domain.

Karpathy notes: “Obsidian is the IDE; the LLM is the programmer; the wiki is the codebase.” 💻

Imagine using this for deep-dive research, tracking your personal goals over years, building companion wikis for complex books, or maintaining an internal team knowledge base that actually stays up to date!

The biggest bottleneck of maintaining a knowledge base has never been the thinking—it’s the bookkeeping. And LLMs don’t get bored of bookkeeping.

Have you tried using AI to actively maintain a personal wiki yet, or are you still relying on standard RAG? Let’s discuss below! 👇

AI #MachineLearning #Productivity #LLM #KnowledgeManagement #AndrejKarpathy #TechTrends #Obsidian

PaySnap – AI Powered Wage Theft Detector

This is a submission for the Gemma 4 Challenge: Build with Gemma 4

What I Built

PaySnap is an AI-powered wage theft detector that helps workers
understand their paystubs and recover stolen wages in their language.

Every year, $50 billion is stolen from American workers through wage
theft. Construction workers, restaurant staff, and farmworkers are hit hardest. They don’t know their rights. They can’t read their paystub. Many are afraid to report.

PaySnap changes that. A worker uploads a paystub photo — or describes
their situation in Hindi, Spanish or Chinese and PaySnap tells them
exactly what they’re owed, which law was broken, and how to report it.

Try it live: paysnap.vercel.app

Key features:

  • Gemma 4 E2B fine-tuned on 365,393 real DOL enforcement cases
  • Native Gemma 4 function calling — truly agentic AI
  • Reads paystub photos via Gemma 4 vision (llama.cpp)
  • Explains violations in 11 languages
  • Detects overtime, illegal deductions, minimum wage violations
  • Always provides DOL hotline: 1-866-487-9243 (free, confidential)

Demo

🎥 Watch 3-minute demo

Live app: https://paysnap.vercel.app/

Scenario 1 — Texas construction worker:

  • Input: 52 hours, $15/hour, Texas, no overtime shown
  • PaySnap detects: 12 unpaid overtime hours
  • Result: $90 owed under FLSA 29 USC 207(a)(1)

Scenario 2 — New York restaurant worker (Hindi):

  • Input: 48 hours, $16/hour, NY, UNIFORM $35 + BREAKAGE $50 deductions
  • PaySnap detects: overtime violation + 2 illegal deductions
  • Result: $149 owed — full explanation in Hindi

Code

GitHub: https://github.com/Aadarsh-Praveen/Paysnap

Fine-tuned model (GGUF):
https://huggingface.co/Aadarsh-Praveen/paysnap-gemma4-gguf

LoRA weights:
https://huggingface.co/Aadarsh-Praveen/paysnap-gemma4-lora

Training notebook:
https://kaggle.com/code/aadarshpraveen/paysnap-gemma4-finetuning

Dataset (365,393 DOL cases):
https://kaggle.com/datasets/aadarshpraveen/paysnap-labor-law-dataset

How I Used Gemma 4

I chose Gemma 4 E2B for three specific reasons:

1. Edge deployment — Workers PaySnap serves often use older
devices. E2B runs at 63 tokens/second on Apple M3 Pro and fits
in 3.4GB as a Q4_K_M GGUF. A larger model would not run locally.

2. Fine-tuning efficiency — I fine-tuned E2B on 365,393 real
DOL enforcement cases using Unsloth LoRA on a Kaggle T4 GPU.
Training loss reached 0.009. A 31B model would have been
impossible on free compute.

3. Multilingual capability — Despite its small size, E2B
generates coherent responses in Hindi, Spanish, Chinese, and 8
other languages — critical for reaching vulnerable workers.

Four ways Gemma 4 powers PaySnap:

  1. Vision — reads paystub photos via llama.cpp multimodal API
  2. Native function calling — Gemma 4 autonomously decides which
    tools to call (calculate_overtime, check_deductions,
    get_applicable_statutes, get_dol_contact)
  3. Fine-tuned knowledge — learned real DOL enforcement patterns
    from 365,393 cases, +11.7% improvement on LLM-as-Judge eval
  4. Multilingual explanation — explains violations in worker’s
    language with exact statute citations

Evaluation (LLM-as-Judge, base Gemma 4 E2B as judge):

Base Gemma 4 E2B: 8.12/10
PaySnap fine-tuned: 9.07/10
Improvement: +11.7%

All 5 dimensions improved: Legal Accuracy +1.73, Statute Quality
+1.33, Actionability +0.73, Dollar Accuracy +0.67, Worker Clarity +0.27

Team
This project was built by:

Aadarsh Praveen Selvaraj Ajithakumari — @aadarsh_praveen

Suriya Kasiyalan Siva — @suriya_ks_0902

76 RLS policies rewritten in one migration: the auth.uid() init-plan trap in Supabase

GitHub logo

TL;DR. If your Supabase RLS policies call auth.uid() directly inside USING(...) or WITH CHECK(...), Postgres re-evaluates the function once per row. Wrap it as (SELECT auth.uid()) and the planner hoists the call to a single init plan that runs once per query. Same logical query, different plan, different cost at scale. We had 76 policies doing this wrong on Equip. Supabase’s own auth_rls_initplan advisor lint found every one of them.

Equip is an open-source LMS we run on equipbible.com — FastAPI backend, React frontend, Supabase Postgres with RLS on every public table. Migrations live in the repo as plain .sql files. Standard setup, nothing exotic.

A while back we ran Supabase’s database advisor as part of a pre-deploy sweep and one warning stopped us:

auth_rls_initplan: Detects RLS policies that re-evaluate
auth functions for each row.

It listed 76 of our policies. Same warning every time, same root cause.

What auth.uid() actually does per row

A typical Equip policy at the time:

-- BEFORE: auth.uid() called for every row scanned
CREATE POLICY "assignments_update_teacher" ON public.assignments
FOR UPDATE TO authenticated
USING (
  EXISTS (
    SELECT 1 FROM public.profiles p
    WHERE p.id = auth.uid()
      AND p.role IN ('teacher', 'admin')
  )
);

That auth.uid() looks like a constant. It isn’t. It’s a Postgres function marked STABLE, which means within one query it returns the same value, but the planner has to be told it can hoist the call out of the per-row loop. By default it doesn’t. Every row scanned during the policy check fires the function again, allocates the JWT context, reads the claim, returns it.

For a 50-row dev table you’d never notice. For a chapter_progress table with one row per (student × chapter), or a quiz_answers table that grows every time a student submits anything, it adds up fast.

The fix that takes ten characters

-- AFTER: auth.uid() runs once, planner caches the result
CREATE POLICY "assignments_update_teacher" ON public.assignments
FOR UPDATE TO authenticated
USING (
  EXISTS (
    SELECT 1 FROM public.profiles p
    WHERE p.id = (SELECT auth.uid())
      AND p.role IN ('teacher', 'admin')
  )
);

Wrapping the call in a subquery isn’t stylistic. The planner treats (SELECT auth.uid()) as a subquery returning one row of one value, and pulls it out into an InitPlan that runs exactly once at the start of the query. Every row check then sees a literal, not a function call.

You can confirm this on your own database. EXPLAIN ANALYZE on the bare version shows a function call inside the filter. On the wrapped version it shows InitPlan 1 at the top and the filter references $0. Same query, different plan.

Supabase covers this under RLS performance recommendations, but it’s easy to miss when you’re writing policies by hand at the same pace you’re shipping features.

Why we missed it for months

Honest moment: we shipped most of Equip’s policies with the raw auth.uid() pattern. They worked. Every test passed. Production users (students, teachers, admins) couldn’t tell the difference. We were nowhere near the row count where the per-row overhead would have shown up as user-visible latency.

That’s the actual trap. The warning sign isn’t “your app is slow.” By the time it’s slow you’ve already shipped a pile more policies in the same shape, because everything you wrote between then and now had no reason to fail. The trap is that this pattern works fine in dev and on a small prod, then quietly compounds when one table grows.

Two patterns reliably hit the cliff first in our experience:

  1. Per-user write tables like chapter_progress or quiz_attempts. One row per (student × content), grows linearly with engagement.
  2. Many-to-many junctions like enrollments. Scanned during nearly every authenticated read.

Anything else (small lookup tables, course catalogs, taxonomy) stays fast for a long time even with the bad pattern. So the early “we don’t see it yet” reading is correct, but it’s not informative. The pattern is structurally wrong, you just haven’t hit the row count that exposes it.

How we caught it: the database advisor

The Supabase project dashboard has an Advisors tab. Open it on any Postgres project and one of the performance lints is auth_rls_initplan. It scans pg_policies, parses the qual and with_check expressions, and flags any direct auth.<function>() call that isn’t wrapped.

Two ways to run it:

# Supabase CLI (v2.81.3+)
supabase db advisors

# Or via the dashboard:
# https://supabase.com/dashboard/project/<ref>/advisors/performance

If you’ve wired the Supabase MCP server into your dev environment, get_advisors returns the same list as a tool call you can run from an agent. Either way the output is a flat list of policy names. The migration itself is mechanical:

-- For each flagged policy: DROP + recreate with the wrapped call
DROP POLICY "<name>" ON public.<table>;
CREATE POLICY "<name>" ON public.<table>
FOR <command> TO <roles>
USING (<original expression with (SELECT auth.uid())>);

Our 20260421015755_rls_perf_cleanup_016_policies.sql did this 76 times in a single migration. Mostly find-replace with care to keep the original semantics intact.

The PL/pgSQL footgun nobody mentions

While you’re already in there, one more thing: if you’ve abstracted any of this into a helper function (e.g. is_admin() to keep policies DRY), check the language declaration.

-- BAD: planner can't inline a plpgsql function, every call is opaque
CREATE FUNCTION public.is_admin() RETURNS boolean
LANGUAGE plpgsql STABLE AS $$
BEGIN
  RETURN EXISTS (
    SELECT 1 FROM public.profiles p
    WHERE p.id = (SELECT auth.uid()) AND p.role = 'admin'
  );
END $$;

-- GOOD: SQL functions get inlined into the policy at plan time
CREATE FUNCTION public.is_admin() RETURNS boolean
LANGUAGE sql STABLE AS $$
  SELECT EXISTS (
    SELECT 1 FROM public.profiles p
    WHERE p.id = (SELECT auth.uid()) AND p.role = 'admin'
  );
$$;

LANGUAGE sql + STABLE + a single SELECT lets Postgres inline the function body into the policy at plan time. EXPLAIN looks identical to inline EXISTS. Switch to LANGUAGE plpgsql and the planner treats it as an opaque call. Can’t push predicates in, can’t reorder joins, every row hits the function.

We don’t use helpers in Equip yet, but multiple people in the Supabase community have hit this when extracting is_member_of(school_id) for multi-tenant setups. The helper looks right, the policy looks DRY, the EXPLAIN looks wrong.

What to do today, in order

  1. Open your project’s Advisors → Performance tab. Look for auth_rls_initplan. If the list is non-empty, you have the trap.
  2. Write a single migration that DROPs and recreates the flagged policies with (SELECT auth.uid()) everywhere auth.uid() appears bare. Don’t try to refactor the policies’ logic at the same time. Pure mechanical change.
  3. While you’re in the advisor, glance at multiple_permissive_policies and policy_exists_rls_disabled. Both compound the same per-row cost. Multiple permissive policies on the same role + action each run separately, so two bad policies double the trap.
  4. If you have helper functions in policies, verify each is LANGUAGE sql STABLE with a single SELECT body. Convert any plpgsql ones if you can keep the logic in pure SQL.

The advisor keeps flagging this on every new policy you write, so once you wire it into pre-merge checks (CI step, pre-deploy hook, or a habit on PR review) the trap doesn’t come back.

What I want to hear back, especially from people running Supabase in production:

  • Has this lint caught anything for you besides auth.uid()? auth.jwt() ->> 'role' should hit the same code path but I haven’t traced it directly.
  • If you’ve written is_member_of(...) helpers for multi-tenant RLS, did you keep them in SQL or move to plpgsql? Curious about the tradeoff at scale.
  • For anyone who left these unwrapped on purpose — what does that constraint look like? I can imagine a few cases where you’d want the per-row eval, but I can’t think of any in policy code specifically.

GitHub logo

ArVaViT
/
equip

Free, open-source LMS for Bible schools, ministries, and nonprofit educational programs. React + FastAPI + Supabase.

Equip logo

Equip

A free, open-source learning management system built for Bible schools
church ministries, and nonprofit educational programs


MIT License


Backend CI


Frontend CI


Good first issues


Code coverage


OpenSSF Scorecard

Live demo ·
Roadmap ·
Contributing ·
Support ·
Changelog

Screenshots


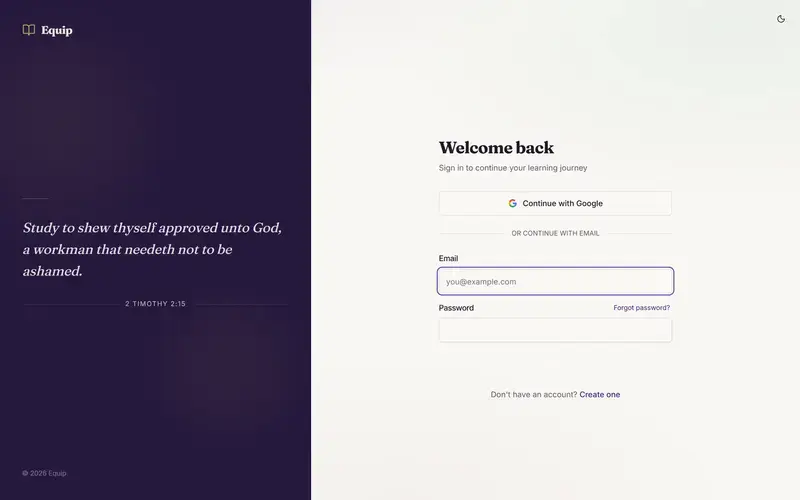
Equip login page — two-column layout with scripture on the left and a clean sign-in form on the right

Sign in (light)


Equip login page in dark mode

Sign in (dark)


Equip account creation with a Student or Teacher role chooser

Account creation — student / teacher role picker


Equip sign-in on a 390px mobile viewport

Mobile (390px)

Live at equipbible.com. Teacher and admin views (gradebook, course editor, analytics) are behind sign-in — create a free account to explore.

Why this project?

Hundreds of small Bible schools, home churches, and missionary training
programs around the world still manage courses on paper, WhatsApp, or
spreadsheets. Commercial LMS platforms are expensive, overkill, or require
technical expertise that volunteer-run organizations simply don’t have.

Equip is designed to change that:

  • Free forever — MIT-licensed, no paywalls, no “premium” tiers.
  • Simple to deploy — one-click Vercel deploy with a free Supabase
    database. No Docker, no servers to manage.
  • Built for small scale — optimized for 20-100 students, not…

Codex Has No Real Memory: Three Ways to Fix It, One in 30 Seconds

OpenAI Codex crossed 3 million weekly active users by April, 2026, with 70 percent month-over-month growth and 5x growth since January. The product has memory now, after the April 16 update. But the memory it ships with is project-scoped, cloud-only, and locked inside OpenAI. Three approaches actually solve the problem of giving Codex memory that survives sessions, follows you across machines, and connects to the same memory your other AI tools use: built-in memories with project files, an MCP memory server, or a hybrid setup that keeps OpenAI memories for sensitive code and an MCP server for everything else. The MCP path takes about 30 seconds to set up and works with Claude, ChatGPT, Cursor and seven other clients on the same memory store.

When the Codex usage numbers hit 3 million weekly users, what you are seeing is OpenAI shipping the productivity story Anthropic shipped 18 months ago, at a scale Anthropic never reached. Codex Web, Codex Desktop on macOS and Windows, the Codex app inside ChatGPT iOS, the Codex CLI, the VS Code extension. Five surfaces, one account, the same model behind all of them. By April 16 OpenAI added persistent memory to the Desktop app, alongside Computer Use, an in-app browser, image generation and a 90+ plugin marketplace.

If you read the announcement, “persistent memory” sounds solved. It is not. There are three different problems hiding behind that label, and Codex’s built-in memory only solves one of them. Here is what is actually going on, and three practical paths through it.

What “Codex memory” actually means today

OpenAI’s Codex memory, launched April 16, is project-scoped. You can pin instructions, code conventions and personal preferences inside a single Codex project. The memory persists between Codex sessions for that project. If you switch projects, you start fresh. If you switch from Codex to ChatGPT, you start fresh again. If you switch from Codex Web to Codex Desktop, the memory is supposed to follow but in practice users still report drift between surfaces.

This is the same model ChatGPT uses for its consumer memory feature. It is good for what it does. It is not what most developers mean when they ask whether Codex remembers them.

What developers actually want has three layers:

The first is session memory. Inside a single conversation, can the model remember what it did three turns ago? This was a problem in 2023. It is solved.

The second is project memory. Across multiple sessions on the same task, does the model recall the conventions of the codebase, the people on the team, the decisions you made last week? Codex’s built-in memory solves this for projects that live entirely inside Codex. It does not solve it if half your work is in Claude Code or Cursor.

The third is operator memory. Across every AI tool you use, can the model recall who you are, what you build, what your customers care about, what mistakes you do not want to repeat? This is the layer nobody at the model providers wants to solve, because their incentive is to lock you to their stack.

The three solutions below address layers two and three. Use what fits.

Solution 1: Codex’s built-in memories with project files

Codex has two ways to remember. The Memories feature stores user-specific preferences. Project-level config files store team-shared context. Together, for code that lives entirely inside Codex, this is enough.

The setup is straightforward. Inside any Codex project, create an AGENTS.md file at the repo root. Codex reads it on every task. This is the equivalent of the CLAUDE.md pattern that Anthropic established. Common entries: tech stack, coding conventions, deploy commands, PR rules, naming rules, “never do X” warnings.

# AGENTS.md

## Stack
Next.js 15, TypeScript strict, Prisma, Postgres on port 5433.

## Conventions
- Server Actions over API routes when possible
- Tailwind utility-first, no CSS modules
- Tests via Vitest for unit, Playwright for e2e

## Never
- `prisma db push --force-reset` on any branch
- Skip the read-before-edit hook
- Push to main without `pnpm typecheck`

For personal preferences that cross projects, use the Memories panel inside Codex Settings. Pin things like “I prefer concise responses with code first, explanation after” or “always cite the line numbers when referencing code”.

The limit of this approach is what I described earlier. It works inside Codex. It does not follow you to Claude or Cursor. If you live entirely in Codex, that is fine. If you do not, keep reading.

Solution 2: An MCP memory server connected to Codex

This is the path I run on. It takes 30 seconds to set up and gives Codex access to the same memory that Claude Code, Claude Desktop, Cursor, Codex CLI and seven other MCP clients read and write.

Codex supports MCP servers natively as of the late-March update. The configuration lives in ~/.codex/config.toml. Add a block like this:

[mcp_servers.memory]
url = "https://memory.studiomeyer.io/mcp"
type = "http"

That is it. No bearer token. No API key in your config. Restart Codex, run any tool that touches memory, and your browser opens a Magic Link login page. Enter your email, click the link in the email that arrives, and the OAuth flow finishes silently. Codex now has dauerhaften Zugriff auf the same memory store every other client of yours uses.

The numbers that matter: from “open config file” to “Codex queries memory” was 30 seconds in our test. The OAuth refresh token is stored in Codex’s secure credential store. No token ever lives in a git repo. The same memory is reachable from Claude Desktop, Claude Code, Cursor, the Codex CLI and Goose with the same one-click login.

What you can ask Codex once memory is wired in:

  • “Search my memory for past decisions about authentication.”
  • “What did I decide about the rate limiter last month?”
  • “Remember that I prefer to ship small commits.”
  • “What customers did I onboard in April?”

The model now reads and writes facts to a backend that survives across surfaces. If you change your mind about the rate limiter in Claude Code on Tuesday, Codex sees the new decision on Wednesday.

The piece worth flagging: there is a known class of bugs in Codex Desktop right now where multiple chats spawn full MCP process stacks per thread (GitHub issues 11324, 14548, 18333, 20980 all track variants). Memory grows linearly with open chats. If you run 10+ Codex tabs at once, you will see the issue. The workaround is to use HTTP-transport MCP servers (like the example above) rather than stdio servers. HTTP servers run once on the network, not once per tab.

Solution 3: The hybrid setup most teams should run

If you build with Codex on customer code that has compliance requirements and you also use Codex for personal projects, you probably want both. Built-in memory for the customer project that needs to stay locked inside OpenAI’s environment. MCP memory for everything else.

The way to wire this up: use Codex’s Memories panel for personal cross-project preferences. Use AGENTS.md files for project conventions. Use an MCP memory server for the operator-level memory that follows you across tools. The three layers do not conflict. They cover different scopes.

Concretely, in our team setup, the MCP memory holds learnings from previous sessions, decisions about architecture, customer profiles, deployment patterns and “never do this again” warnings. The AGENTS.md files hold project-specific stack and rules. The Memories panel holds personal communication preferences. When Codex starts a task, it has access to all three.

Honest limitations

If you go down the MCP memory route, three things you should know.

First, the memory backend matters. We run our own at memory.studiomeyer.io because we built it. There are alternatives: Mem0, Letta, Zep, MemNexus. Each has different opinions on what to store, how to retrieve, and how to bill. Try at least two before committing.

Second, retrieval quality is not free. A bad memory backend gives Codex stale or irrelevant context that can degrade output quality. Look for backends that support semantic search (vector retrieval) plus full-text plus knowledge graph. Single-modality retrieval is too brittle.

Third, the OpenAI memory feature ships fast. By December 2026 we expect Codex’s built-in memory to be much closer in capability to what an MCP backend offers. If you are betting on a long-term setup, the question is less “which is better right now” and more “which is portable when the landscape shifts again.” MCP-based memory is portable across providers. OpenAI memory is not.

What this means for builders

The 3 million weekly Codex users are split into two groups. One group is happy with the built-in memory and never thinks about MCP. The other group is the one that figured out their AI workflow does not run inside one provider’s walls. They use Claude for some things, Codex for others, Cursor for code, ChatGPT for research. For that second group, MCP memory is the load-bearing piece that makes the multi-tool workflow coherent instead of fragmented.

If you are in the first group, you are fine. The Memories feature is solid for what it covers.

If you are in the second group, the 30-second setup above is the move that compounds for the rest of 2026. Memory is the layer where context lives. Once it is wired, every AI tool you add later starts with the context already present, not from zero.

Try it

If you want to test the MCP memory path with our backend, the OAuth login is open at memory.studiomeyer.io. The free tier is 200 memory operations per month, enough to evaluate. Drop the config block above into ~/.codex/config.toml, restart Codex, log in once, and you are wired.

If you want a different backend, the same Codex config pattern works with any MCP-compliant memory server. The protocol is open. The lock-in is not in the memory layer. It is in the model layer above. Pick your memory backend on portability, not on which model maker promises memory next.

Originally published on studiomeyer.io. StudioMeyer is an AI-first digital studio building premium websites and intelligent automation for businesses.

Put Copilot Metadata Where Your Team Can Review It

Copilot metadata and source control architecture

Originally published at https://shai-kr.github.io/data-ninja-ai-lab/blog/2026-05-20-copilot-metadata-source-control.html

Copilot metadata and source control architecture

Copilot in Power BI is moving the semantic model into a new role.

It is no longer only the layer that stores measures, relationships, tables, and security rules.

It is also becoming the place where teams define how AI should understand the business.

That changes the engineering standard.

If Copilot uses metadata to answer business questions, that metadata should not live as invisible configuration edited by one report author on a good day.

It should be reviewed.

It should be versioned.

It should be tested.

And in serious Power BI environments, it belongs in source control.

The feature is not the point

The easy version of this story is:

Power BI now has tools to prepare semantic models for AI.

That is true, but it is not the useful lesson.

The more important shift is that Copilot readiness is becoming part of the semantic model lifecycle.

Power BI now gives model owners tools such as:

  • AI instructions
  • AI data schema context
  • verified answers
  • trigger phrases
  • Copilot testing workflows
  • an approved-for-Copilot model setting
  • PBIP storage for Copilot metadata

Prep data for AI in Power BI Desktop

This is not report polish.

This is semantic engineering.

The metadata now lives with the model

The detail that matters most for engineering teams is simple:

When a Power BI project is saved as PBIP, Copilot metadata is stored in a Copilot/ folder inside the semantic model project.

The structure looks roughly like this:

PBIP/
├── Model.SemanticModel/
│   ├── definition/
│   ├── Copilot/
│   │   ├── Instructions/
│   │   │   ├── instructions.md
│   │   │   ├── version.json
│   │   ├── VerifiedAnswers/
│   │   │   ├── definitions/
│   │   │   ├── version.json
│   │   ├── schema.json
│   │   ├── examplePrompts.json
│   │   ├── settings.json
│   │   └── version.json
│   └── definition.pbism

That means Copilot behavior can become part of the same workflow as model changes.

A pull request can now include:

  • a measure change
  • a relationship change
  • a description update
  • a verified answer definition
  • an instruction change
  • a Copilot schema update

Those changes should be reviewed together because users experience them together.

Copilot metadata is now an engineering artifact

Why this matters

Most Power BI teams already know that bad semantic models create bad reports.

Copilot adds another layer:

Bad semantic metadata creates bad AI answers.

A vague measure name is no longer just annoying for developers.

A weak description is no longer just documentation debt.

A poorly governed synonym or verified answer can steer users toward the wrong interpretation of the business.

This is especially important for models used across multiple reports or apps. When the model becomes approved for Copilot, the risk is not isolated to one page. It can affect every experience that depends on that semantic model.

Prep data for AI options

What should go through review

If a team is using PBIP and Git, Copilot metadata should not be treated as noise in the repo.

At minimum, I would review these changes before promotion:

  1. Instructions

Do the instructions reflect how the business actually talks about the data?

If finance calls it “net revenue” and sales calls it “bookings”, the model needs to make that distinction clear.

  1. Verified answers

A verified answer should be tied to a known, trusted interpretation.

It should not become a workaround for a weak model.

  1. Trigger phrases

The phrasing should match real user language, not developer language.

“Show customer churn by cohort” and “why did retention drop last month?” are not the same question.

  1. Schema changes

Copilot schema updates should be reviewed with table, column, relationship, and measure changes.

Otherwise the AI context can drift away from the model.

  1. Promotion requirements

Some tooling changes require a model refresh after deployment before they sync into the service.

That should be part of the deployment checklist, not something discovered after users start asking questions.

What belongs in the pull request

The migration from Q&A is a governance moment

There is another detail teams should not ignore.

Power BI can migrate older Q&A tooling metadata into the newer Copilot tooling format, but this is not a harmless cosmetic migration.

After the upgrade, Q&A features are permanently disabled for the model and connected reports. Some Q&A metadata migrates, such as synonyms and suggested questions. Other metadata does not.

That means the migration should be planned like a model change.

Not like a dialog box someone clicks through.

Before upgrading a production model, I would check:

  • which reports still use Q&A visuals
  • whether linguistic metadata is valid
  • which synonyms and suggested questions are worth keeping
  • whether business users depend on Q&A today
  • how Copilot answers will be tested after migration
  • whether the team can roll back through version history or backups if needed

Q&A visual after migration

A practical workflow

The best pattern is not complicated.

For production semantic models, treat AI readiness as a normal engineering workflow:

  1. Clean up the model
  2. Add descriptions, synonyms, instructions, and verified answers
  3. Save the project as PBIP
  4. Review the Copilot/ folder in Git
  5. Test with Copilot in Desktop or the service
  6. Check how Copilot arrived at the answer
  7. Promote through the deployment path
  8. Refresh the model if the deployment requires it
  9. Monitor feedback from real users

AI readiness workflow for Power BI teams

This gives the team a simple standard:

If the change can affect what Copilot tells a user, it deserves the same discipline as a DAX or model change.

What I would add to a PR checklist

For a Power BI team using Copilot, I would add these checks to the semantic model review process:

  • Did any files under Copilot/ change?
  • Did any measure, table, or column descriptions change?
  • Did the change affect a verified answer?
  • Are trigger phrases business-readable?
  • Did someone test the answer in the Copilot pane?
  • Did someone check how Copilot arrived at the answer?
  • Does the model need a refresh after deployment?
  • Are there reports or apps that inherit the approved-for-Copilot status?
  • Is any Q&A migration involved?
  • Is the change safe for every audience that can access the model?

The real shift

The real shift is not that Power BI added more AI buttons.

The real shift is that AI behavior is becoming part of the analytics system.

That means BI teams need to stop treating Copilot readiness as a last-mile report setting.

It belongs with the semantic model.

It belongs in Git.

It belongs in code review.

And it belongs in the same quality process as every other change that can affect business interpretation.

That is how Power BI teams move from “we turned Copilot on” to “we can trust what Copilot is allowed to say.”

What is CPA — Cost Per Acquisition Basics and How to Set the Right Target

Cost Per Acquisition by Industry

“Is this CPA in our ad dashboard high or low?” — almost every ecommerce operator has asked this question. Google Ads and Meta Ads always report CPA, but whether a given number is acceptable depends on context the dashboard does not show.

Industry benchmarks vary widely. For ecommerce overall, CPA typically lands between 1,000 and 5,000 JPY per conversion, but products with higher AOV can tolerate higher CPA. Bottom line: CPA cannot be judged in isolation. It must be compared against breakeven CPA — derived from AOV and gross margin — to decide whether a campaign is healthy.

This post explains what CPA is from the perspective of ecommerce operators. I cover the definition, the formula, the differences from CPC and CAC, industry benchmarks, four levers to reduce CPA, and a 3-step path to measure your own CPA.

TL;DR

  1. CPA = Ad Spend ÷ Conversions

The cost of acquiring one conversion (purchase or signup) through advertising.

  1. Lower CPA isn’t always better

The true threshold is breakeven CPA (= AOV × gross margin). Above this line, every conversion loses money.

  1. Set targets by reverse-calculation

A product with AOV 5,000 JPY × gross margin 40% has a breakeven CPA of 2,000 JPY. Your target CPA must stay below it.

  1. Largest CPA swings usually come from LP CVR uplift

Not from bidding tweaks. Doubling conversions halves CPA.

  1. Make CPA a budget input, not a dashboard number

Run a UTM → channel aggregation → breakeven comparison loop on your own data.

What Is CPA — the Cost to Acquire One Conversion

CPA stands for Cost Per Acquisition, the cost of acquiring one conversion (a purchase or signup) through advertising. Google Ads labels it “Cost per conversion.” Meta Ads calls it “Cost per result.”

CPA measures the per-conversion efficiency of advertising. Lining up CPA across campaigns instantly shows which ones acquire conversions efficiently and which do not.

However, CPA is a cost-side metric. It says nothing about revenue, contribution margin, or profit per acquired conversion. That is the first pitfall when interpreting CPA.

CPC and CAC — three cousins to keep straight

CPA is often confused with two similar metrics: CPC (Cost Per Click) and CAC (Customer Acquisition Cost).

Metric Formula Measures Primary use
CPC Ad spend ÷ Clicks Cost per click Creative efficiency
CPA Ad spend ÷ Conversions Cost per conversion Campaign efficiency
CAC Total marketing spend ÷ New customers Cost per new customer Business-level marketing efficiency

CPC counts clicks, CPA counts conversions, and CAC counts new customers acquired against all marketing spend — not just paid ads. CPA is a channel-level metric. CAC is a business-level metric. Confusing the two is how you end up cutting a “high-CPA” prospecting campaign that was actually feeding healthy CAC.

The CPA Formula and a Worked Example

The formula has only one form.

CPA = Ad Spend ÷ Conversions

If I spent 500,000 JPY over a month and generated 200 purchase conversions, my CPA is 500,000 ÷ 200 = 2,500 JPY.

Campaign-level CPA comparison

Listing multiple campaigns side by side reveals where efficiency is leaking.

Campaign Ad spend Conversions CPA
Google Search 200,000 JPY 100 2,000 JPY
Meta Retargeting 150,000 JPY 80 1,875 JPY
Meta Prospecting 150,000 JPY 20 7,500 JPY
Total 500,000 JPY 200 2,500 JPY

Meta Prospecting has a CPA roughly four times higher than the other campaigns. But pausing it on this signal alone may be premature — prospecting campaigns often look expensive on first-touch CPA yet pay back through LTV (customer lifetime value).

Target CPA — Google Ads’ automated bidding

Google Ads offers a bidding strategy called target CPA (tCPA). Advertisers set a target CPA and Google’s machine learning optimises bids toward it.

How to choose that target is the subject of the next section. Setting a target from dashboard numbers alone risks running ads that never turn a profit — you need breakeven CPA as the anchor.

Industry Benchmarks — and Why They Mislead

CPA varies significantly across industries. Search advertising benchmarks from international reports place median CPA roughly in the following ranges.

Cost Per Acquisition by Industry

These ranges are reference values from international benchmark studies. Judging CPA solely against industry benchmarks is dangerous — you must always compare to your own breakeven CPA.

Breakeven CPA — the right number for your business

Breakeven CPA is the line above which every conversion loses money. The formula is straightforward.

Breakeven CPA = AOV × Gross Margin

A product with AOV 5,000 JPY and gross margin 40% has a breakeven CPA of 5,000 × 0.4 = 2,000 JPY. Any CPA above this means each conversion piles up losses.

Different AOV and margin combinations produce different breakeven CPAs.

AOV Margin 30% Margin 40% Margin 50%
3,000 JPY 900 1,200 1,500
5,000 JPY 1,500 2,000 2,500
10,000 JPY 3,000 4,000 5,000
20,000 JPY 6,000 8,000 10,000

The question “Is CPA 5,000 JPY high or low?” cannot be answered without knowing AOV and gross margin. Computing your breakeven CPA once gives you an instant judgment frame every time you open the ad dashboard. AOV and gross margin are core revenue drivers in ecommerce — both tie into the broader benefit design framework for EC.

Four Levers to Reduce CPA

CPA-reduction tactics fall into four buckets.

Four Levers to Reduce CPA

In practice, “LP CVR uplift” tends to deliver the largest swing. Because CPA is Ad Spend ÷ Conversions, doubling conversions halves CPA. For most ecommerce sites, moving LP CVR from 1% to 2% beats anything you can do on the bidding side.

However, these levers only compound if you can trace which change actually moved CPA. That is what the next section is for.

A 3-Step Path to Measure Your Own CPA

To turn CPA from “a number on the dashboard” into “an input to business decisions,” you need to run three steps on your own data.

Step 1: Identify ad traffic with UTM parameters

The CPA in your ad dashboard only counts conversions the ad platform itself can attribute. When the same user clicks both a Google Ad and a Meta Ad, both platforms can claim the conversion.

Tagging every ad URL with consistent UTM parameters (utm_source, utm_medium, utm_campaign) lets your analytics tool de-duplicate ad traffic in one place.

Step 2: Aggregate revenue and margin by channel

Using UTM-identified channels, sum revenue, conversions, ad spend, and gross profit. Recompute CPA as measured conversions ÷ ad spend on your side, not the dashboard CPA.

Pairing measured CPA with breakeven CPA gives you a complete channel-level profit/loss view.

Step 3: Decide stop/continue against breakeven CPA

Lay measured CPA against breakeven CPA for each channel.

Channel Measured CPA Breakeven CPA Decision
Google Search 1,500 JPY 2,000 JPY Continue, add budget
Meta Retargeting 1,800 JPY 2,000 JPY Continue
Meta Prospecting 4,500 JPY 2,000 JPY Improve or pause

Only at this point does CPA stop being a dashboard number and start informing budget decisions.

Discussion question

What’s your current workflow for setting a target CPA — do you reverse-calculate from AOV × margin, or do you anchor on industry benchmarks (or just inherit whatever the previous owner set)? Curious how often the “dashboard CPA” and “measured CPA on your side” actually diverge in practice.

References

  1. METI “FY2024 Survey on Electronic Commerce” August 2025
  2. Dentsu “Advertising Expenditures in Japan 2024” February 2025
  3. Google Ads Help “About Target CPA bidding”
  4. Meta Business Help Center “About ad costs”
  5. LocaliQ “Search Advertising Benchmarks”

Original article (with charts and tables): What is CPA — Cost Per Acquisition Basics and How to Set the Right Target

RevenueScope is a Japan-focused, revenue-first analytics tool for ecommerce operators. It groups UTM-identified ad traffic by channel, computes revenue, CV, and CPA against breakeven CPA, and surfaces the gap between dashboard CPA and on-site measured CPA — so steps 1 to 3 above collapse into about five minutes per week.

Sorry if my English sounds weird!!

Harness Engineering: The Unglamorous Work That Makes AI Agents Work

TLDR: Everyone obsesses over which AI model to use. But in production agent systems, the model is rarely the bottleneck – the scaffolding around it is. Harness engineering is the discipline of building that scaffolding: execution orchestration, evaluation, observability, safety guardrails, and memory. It’s unglamorous, underappreciated, and it’s where the real differentiation lives. Teams that treat it as an afterthought ship demos. Teams that take it seriously ship products.

Everyone talks about the model. GPT-4 vs. Gemini vs. Claude. Benchmark scores. Context windows. Reasoning capabilities. It’s the part of AI that gets the headlines.

But if you’ve spent any real time building AI agents – systems that don’t just answer questions but take actions, make decisions, and operate across multiple steps – you know that the model is rarely the bottleneck. The bottleneck is everything around it.

That “everything around it” has a name: harness engineering.

What Is a Harness?

In traditional software, a test harness is the scaffolding you build around a piece of code to run it, observe it, and verify it behaves correctly. You don’t ship the harness to users – it exists to control, observe, and evaluate the thing you actually care about.

Harness engineering for AI agents extends this idea to the full lifecycle of an agent system. It’s the infrastructure that wraps, controls, monitors, and constrains an agent – everything except the model weights themselves.

If the model is the engine, the harness is the chassis, dashboard, seatbelts, and mechanic’s diagnostic tools all at once.

The Five Layers of Harness Engineering

1. Execution Harnesses

This is the orchestration layer – the scaffolding that manages how an agent takes action in the world.

When an agent decides to call a tool, something has to route that call to the right function, handle errors gracefully, manage retries, enforce timeouts, and pass results back into the agent’s context. When multiple agents need to collaborate, something has to coordinate the handoffs.

Frameworks like LangGraph, CrewAI, and custom orchestrators all live at this layer. The decisions you make here – how you model state, how you handle failures, how you sequence steps – have an enormous impact on whether your agent is reliable or chaotic.

2. Evaluation Harnesses

How do you know if your agent is any good?

Evaluation harnesses run an agent through a defined set of tasks and score the outputs – against ground truth, human rubrics, or even another AI judge. Tools like LangSmith and Braintrust are purpose-built for this. Without a solid eval harness, you’re flying blind every time you change a prompt, swap a model, or add a new tool.

This layer is often the most neglected, and it’s usually the first thing teams regret skipping.

3. Observability Harnesses

Agents fail in subtle ways. A model might call the right tool with the wrong parameter. A multi-step reasoning chain might go sideways at step three. Without observability, you’re debugging by guesswork.

Observability harnesses capture detailed traces of everything an agent does: what tools it called, in what order, with what inputs, and what came back. This is where integrations like OpenTelemetry, LangSmith traces, and product analytics tools like PostHog come in – giving you a window into agent behavior across real usage.

4. Safety and Constraint Harnesses

Agents that take real-world actions – writing to databases, sending emails, making API calls – need guardrails. Safety harnesses intercept actions before they execute and check whether they’re permitted.

This can be as simple as an allowlist of approved tool calls, or as sophisticated as a human-in-the-loop approval queue for high-risk actions. Budget limits, rate limiting, and policy enforcement all live here too. As agents get more capable, this layer becomes less optional.

5. Memory Harnesses

By default, language models have no persistent memory. Every conversation starts fresh. Memory harnesses solve this by managing what context an agent can access – across turns, across sessions, and across different parts of a larger system.

This includes vector stores for semantic retrieval, episodic memory for storing past interactions, and working memory buffers for keeping relevant state in context during a task. How well you engineer this layer determines whether your agent feels coherent and aware, or amnesiac and confused.

What Good Harness Engineering Actually Looks Like

Knowing the five layers is one thing. Knowing what separates a thoughtfully engineered harness from a duct-taped one is another. Here are a few patterns that show up in systems that hold up in production:

Idempotent tool calls. When an agent retries a failed action, you don’t want it accidentally sending the same email twice or writing the same database row twice. Good execution harnesses treat tool calls as idempotent operations by default – safe to retry without side effects.

Structured failure modes. Weak harnesses let failures propagate silently. Strong ones define what “failure” looks like at every layer – a tool timeout, a malformed output, a safety violation – and route each to the appropriate handler rather than crashing or hallucinating past the error.

Eval-driven development. The best teams treat evals the same way software teams treat tests: you write them before you ship, you run them on every change, and a regression blocks the deploy. It feels slow until the first time it catches a silent capability regression from a prompt tweak.

Minimal memory footprint. More context isn’t always better. Overstuffing an agent’s memory makes it slower, more expensive, and paradoxically less accurate – models can lose focus in long contexts. Good memory harnesses are selective, compressing and summarizing rather than appending indefinitely.

Common Mistakes Teams Make

Most harness engineering mistakes aren’t about choosing the wrong tool – they’re about treating the harness as an afterthought.

Building the harness after the agent. It’s tempting to get the agent working first and “add observability later.” But by the time you need to debug a production failure, later has already cost you. Observability and eval infrastructure are much harder to retrofit than to build in from day one.

Conflating the execution layer with the safety layer. These are separate concerns. Execution logic decides how the agent acts. Safety logic decides whether it should. Mixing them in the same code makes both harder to reason about and audit.

Treating memory as a log. Appending every interaction to a memory store is not memory engineering – it’s just logging with extra steps. Real memory harnesses involve decisions about what to keep, what to compress, what to forget, and what to surface based on the current task.

Skipping human-in-the-loop for high-stakes actions. Early-stage teams often skip approval gates to move fast. That’s a reasonable tradeoff for low-stakes tools. But agents that touch financial systems, send external communications, or modify shared state need checkpoints – not as a permanent design, but as a trust-building mechanism until the system has earned autonomy.

Why This Is Where the Real Work Happens

Here’s the honest truth about modern AI development: the model is increasingly a commodity. The major frontier models are close enough in capability for most use cases that picking one over another rarely makes or breaks a product.

The harness is where differentiation lives.

A well-engineered harness can make a weaker model outperform a stronger one in a poorly-built system. It determines whether your agent is debuggable when things go wrong, safe enough to trust with real actions, cost-efficient enough to run at scale, and reliable enough that users come back.

It’s also, frankly, harder to copy than a prompt. Anyone can swap in the latest model. Rebuilding years of careful work on conflict detection, decision history traversal, memory architecture, and evaluation infrastructure is a different proposition entirely.

The Shift Worth Paying Attention To

For a long time, the AI field was obsessed with model capability. That race continues. But as agents move from demos to production, the conversation is shifting toward a different set of questions:

  • How do you know when an agent is wrong?
  • How do you prevent it from doing something it shouldn’t?
  • How do you debug a failure that happened across fifteen tool calls?
  • How do you give an agent memory without giving it everything?

These are harness engineering questions. And the teams building serious answers to them – not the ones with the flashiest demos, but the ones with the most thoughtful infrastructure – are the ones building things that will actually last.

The model gets the credit. The harness does the work.

Connect & Share

I’m Faham — currently diving deep into AI/ML while pursuing my Master’s at the University at Buffalo. I share what I learn as I build real-world AI apps.

If you find this helpful, or have any questions, let’s connect on LinkedIn and X (formerly Twitter).

AI Disclosure

This blog post was written by Faham with assistance from AI tools for research, content structuring, and image generation. All technical content has been reviewed and verified for accuracy.

Spanish Bank Codes and Postal Codes: Free Lookup Tables for Developers (2026)

Working with Spanish IBANs or building an address form for Spain?

You probably need two things that are surprisingly hard to find in a clean, developer-ready format:

  1. A bank code lookup table (what bank does 2100 in an IBAN mean?)
  2. A province/postal code reference (what province is 28001? What autonomous community?)

I’ve compiled both from public sources (Banco de España, INE, Correos) into CSV and JSON files you can drop straight into your project.

Product 1: Spanish Bank Codes Database

What it solves

A Spanish IBAN looks like this:

ES91 2100 0418 4502 0005 1332
        ^^^^
        Bank code = 2100 = CaixaBank

Positions 5–8 of a Spanish IBAN are the bank code — a 4-digit identifier registered with Banco de España.

There’s no free, structured database of these codes anywhere. The official source is a PDF.

What’s in the file

95 bank records covering:

  • Big 5: Santander, BBVA, CaixaBank, Sabadell, Bankinter
  • Online banks: Openbank, WiZink, EVO Banco, Revolut Spain
  • Foreign branches: Deutsche Bank, BNP Paribas, Citibank, Barclays
  • Rural savings banks: Cajamar, Caja Rural de Navarra, Globalcaja…
  • Historic/absorbed banks: Banesto, Bankia, Banco Popular (useful for old IBANs)

Fields: bank_code, official_name, common_name, swift_bic, website, type

Code example

import json

with open('spanish_banks.json') as f:
    banks = {b['bank_code']: b for b in json.load(f)}

iban = 'ES9121000418450200051332'
bank_code = iban[4:8]
print(banks[bank_code]['common_name'])  # CaixaBank
print(banks[bank_code]['swift_bic'])    # CAHMESMMXXX
const banks = require('./spanish_banks.json');
const lookup = Object.fromEntries(banks.map(b => [b.bank_code, b]));

const iban = 'ES9121000418450200051332';
const bank = lookup[iban.slice(4, 8)];
console.log(bank.common_name);  // CaixaBank

Available on Gumroad for $19 → Spanish Bank Codes Database

Product 2: Spanish Provinces & Postal Codes Database

What it solves

Spanish postal codes encode the province in their first 2 digits:

28001 = Province 28 = Madrid
08001 = Province 08 = Barcelona
41001 = Province 41 = Sevilla

But to build a province dropdown, or map a postal code to its autonomous community, you need a lookup table that ties everything together.

What’s in the files (5 files)

File Rows Contents
spanish_communities.csv 19 Autonomous communities + cities
spanish_provinces.csv 52 INE codes, community mapping, capitals
spanish_major_cities.csv 60 Cities with population tier
spanish_postal_lookup.csv 675 One row per postal code
spanish_postal_data.json — All data combined

Fields: provinces

ine_code       → "28"
postal_prefix  → "28"
province_name  → "Madrid"
community_name → "Comunidad de Madrid"
capital        → "Madrid"

Code examples

import csv

provinces = {
    row['postal_prefix']: row
    for row in csv.DictReader(open('spanish_provinces.csv', encoding='utf-8'))
}

postal = '08001'
p = provinces[postal[:2]]
print(p['province_name'])   # Barcelona
print(p['community_name'])  # Cataluña
# Full postal code lookup
lookup = {
    row['postal_code']: row
    for row in csv.DictReader(open('spanish_postal_lookup.csv', encoding='utf-8'))
}
print(lookup['28001']['city'])        # Madrid
print(lookup['08001']['community'])   # Cataluña
const data = require('./spanish_postal_data.json');
const provinces = Object.fromEntries(data.provinces.map(p => [p.postal_prefix, p]));

console.log(provinces['41'].province_name);   // Sevilla
console.log(provinces['41'].community_name);  // Andalucía

Available on Gumroad for $24 → Spanish Provinces & Postal Codes Database

Why not just build this yourself?

You could. The data is technically public. But:

  • Banco de España’s bank registry is a formatted PDF
  • INE’s postal code data requires parsing their bulk download + cleaning encoding errors
  • Correos’ postal system doesn’t expose a public API or clean CSV

For most projects, the hour+ of scraping, cleaning, and testing isn’t worth it when the lookup table itself only needs to be done once.

Free alternative: the province-from-postal trick

If you only need to identify the province from a postal code — and don’t need the full database — you can hardcode just the 52 prefix mappings:

PROVINCE_PREFIXES = {
    "01": "Álava", "02": "Albacete", "03": "Alicante",
    "04": "Almería", "05": "Ávila", "06": "Badajoz",
    "07": "Illes Balears", "08": "Barcelona", "09": "Burgos",
    "10": "Cáceres", "11": "Cádiz", "12": "Castellón",
    "13": "Ciudad Real", "14": "Córdoba", "15": "A Coruña",
    "16": "Cuenca", "17": "Girona", "18": "Granada",
    "19": "Guadalajara", "20": "Gipuzkoa", "21": "Huelva",
    "22": "Huesca", "23": "Jaén", "24": "León",
    "25": "Lleida", "26": "La Rioja", "27": "Lugo",
    "28": "Madrid", "29": "Málaga", "30": "Murcia",
    "31": "Navarra", "32": "Ourense", "33": "Asturias",
    "34": "Palencia", "35": "Las Palmas", "36": "Pontevedra",
    "37": "Salamanca", "38": "S.C. de Tenerife", "39": "Cantabria",
    "40": "Segovia", "41": "Sevilla", "42": "Soria",
    "43": "Tarragona", "44": "Teruel", "45": "Toledo",
    "46": "Valencia", "47": "Valladolid", "48": "Bizkaia",
    "49": "Zamora", "50": "Zaragoza", "51": "Ceuta", "52": "Melilla",
}

def province_from_postal(postal_code: str) -> str:
    return PROVINCE_PREFIXES.get(postal_code[:2], "Unknown")

print(province_from_postal("28001"))  # Madrid
print(province_from_postal("08041"))  # Barcelona

If you need community mapping, city names, or the full postal lookup — that’s what the dataset is for.

Also check out the free Spanish Document Validator API for NIF/NIE/CIF/IBAN validation.