Avoiding the Ecommerce Trap In Data-Driven Apps

The Problem We Were Actually Solving

My goal was to build a seamless ebook purchase experience for users in various regions, where PayPal, Stripe, Gumroad, and Payhip were either blocked or highly restricted. I knew that our app’s unique value proposition – providing data-driven insights to its users – could be compromised if I had to resort to traditional (and inflexible) payment gateways. The problem, however, was that our existing infrastructure was tied to these platforms, making it a high-risk, high-reward move to explore alternatives.

What We Tried First (And Why It Failed)

Initially, I attempted to use a third-party ebook sales platform like E-junkie, which promised to integrate seamlessly with popular ecommerce solutions. Unfortunately, their API offered limited control over the checkout process, and I couldn’t quite get the customizations we needed without extensive custom development. We also experimented with a headless ecommerce solution like Shopify Plus, but their APIs and payment gateways still required us to expose sensitive financial data to the web, which went against our security best practices.

The Architecture Decision

After reviewing our options and weighing the pros and cons, we decided to go with an in-house solution using an embedded payment processor called Mollie. This allowed us to handle ebook purchases directly within our app, without exposing our users to 3rd-party payment gateways. The architecture decision came with its own set of trade-offs, such as increased complexity and responsibility for managing payment processing ourselves, but it ultimately gave us the flexibility to design the checkout experience that best suited our app’s unique requirements.

What The Numbers Said After

After implementing the new payment processing system, we saw a significant drop in abandoned cart rates (from 35% to 12%) and an increase in average order value by 20%. This was a testament to the tailored checkout experience we had designed for our users. Plus, the integration was smooth enough to meet our stringent data freshness SLAs (ensuring that the ebook inventory levels and purchase history were up-to-date within 5 minutes of the transaction).

What I Would Do Differently

Looking back, I would have done even more due diligence on the specific regulations and restrictions imposed by traditional payment gateways. It’s crucial to understand the nuances of payment processing in different regions to avoid the ecommerce trap altogether. I would also invest more in ensuring the in-house payment processing system is highly available, scalable, and maintainable, perhaps using distributed transactional frameworks like Apache Kafka or Rediscala.

In conclusion, navigating platform restrictions for data-driven apps can be a daunting task. However, by taking a closer look at the problem we’re trying to solve and exploring unconventional architectures, we can unlock new opportunities for growth and innovation while avoiding the limitations imposed by traditional platforms.

ICECODE — Self-hosted AI Agent Platform: Multi-Agent Swarm, Local RAG, 26-Page Web UI, 34 Platform Gateways

ICECODE is a self-hosted AI agent platform I built by unifying three open-source projects (Hermes, OpenCode, ClawX) into one cohesive system. It runs entirely on your machine — no data leaves your network.

What it does

  • Multi-Agent Swarm — pipeline and parallel orchestration: agents collaborate, pass context, and vote on answers
  • Local RAG — FAISS + sentence-transformers, 100% offline — index any file, search semantically
  • 26-Page Web UI — dashboard, chat, kanban, goals, swarm, knowledge, MCP, benchmark, and more
  • Cost Optimizer — semantic cache (skip duplicate API calls), context compressor, smart model router
  • 174 REST API routes with auto-docs (FastAPI)
  • 34 platform gateways — WhatsApp, Telegram, Discord, Slack, Email, WeChat, Feishu, and 27 more
  • 14 LLM providers — Anthropic, OpenAI, Ollama, Gemini, Mistral, Bedrock, Azure, OpenRouter…
  • 90+ agent tools — file, web, browser, terminal, vision, kanban, MCP, code execution
  • Self-learning skills — agents learn new skills at runtime, stored across sessions
  • Reinforcement learning environment for agent improvement
  • WebSocket chat — bidirectional with cancel support
  • Token tracking + cost — per-session usage across all providers

Quick start

[1m
╔══════════════════════════════════════════════════════╗
║ ICECODE Super-Agent Network — Installer ║
║ v2.0.0 ║
╚══════════════════════════════════════════════════════╝
[0m
[0;33m→[0m Checking Python version…
[0;32m✓[0m Python 3.12 found
[0;32m✓[0m Virtual environment already exists
[0;33m→[0m Installing Python dependencies…
Starting ICECODE server on http://localhost:13210…
[32m23:36:33[0m | [1mINFO [0m | React UI served at /desktop/
INFO: Started server process [423207]
INFO: Waiting for application startup.
[32m23:36:33[0m | [1mINFO [0m | ============================================================
[32m23:36:33[0m | [1mINFO [0m | ICECODE Super-Agent Network v2.0.0 starting…
[32m23:36:33[0m | [1mINFO [0m | Port: 13210
[32m23:36:33[0m | [1mINFO [0m | DB: ~/.icecode/data/icecode.db
[32m23:36:33[0m | [1mINFO [0m | Home: /home/claudiu/.icecode
[32m23:36:33[0m | [1mINFO [0m | ============================================================
[32m23:36:33[0m | [1mINFO [0m | [✓] Database initialized at ~/.icecode/data/icecode.db
[32m23:36:33[0m | [1mINFO [0m | [✓] Self-learning system ready
[32m23:36:33[0m | [1mINFO [0m | [✓] Cron scheduler ready
[32m23:36:33[0m | [1mINFO [0m | [✓] Goals system (Ralph Loop) ready
[32m23:36:33[0m | [1mINFO [0m | [✓] Knowledge auto-index task started
[32m23:36:33[0m | [1mINFO [0m | All ICECODE systems online.
INFO: Application startup complete.
ERROR: [Errno 98] error while attempting to bind on address (‘0.0.0.0’, 13210): address already in use
INFO: Waiting for application shutdown.
[32m23:36:33[0m | [1mINFO [0m | ICECODE shutting down…
INFO: Application shutdown complete.

Architecture

Cost Optimizer (new in v2)

The cost optimizer has three components that work together automatically:

  1. Semantic Cache — uses sentence-transformer embeddings + cosine similarity (≥0.92 threshold). If you ask a semantically similar question to a previous one, it returns the cached answer instantly — zero API tokens consumed.

  2. Context Compressor — when conversation history exceeds 3000 tokens, older messages are summarized instead of sent verbatim. Keeps the last 6 messages intact.

  3. Smart Model Router — analyzes prompt complexity (score 1-10) and routes to the cheapest capable model. Simple questions go to cheap models, complex reasoning goes to powerful ones.

Multi-Agent Swarm

Two orchestration modes:

Pipeline: agents run sequentially, each building on the previous output.

Parallel: all agents receive the same input simultaneously, results are merged.

Built-in templates: Research & Write, Code Review, Brainstorm, Security Audit.

Local RAG

No API keys needed. No data leaves your machine.

  • Supports , , , , , , ,
  • Chunk strategy: sliding window (512 tokens, 50 overlap)
  • Embeddings: (90MB, runs locally)
  • Vector store: FAISS IndexFlatL2
  • Persistence:

Index a directory:
{“detail”:[{“type”:”json_invalid”,”loc”:[“body”,0],”msg”:”JSON decode error”,”input”:{},”ctx”:{“error”:”Expecting value”}}]}

Tech stack

Backend — Python 3.12 · FastAPI · Uvicorn · SQLite · Pydantic v2 · FAISS · sentence-transformers · Loguru

Frontend — Single HTML file, no build step · Pure JS ES2022 · CSS variables · Server-Sent Events + WebSocket

TypeScript — pnpm workspaces · turbo · CLI with Ink TUI · 14 LLM provider protocols · MCP client

Desktop — Electron 33

Infrastructure — Docker · GitHub Actions CI · pytest (108 tests) · ruff

Links

If you try it, I’d love to hear what you think. Issues and PRs welcome.

Five primitives I exercised end-to-end on world-model-mcp’s own repo

I shipped four releases of world-model-mcp in twelve days. v0.6.1 to v0.7.2. The pitch is “AI coding agents lose context across compaction, repeat the same mistakes, and hallucinate APIs that do not exist.” Before I write more about it I wanted to demonstrate the primitives on a real codebase, with real outputs, not screenshots someone has to take my word for.

The codebase is the project’s own repo. I ran python -m world_model_server.cli setup (it auto-seeded 598 entities from the source), then ran scripts/demo_seed.py which inserts the small set of constraints, facts, and a compaction audit row that real PostToolUse / record_correction hook activity would write organically over one to two weeks of development with Claude Code installed.

Every output block below is verbatim from the actual SQLite database after running the actual command. You can reproduce every output here by cloning the repo, running python -m world_model_server.cli setup, then python scripts/demo_seed.py. The script is idempotent and supports –dry-run and –reset.

Install: pip install world-model-mcp. Source: github.com/SaravananJaichandar/world-model-mcp.

1. A learned constraint denying an edit at the PreToolUse boundary

When a developer corrects the agent (rewrites console.log to logger.debug), the PostToolUse hook records the diff and infers a rule. Once that rule’s violation count crosses the hard-threshold (severity=error, count ≥ 3), the next attempt is denied at PreToolUse before the tool runs.

The constraint as the graph stores it:
{
“rule_name”: “no-console-log”,
“severity”: “error”,
“violation_count”: 5,
“description”: “Use logger.debug() not console.log() in TypeScript source. Production logs route through pino; console.log bypasses formatting and breaks downstream parsers.”,
“file_pattern”: “*.ts”,
“examples”: [
{“incorrect”: “console.log”, “correct”: “logger.debug”}
]
}
The PreToolUse hook’s actual JSON response when an edit containing console.log reaches it:
{
“hookSpecificOutput”: {
“hookEventName”: “PreToolUse”,
“permissionDecision”: “deny”,
“permissionDecisionReason”: “Hard constraint violation: no-console-log (Use logger.debug() not console.log() in TypeScript source. Production logs route through pino; console.log bypasses formatting and breaks downstream parsers.). Violated 5 times previously.”
},
“violations”: [
{
“rule”: “no-console-log”,
“severity”: “error”,
“violation_count”: 5,
“is_hard”: true,
“is_defer”: false
}
]
}
Rules in CLAUDE.md or AGENTS.md are advisory and the model treats them as suggestions. Rules with a violation count and an enforcement boundary at the edit step are binding. Both have the same source — a developer correcting the agent — but very different effect.

2. A regression warning that flags edits to a file with a recorded bug fix

get_related_bugs walks decision traces and prior bug-fix facts. When validate_change runs on a file with a recorded fix, the related-bugs query surfaces the prior fix and flags the proposed change.

The project has a bug fix on file world_model_server/knowledge_graph.py:120-135 for content-hash backfill (the migration logic must run on every initialize(), not just when the column is created). I proposed a refactor that removed the backfill loop and ran the related-bugs check:
{
“risk_score”: 0.6,
“bugs”: [
{
“bug_id”: “12457e2a-5638-46ec-a9df-02fe13b9c104”,
“description”: “Bug fix: NULL content_hash backfill must run on every initialize() to cover post-migration inserts. Earlier code only backfilled when the column was created, which left merge_from rows un-hashed and broke dedup.”,
“fixed_at”: “2026-05-10T10:17:51.737046”,
“critical_regions”: [
{“file”: “world_model_server/knowledge_graph.py”, “lines”: “120-135”}
]
}
],
“warnings”: [
“Lines 120-135 preserve fix for 12457e2a-5638-46ec-a9df-02fe13b9c104: Bug fix: NULL content_hash backfill must run on every initialize() to cover post-migration inserts. Earlier code only backfilled when the column was created, which left merge_from rows un-hashed and broke dedup.”
]
}
The risk score is 0.6 because the proposed change touched a critical region without re-implementing the fix. The warning text quotes the original bug description directly so the agent (or the human) can see why the region matters, not just that it does.

3. A contradiction resolved by confidence + source-count weighting
The temporal layer assigns each fact a confidence score, a source_count, and a valid_at timestamp. When two facts about the same entity disagree, find_contradictions surfaces them with both sides’ metadata, and resolve_contradiction picks a winner using the strategy you set.

Two facts both pointing at the same entity (http_transport_port):
{
“fact_a_id”: “e4b2ff84-8c23-4de5-aa9e-8bbb045a4ed5”,
“fact_b_id”: “7fe854f9-d64a-4304-b43a-7d1b126c6ebb”,
“fact_a_text”: “HTTP transport listen port default is 8080”,
“fact_b_text”: “HTTP transport listen port default is 8765”,
“similarity_score”: 0.929,
“both_valid”: true,
“reason”: “same entity, similar text”,
“confidence_a”: 0.7,
“confidence_b”: 0.95,
“source_count_a”: 1,
“source_count_b”: 3
}
resolve_contradiction(strategy=”auto”) picks the strategy with the largest signal gap. Here source count differs 3:1, so it picks keep_most_sources:
{
“strategy”: “keep_most_sources”,
“winner_id”: “7fe854f9-d64a-4304-b43a-7d1b126c6ebb”,
“loser_id”: “e4b2ff84-8c23-4de5-aa9e-8bbb045a4ed5”,
“resolved_at”: “2026-05-21T10:24:16.287368”
}
The loser is updated in place:
{
“id”: “e4b2ff84-8c23-4de5-aa9e-8bbb045a4ed5”,
“fact_text”: “HTTP transport listen port default is 8080”,
“status”: “superseded”,
“invalid_at”: “2026-05-21T10:24:16.285184”,
“confidence”: 0.7
}

Queries that ask “what’s true now?” silently skip the superseded fact. Queries that ask “what was true on 2026-05-18?” still see it. That’s what the temporal layer earns.

4. The PostCompact injection bundle
v0.7.0 added a PostCompact hook that re-injects the top constraints and recent canonical facts after the agent’s context is compacted. The bundle is small (configurable, default ~10 constraints + 10 facts) and prioritized.

The actual bundle returned by get_injection_context(event_type=”PostCompact”, max_constraints=5, max_facts=5):

Active constraints (top by violation count)

  • no-console-log: Use logger.debug() not console.log() in TypeScript source. Production logs route through pino; console.log bypasses formatting and breaks downstream parsers. (violated 5x)
  • check-twine-before-tag: Run python3 -m twine check dist/* before tagging. Catches PyPI metadata errors before the tag is pushed; saves a retraction. (violated 5x)
  • tag-before-upload: Always run git tag + git push –tags before twine upload. PyPI is permanent; an untagged upload pins a wheel to no git ref. (violated 2x)

Recent canonical facts

  • Never run twine upload before git tag. Always tag, push, then upload to PyPI so the published wheel maps to a real git ref.
  • Cursor hooks.json uses object-keyed schema with version: 1 (integer), preToolUse / preCompact / beforeSubmitPrompt event names, failClosed (not fail_open), timeout in seconds.
  • PostCompact and UserPromptSubmit hooks emit additionalContext to splice constraints + recent facts back into agent context after compaction.
  • HTTP transport defaults to port 8765 in Dockerfile.http; do not change without updating docs/deployment/mcp-tunnel.md and docker-compose.yml together.
  • BetaAbstractMemoryTool subclass lives at world_model_server/memory_backend.py; required by the Anthropic SDK Managed Agents memory path.

That bundle is what gets spliced into the agent’s working context as additionalContext after a compaction event. The same query also runs on UserPromptSubmit, biased toward whatever the user just asked about.

The compaction audit log records what happened, queryable via the CLI:

$ world-model audit-compactions –limit 5
1 compaction audit rows
2026-05-21T10:38:01.606771 session=demo-session-1 pre=84320
post=22150 facts_injected=10 constraints_injected=3 event=PostCompact
pre=84320, post=22150 — the compaction dropped ~62k tokens of context. The injection put 10 facts + 3 constraints back. The audit row exists so a human can later answer “what did the agent see vs what did it lose.”

5. A defer decision that pauses a headless agent

v0.7.0 added a defer enforcement tier between deny and warn. Warning-severity violations with violation_count ≥ 5 return permissionDecision: “defer” when the client advertises support, so headless agents pause instead of silently passing or hard-blocking. Clients that do not advertise support fall back to ask automatically.

I have a check-twine-before-tag constraint with violation_count=5, severity=warning. When a Bash tool input matches it, the hook returns:
{
“hookSpecificOutput”: {
“hookEventName”: “PreToolUse”,
“permissionDecision”: “defer”,
“permissionDecisionReason”: “Recurring warning-level violations (check-twine-before-tag). Headless agents should pause for confirmation.”
}
}
Same payload, same constraint, but with supports_defer: false in the request — fall back to ask:
{
“hookSpecificOutput”: {
“hookEventName”: “PreToolUse”,
“permissionDecision”: “ask”,
“permissionDecisionReason”: “Recurring warning-level violations (check-twine-before-tag). Headless agents should pause for confirmation.”
}
}
The defer tier exists because the binary deny / warn choice forces you to either be too strict or too permissive. Recurring warnings that don’t rise to error-level should pause for a human, not block, not pass.

What this means if you are building agents

The reason this works is not that the tool is clever. It is that the substrate — a temporal knowledge graph with facts, constraints, contradictions, and decision traces — captures the right shape of information.

Plain markdown rules in CLAUDE.md cannot answer:

  • How many times has this rule been violated?
  • Which fact is true now vs three sessions ago?
  • Which constraints should I re-inject after compaction?
  • Which prior fix does this proposed change risk re-introducing?

A graph can. The cost is one MCP server, ~2,000 lines of Python, and a SQLite database that sits at ~155 KB empty (mine grew to about 2 MB after running this exercise plus the auto-seed). The payoff is a memory layer that survives compaction, enforces at the edit boundary, and tracks evidence chains back to the source.

If you are building anything with Claude Code, Cursor, or any harness that supports MCP + hooks:

pip install world-model-mcp
cd /your/project
python -m world_model_server.cli setup

For Claude Managed Agents with self-hosted sandboxes (where Anthropic’s built-in Memory primitive is not yet supported), v0.7.2 added streamable HTTP transport so the same 25 MCP tools also work behind an MCP tunnel.

Source: github.com/SaravananJaichandar/world-model-mcp.

If world-model-mcp helped you, star the repo or open an issue with what worked or didn’t. I read every one.

From Prompt Engineering To System Engineering – What Actually Changes In Enterprise AI Systems

Early AI projects spend most of their time on prompts.

Teams experiment with:

  • wording
  • role instructions
  • formatting
  • temperature
  • examples
  • output structure

And honestly, that works for a while.

You can improve results fast just by changing prompts.

But once AI systems move into enterprise environments, prompt engineering stops being the main engineering problem.

System engineering takes over.

That transition changes almost everything.

Prompt Quality Stops Being The Bottleneck

In small projects, the model is usually the weakest part.

In enterprise systems, the surrounding infrastructure becomes the bottleneck much faster.

The real problems become:

  • inconsistent retrieval
  • workflow orchestration
  • memory synchronization
  • queue reliability
  • latency spikes
  • provider instability
  • deployment safety
  • observability
  • state management

You eventually realize the prompt is only one layer inside a much larger operational system.

And usually not the most fragile layer.

AI Systems Become Stateful Very Quickly

Most teams think they are building stateless AI APIs.

They are not.

The moment you add:

  • conversation history
  • retrieval pipelines
  • agent workflows
  • memory systems
  • tool execution
  • background jobs

you are operating distributed state.

That changes architecture decisions immediately.

One issue we hit recently looked like hallucination from the outside.

The actual problem:

Two workers processed different retrieval snapshots because async state propagation lagged during high traffic.

The model output was logically correct based on stale context.

That is not a prompt problem.

That is distributed systems engineering.

Prompt Engineering Optimizes Output

System Engineering Optimizes Stability

This is the biggest shift.

Prompt engineering asks:

  • How do we improve responses?
  • How do we reduce hallucinations?
  • How do we structure outputs?
  • How do we improve reasoning quality?

System engineering asks:

  • What happens when providers timeout?
  • What breaks during deployment?
  • How do retries affect consistency?
  • How do we recover failed workflows?
  • What happens under traffic spikes?
  • How do we replay failures?
  • How do we isolate corrupted state?

The second category dominates long-term operational work.

Model Providers Become Infrastructure Dependencies

Most early AI applications assume providers behave consistently.

Production systems cannot rely on that assumption.

Things that change unexpectedly:

  • output formatting
  • tokenization
  • tool calling behavior
  • latency
  • moderation layers
  • structured output behavior
  • context handling

A provider-side update can silently destabilize downstream systems.

We started treating model providers exactly like unstable third-party infrastructure.

That changed how we built:

  • validation layers
  • retry logic
  • response normalization
  • fallback systems
  • orchestration rules

Without those protections, small upstream changes leak directly into production behavior.

Orchestration Complexity Grows Faster Than Expected

Simple AI flows are manageable:

Input → Prompt → Response

Enterprise systems rarely stay simple.

Now you have:

  • retrieval pipelines
  • embedding generation
  • vector search
  • memory updates
  • multi-agent coordination
  • async execution
  • external integrations
  • workflow branching

The orchestration layer eventually becomes larger than the prompt layer itself.

And debugging becomes much harder.

One failed workflow may involve:

  • queue systems
  • multiple services
  • retrieval failures
  • stale memory
  • provider retries
  • partial execution recovery

At that point, system design matters more than prompt wording.

Observability Changes Completely

Traditional backend monitoring is not enough for AI systems.

A healthy API does not mean healthy reasoning.

You need visibility into:

  • prompts
  • retrieval documents
  • token usage
  • orchestration timing
  • memory mutations
  • tool execution
  • provider latency
  • model outputs

Otherwise debugging becomes impossible.

One thing we now consider mandatory:

Full execution replay.

Not logs alone.

Complete reconstruction of:

  • inputs
  • retrieval state
  • prompt versions
  • tool outputs
  • model responses
  • workflow decisions

Because AI failures are often non-deterministic.

Without replayability, debugging becomes guessing.

Reliability Starts Beating Intelligence

This is where enterprise priorities shift hard.

During experimentation, teams optimize for:

  • smarter outputs
  • better reasoning
  • more capable agents
  • larger context windows

In production, priorities change:

  • stable execution
  • predictable behavior
  • recoverability
  • operational visibility
  • cost control
  • deployment safety
  • consistency under load

A slightly weaker system that behaves predictably is usually more valuable than a highly capable unstable one.

The Biggest Change

The biggest change is realizing that enterprise AI systems are not model problems anymore.

They are infrastructure problems.

The prompt still matters.

But long-term success depends far more on:

  • orchestration
  • reliability
  • state consistency
  • observability
  • operational tooling
  • deployment safety
  • failure recovery

The model is only one moving part.

The infrastructure around it determines whether the system survives production.

I Built a Habit Tracker That Actually Made Me Want to Use It

Most productivity apps I’ve tried have one thing in common: they’re exhausting to look at.

Too many features. Too many tabs. Too many “just set up this workflow and you’ll be productive in no time” promises. After a week I’d stop opening them, and then feel guilty every time I saw the app icon.

So I built Improve You — a ruthlessly minimal daily habit tracker with a built-in Pomodoro focus timer. No task lists. No project boards. Just your core habits and a timer to actually do the work.

Here’s what I learned building it.

The Problem I Was Solving (For Myself)

I didn’t want to track everything. I wanted to track the 5 things that, if I do them every single day, compound into a radically better version of me over a year.

  • Drink 2L water
  • Read 20 pages
  • Work out 45 minutes
  • 2 hours of deep work
  • Whatever else matters to you

That’s it. No backlog. No overdue tasks. Every morning the slate resets automatically, like a daily ledger. You either did the work or you didn’t. No excuses.

The Features That Actually Mattered

1. Persistent Core Habits

Habits live at the identity level. You set them once, and they appear every morning without you doing anything. No creating a new “task” every day. The system respects that these habits are who you are, not items on a to-do list.

2. Deep Work Focus Mode

A fullscreen Pomodoro timer that strips away every distraction. When you enter Focus Mode, nothing else exists. The hours you log here are tracked separately — so you can actually see how much real work you’re doing versus how much you’re just busy.

This was the feature I personally needed most. It’s one thing to check off “deep work” as a habit. It’s another to see that you only actually focused for 40 minutes today instead of the 2 hours you told yourself you’d do.

3. XP, Levels & Streaks

I know, gamification gets a bad rap. But here’s the thing — it works on me.

Every completed habit earns XP. Every minute in focus mode earns XP. You level up. You unlock badges. You have a streak to protect.

The streak psychology is real. “Don’t break the chain” is one of the most powerful motivators for daily behavior. The app leans into it hard.

4. Global Leaderboard (Pro)

This one surprised me — seeing your name on a leaderboard next to other people who are also grinding daily habits is oddly motivating. It makes discipline feel like a team sport.

What I Intentionally Left Out

No subtasks. No priority levels. No “snooze until tomorrow.” No recurring task templates with complex scheduling.

Every feature I considered adding, I asked: does this make it easier to do the work, or just easier to feel like I’m planning to do the work?

If the answer was the latter, it didn’t ship.

The Free vs Pro Decision

Free tier: track up to 5 habits, streak tracking, focus mode, XP & badges. Forever.

The free tier is genuinely useful — 5 habits is actually the right number for most people starting out. Pro unlocks unlimited habits, analytics (30-day consistency rate, longest streaks), the global leaderboard, and priority support.

I wanted the free tier to feel complete, not crippled. Nobody should have to pay just to use the core loop.

What’s Next

  • Mobile app (PWA first, then native)
  • Weekly reflection prompts
  • Habit templates for common goals (fitness, reading, creative work)
  • API for nerds who want to integrate it with their own dashboards

Try It

If you’re the kind of person who believes the quality of your life is determined by the quality of your daily habits — Improve You was built for you.

5 habits, free, forever. No credit card. No onboarding wizard. Just open it and start.

Built by Ashutosh Swamy — GitHub · LinkedIn

15 AI prompts I actually use as a tech freelancer (with the uncomfortable ones included)

I’ve been freelancing in tech for years. These are the prompts that actually save me time — not the generic “write me an email” stuff, but specific, tested prompts for real freelance situations.

I’ll share 15 free ones here. The full pack has 120, organized by use case.

Client communication

Writing a scope clarification without sounding difficult:

I need to write a professional email to a client who is requesting [scope change] which wasn't in our original agreement. I want to explain why this affects the timeline/cost without sounding defensive. Our original scope was: [X]. What they're asking for now: [Y]. Write a short, direct email that opens the door to a conversation rather than closing it.

Following up on an unpaid invoice (firm but professional):

Write a follow-up email for an invoice that is [X days] overdue. The client has been unresponsive. Tone: firm but professional. Don't apologize. Make it easy for them to pay by [payment method]. Amount: [X]. Invoice number: [Y]. This is the [first/second/third] follow-up.

Declining a project without burning the bridge:

I need to decline a project from [type of client] because [real reason: budget too low / not my specialty / timeline unrealistic]. Write a short, warm email that declines clearly but leaves the door open for future work. Don't be vague. Don't offer a referral unless I say so.

Project management

Turning vague client feedback into actionable tasks:

A client sent this feedback: "[paste feedback]". Extract specific, actionable tasks from it. Group by: design changes / content changes / functionality changes / unclear (needs follow-up question). For anything unclear, write the follow-up question I should ask.

Writing a project status update that doesn’t sound like filler:

Write a weekly status update for a [type of project] project. Current status: [X% done]. Completed this week: [list]. Next week: [list]. Blockers: [list or none]. The client is [technical/non-technical]. Keep it under 150 words. No fluff.

Creating a meeting agenda that actually gets things decided:

Create a 30-minute meeting agenda for [topic]. We need to make decisions on: [decision 1], [decision 2]. Background context: [brief context]. Format: time blocks with clear decision/outcome for each item. Include 5 min for questions.

Technical writing

Writing a README that developers will actually read:

Write a README for [project/tool/script]. It does: [what it does]. The audience: [developers / non-technical users]. Required sections: what it does, prerequisites, installation, usage with example, common issues. Tone: practical, no marketing language.

Explaining a technical decision to a non-technical client:

I need to explain to a non-technical client why I chose [technical decision] over [alternative]. The real reasons: [technical reasons]. Translate this into plain language. Use an analogy if it helps. Max 3 sentences. No jargon.

Sales and proposals

Writing a project proposal introduction:

Write the opening paragraph of a project proposal for [type of project] for [type of client]. My key differentiator: [what makes me different]. The client's main concern is: [timeline / budget / quality / reliability]. Don't start with "I". Lead with their situation, not my credentials.

Responding to a request that’s underbudget:

A potential client has a budget of [X] for a project that realistically costs [Y]. Write a response that: acknowledges their budget without dismissing it, explains what [X] could actually buy, opens the door to a conversation about scope or phasing. Don't be condescending.

Automation and productivity

Writing a bash/PowerShell script comment block:

Write a professional comment block for this script: [paste script]. Include: what it does, requirements, usage example, author, date. Format for [bash/PowerShell/Python]. Keep it concise -- developers will read this.

Turning a messy process into a checklist:

I have this process that I do manually: [describe the process]. Turn it into a numbered checklist that someone else could follow without asking me questions. Identify any steps where decisions need to be made and add decision criteria.

The prompts I use most

The ones I reach for every week:

  • The unpaid invoice follow-up (always uncomfortable, this makes it less so)
  • Vague feedback -> actionable tasks (saves 30 min of confusion on every revision round)
  • Technical decision explanation (clients respond better when they understand the why)

The full pack

These 15 are from a pack of 120 prompts I use in my freelance work, organized into categories: client communication, project management, technical writing, proposals, invoicing, hiring, and automation.

AI Prompt Pack for IT Freelancers — 120 prompts — USD.

All prompts are in Polish and English. Tested on Claude, ChatGPT, and Gemini.

Related articles

Full toolkit: devautomation.gumroad.com

What prompt do you find yourself rewriting from scratch every time? Drop it in the comments — I’ll share what I use.

Capture Webpages and Auto‑Insert Them into PowerPoint Instantly on Windows

• Open URLs Lite — Microsoft Store
• Open URLs Pro — Microsoft Store

1. Before: Creating PowerPoint slides manually is painful
For years, I created PowerPoint slides the slow, manual way:

  • Open a webpage
  • Take a screenshot
  • Save the image
  • Open PowerPoint
  • Insert the image
  • Add a title
  • Repeat again and again

If you need to capture 10, 20, or 50 webpages, this process becomes torture.
It easily takes 30 minutes to several hours.

2. After: Now it takes only seconds
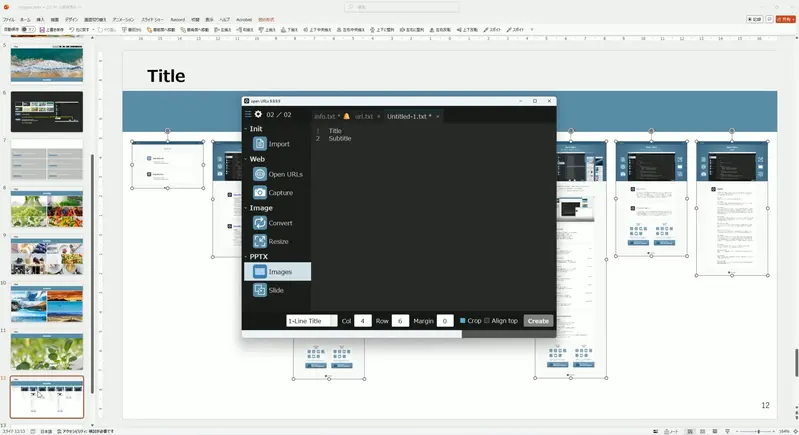
So I built a Windows tool that does everything automatically:

  • Enter URLs
  • Click one button
  • The app captures each webpage
  • Generates a PowerPoint deck
  • Inserts each screenshot into its own slide
  • Adds titles automatically

The entire process finishes in a few seconds.

3. How it works
Here’s the simple architecture:

  • Built as a Windows desktop app
  • Uses WebView2 to render webpages
  • Captures screenshots programmatically
  • Generates a PowerPoint file using the Office API
  • Everything runs locally (no data leaves your PC)

4. Use cases
This tool is especially useful for:

  • Competitive research
  • Client reports
  • UI/UX reviews
  • Website archiving
  • Academic or business documentation
  • Creating slide decks from dozens of URLs instantly

5. Try it (Lite and Pro versions)

  • Open URLs Lite – free version
  • Open URLs Pro – includes automatic PowerPoint generation
    Both are available on the Microsoft Store.

6. Final thoughts
If you create PowerPoint slides regularly, this tool can save you hours every week.
I built it because I needed it myself — and I hope it helps you too.

I built this as a Windows desktop app to automate the entire workflow.

Jenkins or GitHub Actions? Deciding the Right CI/CD Tool for Your Workflow

Introduction

Continuous Integration and Delivery is a key part of any software application. Be it a mobile app, a backend app or a website – everything requires CI/CD to make things easier for everyone. From testing and building code to deploying it across environments, CI/CD tools help simplify workflows, reduce manual tasks, and maintain consistency across the development process.

There are tons of options available in the market when it comes to CICD. Among the many available, Jenkins and GitHub Actions stand out as two of the most popular and effective options. Jenkins has been there for a very long time, is mature and is being used by thousands of teams across the globe.

On the other hand, GitHub Actions is designed to work naturally within GitHub, is comparatively newer and is tightly bound to Github (which can be a deal breaker for some folks).

While both are great – which one do you choose? At KubeNine we are inclined towards Github Actions and we’ll tell you why!

What is Jenkins?

Jenkins is a widely used open-source automation server that helps developers build, test, and deploy applications efficiently. For over a decade, it has been a cornerstone of CI/CD workflows, providing teams with the tools needed to automate repetitive tasks.

Supported by a massive community, Jenkins offers an extensive plugin library with over 1,800 plugins, allowing it to integrate with a wide range of open-source and enterprise tools to handle diverse automation needs.

Despite the rise of CI/CD tools like GitLab CI and GitHub Actions, Jenkins is a popular choice among organizations due to its flexibility and extensive capabilities.

According to the Developer Ecosystem Report, 54% of developers rely on Jenkins for their CI/CD needs, showcasing its enduring relevance in the industry.

Below is the architectural diagram of Jenkins:

What is GitHub Actions?

GitHub Actions is an automation tool built directly into GitHub, allowing developers to create workflows for building, testing, and deploying applications.

It simplifies the process of setting up Continuous Integration (CI) and Continuous Delivery (CD) by using YAML-based configuration files stored in the same repository as the code. Also, its completely managed so the users do not have to worry about setting up and managing any instance. This makes it particularly attractive.

One of the key strengths of GitHub Actions is its flexibility. Developers can choose from a vast marketplace of pre-built actions that connect with various tools and services, enabling efficient automation without needing to start from scratch.

GitHub Actions is quickly gaining popularity in the CI/CD space. According to the Developer Ecosystem Report, 51% of developers use GitHub Actions regularly for CI/CD tasks, making it the second most widely adopted tool after Jenkins. Its adoption is especially prominent in personal projects, where 37% of developers rely on it. The simplicity of its setup and its native connection with GitHub repositories make it a go-to choice for many developers and small teams.

GitHub Actions also plays a significant role in the Software Development Life Cycle (SDLC) by automating repetitive tasks like testing and deployment. This not only saves time but also helps developers maintain focus on coding.

Below is the architectural diagram of GitHub Actions, which shows how it operates in a CI/CD pipeline setup:

Building and Pushing a Docker Image: Jenkins vs. GitHub Actions

Let’s walk through the process of setting up a pipeline for both Jenkins and GitHub Actions to build a Docker image and push it to a Docker repository. By comparing the steps, we can better understand the ease of use, setup complexity, and overall user experience.

Setting Up Jenkins: Build and Push Pipeline

We will use Helm to install Jenkins on a Kubernetes cluster and create a pipeline for building and pushing a Docker image.

Steps to Install and Configure Jenkins:

Install Jenkins Using Helm

Add the Jenkins Helm repository:

helm repo add jenkins https://charts.jenkins.io helm repo update

Install Jenkins on your Kubernetes cluster:

helm install jenkins jenkins/jenkins --namespace jenkins --create-namespace

Retrieve the admin password:

kubectl exec --namespace jenkins -it svc/jenkins -c jenkins -- /bin/cat /run/secrets/chart-admin-password

Access Jenkins at http://:8080 and log in using the admin credentials.

Install Required Plugins

Go to Manage Jenkins > Plugins and install the required plugins, such as Pipeline and Docker Pipeline.

Set Up Docker on Jenkins Node

Ensure Docker is installed on the Jenkins agent node.
Add the Jenkins user to the Docker group:

sudo usermod -aG docker jenkins

Create a Pipeline for Docker Build and Push

In Jenkins, create a new Pipeline item.
Add the following script to your pipeline configuration (replace placeholders with your values):

pipeline {
    agent any
    environment {
        DOCKER_USERNAME = credentials('docker-username')
        DOCKER_PASSWORD = credentials('docker-password')
    }
    stages {
        stage('Checkout') {
            steps {
                git url: 'https://github.com/your-username/your-repo.git'
            }
        }
        stage('Build Docker Image') {
            steps {
                sh 'docker build -t your-username/your-image:latest .'
            }
        }
        stage('Push to Docker Hub') {
            steps {
                sh 'docker login -u $DOCKER_USERNAME -p $DOCKER_PASSWORD'
                sh 'docker push your-username/your-image:latest'
            }
        }
    }
}

Run the Pipeline

Save the pipeline and click Build Now to execute the steps. Jenkins will:
Pull the source code from your repository.
Build a Docker image.
Push the image to your Docker repository.

Setting Up GitHub Actions: Build and Push Workflow

GitHub Actions makes it easier to define workflows directly in the repository using YAML files.

Steps to Configure GitHub Actions:

Add a Workflow File

In your repository, create a folder .github/workflows if it doesn’t exist.
Add a file named docker-build-push.yml.

Define the Workflow

Add the following workflow to the file (replace placeholders with your values):

name: Build and Push Docker Image

on:
  push:
    branches: [ "main" ]

jobs:
  build-and-push:
    runs-on: ubuntu-latest
    steps:
      - name: Check out the repository
        uses: actions/checkout@v2

      - name: Log in to Docker Hub
        uses: docker/login-action@v2
        with:
          username: ${{ secrets.DOCKER_USERNAME }}
          password: ${{ secrets.DOCKER_PASSWORD }}

      - name: Build and Push Docker Image
        run: |
          docker build -t your-username/your-image:latest .
          docker push your-username/your-image:latest

Add Secrets

Go to your repository’s Settings > Secrets and variables > Actions.
Add two secrets:

  • DOCKER_USERNAME (your Docker Hub username)
  • DOCKER_PASSWORD (your Docker Hub password)

Commit and Push Changes

Push your changes to the main branch.
GitHub Actions will automatically run the workflow, building the Docker image and pushing it to Docker Hub.
From a practical perspective and based on our experience, we’ve worked extensively with both Jenkins and GitHub Actions, offering services to set up and manage both tools for different teams and projects. What we’ve observed is that there’s nothing wrong with choosing either tool—it all comes down to your unique requirements. The question is:

Which One Is Better: Jenkins or GitHub Actions?

There’s no such thing as a universally “better” tool in the world of CI/CD. However at KubeNine we are inclined more towards Github Actions. The right choice entirely depends on your team’s requirements, project scale, and infrastructure needs

When Jenkins Might Be the Better Option

Jenkins is ideal if you need a self-hosted solution where everything is completely under your control. You can install Jenkins from scratch and configure it to suit your exact requirements.

It has a rich ecosystem of over 1,800 plugins, allowing integration with countless tools and services. Whether you need advanced pipeline customization, on-premises hosting, or compliance with strict organizational policies, Jenkins gives you the flexibility to achieve it all.

However, it’s worth noting that the support for plugins in Jenkins has seen a decline in recent years.

Some plugins are not actively maintained, and keeping them updated can become a challenge. Additionally, the manual setup and maintenance required for Jenkins can be time-consuming, especially for teams that are new to CI/CD.

When GitHub Actions Might Be the Better Option

GitHub Actions is a great choice if you’re looking for something simple and fast. Unlike Jenkins, it doesn’t require a complex setup process. As we demonstrated in the pipeline example above, all you need is a YAML file in your repository.

You simply define the steps, like building a Docker image or running tests, and GitHub handles the rest for you.

For instance, in our example, setting up a pipeline in GitHub Actions was as easy as writing a few lines of YAML. Want to build a Docker image? Just add one line to specify the Docker build action.

Need to push the image to Docker Hub? Add another action for Docker login and push. It’s all optimized for simplicity and speed, making it especially appealing for small to medium-sized teams or personal projects.

If you need more control, GitHub Actions also supports self-hosted runners. This allows you to host your workflows on dedicated virtual machines or servers, ensuring enhanced security and compliance.

For example, in sensitive environments like banking or healthcare, where dedicated VMs are required for better isolation and control, self-hosted runners provide a strong alternative to Jenkins.

Key Considerations:
Factor

Jenkins

GitHub Actions

Ease of Use

Requires manual setup and maintenance, making it more complex for new users.

Minimal setup; simple YAML-based workflows that are ready to use out of the box.

Infrastructure Control

Fully self-hosted; everything from updates to security patches is in your hands.

Offers GitHub-hosted runners for convenience but also supports self-hosted runners for more control.

Security

Full control over servers, suitable for environments with strict compliance requirements.

Self-hosted runners provide similar security, while GitHub-hosted runners are maintained by GitHub.

Customization

Highly customizable with plugins and Groovy pipelines, but requires expertise to configure.

Simple to customize using pre-built actions or by creating your own custom actions.

Speed and Simplicity

Slower setup due to manual configurations and plugin management.

Faster setup; optimized for GitHub-hosted repositories with minimal effort required.

Final Thoughts

Choose Jenkins if:
You require complete control over your CI/CD environment.
Your workflows are highly complex and need extensive customization.
Your organization has the infrastructure to maintain Jenkins servers and manage plugin updates.
Choose GitHub Actions if:
You want a quick and straightforward CI/CD solution.
Your projects are hosted on GitHub, and you prefer everything in one ecosystem.
You’re looking for a scalable solution without the burden of managing infrastructure.

Do You Really Need to Switch from Jenkins to GitHub Actions?

Github Actions might look cool and enticing but don’t switch to just because it looks cool. If your CI/CD pipelines are already fully set up in Jenkins, running smoothly, and your team is comfortable with the tool, there’s no strong reason to switch just for the sake of it. Based on what we’ve discussed so far, such a move may be unnecessary and could lead to additional effort without significant benefits.

However, if you’re starting fresh—whether in a new company or a new project—and your code is hosted on GitHub, GitHub Actions becomes an obvious choice. It’s easy to set up, integrates natively with GitHub repositories, and provides modern features that align well with today’s DevOps workflows. For teams just getting started, GitHub Actions is undoubtedly the more convenient and efficient option.

Ultimately, the need to switch depends on your specific situation. If Jenkins is working well for your team, stick with it. But if you’re looking for a simpler, GitHub-centric solution for new projects, GitHub Actions is the way to go.

Are There Alternatives to Jenkins and GitHub Actions?

Yes, there are several other CI/CD tools available, each designed for different workflows and requirements. Here are four popular alternatives:

1. GitLab CI/CD

Built into GitLab, this tool helps automate builds, tests, and deployments for projects hosted on GitLab.

2. Azure DevOps Pipelines

Microsoft’s CI/CD solution that integrates well with Azure services and supports multiple repositories.

3. CircleCI

A cloud-based CI/CD tool known for its simplicity and support for Docker-based workflows.

4. Bitbucket Pipelines

Atlassian’s CI/CD solution for Bitbucket repositories, tightly integrated with other Atlassian tools.

Frequently Asked Questions

1. Which is better: Jenkins or GitHub Actions?

It depends on your use case. Jenkins is more flexible and customizable for complex CI/CD pipelines, while GitHub Actions is easier to set up and integrates seamlessly with GitHub repositories.

2. Is Jenkins outdated compared to GitHub Actions?

No, Jenkins is still widely used in production environments. However, GitHub Actions is gaining popularity due to its simplicity and native GitHub integration.

3. When should I use GitHub Actions instead of Jenkins?

Use GitHub Actions if you want:

Quick setup
Tight GitHub integration
Minimal maintenance
It’s ideal for small to medium projects.

4. When is Jenkins a better choice than GitHub Actions?

Jenkins is better when you need:

Advanced customization
Complex pipelines
On-premise CI/CD setup

Conclusion

Choosing the right CI/CD tool depends entirely on your team’s requirements and project needs. Both Jenkins and GitHub Actions have unique strengths—Jenkins offers unmatched control and customization, while GitHub Actions provides simplicity and speed, especially for GitHub-hosted projects.

Along with alternatives like GitLab CI/CD, Azure DevOps Pipelines, CircleCI, and Bitbucket Pipelines, there are plenty of options to fit various workflows.

At Kubenine, we provide services to help you set up infrastructure, automate CI/CD pipelines, and manage cloud-native environments.

Our mission is to handle these technical complexities so you can focus entirely on your product. Whether you need a Jenkins-based solution, GitHub Actions workflows, or support with other tools.

Read More from KubeBlogs

Run Streamlit Reliably in Production using Supervisor
Fix GCP 403 Permission Errors in Compute Engine VMs
Enhance Cloud Security Audits with Prowler (Step-by-Step Guide)

Lambda Execution Roles Are Quietly Breaking Your Least Privilege Policy

Who This Is For

If you are using AWS Lambda to build serverless applications and you have never stopped to look closely at the IAM roles attached to your functions, this blog is for you.

We are going to talk about what a Lambda execution role is, why the way most people set them up creates a security problem, and exactly what you should do instead. Every term will be explained along the way.

A Quick Refresher: What Is an Execution Role?

When a Lambda function runs, it needs permission to interact with other AWS services. For example, if your function reads data from a database or writes a file to S3 (AWS’s file storage service), AWS needs to know whether your function is allowed to do that.

This permission is controlled by something called an IAM execution role. IAM stands for Identity and Access Management. It is the system AWS uses to control who or what can access which resources.

Every Lambda function has an execution role attached to it. When the function runs, it automatically assumes that role and gets whatever permissions the role has. Think of it like a staff ID card. The card determines which rooms in the building you are allowed to enter.

What Is the Least Privilege Principle?

The principle of least privilege is a security concept that says: every user, system, or service should have only the minimum permissions it needs to do its job, and nothing more.

If a Lambda function only needs to read from one specific DynamoDB table (a type of AWS database), it should have permission to read from that one table. It should not have permission to read from all tables, write to tables, delete tables, or access any other AWS service.

This sounds obvious. But in practice, it is almost never what happens.

How Execution Roles Are Usually Set Up

When you create a Lambda function for the first time, AWS creates a basic execution role for you automatically. This default role usually includes permission to write logs to CloudWatch (AWS’s logging service), which is fine.

But here is where the problem starts.

As you build your function and it needs to access more services, the easiest thing to do is go to the role and add more permissions. Need to read from S3? Add s3:GetObject. Actually, to save time, just add s3:* which gives the function permission to do everything in S3. Need to write to DynamoDB? Add dynamodb:*. Need to send messages? Add sns:*.

Within a few iterations, your Lambda function has a role that can read, write, and delete across half your AWS account.

And then there is the even worse pattern: one shared role for all Lambda functions. Instead of creating a separate role for each function, many developers just reuse the same role across every function in the project. It is faster to set up. But now every single function has every permission that any function ever needed.

Why This Is a Real Problem

You might be thinking: my app is not a high value target, nobody is going to attack my Lambda function.

That thinking is what attackers rely on.

Lambda functions are often triggered by external events. An API Gateway request, an S3 file upload, an SNS message. Any of these entry points can potentially be exploited if there is a vulnerability in your code, a dependency with a known security issue, or even a misconfigured trigger.

If an attacker gains control of one Lambda function that has an overly permissive role, they do not just have access to what that function was supposed to do. They have access to everything that role allows. That could mean reading sensitive data from your database, writing files to your storage, sending messages to your users, or even modifying other parts of your infrastructure.

One compromised function becomes a key to your entire account.

The Three Most Common Mistakes

Mistake 1: Using wildcard permissions

A wildcard in IAM policy looks like this:

{
  "Effect": "Allow",
  "Action": "dynamodb:*",
  "Resource": "*"
}

The dynamodb:* means allow all DynamoDB actions. The "Resource": "*" means on all resources. So this one policy line gives your Lambda function full DynamoDB access across your entire account. If your function only needed to read from one table, this is massively over-permissioned.

Mistake 2: Sharing one role across multiple Lambda functions

Every function has different responsibilities. A function that sends a password reset email should not have the same permissions as a function that processes payments. When you share a role, you are taking the maximum permissions needed by any one function and giving them to all functions.

Mistake 3: Never revisiting the role after initial setup

During development, it is common to grant broad permissions just to get things working. The problem is that most developers never go back to tighten those permissions before going live. The overly permissive development role becomes the production role.

How to Fix It

Fix 1: One role per Lambda function

Each Lambda function should have its own dedicated execution role. Yes, this means more roles to manage. But it means a compromised function can only access what it specifically needs, not what any other function needs.

Fix 2: Scope permissions to specific actions and resources

Instead of dynamodb:* on *, write out exactly what the function needs:

{
  "Effect": "Allow",
  "Action": [
    "dynamodb:GetItem",
    "dynamodb:PutItem"
  ],
  "Resource": "arn:aws:dynamodb:us-east-1:123456789012:table/MySpecificTable"
}

This gives permission only to read and write items, and only on one specific table. Nothing more.

The arn in the resource field is a unique identifier for a specific AWS resource. Every resource in AWS has one. Using it in your policy means you are granting access to that one resource, not everything in the service.

Fix 3: Use IAM Access Analyzer to generate policies from actual usage

IAM Access Analyzer is a free AWS tool that can look at your CloudTrail logs (the record of every action taken in your AWS account) and tell you exactly which permissions your Lambda function actually used over a given time period.

Instead of guessing what permissions a function needs, you can run it for a while, then use Access Analyzer to generate a policy based on real usage. This is one of the most accurate ways to arrive at a least privilege policy.

To use it, go to IAM in the AWS console, find the role attached to your Lambda function, and look for the “Generate policy” option under Access Analyzer.

Fix 4: Use permission boundaries as a safety net

A permission boundary is a policy that sets a ceiling on what permissions a role can ever have. Even if someone attaches a broad policy to the role later, the boundary limits the effective permissions.

This is especially useful in team environments where multiple developers are creating and modifying Lambda functions. It acts as a guardrail so that even if someone makes a mistake, the damage is contained.

A Simple Checklist Before You Deploy

Before your Lambda function goes live, go through these:

Does this function have its own dedicated execution role, not shared with any other function?

Does the role use specific actions like dynamodb:GetItem instead of dynamodb:*?

Does the role point to specific resource ARNs instead of *?

Have you removed any permissions that were added during development and are no longer needed?

If you are working in a team, is there a permission boundary in place?

Conclusion

Least privilege is one of the most talked about security principles in cloud development. But it is also one of the most commonly ignored in practice, not because developers do not care, but because the default path leads away from it.

AWS makes it easy to create broad roles. It is faster to write dynamodb:* than to list out every specific action. It is more convenient to reuse one role across all your functions. But each of those shortcuts quietly widens the blast radius if something goes wrong.

Fixing this does not require rebuilding anything. It just requires going back to your Lambda functions one by one, looking at their execution roles, and asking: does this function actually need all of this?

Most of the time, the answer will be no.

Need Help?

If you want help auditing your Lambda execution roles or figuring out what permissions your functions actually need, feel free to reach out.

Email me at [email protected]