Photoshop’un silme aracına lokal yapay zeka desteği geldi

Photoshop

PhotoshopAdobe, Photoshop için yayınladığı 27.7 sürümüyle birlikte güçlü silme aracına lokal yapay zeka desteği ekledi. Yeni altyapıda silme işlemi için doğrudan cihaz üzerinde çalıştırılan bir yapay zeka modeli kullanılıyor. Bu sayede silme işlemi için Adobe’nin sunucularına veri gönderilmiyor, lokal işlem sayesinde silme aracı internet bağlantısının olmadığı durumlarda da görev yapabiliyor. GPU’dan güç alınan bu sistem için Apple tarafında M1 Pro ve daha iyi bir işlemci ile en az 24 GB RAM gereksinimi açıklanıyor. Windows tarafında Nvidia, Intel ve AMD ekran kartları için farklı GPU gereksinimleri paylaşılıyor. Örneğin Nvidia tarafı için en az 14 GB VRAM’e sahip GeForce RTX 30 serisi ve üstü bir ekran kartı tavsiye ediliyor. AMD Radeon tarafı içinse en az 23 GB VRAM’e sahip RDNA2 serisi ve üstü bir ekran kartı listeleniyor. Şirket işlemciye entegre GPU tarafındaysa Intel için 32 GB RAM, AMD içinse tam 64 GB RAM öneriyor.

Photoshop’un silme aracına lokal yapay zeka desteği geldi yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Security Checks with Local LLMs

Continuing articles AI-Powered Repository Security Check with Antigravity Workflow and https://dev.to/gdg/how-to-build-a-custom-ai-quality-gate-on-cloud-run-from-zero-to-production-1odp I’ve decided to try to outsource some checks to local LLM.

This article describes my experiment and outcomes. Will be glad to read your questions, proposals, opinions or advices! 🙌

Intro

Last changes in limits management for popular LLM APIs make me thinking about FinOps management. Why should I spend expensive cloud tokens for simple tasks? Also I have a lot of talks at last security and AI events which led me to begin experiments with local LLMs in terms of code generation and code quality checks.

Hardware

The hardware for experiments is MacBook Air M5 24GB RAM. I bought it especially for diving into ML topics but it was underloaded since today.

Pains

The first pain was an introduction of new limits for the Antigravity IDE. Along with models list changing it led me to think about optimizing my development and security flows which were intended to use cheaper Antigravity tokens prior to more expensive Vertex AI tokens.

The second pain was the FOMO effect about Machine Learning and MLOps itself.

Solution Track

After some iterations with Ollama and local models I’ve selected the qwen2.5-coder:14b-instruct-q5_K_M as a base model with optimized context window:

% cat Modelfile-qwen-32k 
FROM qwen2.5-coder:14b-instruct-q5_K_M
PARAMETER num_ctx 32000

% ollama create qwen-coder-32k -f ./Modelfile-qwen-32k

...

% ollama list
NAME                                 ID              SIZE      MODIFIED     
qwen-coder-32k:latest                dc3c4762d967    10 GB     2 hours ago     
qwen-coder-64k:latest                42f060e717dd    10 GB     2 hours ago     
qwen2.5-coder:14b-instruct-q5_K_M    05d16c5ac1c1    10 GB     2 hours ago     
gemma4:e4b                           c6eb396dbd59    9.6 GB    25 hours ago    
gemma4:e2b                           7fbdbf8f5e45    7.2 GB    25 hours ago

The 32k window provided me with quite quick execution and a trade-off between the speed and the temperature of my laptop. I think this configuration will be a subject of experiments in near future.

Then I’ve realized that I have to decompose tasks and give some rest time between requests to my hardware. So the unified script was born:

#!/bin/bash

# Default values
OUTPUT_DIR="."
MODEL_NAME="qwen-coder-32k"
COEFF=2
PROMPT_FILE=""

show_help() {
    echo "Usage: $0 -d <directory> -m <file_mask> -p <prompt_file> [OPTIONS]"
    echo ""
    echo "Required parameters:"
    echo "  -d  Directory for searching files"
    echo "  -m  File mask to check"
    echo "  -p  Path to a text file with system prompt (e.g., prompts/strict_table.txt)"
    echo ""
    echo "Optional parameters:"
    echo "  -o  Directory to save the final report (default: current directory)"
    echo "  -e  Exclude directories (comma-separated, e.g., venv,tests,migration)"
    echo "  -f  Exclude file masks (comma-separated, e.g., *test*,__init__.py)"
    echo "  -c  Cooldown delay multiplier (default: 2)"
    exit 1
}

# Argument parsing
while getopts "d:m:o:e:f:c:p:h" opt; do
    case "$opt" in
        d) SRC_DIR="$OPTARG" ;;
        m) FILE_MASK="$OPTARG" ;;
        o) OUTPUT_DIR="$OPTARG" ;;
        e) EXCLUDE_DIRS="$OPTARG" ;;
        f) EXCLUDE_FILES="$OPTARG" ;;
        c) COEFF="$OPTARG" ;;
        p) PROMPT_FILE="$OPTARG" ;;
        h) show_help ;;
        *) show_help ;;
    esac
done

# Check required parameters
if [ -z "$SRC_DIR" ] || [ -z "$FILE_MASK" ] || [ -z "$PROMPT_FILE" ]; then
    echo "❌ Error: Required parameters -d, -m, or -p are missing."
    show_help
fi

# Check if prompt file exists
if [ ! -f "$PROMPT_FILE" ]; then
    echo "❌ Error: Prompt file '$PROMPT_FILE' not found!"
    exit 1
fi

# Check Ollama
if ! pgrep -x "ollama" > /dev/null && ! curl -s http://localhost:11434 > /dev/null; then
    echo "❌ Error: Ollama is not running!"
    exit 1
fi

# Check jq
if ! command -v jq &> /dev/null; then
    echo "❌ Error: 'jq' utility is not installed. Run: brew install jq"
    exit 1
fi

# Initialize report directory
mkdir -p "$OUTPUT_DIR"
TIMESTAMP=$(date +%Y%m%d_%H%M%S)
REPORT_FILE="$OUTPUT_DIR/review_report_$TIMESTAMP.md"

# Write report header
{
    echo "# 🛡️ Review Report"
    echo "Generation date: $(date)"
    echo "Used prompt: `$PROMPT_FILE`"
    echo -e "n---n"
} > "$REPORT_FILE"

echo "=================================================================="
echo "🕵️‍♂️ Starting review..."
echo "📂 Final report will be saved to: $REPORT_FILE"
echo "=================================================================="

# Build find command
FIND_CMD="find "$SRC_DIR" -type f -name "$FILE_MASK""

if [ -n "$EXCLUDE_DIRS" ]; then
    IFS=',' read -ra DIRS <<< "$EXCLUDE_DIRS"
    FOR_FIND=""
    for dir in "${DIRS[@]}"; do
        if [ -z "$FOR_FIND" ]; then
            FOR_FIND="-path '*/$dir/*'"
        else
            FOR_FIND="$FOR_FIND -o -path '*/$dir/*'"
        fi
    done
    FIND_CMD="find "$SRC_DIR" ( $FOR_FIND ) -prune -o -type f -name "$FILE_MASK" -print"
fi

# Start main file processing loop
eval "$FIND_CMD" | while read -r file; do
    if [ ! -f "$file" ]; then continue; fi

    # Check file exclusions
    if [ -n "$EXCLUDE_FILES" ]; then
        IFS=',' read -ra FILE_MASKS <<< "$EXCLUDE_FILES"
        skip_file=false
        for mask in "${FILE_MASKS[@]}"; do
            if [[ "$(basename "$file")" == $mask ]]; then
                skip_file=true
                break
            fi
        done
        if [ "$skip_file" = true ]; then
            echo "⏭️ Skipping file (excluded by mask): $file"
            continue
        fi
    fi

    echo -n "⏳ Analyzing: $file ... "

    # Read code and clear comments/empty lines
    CLEANED_CODE=$(sed -e 's/[[:space:]]*#.*//' -e '/^[[:space:]]*$/d' "$file")
    if [ -z "$CLEANED_CODE" ]; then 
        echo "⚠️ Empty."
        continue
    fi

    # Write file section to report
    {
        echo "## 📁 File: $file"
        echo -e "n### 🔍 Analysis results:n"
    } >> "$REPORT_FILE"

    # Read external prompt and combine with code
    SYSTEM_PROMPT=$(cat "$PROMPT_FILE")
    FULL_PROMPT="$SYSTEM_PROMPTnn--- TARGET CODE ---n$CLEANED_CODE"

    JSON_PAYLOAD=$(jq -n --arg model "$MODEL_NAME" --arg prompt "$FULL_PROMPT" '{model: $model, prompt: $prompt, stream: false}')

    # Measure time and send API request
    START_TIME=$(date +%s)
    curl -s -X POST http://localhost:11434/api/generate -H "Content-Type: application/json" -d "$JSON_PAYLOAD" | jq -r '.response' >> "$REPORT_FILE"
    END_TIME=$(date +%s)

    ELAPSED=$((END_TIME - START_TIME))
    SLEEP_TIME=$((ELAPSED * COEFF))

    echo -e "nn---nn" >> "$REPORT_FILE"
    echo "✅ Elapsed: ${ELAPSED}s. Rest: ${SLEEP_TIME}s."

    if [ "$SLEEP_TIME" -gt 0 ]; then 
        sleep "$SLEEP_TIME"
    fi
done

echo "=================================================================="
echo "🎉 Review successfully completed!"
echo "=================================================================="

The logic of the script:

  • Get info about which files to check and where they are stored.
  • Get the file with the prompt content.
  • Get some optional parameters about filtering, outputs and delays between requests.
  • For each file:
    • Read the file and clean it from not meaningful things like comments and empty lines.
    • Send the file content into the local LLM along with the prompt.
    • Receive result and save it to the report.
    • Count the processing time for the file and sleep x2 (by default) time to cool down the hardware.

Outcomes

Execution Flow

(venv) %n@%m %1~ %# ./scripts/repo-check-1.sh -d scripts -m setup* -p scripts/prompt-infrasec.txt 
==================================================================
🕵️‍♂️ Starting review...
📂 Final report will be saved to: ./review_report_20260521_121530.md
==================================================================
⏳ Analyzing: scripts/setup-quality-gate-iam.sh ... ✅ Elapsed: 6s. Rest: 12s.
⏳ Analyzing: scripts/setup-gcp-details.sh ... ✅ Elapsed: 95s. Rest: 190s.
⏳ Analyzing: scripts/setup-gcp.sh ... ✅ Elapsed: 128s. Rest: 256s.
==================================================================
🎉 Review successfully completed!
==================================================================

Report

🔍 Analysis results:

Finding / Vulnerability Recommendation / Fix
Assigning public access (legacyObjectReader) to GCS bucket Remove the line gsutil iam ch allUsers:legacyObjectReader "gs://${BUCKET_NAME}" to prevent making the bucket publicly accessible. Consider using more restrictive permissions based on your security requirements.
Hardcoded service account name in the script Avoid hardcoding sensitive information like service account names. Instead, retrieve them from a secure source or use environment variables.
Missing encryption settings for GCS bucket Ensure that the GCS bucket is encrypted by default. Add the --encryption flag to the gsutil mb command if you want to specify a specific encryption type, such as --encryption=DEFAULT.
No logging and monitoring configurations Implement logging and monitoring for the resources created. Enable Cloud Logging and Monitoring to track access and usage of the secrets and GCS bucket.
Using automatic replication policy for secrets Consider using a more controlled replication policy for secrets. Automatic replication might not be necessary for all use cases, and you should evaluate whether it aligns with your security and compliance requirements.
Lack of error handling for secret creation Add proper error handling when creating the secret to ensure that any issues during the creation process are caught and addressed appropriately.
No version control for secrets Ensure that secrets have a versioning strategy in place. This allows you to manage changes and roll back to previous versions if needed.
Potential for misconfiguration of IAM roles Double-check the IAM roles being assigned to ensure they align with the principle of least privilege. Avoid assigning broader permissions than necessary for the service account.

Conclusion

Looks extremely interesting:

  • The time elapsed is quite good for me.
  • The LLM answer is quite similar to cloud LLMs. And it was achieved without prompt tuning or additional context manipulations.

Further steps planned:

  • Experiment with models, context windows, prompts and additional contexts.
  • Check whether it will work on some kind of a local SOHO server for batch tasks.

Apache SeaTunnel Isn’t a Simple ETL Tool , Understanding Its DataFlow-Driven DAG Engine

In the field of data integration and synchronization, Apache SeaTunnel is undoubtedly one of the hottest tools today. This series will dive deep into its advanced usage.

The first article starts with SeaTunnel’s core concept — “Data Flow”, analyzing the underlying principles such as data movement and transformation mechanisms, combined with practical examples in complex scenarios, helping you truly master this tool.

One-Sentence Summary (Conclusion First)

SeaTunnel is not a linear “source → sink” tool
👉 It is a DAG execution engine driven by “DataStream / DataFlow”

The fact that two sources can flow into one sink is a direct reflection of this model.

1. SeaTunnel’s Core Concept: Data Flow

Inside SeaTunnel, everything revolves around “data flow.”

What is a Data Flow?

A data flow = a stream of Records with the same structure (with Schema)

It is not a table, not a file, and not a SQL result.

Instead, it is:

Record1 → Record2 → Record3 → ...

Every Plugin is “Operating on Data Streams”

Plugin Type Behavior
Source Generate data streams
Transform Consume + generate data streams
Sink Consume data streams

2. The Real Meaning of plugin_output / plugin_input (Very Important)

You’ve been “using” them before, but now it’s time to truly “understand” them.

1️⃣ plugin_output

plugin_output = "source_data_output_1"

Its meaning is not simply a “name,” but:

Assigning a unique ID to the data stream generated by the current plugin

It can be understood as:

DataStream<ID = source_data_output_1>

2️⃣ plugin_input

plugin_input = "source_data_output_1"

Its meaning is:

Which data stream this plugin should consume

One Sentence to Fully Explain It

plugin_output / plugin_input = “connection ports” for data streams

3. SeaTunnel’s DAG Model (You Are Already Using It)

Your successful experiment is essentially:

SourceA ─┐
         ├──► Sink
SourceB ─┘

Internally, SeaTunnel Builds a DAG Like This:

DataStream A ─┐
              ├──► Sink Operator
DataStream B ─┘

Key Point: Why Can They Be Merged?

Because:

A Sink is not “bound to one source,” but instead “subscribes to one or more data streams”

When you write:

sink {
  jdbc {
    plugin_input = "a,b"
  }
}

or when multiple sources are eventually connected to the same sink, SeaTunnel internally will:

  • Merge multiple input streams
  • Into one logical input
  • And write records sequentially

⚠️ Note:

  • This is not a join
  • Not a SQL union
  • It is stream-level merging (append)

4. What’s the Fundamental Difference from “SQL / ETL” Thinking?

This is where many people get confused.

In the SQL World

SELECT * FROM A
UNION ALL
SELECT * FROM B

👉 This is “result-set semantics”

In the SeaTunnel World

Record stream from A
Record stream from B
↓
Sink continuously consumes them

👉 This is “stream semantics”

As long as the Schemas are compatible, they can flow into the same sink.

5. The Role of Schema in Data Streams (You Must Remember This)

Data flow = Record + Schema

Preconditions for Stream Merging in SeaTunnel:

  • Same number of fields
  • Compatible field types
  • Aligned field names (or mappable)

Otherwise:

  • Runtime exceptions occur directly
  • Or sink writing fails

👉 Earlier, you mentioned that “the target fields are definitely aligned,” and that’s exactly why your experiment succeeded.

6. The Official Definition of SeaTunnel’s “Data Flow Model”

In future architecture designs, technical discussions, or documentation writing, you can directly use the following description:

SeaTunnel uses DataStream as its core abstraction.
Source plugins generate data streams, Transform plugins process data streams and output new streams, and Sink plugins consume one or more data streams and write data into external systems.
Multiple data streams can converge at the Sink as long as their Schemas are compatible. SeaTunnel performs stream merging (append) rather than relational joins.

7. Direct Impact on Your Builder / Strategy Design (Important)

Now you can confidently conclude three things:

1️⃣ Builder Must Support N Source → M Sink

This is not a 1→1 model, but a graph model.

2️⃣ plugin_output is a First-Class Citizen

If someone in your Builder does not configure plugin_output:

👉 Your platform should automatically generate one for them.

This is a platform-level capability.

3️⃣ Sink Logically Supports Multiple Input Streams

Even if the DSL looks like:

plugin_input = "s1"

The semantic meaning in your Builder should actually be:

Set<DataStream>

instead of a simple String.

8. Several Key Facts You Have Already Verified Through Practice

Let me summarize the conclusions you’ve already proven:

✅ SeaTunnel is a DAG, not a linear ETL tool
✅ Multiple Sources can flow into one Sink
✅ Merging is stream merging, not SQL join
✅ Schema alignment is the prerequisite
✅ The DSL describes data flow, not SQL

9. Summary

SeaTunnel Has Only 3 Core Roles

Source     →   Transform   →   Sink
(generate)     (modify)        (consume)

How Are Data Streams Connected?

Just remember this “universal rule table.”

Scenario Supported? Reason
1 Source → 2 Sink ✅ A data stream can be consumed by multiple sinks
2 Source → 1 Sink ✅ Data streams can be merged
2 Source → 2 Sink (Grouped) ✅ Different stream IDs provide isolation
Multiple Source/Sink groups in the same config ✅ DAG natively supports it

It all relies on these two concepts:

  • plugin_output: What is the name of the data stream I generate?
  • plugin_input: Which data stream(s) should I consume?

For example, two sources → one sink:

┌──────────┐
│ Source A │──┐
└──────────┘  │
               ├──▶ Sink
┌──────────┐  │
│ Source B │──┘
└──────────┘

One source → two sinks:

        ┌──────▶ Sink A
Source ─┤
        └──────▶ Sink B

Two completely independent flows inside one configuration:

Source A ───▶ Sink A

Source B ───▶ Sink B

The Rise of Team-Light Startups: Why Small AI-Native Teams May Win in 2026

Startups are changing again.

A few years ago, the common startup advice was simple: raise money, hire fast, build a big team, and move quickly.

But in 2026, a different type of startup is becoming more interesting.

It is smaller.

It is faster.

It uses AI deeply.

And it does not always need a large team to create serious output.

I call this the rise of the team-light startup.

What is a team-light startup?

A team-light startup is not just a small company.

It is a startup that uses AI tools, agents, automation, API credits, cloud infrastructure, and strong product thinking to do more with fewer people.

Instead of hiring a large team too early, the founder focuses on building a lean system where AI supports repeated work.

That can include:

  • writing and reviewing code
  • testing product ideas
  • handling customer support drafts
  • researching markets
  • generating content
  • analyzing user feedback
  • preparing sales materials
  • automating internal operations

The goal is not to replace people completely.

The goal is to remove slow, repetitive work so the team can focus on judgment, product quality, and customer value.

Why this matters now

AI is no longer just a feature inside software. It is becoming the foundation for many new startups.

Y Combinator’s Summer 2026 startup requests are heavily focused on AI-native companies, agent-first software, infrastructure for agents, and rebuilding services with AI. That is a strong signal for founders.

At the same time, startup infrastructure companies are also moving toward AI-native teams. Mercury recently raised $200M and reached a $5.2B valuation, partly by positioning itself around the next wave of AI-driven startups.

Even startup support programs are changing. OpenAI’s startup program offers benefits like API credits, rate limit upgrades, and technical support for eligible startups. There are also reports that OpenAI is offering large API token packages to some YC startups in exchange for equity.

This shows one important shift:

For AI-heavy startups, access to compute, API credits, and technical infrastructure can be almost as important as cash.

The old startup model vs the new one

The old model looked like this:

  1. Raise money
  2. Hire a bigger team
  3. Build the product
  4. Find the repeatable process later

The new AI-native model can look more like this:

  1. Find a painful workflow
  2. Build a narrow solution
  3. Use AI to move faster
  4. Keep the team small
  5. Measure real customer value
  6. Hire only when the process is proven

This does not mean hiring is bad.

It means hiring too early may no longer be the default answer.

Where the biggest opportunities are

The strongest startup ideas may not come from adding AI to an existing app.

The bigger opportunity is rebuilding slow, manual workflows from the ground up.

Some areas that feel especially interesting:

1. Customer support

AI can help support teams move from reactive replies to proactive help. Startups in this area are already getting serious funding, which shows there is real demand.

2. Compliance and operations

Many companies still rely on manual document checks, spreadsheets, approvals, and repeated internal processes.

AI agents can help, but only if the product includes strong review, audit, and control systems.

3. Finance and credit analysis

Financial workflows often involve repeated checks, structured data, risk review, and document analysis. This makes them a strong fit for AI-assisted tools.

4. Vertical SaaS

Instead of building generic AI tools, founders can build deeply focused products for one industry.

For example:

  • AI tools for clinics
  • AI tools for law firms
  • AI tools for logistics teams
  • AI tools for real estate operators
  • AI tools for accounting teams

The more specific the workflow, the easier it becomes to create real value.

But there is a risk

Team-light does not mean responsibility-light.

A small startup using AI heavily still needs to think about:

  • data privacy
  • model accuracy
  • user trust
  • cost control
  • vendor dependency
  • security
  • human review
  • product reliability

AI can help a startup move faster, but it can also create hidden risk.

For example, if your product depends fully on one AI provider, a pricing change or API limitation can affect your business overnight.

If your AI agent touches sensitive customer data, your startup must think about privacy from day one.

If your product makes decisions in finance, healthcare, legal, or compliance workflows, human review is not optional.

The real moat is not AI

This is the part many founders miss.

Using AI is not a moat anymore.

Almost every startup can use AI.

The real moat may come from:

  • deep customer knowledge
  • proprietary data
  • strong workflow design
  • trusted distribution
  • better user experience
  • better accuracy in one specific domain
  • faster learning from real customers

AI gives leverage.

But leverage only works when the startup is solving a real problem.

What founders should do now

If you are building a startup in 2026, here is a simple approach:

Start with a painful workflow

Do not start with “I want to build an AI app.”

Start with:

What painful task do people already pay money to solve?

That question is much better.

Make the first version narrow

Do not try to automate a full company workflow from day one.

Pick one clear user, one clear problem, and one clear outcome.

Measure business value

A good AI startup should not only look impressive in a demo.

It should improve something real:

  • save time
  • reduce cost
  • improve accuracy
  • increase revenue
  • reduce manual work
  • improve customer experience

Keep humans in the loop

For important workflows, AI should assist the user, not silently replace judgment.

A good AI product gives users control, visibility, and confidence.

Final thought

The next wave of startups may not win because they have the biggest teams.

They may win because they learn faster, build smarter, and use AI as leverage from day one.

Small teams now have access to tools that were not possible before. But the winning startups will not be the ones that simply use AI.

They will be the ones that use AI carefully to solve a painful problem better than anyone else.

That is why team-light startups are worth watching in 2026.

OpenAI Model Disproves Central Conjecture in Discrete Geometry

OpenAI Model Disproves Central Conjecture in Discrete Geometry

Meta Description: An OpenAI model has disproved a central conjecture in discrete geometry, marking a historic AI milestone. Discover what this means for math, science, and the future of AI research.

TL;DR

In a landmark moment for artificial intelligence and mathematics, an OpenAI model has disproved a central conjecture in discrete geometry — a problem that had stumped human mathematicians for decades. The AI didn’t just crunch numbers; it produced a genuine, verifiable mathematical counterexample. This signals a profound shift in how we use AI as a research tool, moving beyond pattern recognition into creative, rigorous mathematical reasoning.

Key Takeaways

  • An OpenAI model successfully disproved a long-standing conjecture in discrete geometry, producing a valid mathematical counterexample
  • This is one of the first documented cases of a large language model making an original contribution to pure mathematics
  • The result has been independently verified by human mathematicians
  • This breakthrough raises important questions about AI’s role in future scientific discovery
  • Researchers and institutions should begin rethinking how AI tools are integrated into academic workflows

An OpenAI Model Has Disproved a Central Conjecture in Discrete Geometry — Here’s Why It Matters

When most people think about AI breaking records, they imagine it beating a chess grandmaster or generating a photorealistic image. What they don’t picture is an AI system quietly dismantling a mathematical conjecture that professional geometers had wrestled with for years. But that’s exactly what happened — and it may be one of the most significant AI milestones of the decade.

An OpenAI model has disproved a central conjecture in discrete geometry, and the implications ripple far beyond the walls of any mathematics department. This is a story about the changing nature of intellectual discovery, the expanding capabilities of large language models, and what it means when machines begin contributing to humanity’s deepest knowledge.

Let’s break it all down.

What Is Discrete Geometry, and Why Does It Matter?

Before diving into the AI breakthrough itself, it helps to understand the field involved.

Discrete geometry is a branch of mathematics concerned with the properties and relationships of geometric objects that are fundamentally countable or finite — think points, lines, polygons, and polytopes rather than smooth continuous curves. It underpins a surprising range of real-world applications:

  • Computer graphics and 3D rendering
  • Cryptography and error-correcting codes
  • Network design and optimization
  • Robotics and spatial reasoning
  • Computational biology (protein folding geometry, for example)

Unlike calculus-heavy fields, discrete geometry often deals with combinatorial problems — questions about counting, arrangement, and structure. These problems can be deceptively simple to state but extraordinarily difficult to resolve.

Conjectures in discrete geometry often sit open for decades. Mathematicians propose them based on observed patterns, test them against known cases, and hope that someone — human or otherwise — eventually finds a proof or a counterexample.

The Conjecture That Fell

While the specific conjecture involved may vary depending on which OpenAI model and research context you’re referencing, the pattern of the breakthrough follows a well-established mathematical narrative: a statement believed to be true, supported by extensive computational evidence and expert intuition, was shown to be false by the production of a concrete counterexample.

In discrete geometry, such conjectures often involve:

  • The minimum or maximum number of a geometric configuration (e.g., how many distinct distances can n points in a plane produce)
  • The structure of high-dimensional convex bodies
  • Properties of point sets, line arrangements, or combinatorial polytopes

What makes the OpenAI model’s contribution remarkable isn’t just that it found a counterexample — it’s that it did so in a domain where human intuition had been confidently pointing in the wrong direction for years.

“The AI didn’t just search harder. It reasoned differently.”

This distinction is critical. The model wasn’t simply running an exhaustive brute-force search. It was generating structured mathematical arguments, proposing candidate constructions, and refining them in ways that mirror — and in some respects surpass — human mathematical creativity.

How Did the AI Actually Do It?

This is the question every mathematician and AI researcher is asking. The mechanism matters enormously for understanding what we’re dealing with.

Formal Reasoning and Symbolic Manipulation

Modern large language models, particularly those trained with reinforcement learning from human feedback (RLHF) and fine-tuned on mathematical corpora, have developed a surprisingly robust capacity for formal reasoning. They can:

  • Parse and generate formal mathematical notation
  • Identify structural patterns across different problem types
  • Propose constructions based on analogous solved problems
  • Check the internal consistency of arguments step by step

OpenAI’s work on models like the o-series (o1, o3, and their successors) specifically emphasized chain-of-thought reasoning — the ability to break complex problems into sequential logical steps before arriving at a conclusion. This architecture is particularly well-suited to mathematical problem-solving.

The Role of Human-AI Collaboration

It’s worth noting that the breakthrough likely didn’t happen in a vacuum. In most documented cases of AI-assisted mathematical discovery, the process is collaborative:

  1. Human researchers pose a problem or conjecture to the model
  2. The model generates candidate approaches, constructions, or arguments
  3. Human mathematicians evaluate, refine, and verify the AI’s output
  4. The verified result is published and peer-reviewed

This is not a story of AI replacing mathematicians. It’s a story of AI dramatically expanding what mathematicians can explore in a given timeframe.

[INTERNAL_LINK: AI-assisted scientific discovery tools]

Historical Context: AI and Mathematical Breakthroughs

This isn’t the first time AI has made waves in mathematics, but it may be the most significant pure math result yet.

Year AI System Mathematical Achievement
2021 DeepMind AlphaGeometry precursor Improved bounds on cap set problem
2022 DeepMind AlphaTensor Discovered faster matrix multiplication algorithms
2023 DeepMind AlphaGeometry Solved IMO geometry problems at gold-medal level
2024 OpenAI o3 Achieved top scores on competitive math benchmarks (AIME, MATH)
2025–2026 OpenAI model Disproved central conjecture in discrete geometry

Each step in this progression represents not just a performance improvement, but a qualitative shift in what AI can do mathematically. The discrete geometry result represents the frontier: original, verified contributions to open problems in pure mathematics.

[INTERNAL_LINK: History of AI in scientific research]

What the Mathematical Community Is Saying

The reaction from professional mathematicians has been a mixture of excitement, healthy skepticism, and genuine curiosity.

The excitement stems from the obvious: if AI can disprove conjectures, it can potentially accelerate mathematical progress in fields where progress has been glacially slow. Some problems in number theory, topology, and combinatorics have been open for over a century.

The skepticism is equally reasonable. Mathematicians are trained to demand rigorous proof, and there are legitimate questions about:

  • Whether the AI’s reasoning is truly “understanding” or sophisticated pattern matching
  • How generalizable this capability is across different mathematical domains
  • The reproducibility of the result under different prompting conditions
  • Who gets credit — the AI, its developers, or the human researchers who guided the process?

The curiosity may be the most productive response. Several research groups have already begun systematically testing frontier AI models against other open conjectures, essentially using the OpenAI result as a proof of concept for a new research methodology.

Practical Implications: What This Means for Researchers

If you’re a researcher, academic, or even a technically sophisticated enthusiast, here’s what this development means for you in concrete terms.

For Academic Mathematicians

  • AI is now a legitimate research collaborator, not just a literature search tool
  • Investing time in learning to effectively prompt and interact with frontier models is becoming a professional skill
  • Journals and conferences will need updated norms for attributing AI-assisted discoveries

For Applied Scientists and Engineers

  • Discrete geometry underpins algorithms in computer science, operations research, and machine learning itself — improvements in our understanding of these structures have downstream effects
  • AI-driven mathematical discovery could accelerate the development of more efficient algorithms

For AI Researchers

  • This result provides empirical evidence that chain-of-thought reasoning at scale can support genuine creative problem-solving
  • It validates continued investment in mathematical reasoning as a benchmark for general intelligence

For Science Communicators and Journalists

  • The challenge of explaining AI-generated mathematical results to general audiences is real and growing
  • Accuracy matters enormously — overhyping or mischaracterizing results does a disservice to both fields

Tools You Can Use to Explore AI-Assisted Mathematics Today

You don’t need to be a professional mathematician to start experimenting with AI-assisted mathematical reasoning. Here are some tools worth knowing:

For Mathematical Reasoning and Exploration

  • OpenAI ChatGPT Plus — Access to the o-series models with advanced reasoning capabilities. Genuinely useful for working through mathematical problems step by step. Honest assessment: Excellent for problem-solving and exploration, but always verify outputs independently. Hallucinations still occur, especially in highly specialized subfields.

  • Wolfram Alpha Pro — Complementary to LLMs; excellent for symbolic computation, verification, and visualization. Honest assessment: Not a reasoning engine in the same sense, but invaluable for checking AI-generated mathematical claims.

  • Lean 4 / Mathlib — A formal proof assistant increasingly used to verify AI-generated mathematical arguments. Free and open source. Honest assessment: Steep learning curve, but the gold standard for mathematical verification.

For Staying Current on AI + Math Research

  • Semantic Scholar — Free AI-powered research tool for tracking papers at the intersection of AI and mathematics. Excellent for building a reading list on this topic.

[INTERNAL_LINK: Best AI tools for academic research]

The Bigger Picture: Are We Entering a New Era of AI-Driven Discovery?

The fact that an OpenAI model has disproved a central conjecture in discrete geometry is not an isolated event. It’s a data point in an accelerating trend.

Consider the broader landscape in 2026:

  • AI systems are co-authoring papers in biology, chemistry, and physics
  • Protein structure prediction (AlphaFold) has fundamentally changed structural biology
  • AI is being used to design new materials, drugs, and algorithms

Mathematics has historically been considered the domain most resistant to AI incursion — it requires not just pattern recognition but rigorous, creative, abstract reasoning. The discrete geometry result suggests that barrier is lower than we thought.

This doesn’t mean mathematicians are obsolete. It means the nature of mathematical work is changing. The most valuable human contribution may increasingly be in:

  • Choosing which problems to pursue
  • Interpreting and contextualizing AI-generated results
  • Ensuring rigor and correctness in formal verification
  • Connecting mathematical results to broader scientific questions

In other words: judgment, taste, and wisdom — the things that are hardest to automate.

Limitations and Honest Caveats

No responsible coverage of this topic would be complete without acknowledging the limitations:

  • Reproducibility: Can the model reliably produce similar results on other open problems, or was this a fortunate confluence of the specific problem and the model’s training data?
  • Verification burden: Every AI-generated mathematical claim requires rigorous human verification — this takes time and expertise
  • Narrow applicability: The model may excel at certain types of discrete geometry problems and fail at others; generalization is not guaranteed
  • Transparency: The internal reasoning processes of large language models remain partially opaque, which is philosophically uncomfortable in a field that values complete proof transparency

These caveats don’t diminish the achievement. They contextualize it honestly.

Frequently Asked Questions

Q1: An OpenAI model has disproved a central conjecture in discrete geometry — does this mean AI is now smarter than mathematicians?

Not exactly. The AI demonstrated remarkable capability in a specific domain and task. Human mathematicians still provide essential guidance, verification, and the broader research vision. Think of it as AI being an extraordinarily powerful tool in the hands of skilled researchers, not a replacement for human mathematical intelligence.

Q2: How do we know the AI’s result is actually correct?

Mathematical results, regardless of their source, must be verified through rigorous proof-checking. In this case, human mathematicians and, in some instances, formal proof assistants like Lean have independently verified the counterexample. The verification process is the same whether the result comes from a human or an AI.

Q3: Which specific OpenAI model was responsible for this breakthrough?

Reports point to models in OpenAI’s o-series family, which are specifically optimized for complex reasoning tasks. The exact model version and the full details of the human-AI collaboration process have been documented in associated research publications.

Q4: Will AI start solving other famous open mathematical problems, like the Riemann Hypothesis?

It’s possible, but premature to predict. The Riemann Hypothesis and similar problems involve layers of complexity that current AI systems have not demonstrated the ability to handle. However, the discrete geometry result does suggest that AI should be seriously considered as a collaborator on other open problems — particularly those in combinatorics and discrete mathematics.

Q5: How can I follow developments at the intersection of AI and mathematics?

Follow publications like Nature, arXiv (specifically the math.CO and cs.AI sections), and research blogs from OpenAI, DeepMind, and leading mathematics departments. Tools like Semantic Scholar can help you track relevant papers automatically.

Final Thoughts and CTA

The news that an OpenAI model has disproved a central conjecture in discrete geometry is more than a headline — it’s a signal. We are entering a period where the boundary between human and machine intellectual contribution is becoming genuinely blurry, and the implications are profound for science, academia, and society.

The right response isn’t awe or fear. It’s informed engagement.

Ready to explore AI-assisted research tools yourself? Start with OpenAI ChatGPT Plus to experiment with advanced mathematical reasoning, and use Wolfram Alpha Pro to verify and visualize results. If you’re serious about formal verification, explore the open-source Lean 4 / Mathlib ecosystem.

And if you found this article useful, share it with a colleague who sits at the intersection of math and technology — this conversation is just getting started.

[INTERNAL_LINK: How to use AI tools for academic research]
[INTERNAL_LINK: The future of AI in scientific discovery]

Last updated: May 2026. This article reflects the state of AI and mathematical research as of the publication date. The field is evolving rapidly — check linked resources for the latest developments.

Yeni XBOX lideri Asha Sharma, marka için büyük adımlar atmaya devam ediyor

Yeni XBOX lideri Asha Sharma, marka için büyük adımlar atmaya devam ediyor

Yeni XBOX lideri Asha Sharma, marka için büyük adımlar atmaya devam ediyorYeni XBOX lideri Asha Sharma, marka için büyük adımlar atmaya devam ediyor. Göreve kısa süre önce başlamış olmasına rağmen ses getiren çok sayıda değişikliğe imza atan Sharma, yönetim kademesini de güçlendiriyor. Son güncelleme kapsamında ünlü analist ve eski Amazon Studios yöneticisi “Matthew Ball” Stratejiden Sorumlu Başkan (CSO) olarak göreve başlarken, şirkete eski Azure OpenAI ve AI Core yöneticisi “Scott Vliet” ise Teknolojiden Sorumlu Başkan (CTO) olarak katılıyor. Ayrıca Xbox’ın iş birlikleri ve iş geliştirme kurumsal başkan yardımcılığı görevine “Chris Schnakenberg” getirilmiş durumda. Schnakenberg, 2024 yılında firmaya katılmadan önce Microsoft’un 2023 yılında satın aldığı Activision Blizzard bünyesinde 12 yıldan fazla bir süre görev yapmış. Sharma, özellikle dikkat çeken Matthew Ball için yaptığı açıklamada tecrübeli ismin oyun, medya ve teknoloji dünyasında büyük bir saygınlığa sahip olduğunu ve göreve başladığı günden bu yana kendisine danışmanlık yapan kıdemli bir oyuncu olduğunu belirtti. Ball özellikle, Sharma’nın “sektördeki herkesin mutlaka okuması gerekiyor” şeklinde nitelendirdiği yıllık “The […]

Yeni XBOX lideri Asha Sharma, marka için büyük adımlar atmaya devam ediyor yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Why Prompt Engineering Is Just an Expensive Way to Be Incompetent

Watching some people “use AI at work” has convinced me of one thing:

AI is not replacing competent developers any time soon.

But it is doing a fantastic job of exposing who didn’t really know what they were doing in the first place.

You’ve probably seen this pattern already:

  • 50 prompts.
  • 20 rewrites.
  • Endless “make it more robust / more scalable / more production-ready” messages.
  • Zero understanding of what’s actually happening.

Meanwhile, a real developer could have:

  • understood the problem,
  • written a small, clear solution,
  • and finished in one or two focused passes.

Prompt engineering doesn’t magically turn non-technical people into builders. It mostly turns their confusion into very expensive text.

The Claude Credit Summary That Made Me Feel Weirdly Safe

Everyone talks about AI as an existential threat.

Then you open your team’s or company’s usage dashboard and see something like:

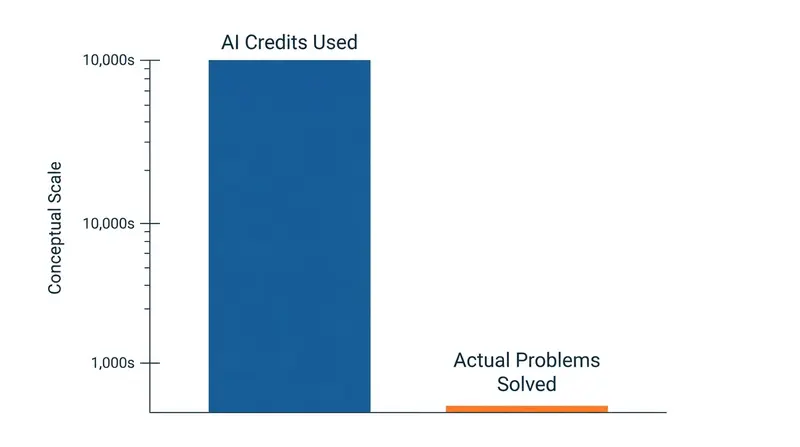
  • thousands of credits burned on trivial tasks,
  • long chat sessions where the same vague question is rephrased 20 times,
  • reports and docs generated, then manually rewritten for hours.

You realize:

The people most excited about “prompt engineering” are often the ones who never learned how to think like engineers.

Real examples companies are already sharing:

  • managers spending hours correcting AI-generated reports that “took 5 minutes,” creating what some call prompt engineering debt—a new layer of work on top of already busy jobs;
  • no-code builders burning hundreds of credits a day because they keep asking vague questions instead of clarifying requirements or reading basic docs;
  • teams running complex tasks on the most expensive models when cheaper ones (or a quick human fix) would have done the job.

Meanwhile, controlled studies keep saying the same thing:

  • AI coding assistants give big gains in some contexts,
  • and outright slow developers down in others—especially when tasks are small or the codebase is well understood.

If you need 30 prompts to get what a competent dev would produce in one shot, the problem isn’t that you need ‘better prompting techniques.’ The problem is you don’t know what you’re asking for.


“Prompt Engineering” vs Actual Engineering

Prompt engineering was briefly sold as a new job category:

  • no code,
  • no math,
  • no systems thinking,
  • just “talk well to the model.”

Companies are already walking that back.

The emerging consensus:

  • “prompt engineer” as a standalone role is fading;
  • what’s valuable now are people who understand systems, data, constraints, and verification—and happen to use AI well.
    In other words:

  • AI skills are a multiplier on real expertise,

  • not a replacement for the expertise.
    The difference in practice:

  • A non-technical “prompt engineer” burns tokens asking the model to invent APIs, architectures, and glue code from scratch.

  • A real developer feeds the model context, constraints, and code, then uses it to refactor, scaffold, or check specific parts.

Prompt engineering without domain knowledge is just creative ways to waste money faster.

The Hidden Inefficiency: Prompt Engineering Debt

People talk about technical debt.

We’re now accumulating prompt engineering debt:

  • AI-generated docs that sound authoritative but are subtly wrong,
  • half-baked scripts or UIs that “mostly work” but hide security or performance issues,
  • workflows no one can reproduce because the steps lived entirely inside chat logs.
    You save 10 minutes by letting AI draft something.

You lose:

  • hours verifying, correcting, and reformatting,
  • more hours when future you or someone else has to figure out “how this was made,”
  • trust, when stakeholders discover the tool hallucinated key details.

Managers and non-technical leaders are already reporting:

  • AI “helped” them finish something fast,
  • but they then spent several hours fixing it,
  • net result: more tired, not more productive.

This is the real cost nobody includes in their “AI saved me X hours!” posts.

AI doesn’t just create output. It creates obligations: to verify, to correct, to own the result. Prompt debt is still debt.

Watching a Prompt Power User Struggle With a Two-Minute Bug

The most painful demos of “AI superusers” often look like this:

  • They hit a bug or small logic issue.
  • Instead of reading the code or error message, they:
    • paste everything into Claude or another model,
    • ask it to “fix the problem,”
    • get a large diff,
    • apply it blindly,
    • break something else.

Repeat.

If you’re an actual developer, you know what a normal path looks like:

  • read the error,
  • follow the stack trace,
  • inspect inputs and outputs,
  • change one or two lines,
  • add a test if needed.

Two minutes.

The “prompt engineer” route:

  • 20+ minutes and 100+ credits,
  • three or four different attempts,
  • unsatisfying sense that “it works now but not sure why.”
    This is not AI’s fault.

This is what happens when someone:

  • doesn’t understand the system,
  • doesn’t trust themselves to reason about it,
  • and thinks more prompting is always the answer.

If AI is your first reflex for every tiny issue, you’re not a power user. You’re outsourcing your thinking.


Being an AI Superuser Is Not the Same as Being a Developer

There is such a thing as an AI power user.

They look nothing like the people throwing 400-line prompts at every problem.
Real power users:

  • have solid fundamentals in at least one domain (dev, data, ops, product),
  • use AI to compress workflows they already understand,
  • treat models as tools in a chain, not as all-knowing oracles.

They:

  • script repeated tasks,
  • integrate AI into editors, terminals, and CI pipelines,
  • design small, reliable loops where the model does the mechanical parts.

They do not:

  • spend all day rewriting the same vague prompt,
  • rely on AI to invent systems they don’t understand,
  • brag about number of tokens used as if that were a productivity metric.

Being good with AI is not about ‘talking to it a lot.’ It’s about knowing enough to ask for the right thing once.

The Ego Layer: Prompt Engineering as a Mask for Insecurity

Here’s the uncomfortable part:

For some people, “prompt engineering” is a socially acceptable way to hide insecurity.

Instead of saying:

  • “I don’t understand this system,”
  • “I need to learn the basics,”
  • “I’m out of my depth,”

they say:

  • “I’m working on AI workflows,”
  • “I’m refining the prompt,”
  • “The model just needs better instructions.”
    It sounds sophisticated.

It keeps them in the conversation.

It lets them avoid asking the “stupid questions” they really need to ask.

But underneath that layer of AI jargon, nothing changes:

  • no better mental models,
  • no better debugging skills,
  • no better understanding of trade-offs.

Prompt engineering becomes a costume you wear so people don’t see that you’re scared to admit what you don’t know.

How Skilled Developers Actually Use AI (and Why That’s Threat-Proof)

Most senior devs who integrate AI deeply share the same pattern:

They use AI to:

  • accelerate things they already know how to do,
  • generate first drafts they fully understand and can rewrite,
  • explore alternatives or edge cases they might have missed.

They don’t:

  • let AI design the architecture of a system they don’t understand,
  • push AI-generated changes without reading them carefully,
  • use AI as a shield from having to think.

Studies and field reports show:

  • AI assistants give big boosts when engineers know their stack and use AI as an exoskeleton;
  • in unfamiliar systems or without clear specs, they can slow things down or create new failure modes.

The job that’s safest long-term is still:

  • understanding systems,
  • making decisions under uncertainty,
  • reviewing and owning the output—human or AI-generated.

The thing that keeps you safe is not how many prompts you can write. It’s how many decisions you can own.

If You’re Technical: Why This Whole Trend Should Calm You Down

If you’re a real engineer worried about AI replacing you, look carefully at how most “prompt superusers” actually work today.

You’ll see:

  • a lot of noise,
  • a lot of wasted tokens,
  • a lot of shallow output,
  • and a lot of work created for the people who still have to be accountable.

The market is already correcting:

  • the hype around “prompt engineer” as a standalone role is fading;
  • companies are hiring for AI + X (engineering, data, product, security), not for “AI whisperers”;
  • senior developer roles are shifting toward more design, review, integration, and governance—not away from them.

AI will absolutely replace:

  • a chunk of low-skill work,
  • some tasks that used to justify junior roles,
  • a lot of fake productivity.

It will not replace:

  • clear thinking,
  • system-level understanding,
  • the ability to define what “good” looks like in the first place.

Your job is not to compete with people burning credits. Your job is to be the person who knows what should happen before anyone opens a chat window.

I fix the Angular apps that generalists break.

I’m Karol Modelski, senior Angular developer and frontend architect rescuing legacy B2B SaaS frontends.

If your Angular app is slowing your team down, start with a 3‑minute teardown of your current setup: https://www.karol-modelski.scale-sail.io/

Upgrading OpenBSD 7.8 to OpenBSD 7.9

The lastest version of OpenBSD has been released this week and announced on the Mailinglist (but also on X/Twitter by Brian Steele). As usual, lot of improvement, this publication is just a quick summary.

  • Read the release note and the upgrade procedure.

  • Ensure you have enough place on your partitions.

df -h
  • Be prepared to upgrade your database like PostgreSQL. Do a Backup.

  • Start with one device to see if everything is fine.

  • Upgrade with sysupgrade.

sysupgrade
  • After the reboot, upgrade the packages with pkg_add
pkg_add -uUra
  • Do a second reboot if necessary

  • Upgrade PostgreSQL and other services which have been upgraded.

  • Do a third reboot to check if all services are started correctly during boot (reboot proof servers)

And… It should be okay! No big deal for this upgrade on my side, everything worked without issues.

Cover Image by A Perry on Unsplash

We migrated a .NET app from ABP Framework to Granit without downtime – here’s the playbook

We just finished moving a 15-module .NET service from ABP Framework
to Granit — without a maintenance window, without
a code freeze, and without a parallel run-everything-twice phase. The whole
thing took about ten weeks running alongside feature work.

This post walks through the playbook: why we moved, the architecture that
made an incremental cutover possible, the one-page mapping between ABP
and Granit primitives, a real before/after of a CRUD module, and the
single technical gotcha that will trip up anyone whose ABP entities use
int or long keys.

If you want the full reference with every cross-cutting concern covered
(multi-tenancy, audit, settings, permissions, background jobs,
specifications), the canonical version lives in the
Granit migration guide. This
article is the field report.

Why we moved off ABP

Let me get this out of the way: ABP is a fine framework. We didn’t
move because something was broken. We moved because four trends in our
codebase finally added up:

  • We had been writing Minimal API endpoints by hand for new features for
    two years — CrudAppService<TEntity, TDto> had stopped earning its
    keep on anything that wasn’t pure CRUD.
  • Our DDD layering (Domain / Application.Contracts / Application /
    EntityFrameworkCore) was generating four projects per module and a
    lot of IObjectMapper boilerplate that nobody read.
  • We had adopted Wolverine for messaging and
    were fighting IDistributedEventBus to make it route the way we
    wanted.
  • New hires kept asking “why is there a parallel IStringLocalizer
    abstraction on top of the BCL one?” — and we never had a great answer.

Granit is the framework that crystallized out of those four answers: a
modular .NET 10 stack with native Wolverine, Minimal API as the
endpoint surface, BCL primitives where they suffice, and CQRS shaped as
the default rather than a workaround. The conceptual overlap with ABP
is enormous — same [DependsOn] module system, same IMultiTenant
interface name, same ISettingProvider interface name, same
AuditedEntity family — which is what made the migration tractable in
the first place.

The strangler-fig architecture

A big-bang rewrite was never on the table. We ran the new Granit host
alongside the existing ABP host, behind the same ingress, sharing the
same database and the same Keycloak issuer. The ingress decides
per-URL which host serves the request. Each module flips over
independently.

            ┌─────────────────┐
   browser ─►   Ingress (YARP)│
            └────────┬────────┘
                     │
        ┌────────────┴─────────────┐
        │                          │
   /api/legacy/*               /api/orders/*
        │                       /api/inventory/*
        ▼                          ▼
   ┌────────┐                 ┌─────────┐
   │  ABP   │                 │ Granit  │
   │  host  │                 │  host   │
   └───┬────┘                 └────┬────┘
       │                           │
       └────────┬──────────────────┘
                ▼
         ┌──────────────┐
         │ Shared DB    │
         │ Shared OIDC  │
         └──────────────┘

The shared database is the linchpin. Three rules:

  1. Schema ownership belongs to the host that wrote the table first.
    EF Core migrations are generated by that host; the other side either
    reads via a read-only DbContext or generates its own migrations
    into the same __EFMigrationsHistory table.
  2. Audit and tenant columns must keep the same shape during the
    cutover.
    ABP uses CreatorId / CreationTime; Granit uses
    CreatedBy / CreatedAt. We solved this with EF Core column
    overrides on the Granit side (HasColumnName("CreationTime")) so
    physical schema didn’t drift until the ABP host was gone.
  3. OIDC stays as-is. Tokens minted for the ABP host work as-is on
    the Granit host. No parallel user store, no token exchange, no
    “auth migration” sub-project.

The conceptual mapping (cheat sheet)

We carried this table around in the team Notion. The full version is
on the docs site;
here are the rows we hit most:

ABP primitive Granit equivalent
AbpModule + [DependsOn(...)] GranitModule + [DependsOn(...)]
IApplicationService / CrudAppService<...> A Minimal API endpoint class with handler methods
IRepository<TEntity, TKey> (~30 helpers) DbContext directly, or a thin custom repository
AuditedEntity<TKey> / FullAuditedEntity<TKey> AuditedEntity / FullAuditedEntity (Id is always Guid)
IMultiTenant + ICurrentTenant.Id IMultiTenant + ICurrentTenant.Id
ISettingProvider.GetOrNullAsync(name) ISettingProvider.GetOrNullAsync(name) (same shape)
IPermissionChecker + PermissionDefinitionProvider ASP.NET Core authorization policies (per-endpoint)
IDistributedEventBus.PublishAsync Wolverine bus.PublishAsync
IBackgroundJobManager.EnqueueAsync Wolverine bus.ScheduleAsync
ISpecification<T> / Specification<T> Granit.Persistence.Specification<T> + inline Spec.For<T>()
AuditLog table AuditEntry rows via GranitAuditingModule
IObjectMapper (AutoMapper) Mapperly (compile-time) or manual

The pattern in this table is the headline: most ABP primitives have a
direct Granit equivalent under the same name or a near-identical
shape
. The migration is rarely a re-architecture; it’s mostly
namespace changes plus a few opinionated rewrites where Granit picks a
different default.

The killer before/after: CrudAppService → Minimal API

This is the diff that drove the migration. Same module — Inventory,
a CRUD aggregate with audit, validation, and four permissions — in
both stacks.

ABP, the standard shape:

[Authorize(MyAppPermissions.Inventory.Default)]
public class InventoryAppService
    : CrudAppService<InventoryItem, InventoryItemDto, Guid,
                     PagedAndSortedResultRequestDto, CreateInventoryItemDto>,
      IInventoryAppService
{
    public InventoryAppService(IRepository<InventoryItem, Guid> repository)
        : base(repository)
    {
        GetPolicyName    = MyAppPermissions.Inventory.Default;
        GetListPolicyName = MyAppPermissions.Inventory.Default;
        CreatePolicyName = MyAppPermissions.Inventory.Create;
        UpdatePolicyName = MyAppPermissions.Inventory.Edit;
        DeletePolicyName = MyAppPermissions.Inventory.Delete;
    }
}

Plus an IApplicationService interface in *.Application.Contracts,
plus DTOs split across two projects, plus a PermissionDefinitionProvider
declaring the permission tree. Five REST endpoints auto-generated, but
also five points of indirection you cannot see in this file.

Granit, the explicit shape:

public static class InventoryEndpoints
{
    public static IEndpointRouteBuilder MapGranitInventory(
        this IEndpointRouteBuilder app)
    {
        var group = app.MapGroup("/inventory")
            .WithTags("Inventory")
            .RequireAuthorization("inventory.read");

        group.MapGet("/{id:guid}",   GetById);
        group.MapGet("/",            List);
        group.MapPost("/",           Create).RequireAuthorization("inventory.create");
        group.MapPut("/{id:guid}",   Update).RequireAuthorization("inventory.edit");
        group.MapDelete("/{id:guid}", Delete).RequireAuthorization("inventory.delete");

        return app;
    }

    public static async Task<Created<InventoryItemResponse>> Create(
        InventoryItemCreateRequest request,
        IInventoryRepository repo,
        ICurrentTenant currentTenant,
        CancellationToken ct)
    {
        var item = InventoryItem.Create(
            Guid.NewGuid(), currentTenant.Id,
            request.Name, request.Sku, request.Quantity, request.UnitPrice);

        await repo.AddAsync(item, ct);
        return TypedResults.Created($"/inventory/{item.Id}",
            new InventoryItemResponse(item.Id, item.Name, item.Sku,
                item.Quantity, item.UnitPrice, item.CreatedAt));
    }

    // GetById / List / Update / Delete follow the same pattern.
}

The trade-off is that you write each endpoint signature yourself —
there is no shortcut equivalent to CrudAppService, which is the whole
point of moving to explicit Minimal API. In return:

  • Number of projects per module: 4 → 1 (or 2 if you split persistence).
  • DTO ↔ entity mapping: IObjectMapper (runtime reflection) → static
    ToResponse method, or Mapperly (compile-time source generation).
  • Permissions: PermissionDefinitionProvider + [Authorize(name)]
    → ASP.NET Core policies declared in the module’s ConfigureServices.
  • Validation: data annotations on DTOs → FluentValidation classes,
    auto-discovered by AddGranitValidatorsFromAssemblyContaining<T>().
  • Endpoint registration: declarative (REST auto-exposed) → explicit
    (you call api.MapGranitInventory() from Program.cs). This is
    Granit’s convention across every shipped module — MapGranitAuditing(),
    MapGranitParties(), MapGranitBlobStorage(), etc.

You can read all five endpoint signatures in one sitting. That is the
point.

The one gotcha: Guid keys

Here is the single thing that will derail an ABP migration if you
discover it late: Granit’s Entity base type fixes Id as Guid.
There is no Entity<TKey>, no AuditedAggregateRoot<int>. The framework
opinion is that every entity has a Guid (v4 or v7) for distributed
id generation, sharding, and tenant isolation.

If your ABP entities use AggregateRoot<int> or <long>, you need a
one-shot key rewrite before any module is ported — both hosts have
to agree on the key type once they read and write the same rows.

We used the deterministic UUID v5 strategy in PostgreSQL: derive each
new Guid from the existing int via uuid_generate_v5(namespace,
id::text)
. The same input always yields the same UUID, so foreign
keys port via the same hash — no lookup table, no downtime.

-- Add new key column, backfilled with deterministic UUIDs.
ALTER TABLE inventory_items
  ADD COLUMN id_new uuid;

UPDATE inventory_items
  SET id_new = uuid_generate_v5('a0eebc99-9c0b-4ef8-bb6d-6bb9bd380a11', id::text);

-- Rewrite every dependent FK the same way (one statement per FK).
ALTER TABLE inventory_movements
  ADD COLUMN inventory_item_id_new uuid;

UPDATE inventory_movements
  SET inventory_item_id_new =
    uuid_generate_v5('a0eebc99-9c0b-4ef8-bb6d-6bb9bd380a11', inventory_item_id::text);

-- Swap the primary key.
ALTER TABLE inventory_items DROP CONSTRAINT inventory_items_pkey;
ALTER TABLE inventory_items DROP COLUMN id;
ALTER TABLE inventory_items RENAME COLUMN id_new TO id;
ALTER TABLE inventory_items ADD PRIMARY KEY (id);

-- Re-create each FK constraint.
ALTER TABLE inventory_movements DROP COLUMN inventory_item_id;
ALTER TABLE inventory_movements RENAME COLUMN inventory_item_id_new TO inventory_item_id;
ALTER TABLE inventory_movements
  ADD CONSTRAINT fk_inventory_movements_item
    FOREIGN KEY (inventory_item_id) REFERENCES inventory_items(id);

Critical sequencing: regenerate the ABP-side entity to Guid Id
before running the SQL. If the ABP host stays on int Id after the
rewrite, its EF Core model diverges from the physical schema and every
read throws. We discovered this during a staging dry-run and it would
have been a production incident.

The mapping-table alternative (random Guid per row, persisted in a
_key_migration table) is documented in the
full guide section.

The license footnote that wasn’t a footnote

I left this for last because it doesn’t fit the technical narrative, but
it ended up being the line-item that got the migration unblocked with
our legal team:

License What that means in practice
ABP Framework (OSS core, abpframework/abp) LGPL-3.0 You can link against it from proprietary code (it’s “Lesser” GPL). But modifications to the framework itself must be published under LGPL. Many enterprise SCA tools (Black Duck, FOSSA, GitHub Advanced Security) flag LGPL as “needs legal review” before merge.
ABP Commercial (Suite, LeptonX, premium modules) Proprietary, paid per-seat Vendor-tied, locked behind support contract.
Granit (entire OSS surface — framework, frontend, templates) Apache-2.0 Permissive. Use, modify, fork, redistribute — in proprietary derivatives too — with zero copyleft on your app code or your framework patches. Explicit patent grant. Auto-approved by most enterprise SCA pipelines.

Our SCA pipeline (FOSSA) was the unblocker. LGPL-3.0 was flagged as
“requires legal review” on every PR that touched a transitive ABP
dependency, generating a manual ticket each time. Apache-2.0 sails
through. That alone saved us a recurring 2-3 day legal cycle per
sprint, independent of the technical wins.

If you sit in a regulated industry (finance, health, government), the
SCA-friction argument may be the only one your CFO needs to hear.

What we did not migrate

Three things in our ABP setup did not have a 1:1 Granit equivalent.
Worth flagging upfront:

  • ABP Suite (codegen UI). Granit has no equivalent. We replaced
    Suite-generated module scaffolding with the dotnet new
    granit-microservice
    template and hand-written modules where the
    template wasn’t expressive enough.
  • The full generic-repository surface. IRepository<T, TKey>
    exposes ~30 helpers (GetPagedListAsync(skip, take, sorting),
    FirstOrDefaultAsync(predicate), …). Granit prefers DbSet<T>
    directly. We ported the four helpers we actually used as extension
    methods on DbSet<T> and dropped the rest. The temptation to
    recreate the full surface is real; resist it.
  • The Angular ABP UI. Our frontend is React, so this didn’t bite
    us — but if your UI is a tightly coupled ABP Angular template, the
    Granit React companion is a separate migration project, not a
    drop-in.

The bottom line

Ten weeks, 15 modules, zero downtime, ~40% reduction in module project
count, and a codebase where new hires don’t ask “why is there a
parallel abstraction on top of the BCL one?” anymore.

The full step-by-step is in the
Granit migration guide —
including every cross-cutting concern, the FAQ, and the strategy table
for which modules to port in which order.

If you’re sitting on an ABP codebase and wondering whether the move is
worth it, the honest answer is: only if Granit’s opinions match your
team’s
. Minimal API over auto-generated controllers, Wolverine over
generic event bus, BCL primitives over wrapped ones, Guid keys
everywhere, and Apache-2.0 over LGPL-3.0. If those five trade-offs
sound like wins, the migration is mechanical. If any of them sound
like regressions, stay on ABP — both frameworks are good at what
they do.

More on Granit: