iOS 27, sesle iPhone / iPad kontrolünü çok daha doğal hale getirecek [Video]

iPhone

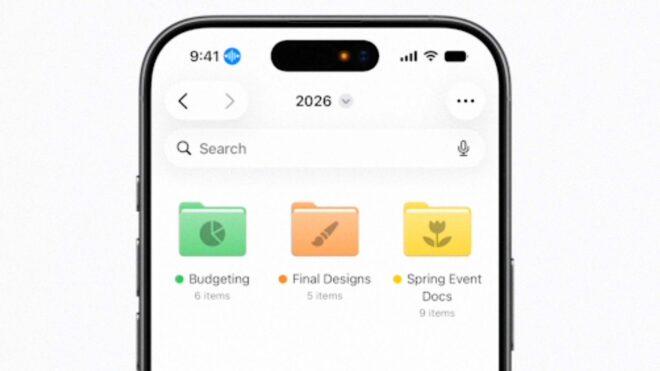
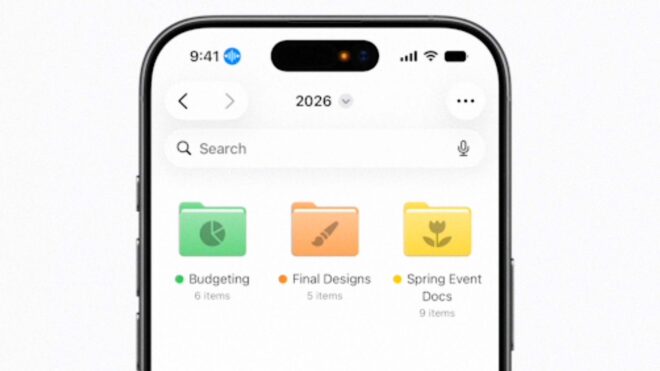
iPhoneApple tarafından yapılan resmi açıklamaya göre sesli komutlarla iPhone ve iPad’i kontrol etme süreci Apple Intelligence sayesinde çok daha doğal hale geliyor. Apple’ın, “Apple Intelligence sayesinde Sesle Denetim, çeşitli fiziksel engellere sahip kullanıcıların iPhone ve iPad’i tamamen sesle kontrol etmelerine yardımcı olmak için doğal dilden yararlanarak şimdi her zamankinden daha pratik hale geliyor. Yeni esnek giriş olanağıyla kullanıcılar, etiketleri veya numaraları ezberlemek yerine ekrandaki düğmeleri ve kontrolleri doğal dil kullanarak açıklayabiliyor. “Gördüğünüzü söyleyin” seçeneği, Apple Harita veya Dosyalar gibi görsel düzenlere sahip olanlar dahil tüm uygulamalarda “en iyi restoranlarla ilgili kılavuza dokun” veya “mor klasöre dokun” gibi pratik bir dil kullanarak kolayca gezinme imkanı sunuyor. Bu özellik, öğelerin erişilebilirlik için doğru şekilde etiketlenmediği durumlarda da kullanıcıların engelleri aşmalarını sağlıyor.” açıklamasını yaptığı, resmi oalrak aşağıdaki videoda gözler önüne serilen sistem, maalesef ilk aşamada Türkçe / Türkiye desteğine sahip olmayacak. “Apple Intelligence ile desteklenen Sesle Denetim; ABD, Kanada, Birleşik Krallık ve Avustralya’da […]

iOS 27, sesle iPhone / iPad kontrolünü çok daha doğal hale getirecek [Video] yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Instruction: how to create a website (HTML file, webpage, or HTML document)

To create an HTML page and view it, we will use your pre-installed programs, such as a text editor and a browser.

  1. First step: you need to create a file “index.html” with the “.html” extension. To do this, use this instruction to enable file extensions:

Create a file: index.html

  1. The second step is to place this code in an index.html file. To do this, open your index.html file in a text editor or in a code editor, copy this code, paste it into the editor, and save the changes or save file (or save as “index.html”).

code:

<!DOCTYPE html>
<html>
<head>
<title>This is a title</title>
</head>
<body>
<p>Hello world!</p>
</body>
</html>

  1. Done. Open your index.html file in a browser, such as Chrome, Firefox, Edge, or Safari, to see the result.

Sources:

Forgelab PDF API Review: Affordable REST API for PDF Merge, Split, and Compress

PDF processing looks trivial until you ship it. Merging two files, splitting a report into per-chapter documents, compressing a 40 MB scan so it clears an email size limit — each one is a solved problem inside some library, and each one becomes your problem the moment it runs in production. Forgelab shipped a PDF API in May 2026 that bets you would rather not own that problem. It starts at $5 a month. We worked through its endpoint design and pricing to figure out who that number actually serves.

What Forgelab’s PDF API actually does

Forgelab’s PDF API exposes four operations behind a plain REST interface:

  • Merge — combine multiple PDFs into a single document.
  • Split — break one PDF into several separate files.
  • Compress — reduce file size for storage or email limits.
  • PDF-to-image — render PDF pages as image files.

You send a request, you get a processed file back. There is no SDK to install, no native binary to compile against, no headless browser to keep alive. If you have ever shipped a feature that leaned on Ghostscript or a Chromium render farm, that absence is the entire pitch.

The $5 entry price is the other half of it. PDF work is rarely a product’s core feature — it is the invoice export, the report download, the combine-these-uploads button. Spending an engineering week on something that peripheral is hard to justify, and so is an enterprise contract. A few dollars a month for a working endpoint changes that math.

What the launch material leaves out matters just as much: there is no published rate limit, no uptime commitment, and no detailed breakdown of how higher-volume tiers are priced. Read the four operations as confirmed and the operational guarantees as still unknown — we come back to that below.

The buy-versus-build math for PDF processing

Three paths exist for PDF processing, and the real cost of each is mostly hidden.

Self-hosting a library looks free. pdf-lib, Apache PDFBox, qpdf, Ghostscript, and mupdf all merge, split, and compress without a license fee. The cost shows up later. Ghostscript carries a long history of security advisories, malformed PDFs exhaust memory in ways that are hard to reproduce, and compression quality depends on flags you will spend a day tuning. Free libraries are not free — they are deferred maintenance, and you are the one who pays it.

Adobe PDF Services API is the enterprise answer. It is broad, well-documented, and dependable. It is also priced and scoped for organizations running document pipelines, not for a solo developer adding a download button. For a small SaaS, you are buying surface area you will never touch.

A low-cost API sits in the gap between those two:

None of this makes Forgelab automatically the right pick. It makes it a genuine third option where, for small teams, there were only two awkward ones before.

Forgelab’s PDF API is new. The launch announcement does not publish an uptime SLA, concrete rate limits, or a retention policy for uploaded files. Before you route customer documents through it, get answers to two questions: how long are uploaded files stored, and what is your fallback if the endpoint returns errors for an hour? Treat it as a dependency you can swap — not one you build your product on top of.

Where a hosted PDF API fits — and where it doesn’t

This kind of service earns its place when PDF handling is a feature, not the product. Invoice and receipt generation, letting users combine uploaded documents, compressing files before you store them, turning a PDF report into preview thumbnails — all of that is a clean fit. The work is occasional, the volume is moderate, and nobody on the team wants to be the person who owns the PDF library.

It fits poorly in three cases. If PDFs are your product — a document editor, a contract platform — you want that pipeline in-house, where you control quality and latency. If you handle regulated or sensitive documents, sending them to a third-party processor is a compliance conversation, not a coding decision. And if you process at high volume, per-operation economics can flip against you; check Forgelab’s upper tiers against your real numbers before you commit.

The integration itself is light: an HTTP client, a multipart upload or file reference, error handling, and a retry when a render fails. That is glue code — the kind of task an AI-assisted editor clears in minutes.

Whatever PDF API you choose, wrap it behind your own small interface — a pdfService.merge() function rather than raw HTTP calls scattered across your codebase. If Forgelab raises prices, adds latency, or you outgrow it, swapping providers becomes a one-file change instead of a refactor.

Forgelab’s PDF API will not be the deepest PDF tool you can buy, and at $5 a month it does not need to be. It needs to be cheaper than your time and simpler than Adobe. For a small team shipping a document feature, it clears both bars — provided you treat the missing SLA and retention details as open questions, not afterthoughts.

Originally published at pickuma.com. Subscribe to the RSS or follow @pickuma.bsky.social for new reviews.

UseState – Exercises

*Toggle Button *

import { useState } from "react";

function Toggle(){

   const [bulb,setBulb] = useState("https://www.w3schools.com/js/pic_bulboff.gif")
//    const [flag,setFlag] = useState(false);


   function toggle(){
    if (bulb === "https://www.w3schools.com/js/pic_bulboff.gif"){
        setBulb("https://www.w3schools.com/js/pic_bulbon.gif")
        // setFlag(true);
    }
    else{
        setBulb("https://www.w3schools.com/js/pic_bulboff.gif")
        // setFlag(false);
    }
   }


    return(
        <>
        <img src= {bulb}></img>
        <button onClick = {toggle}>{bulb==="https://www.w3schools.com/js/pic_bulboff.gif"?"ON":"OFF"}</button>
        </>

    )


}

export default Toggle

output:

Input Field Value

import { useState } from "react";

function Input(){

    const[name,setName] = useState('')


    return(
    <>
      <input value={name} type="text" onChange={(e)=>setName(e.target.value)}></input>
        <p>Hi! Welcome {name}</p>
        </>

    )

}

export default Input

Output:

Show/Hide Text

function Show(){

    const[text,setText] = useState("");
    const[show,setShow] = useState(false);


    function showContent(){
        if(show===false){
             setShow(true);
        }
        else{
            setShow(false);
        }

    }

    return(
        <>
        <input type="password" onChange={(e)=>setText(e.target.value)}></input>
        <button onClick={showContent}>{show===false ?"Show":"Hide"}</button>
        {show && <p>{text}</p>}
        </>

    )
}

export default Show 

Output:

Character Counter

import { useState } from "react";

function Character (){

const [count,setCount] = useState(0);

    return(
        <>
        <input type="text" onChange={(e)=>setCount(e.target.value.length)}></input>
        <p>Count :{count} </p>
        </>

    )
}

export default Character

Output:

Form with Multiple Input

import { useState } from "react";


function Multiple(){

    const[name,setName]= useState('');
    const[email,setEmail]= useState('');
    const[number,setNumber]= useState('');
    const[city,setCity]= useState('');
    const[password,setPassword]= useState('');


    return(
        <>
        <input type="text" onChange={(e)=>setName(e.target.value)}></input>
        <input type="email" onChange={(e)=>setEmail(e.target.value)}></input>
        <input type="text" onChange={(e)=>setNumber(e.target.value)}></input>
        <input type="text" onChange={(e)=>setCity(e.target.value)}></input>
        <input type="password" onChange={(e)=>setPassword(e.target.value)}></input>
        </>
    )
}

export default Multiple

CheckBox Selection List

import { useState } from "react";

function Selection(){

    const [value,setValue] = useState([]);
    const [checked,setChecked] = useState(false);

   function addValue(e) {

        const checked = e.target.checked;
        const item = e.target.value;

        if (checked) {
            setValue([...value, item]);
        } else {
            setValue(value.filter((val) => val !== item));
        }
    }

    return(
        <>
        <input value="React" type="checkbox" onChange={addValue}></input>
        <label>React</label>
        <input value="Node" type="checkbox" onChange={addValue}></input>
        <label>Node</label>
        <input value="Java" type="checkbox" onChange={addValue}></input>
        <label>Java</label>
        <input value="SQL" type="checkbox" onChange={addValue}></input>
        <label>SQL</label>

        <ul>
                {value.map((val, index) => (
                    <li key={index}>{val}</li>
                ))}
            </ul>
        </>
    )
}

export default Selection

Output:

Dependent Dropdown

import { useState } from "react";

function Dependent() {

    const states = {
        india: ["tamilnadu", "kerala"],
        usa: ["arizona", "newyork"]
    };

    const cities = {
        tamilnadu: ["chennai", "trichy"],
        kerala: ["trivandrum", "kochi"],
        arizona: ["phoenix"],
        newyork: ["washington"]
    };

    const [country, setCountry] = useState("");
    const [state, setState] = useState("");
    const [city, setCity] = useState("");

    return (
        <>

            <select value={country}
         onChange={(e) => {
        setCountry(e.target.value);
        setState("");
        setCity("");
        }}
        >   

                <option value="">Select Country</option>

                <option value="india">India</option>

                <option value="usa">USA</option>

            </select>


            <select value={state} onChange={(e) => {
                setState(e.target.value);
                setCity("");

            }

            }>

                <option value="">Select State</option>

                {
                    country &&
                    states[country].map((val, index) => (
                        <option key={index} value={val}>
                            {val}
                        </option>
                    ))
                }

            </select>


            <select value={city} onChange={(e) => setCity(e.target.value)}>

                <option value="">Select City</option>

                {
                   country && state &&
                    cities[state].map((val, index) => (
                        <option key={index} value={val}>
                            {val}
                        </option>
                    ))
                }

            </select>


        </>
    );
}

export default Dependent;

Output:

The Pope, Anthropic, and the Weight of Rerum Novarum

On May 25, an American pope will stand in the Vatican’s Synod Hall and present the first papal encyclical on artificial intelligence. Alongside him: Christopher Olah, co-founder of Anthropic and one of the field’s leading interpretability researchers. The document is called Magnifica Humanitas, or “Magnificent Humanity.” Pope Leo XIV signed it on May 15, 135 years to the day after his namesake, Leo XIII, signed Rerum Novarum, the encyclical that defined Catholic social teaching on labor and capitalism as the Industrial Revolution reshaped the world.

That date was not a coincidence. It was a claim.

The Church is saying, explicitly, that AI is the industrial revolution of our moment. The same questions about human dignity, labor, and the limits of capital that Leo XIII addressed in 1891 are back. The framing is grand, but it’s also serious: Rerum Novarum became the foundation of modern Catholic social thought on workers’ rights. The current pope has already been citing it in speeches. If this encyclical lands with similar weight, it will be the most significant moral framework for AI published by any institution outside a technology lab itself.

What makes the moment stranger: Anthropic is currently suing the Trump administration, which in February ordered all U.S. agencies to stop using the company’s technology. The White House reportedly imposed those penalties because Anthropic refused to grant the military unrestricted use of its AI. Having Anthropic’s co-founder on the Vatican stage presenting a document on AI and human dignity is not a neutral act. PBS framed it bluntly: Olah’s presence “suggests that the U.S. pope’s position on AI will become a new flashpoint with the Trump administration.”

I find this genuinely hard to parse, and that’s why I keep thinking about it.

The obvious read is that the Vatican chose a side, the safety-focused AI company over the military-access-first posture of the current U.S. government. And it did so not with a press release or a policy brief, but with the most solemn form of papal teaching available. That’s a lot of institutional weight to throw behind one company’s positioning.

The less cynical read is that Olah, specifically, makes sense here. He’s not Dario Amodei. He’s the person most associated with Anthropic’s mechanistic interpretability work: the attempt to actually understand what’s happening inside these models. If the Vatican wanted an AI researcher who could speak honestly about uncertainty, opacity, and the genuine unknowability of these systems, Olah is a reasonable choice. His concern about AI isn’t performative. Whether his presence gets read that way is a separate question.

The encyclical itself hasn’t been published yet. It drops in four days. What it actually argues will matter more than the staging. But the staging already tells you something. This is not the Vatican issuing a cautious statement through the Pontifical Academy of Sciences. The pope will be in the room, breaking with the usual protocol of delegating presentations to officials. Two senior cardinals are presenting alongside theologians from Durham and Santa Clara. The ceremony is in the main Vatican auditorium.

The Church has done this before with transformative technologies. It was usually slow, often wrong, and occasionally right in ways that outlasted the politics of the moment. Whether Magnifica Humanitas joins that tradition or collapses into a well-intentioned document nobody reads past the headlines, that’s the question. But as a signal that AI ethics has moved from conference panels to the oldest continuous moral institution in the Western world, this week is hard to dismiss.

The last time a pope addressed a technology by invoking Leo XIII, the resulting framework shaped labor law across multiple continents. That’s a high bar. Four days to see if the document itself comes anywhere close.

NVIDIA’s $81.6B Quarter Confirms the Networking Bottleneck — Here’s What Developers Should Know

NVIDIA reported $81.6 billion in revenue for Q1 FY2027 yesterday. That’s an 85% year-over-year increase. Non-GAAP EPS of $1.87 beat consensus by 6%. Q2 guidance of $91 billion is 4% above what analysts expected.

By every headline measure, this was a clean beat and raise. The stock closed up 1.8% and was flat after hours.

The pattern is now five out of six quarters where NVIDIA beats the numbers and the stock doesn’t rally. The headline numbers are priced before the print. The signal is in the composition of revenue, not the total.

The networking number that changes the story

Data Center networking revenue reached $14.8 billion — a record, up 199% year-over-year and 35% sequentially. Compare that to Data Center compute revenue of $60.4 billion, which grew 77% year-over-year.

The networking segment is growing at 2.6x the rate of the compute segment.

This is the clearest signal yet that the bottleneck in AI training is migrating from GPU FLOPs to inter-GPU bandwidth. As clusters scale past 50,000 devices, the wall-clock constraint shifts from “how fast can the GPU multiply matrices” to “how fast can the network move gradients between GPUs.”

Two years ago, networking was roughly 12% of Data Center revenue. It is now 20% and accelerating.

The full-stack moat is protecting margins

GAAP gross margin reached 74.9% — up from 60.6% a year ago. This directly contradicts the narrative that Blackwell volume production would compress margins through CoWoS packaging and HBM memory costs.

Margins are expanding because the full stack (CUDA + NVLink + Spectrum-X + Blackwell silicon) creates pricing power that chip-design-alone cannot match. No competitor currently replicates this combination of scale and margin.

Key number: Operating income of ~$53.3 billion, up 147% year-over-year. GAAP net income tripled to $58.3 billion.

$48.6 billion in free cash flow — in one quarter

That’s a 60% FCF margin. Only about 15 companies in the world generate more net profit in an entire year than NVIDIA generates in cash in three months.

Management’s confidence shows in capital returns: dividend from $0.01 to $0.25 per share (25x increase), new $80 billion buyback authorization, and ~$20 billion returned to shareholders during the quarter.

Vera Rubin timeline de-risks the transition

Confirmed: on track for H2 2026, starting Q3, volume ramp in Q4. Architectural transitions are the highest-risk moment for any semiconductor company. This quarter’s confirmation substantially de-risks the handoff.

Blackwell demand is so strong it’s driving up secondary-market prices for older Hopper and Ampere GPUs.

Why the bottleneck matters for infrastructure engineers

If you’re designing training clusters, the implication is direct: the binding constraint on throughput is shifting from GPU selection to network topology. Spectrum-X Ethernet and InfiniBand choices matter more per dollar than GPU generation increments at the margin.

For inference workloads, the bottleneck migration has different dynamics — memory bandwidth and model distribution across nodes become the constraint. But the pattern holds: the easy gains are no longer at the compute layer.

The one risk

Data Center now accounts for 92% of revenue. This is not a company risk — it’s a regime risk. If hyperscaler capex cycles, 92% of revenue faces the same headwind.

All falsification triggers are green

  • Q2 guide below $85B → Guided $91B
  • Vera Rubin delayed beyond Q3 → On track Q3
  • Gross margin below 73% → 74.9%
  • Networking growth < compute growth → 199% vs 77%

The thesis is intact and the data is strengthening it.

Originally published on The Durability Curve.

Open Source Software Monetization: How Developers Are Actually Making Money in 2026

Open Source Software Monetization: How Developers Are Actually Making Money in 2026

Published: 2026-05-05

Open source software powers the modern internet. Every cloud service, every mobile app, every enterprise system runs on open source foundations. And yet, the economics of open source have always been paradoxical: the people who use your software the most — companies making billions — often pay the least.

This guide is about how open source monetization actually works in 2026. Not the theory. Not the idealistic models that sound good in blog posts. The actual mechanisms that developers are using right now to generate real revenue from open source projects.

Why Open Source Monetization Is Hard

Before diving into specific models, it’s worth understanding why open source monetization has historically been so difficult.

The zero marginal cost problem: Once you’ve written software and released it under an open source license, the cost of providing it to additional users is effectively zero. This makes traditional pricing models impossible — you can’t charge per user when the marginal cost of serving the next user is nothing.

The perception problem: Open source is associated with free. When something is free, users expect it to stay free. Asking for money later — after people have built dependencies on your software — feels like a bait-and-switch.

The “someone else will fork it” problem: If you put useful software behind a paywall, a community member can always fork it and remove the restrictions. This is both legally permissible (under most open source licenses) and practically inevitable for popular projects.

The maintenance burden: Open source isn’t a one-time cost. Every user creates support burden. Every dependency update requires attention. Every security vulnerability demands immediate response. The developers who pour hundreds of hours into maintaining popular projects often burn out because there’s no sustainable revenue model.

These challenges are real, but they’re not insurmountable. The developers who succeed have found ways to work with these constraints rather than against them.

The Open Source Monetization Landscape in 2026

Model 1: Dual License (The Classic Approach)

The dual license model is the original open source monetization strategy. You release your software under an open source license (typically GPL) for non-commercial use, and sell a commercial license for companies that want to use it in proprietary products without open sourcing their own code.

How it works in practice:

  • Individual developers and hobbyist projects use the GPL version for free

  • Companies that build products on top of your software pay for a commercial license

  • The commercial license typically costs on a per-developer or per-product basis

Real example — Qt: Qt is a cross-platform GUI framework used in thousands of commercial products. They offer Qt under GPL for open source projects, but companies that want to use Qt in closed-source commercial products must purchase a commercial license. This model has sustained Qt for over two decades.

The math: Qt’s commercial licenses range from $350/month for a single developer to custom enterprise pricing. A mid-sized company with 50 developers using Qt could be paying $50K+/year. This is real money that funds continued development.

When it works: Dual licensing works best for infrastructure-level projects — libraries, frameworks, compilers, database engines — where companies inevitably build proprietary products on top. It works less well for end-user applications where the open source version is the actual product.

Model 2: Open Core (The “Free” Tier + Paid Enterprise)

Open core is the most common monetization model for developer tools in 2026. You release the core functionality open source, then charge for enterprise features that companies need: advanced security, compliance tools, priority support, team management, and SLA guarantees.

How it works in practice:

  • The open source version is fully functional for individuals and small teams

  • Enterprise features (SSO, audit logs, compliance certifications, 24/7 support) require a paid license

  • Pricing is typically per-seat or per-instance

Real examples — GitLab, Elastic, Redis:

GitLab offers an open source Community Edition that is genuinely full-featured. But advanced DevOps capabilities, security scanning, compliance tools, and enterprise management require GitLab Ultimate (starting at $39/user/month). This model has made GitLab a multi-billion dollar company while maintaining a vibrant open source community.

Elastic took the same approach — open source Elasticsearch + Kibana, with paid features like security, alerting, and support in the commercial tiers. When AWS started offering Elasticsearch as a managed service, Elastic’s response was to change their license to further restrict the cloud provider use case — a direct monetization play.

Redis followed a similar path, eventually relicensing to restrict cloud providers from offering managed Redis services without contributing back.

The key to open core success: Your open source version must be genuinely useful. If companies can get everything they need from the free version, they won’t pay. If the enterprise features aren’t meaningfully different, they won’t pay. The enterprise features need to solve real pain for real companies.

Model 3: Software as a Service Wrapper

The SaaS wrapper model takes an interesting approach to the open source monetization problem. You release the core software as open source, but the version that runs in the cloud — managed and hosted by you — is the product.

How it works in practice:

  • The self-hosted version is open source and free

  • The cloud-hosted version (where you handle all infrastructure, updates, and support) is the paid product

  • Pricing is typically per-month per-instance or per-seat

Real examples — WordPress.com vs WordPress.org, Ghost.org vs Ghost:

WordPress started as open source software. WordPress.org lets you download and self-host it for free. WordPress.com (Automattic’s commercial venture) offers hosted WordPress with additional features. This has generated substantial revenue while maintaining a fully open source codebase.

Ghost took a more deliberate approach: the software is fully open source, but if you want to use Ghost’s hosted platform (ghost.org), you pay $9/month for the Starter plan. This funds the core development team while respecting the open source ethos.

The monetization advantage of SaaS: With SaaS, you control the infrastructure. Users pay for convenience, not features. The marginal cost of serving an additional user is real (compute, bandwidth, support), so the pricing model aligns with actual costs.

The challenge: With the rise of cloud providers offering one-click installs of any open source software, the managed hosting advantage is eroding. If your open source software is easy to install and AWS offers a managed version, you need to compete on something beyond just “we’ll host it for you.”

Model 4: Donation and Sponsorship

The donation model asks users to contribute money voluntarily. This can work through direct donations (Buy Me a Coffee, GitHub Sponsors, Open Collective), corporate sponsorship, or foundations that fund open source work.

How it works in practice:

  • Platform takes a percentage, you get the rest

  • Corporate sponsors get their logo on the project page and sometimes influence roadmap

  • Individual donors get… good feelings, mostly

Real examples — Redis, Node.js, Python:

Redis Labs (now Redis) had a program where cloud providers that built on Redis paid back into the ecosystem. This generated meaningful revenue while maintaining the open source nature of the core project.

The Python Software Foundation funds Python development through corporate sponsorships. Companies like Microsoft, Google, and Red Hat pay to support the language that their businesses depend on.

Open Collective hosts projects like webpack, Babel, and OpenSSL, where companies contribute to the maintenance of infrastructure they rely on.

The honest assessment of donations: Donation models work best for projects that are:

  1. Essential infrastructure (breaking them breaks the internet)

  2. Used by large companies with money and a sense of responsibility

  3. Have a charismatic maintainer who can build relationships with corporate sponsors

For a typical developer working on a useful but not critical library, donations typically generate $0-500/month — not enough to fund development full-time.

Model 5: Consulting and Services

The consulting model monetizes open source through expertise rather than the software itself. You build open source software, people adopt it, and then they pay you to help them implement, customize, and maintain it.

How it works in practice:

  • Software is free to use

  • Implementation, customization, and support are paid services

  • Can scale to significant revenue if you have deep expertise

Real examples — HashiCorp, Datadog:

HashiCorp built a suite of open source infrastructure tools (Terraform, Vault, Consul, Nomad). They monetized through enterprise versions of the open source software plus consulting and support contracts. The open source versions are genuinely used by thousands of companies; HashiCorp’s enterprise revenue funds the open source development.

Datadog started by building integrations with open source tools. They eventually built their own open source agent (dd-agent), which is genuinely useful and open source. Their commercial product builds on this foundation.

The sustainable consulting business: For a single developer or small team, consulting can generate $100-500/hour. At 20 hours/week, that’s $8K-40K/month. But consulting doesn’t scale — you’re trading time for money indefinitely, and it’s exhausting.

The Infrastructure Play: Building on Open Source Fundamentals

Here’s a model that more developers should consider: build commercial infrastructure on top of open source foundations, then monetize the infrastructure layer.

The strategy:

  1. Identify a popular open source tool that lacks good managed infrastructure

  2. Build a SaaS wrapper that handles deployment, scaling, monitoring, and support

  3. Charge a premium for the convenience of managed infrastructure

Why this works: The open source project does the hard work of building and maintaining the core software. You do the operational work of making it reliable and scalable. You capture the margin between your costs (infrastructure, support) and what companies will pay (a lot) for not having to deal with operations.

Real examples:

  • Elastic Cloud (managed Elasticsearch) vs self-hosted Elasticsearch

  • MongoDB Atlas (managed MongoDB) vs self-hosted MongoDB

  • Redis Enterprise (managed Redis) vs self-hosted Redis

  • GitLab Ultimate (managed GitLab) vs self-hosted GitLab

The pattern is consistent: take an open source project that requires significant operational expertise to run reliably, wrap it in managed infrastructure, and charge a premium.

The Direct Monetization Play: Developer Tools

For open source developer tools specifically, there’s a more direct path that has emerged in the past few years.

The model: Release a CLI tool or library as open source. Build a cloud service that enhances it. Charge for the cloud service.

Real examples:

  • Snyk — open source security scanning tools, paid cloud platform for teams

  • Dependabot — open source dependency updates (acquired by GitHub), GitHub Enterprise gets advanced features

  • GitHub Actions templates — open source action templates, paid premium versions with additional features

Why developer tools are different: Developers are willing to pay for tools that make them more productive. The “we’ll host it for you” model works when the alternative is hours of operational work. And the market is large enough that even small conversion rates generate real revenue.

Building Sustainable Open Source Economics

The developers who make real money from open source share certain characteristics:

They solve real problems. Not interesting technical challenges. Not “what if we rebuilt X in Rust.” Real problems that companies pay real money to solve.

They focus on developer experience. The open source projects that generate revenue are the ones developers enjoy using. Clear documentation, sensible defaults, helpful error messages, good API design.

They have patience. Open source monetization takes time. You build the software. People start using it. They build dependencies on it. Eventually, companies start paying. This process takes years, not months.

They combine models. The most successful open source businesses usually combine multiple monetization approaches: open core + SaaS + services + consulting. Pure donation models rarely work. Pure proprietary models lose community trust.

They engage the community. The most valuable asset an open source project has isn’t its code — it’s its community. Projects that nurture contributor communities, respond to issues thoughtfully, and maintain positive relationships with users generate more revenue than projects that don’t.

The Honest Numbers

Here’s what open source monetization actually looks like in 2026:

For a popular project (10K+ GitHub stars, 100+ companies using it in production):

  • Donation-based: $1K-10K/month

  • Open core (commercial features): $10K-100K/month

  • SaaS wrapper: $50K-500K/month

For a useful project (1K-10K stars, 10+ companies using it):

  • Donation-based: $100-1K/month

  • Consulting: $5K-30K/month

  • Open core: Often not viable — not enough companies to sell to

For a small project (<1K stars, individual users):

  • Donation-based: $0-200/month

  • Not viable for commercial monetization without significant growth

The median open source project generates no revenue. The top 5% generate the majority of revenue. This is not a median-income career path.

Getting Started

If you’re considering building an open source project with monetization in mind:

  1. Start with a real problem you’re solving for yourself. The best open source projects come from developers who were frustrated by existing solutions and built something better for their own use.

  2. Release early, not perfect. Get the software into users’ hands. Let the community shape the direction. Monetization comes later, after you have something valuable.

  3. Focus on developer experience. Documentation matters more than features. Sensible defaults matter more than configurability. Clear error messages matter more than clever architecture.

  4. Choose your license carefully. The license determines your monetization options. GPL prevents proprietary use. MIT/Apache allow everything. If you want dual licensing, you need a strong copyleft license.

  5. Think about monetization day one, but implement it year two. You need users before you can monetize. But you also need a plan for how you’ll eventually sustain development costs.

  6. Build in public. The most successful open source monetization stories involve developers who were genuinely excited about building something useful. That enthusiasm, shared publicly, attracts contributors and users naturally.

This guide reflects the open source monetization landscape as of May 2026. Verify specific platform terms and pricing before committing to any strategy.

This article contains affiliate links. If you sign up through the links above, I may earn a commission at no additional cost to you.

Ready to Build Your AI Business?

Get started with Systeme.io for free — All-in-one platform for building your online business with AI tools.

Why Stripe Didnt Cut It for Creators in Pakistan — and How We Built a Parallel Pipeline for $0.05 Per Transaction

The Problem We Were Actually Solving

Our creators in Lahore, Karachi, and Islamabad needed to receive payouts. Stripe didnt support Pakistani creators. PayPal wouldnt touch them with a ten-foot pole. Local banks had 24-hour settlement windows and 3% cross-border fees. We had to move money within minutes, not days, and we had to prove every cent was where it belonged before the next ad break.

The real engineering challenge wasnt the money—it was the data. Every payout triggered a cascade: ledger entries, fraud review, tax calculations, creator dashboard update, and an email receipt. If the pipeline lagged by more than 30 minutes, creators flooded support. If the numbers didnt match between our ledger and JazzCashs, the finance team locked the spreadsheet and emailed me at 2 a.m.

We measured success with one metric: latency from checkout to creator payout confirmation. Target: under 15 minutes end-to-end. Failure meant cancellations and refunds that cost us more than the transaction itself.

What We Tried First (And Why It Failed)

We bolted Stripe webhooks onto our Snowflake warehouse. Each webhook fired a JSON blob that landed in S3. An Airflow DAG read the blob, applied a CASE statement to map JazzCash transaction IDs, and wrote the row to the payout table. Expected latency: 2 minutes. Reality: 47 minutes.

The problem wasnt the warehouse—it was the staging layer. Airflows S3 sensor polled every 5 minutes. That introduced a 150-second blind spot. Worse, if S3 object creation timestamps showed up out of order (because of eventual consistency or JazzCashs retries), Airflow treated them as late and skipped them. We lost $12,400 in payouts before we noticed the silent failures.

I added a Kafka mirror of the webhook stream. Kafka read every message within 200 ms. Then I wrote a Python UDF in Snowflake that consumed the topic via a Kafka connector. Freshness improved to 8 minutes. Still not enough. The UDF blocked warehouse compute for two seconds per message, and our finance team started throttling the warehouse because report dashboards were timing out.

We tried Flink next. It achieved 90-second latency on a good day. But Flinks state backend was RocksDB on local disk. When the pod restarted, we replayed two hours of events. That violated our 15-minute SLA. Our SRE team refused to let Flink run in production until we added a Kafka exactly-once checkpointing layer—another three weeks of yak shaving.

The Architecture Decision

We ripped out the warehouse as a processing engine.

The new stack:

  • Ingestion: HTTP endpoints writing directly to Kafka topics sharded by country.
  • Stream processing: ksqldb in EC2 instances with 10-minute retention, exactly-once semantics, and disk snapshots every hour.
  • Storage: Iceberg tables on S3 with 5-minute compaction cadence.
  • Serving: Postgres read replicas for creator dashboards, updated via Debezium CDC from Iceberg tables.
  • Cost control: Spot instances for ksqldb, kept only during peak hours (6 p.m. to 11 p.m. Pakistan time).

Latency after go-live:

  • Checkout to Kafka: 200 ms
  • Kafka to ksqldb aggregation: 90 seconds
  • ksqldb to Iceberg: 2 seconds
  • Iceberg to Postgres: 15 seconds
    Total payout confirmation: 107 seconds.

We also instrumented a new metric: ledger drift. Every ksqldb query includes a checksum of the last 10,000 transaction rows. If the checksum changes between two consecutive runs, we trigger a PagerDuty alert and freeze the payout queue until teams reconcile. This caught a JazzCash duplicate event last month and saved us $8,200 in duplicate refunds.

Cost per transaction dropped from $0.22 on Snowflake/Airflow to $0.05 on spot Kafka + ksqldb + Iceberg. The finance team stopped complaining about warehouse bills.

What The Numbers Said After

Latency distribution over 30 days:

  • P50: 87 seconds
  • P95: 146 seconds
  • P99: 228 seconds
  • Breaches: 3 (all caused by JazzCash API brownouts)

Cost per million transactions:

  • Dec 2025: $18,100 (warehouse + Airflow)
  • Jan 2026: $4,500 (Kafka + ksqldb + Iceberg)
  • Feb 2026: $4,900 (added redundancy for spot failures)

Freshness SLA compliance:

  • Jan 2026: 98.7%
  • Feb 2026: 99.4%
  • Mar 2026: 99.9% (after adding a Redis cache for last-known balances)

These numbers arent abstract. When a creator in Faisalabad streams live and the dashboard says their payout arrived, its not a cache—its the ksqldb state file pinned in memory on ksqldb-03 at 9:15 p.m. that matches the JazzCash API response we received at 9:13 p.m.

What I Would Do Differently

I would not have tried to make Snowflake the center of the universe for a real-time ledger. Warehouses are for analytics, not for 100 transactions per second.

I would have started with a topic-per-country design from day one instead of sharding later. Our first Kafka cluster had a single topic with 50 partitions. Adding a country caused partition rebalances that dropped throughput 40% for 20 minutes. Now we have topic patterns like payments-pakistan-live. No more rebalances.

I would skip Flink entirely unless I needed stateful joins longer than 24 hours. ksqldbs windowed aggregations are simpler and keep the state in memory instead of RocksDB, so pod restarts only lose the last 30 seconds of

Why Long-Running AI Agents Break on HTTP, and How Ably’s Durable Sessions Fix It

An AI agent that summarizes a paragraph finishes in two seconds. An AI agent that researches a question, calls six tools, and drafts a report can run for four minutes — or forty. The first fits HTTP comfortably. The second fights it the whole way.

Most agent backends are still wired the way web apps have been wired since the 1990s: a client sends a request, the server sends a response, the connection closes. That contract holds because the response usually arrives fast enough that nobody notices the connection was open at all. Long-running agents break the contract. They produce output gradually, they outlive the patience of every proxy between client and server, and they keep working even after the user closes the tab. We dug into why this fails so often, and how Ably’s durable session model is built to absorb it.

Where HTTP runs out of road

HTTP’s request-response cycle assumes a short, bounded exchange. Three things go wrong once an agent runs for minutes instead of milliseconds.

Idle timeouts close the socket. Your connection passes through load balancers, reverse proxies, and CDNs, and each one drops connections that go quiet. An AWS Application Load Balancer closes idle connections after 60 seconds by default. An agent that reasons for 90 seconds before emitting its first token has already lost the socket underneath it.

Streaming is still one fragile pipe. Server-Sent Events and WebSockets hold the connection open and solve the timeout, which is why most agent UIs use them today. But the stream is bound to a single TCP connection. When a phone switches from Wi-Fi to cellular, a laptop sleeps, or the server is redeployed mid-task, that connection dies — and every token emitted during the gap is gone. The agent kept running on the server; the client simply stopped hearing it.

Nothing remembers what was missed. Reopen the connection and you get a fresh stream from that instant forward. HTTP gives you no way to ask which messages arrived between second 30 and second 95. The protocol has no concept of a session that outlives the socket.

The naive fix — let the client reconnect and re-issue the request — quietly doubles your bill and corrupts state. If the original run is still executing server-side, a retry starts a second one. Now two agents call the same tools, write the same files, and bill you twice for tokens. Reconnection has to resume an existing session, not start a fresh one.

What durable sessions actually mean

Ably’s approach is to stop treating the session and the connection as the same object. A durable session is a logical channel that lives on the server; the WebSocket connection is just a temporary attachment to it. Three mechanisms make that work.

Decoupled lifecycle. The agent publishes to a channel, not to a socket. The session exists whether or not a client is currently listening. The user can shut the laptop, the agent keeps running, and the messages wait on the channel.

Message persistence and replay. Every message gets an ID and is retained for a configurable window. Ably’s history and rewind features let a reconnecting client ask for everything since a given message ID and receive the gap in order — no tokens lost, no duplicates inserted.

Connection state recovery. When a client reconnects inside the recovery window — roughly two minutes by default — Ably restores the prior connection state and resumes delivery from the last message the client acknowledged. To the application, the interruption never happened.

Presence sits alongside these three: the server can see whether a human is currently attached, so an agent can decide whether to stream every token or just checkpoint its progress and notify the user later.

Patterns for infrastructure that survives a dropped connection

You don’t need Ably specifically to apply the ideas, but you do need to design for them on purpose.

Give every message a monotonic ID. Ordering and gap detection are impossible without one. The client tracks the last ID it processed, and reconnect logic replays from there.

Make the session the unit of work, not the request. Store run state — current step, tool calls, partial output — keyed by a session ID the client holds. Reconnection re-attaches to that ID; it never re-submits the prompt and never starts the agent over.

Guard every side effect. Even with clean resume logic, a tool call that fires twice should not double-charge a card or send two emails. Put an idempotency key on each external action.

Separate “the agent finished” from “the client got the result.” Persist the final output, and treat delivery as its own retryable step. An agent that completes while the user is offline should still deliver when they return.

Done together, these patterns turn a dropped connection from a lost task into a resumable one — the difference between an agent demo and an agent users trust with a forty-minute job.

Common questions

Originally published at pickuma.com. Subscribe to the RSS or follow @pickuma.bsky.social for new reviews.

Anthropic vs OpenAI: What the Latest Releases Mean for AI Developers

Every few weeks, Anthropic or OpenAI ships something: a new model, a cheaper tier, a new API primitive. If you build on either platform, most of that news never touches your code. The announcements that matter sort into three buckets — model capability, pricing structure, and API surface — and only two of them usually justify a change. We read through the recent release cycle from both labs and sorted what changed so you can tell a refactor from a headline.

Capability gains rarely change your architecture

A new model topping a benchmark chart is the most-shared release news and the least useful. Headline scores on reasoning or coding suites tell you little about whether a model holds up on your prompts. What changes your architecture is narrower: a larger context window, more consistent tool calling, or a reasoning mode you can toggle per request.

Anthropic’s lineup splits along a clear axis — Opus for hard reasoning, Sonnet for the default workload, Haiku for cheap high-volume calls. OpenAI’s tiered lineup does the same thing under different names. The practical signal from the recent cycle is that the gap between the mid tier and the top tier has narrowed for everyday tasks. If you default to the most expensive model “to be safe,” the current mid tier probably handles your traffic now — but you only find that out by running your own eval set, not by reading a launch post.

Extended reasoning is the capability shift worth wiring in. Both labs expose a mode where the model spends more tokens thinking before it answers, and you control it per call. That turns model selection into a routing decision: a fast path for simple requests, a reasoning path for the fraction that genuinely need it.

Pricing is now an architecture decision

The pricing changes from the last cycle do more to your bill than any benchmark gain does to your output quality. Three features are worth building around.

Prompt caching is the one to design for first. If your requests share a large stable prefix — a system prompt, a tool schema, a retrieved document — caching bills those tokens at roughly a tenth of the normal input rate on a cache hit. For a RAG app or an agent with a heavy system prompt, that is the difference between a sustainable margin and a cost spiral. It is not automatic: you have to structure prompts so the stable part comes first and mark the cache boundary explicitly.

Batch endpoints take roughly 50% off when you can tolerate a delayed response — useful for evals, bulk generation, and overnight enrichment jobs. And the cheaper small-model tiers from both labs are now strong enough that classification, routing, and extraction no longer need a flagship model.

The pattern is the same on both platforms: stop sending every request to one model. Route by task, cache aggressively, and batch whatever you can defer.

Before you switch models or platforms on the strength of a release, run your own eval set against both the old and new model. A 20-prompt suite that mirrors your real traffic catches regressions that public benchmarks hide — and it takes an afternoon to build.

API surface: where lock-in actually happens

Model weights are replaceable. The API surface around them is where you get stuck. The recent releases lean heavily into agent tooling, and that is where to move deliberately.

Anthropic has pushed the Model Context Protocol, an open standard for connecting models to tools and data sources. Because it is a spec rather than a proprietary endpoint, an MCP server you build works with any client that speaks the protocol. OpenAI’s Responses API consolidates tool use, state, and multi-step calls into one stateful endpoint — convenient, but it ties that orchestration logic to OpenAI’s shape.

Neither choice is wrong. The mistake is letting either platform’s agent framework spread through your codebase unchecked. Keep a thin adapter between your application logic and the provider SDK: one module that takes your request and returns your response, with provider-specific calls hidden behind it. When the next release makes the other platform cheaper or smarter, switching becomes a one-file change instead of a quarter-long migration.

That is also why model-agnostic tooling has an edge right now.

Tools that let you swap the underlying model — in your editor, your agent runtime, your eval harness — turn each release from a disruption into an option. You test the new model on a Friday, then keep it or roll back, without rewriting anything around it.

Originally published at pickuma.com. Subscribe to the RSS or follow @pickuma.bsky.social for new reviews.