
Vellum — a private, on‑device screenshot assistant powered by Gemma 4

Vellum Main UI

This is a submission for the Gemma 4 Challenge: Build with Gemma 4

What I Built

Vellum is a tray‑resident macOS app that turns any screenshot into a conversation. Hit ⌘⇧1 to drag a region, or ⌘⇧2 to grab the whole screen — the capture pops open in a chat window, the image is described and OCR’d in the background, and you can immediately ask follow‑up questions about what’s on screen.

The interesting bit: Vellum runs Gemma 4 locally on Apple Silicon by default. No screenshot ever leaves the machine. There’s no account, no API key, no cloud round‑trip — just a global hotkey and a vision‑language model living in your menu bar.

How I actually use it: over a few days I capture screenshots of things I read on the internet — articles, threads, diagrams, half‑finished thoughts — and let them pile up. Then one evening I sit down and review the whole stack. Because every capture is OCR’d by Gemma 4, the pile is fully searchable, and the review session turns into something more useful than a screenshot graveyard:

  • Capture now, think later. Grab anything interesting with ⌘⇧1 and keep reading — no context switch, no “where do I save this”.
  • OCR everything automatically. Gemma 4 reads the text out of each image on capture, so I can search across days of captures by what was in them, not just when I took them.
  • Review in one sitting. An evening pass over the gallery surfaces patterns I’d never have spotted scrolling live.
  • New blog‑post ideas. Asking Gemma about a cluster of related captures regularly hands me an angle for something I want to write.
  • Organize with tags. Group captures into themes so the next review starts already sorted.

A few quality‑of‑life touches that make the review session flow:

  • One‑click “Copy for Slack / JIRA”. From the capture’s action bar, Vellum puts the image and a ready‑to‑paste blurb on the clipboard — Gemma 4’s description plus the tags, formatted for each tool (Slack mrkdwn or Jira markup). Paste straight into a thread or ticket.
  • “Copy with shadow” for a polished share. One click composites the raw screenshot onto a transparent canvas with padding, rounded corners and a soft drop shadow, then drops it on the clipboard — the kind of framed shot you’d otherwise reach for a separate tool to make.
  • Plain “Copy image” for everything else.

Each action also has a ⌘1…9 shortcut, so the whole review‑and‑share loop stays on the keyboard.

Source + install script (one curl line for Apple Silicon): https://github.com/arunkant/vellum

Demo

Screenshots:
Vellum Main UI
Vellum ai sidepanelVellum search screenshots
Vellum Tray widget

Install on macOS (Apple Silicon):

curl -fsSL https://www.arunkant.com/vellum/install.sh | bash

How I Used Gemma 4

Vellum bundles llama.cpp‘s llama-server as an extraResource and, on first use of the local provider, downloads:

  • gemma-4-E4B-it-Q4_K_M.gguf — Google’s vision‑capable Gemma 4 E4B‑it, quantized to Q4_K_M (~5 GB).
  • mmproj-BF16.gguf — the multimodal projector that lets Gemma 4 actually look at pixels.

Both come from Unsloth’s GGUF mirror of the official google/gemma-4-E4B-it. The server is launched lazily the first time the user takes a screenshot, then kept warm for the rest of the session.

The request flow is a regular OpenAI‑compatible vision call to localhost — Gemma 4 happily accepts an image part next to a text part:

// src/ai/local.ts
await net.fetch(`${serverEndpoint()}/v1/chat/completions`, {
  method: 'POST',
  body: JSON.stringify({
    model: 'gemma-4-e4b',
    messages: [{
      role: 'user',
      content: [
        { type: 'text', text: req.prompt },
        { type: 'image_url', image_url: { url: imageToDataUrl(req.imagePath) } },
      ],
    }],
    max_tokens: req.maxTokens ?? 2000,
    temperature: 0.2,
  }),
});

The launcher arguments are deliberately conservative so it fits comfortably alongside a browser and an IDE on a 16 GB MacBook:

// src/ai/llama-server.ts
const args = [
  '-m', modelPath(),
  '--mmproj', mmprojPath(),
  '--host', '127.0.0.1',
  '--port', String(port),
  '-c', '8192',
  '--no-webui',
];

Two prompts drive everything:

  1. Auto‑analysis — a short instruction asking Gemma 4 to describe the app/page and pull out the most important visible text, runs the moment a capture lands.
  2. Chat — every user message is forwarded with the original image still attached, so Gemma can ground each answer in the pixels rather than its own prior summary.

The same VisionProvider interface is also implemented by an OpenRouter‑backed provider, so users who want a beefier hosted model can swap in one without touching the rest of the app. Gemma 4 is the default, and it’s the only path that works fully offline.

Multimodal Insights

A few things I learned shipping Gemma 4 to end‑users:

  • The 4B/E4B vision model is genuinely shippable. It comfortably reads UI text, error dialogs, and code editors, and an 8k context (-c 8192) is plenty for a single screen capture.
  • The multimodal projector is the easy thing to forget. Without --mmproj, the model will silently treat the image like noise. Vellum downloads it alongside the weights and refuses to start the server if either file is missing.
  • Q4_K_M is the right tradeoff for laptops. It keeps the whole thing under ~5 GB on disk, leaves headroom for a browser, and the quality cost on screenshot tasks is invisible to me in practice.
  • I run Gemma at a low temperature: 0.2. Screenshot Q&A wants literal, deterministic answers rather than creative ones, so a low temperature is the safer default.

Why Gemma 4 for this app

I built Vellum around a habit: capturing things I read over days, then reviewing the pile in one sitting. That only works if every capture is OCR’d and searchable the moment I take it — and I’m not about to stream days of half‑formed reading habits and private dashboards to a third‑party endpoint just to make that happen. An open‑weights vision model I can bundle and ship inside an Electron app is the only way that problem actually gets solved: it runs the moment I hit ⌘⇧1, with no account, no API key, and no network hop. Gemma 4 E4B‑it is the first model in this size class where the OCR and the follow‑up answers are consistently good enough that I stopped reaching for the cloud fallback.

Tech stack

  • Model: google/gemma-4-E4B-it (Q4_K_M GGUF, BF16 mmproj) via Unsloth
  • Runtime: llama.cpp llama-server, bundled per‑arch as an Electron extraResource
  • App shell: Electron + Vite + TypeScript, packaged with Electron Forge
  • Storage: SQLite for screenshots + AI results + chat history; images on disk
  • Auto‑update: GitHub Releases + a tiny installer script served from GitHub Pages

Links

Thanks to the Gemma team for shipping a vision model small enough to live in a menu bar, and to the llama.cpp and Unsloth communities for making GGUF inference this painless.
Seasons time-lapse – the foundations

I live close to nature. I regularly go for a run in the countryside. Over several years, during my runs, I’ve taken pictures from the same position, always roughly the same angle. I had a vague idea in the back of my mind, as an “artistic” project. One day, I’d turn those photos into a time-lapse video, one that would show the passage of seasons across a single place.

Spoiler, here’s the work in progress:

However, I knew that this project would take ages. I have no experience in image manipulation and video making. My knowledge of codecs is that the movie I have doesn’t play on my Internet box.

The amazing progress in coding assistants made this project possible. I hate the term “vibe coding”, and I hope I provided accurate technical direction, but I admit I didn’t do anything on my own. I just fed my instructions to the assistant, and it did the job.

In this multi-part series, I aim to reflect on my actions. There’s no reason why we can’t have a useful retrospective in LLM-assisted projects.

In any regular project, choosing your stack is the most important part. You can refer to Choosing a dependency for them. Vibe-coding adepts will gladly tell you that code is not an asset anymore, but that you can (and should) discard it and start from scratch at every iteration.

After describing my idea and its foundation, I asked the assistant whether to choose between the JVM, Python, or any other stack. It chose Python. At several steps in the process, I asked it to reassess its choice again. Still Python.

My argument for performance got rebuked:

The performance argument doesn’t apply. The slow parts — OpenCV operations, neural inference — run as C++/CUDA/Metal underneath regardless of whether you call them from Python or Java. Python’s interpreter overhead is irrelevant here.

To keep things in check and help the assistant, I enforce types and tests.

The project is fundamentally a processing pipeline. Steps are:

  1. Inventory: glob all configured directories for photos and extract EXIF metadata, date, focal length, GPS coordinates.
  2. Filter: keep only photos taken within 100 metres of a configured reference GPS point. Many photos lacked GPS data entirely, those are dropped.
  3. Align: warp each photo so it looks like it was taken from exactly the same angle as a reference image. This is the hard part, and it gets its own post.
  4. Order: sort the aligned frames according to a simple algorithm. I chose by day-of-year and time-of-day to assemble a composite year from photos taken across multiple real years.
  5. Render: encode the ordered frames into a video.

The pipeline is driven by a config file at the project root:

[input]
dirs = ["/path/to/photos/1", "/path/to/photos/2"]        # 1
extensions = [".heic", ".jpg", ".jpeg"]                  # 2

[reference]
dir = "reference"
latitude = 46.135536
longitude = 6.111831

[filter]
gps_radius_m = 100.0

[output]
fps = 12
blend = true
  1. The autosave application changed its default location
  2. I changed my phone as well

GPS coordinates are mandatory. The pipeline fails early if they’re missing. Without them, the filter step has nothing to anchor to.

To iterate more quickly, I weaved in a --sample flag to run the full pipeline on a random subset of photos. A full run processes hundreds of images and takes minutes; a 50-image sample takes seconds. Iterating on the alignment code was initially too time-consuming without sampling.

The inventory, filter, order, and render steps are largely straightforward. Alignment is not. In the next part, I’ll describe how I went from a naive approach that produced wobbly, misaligned frames to a neural matcher that gets most frames right.

Originally published at A Java Geek on May 17th, 2026.

How to Measure AI Coding Agents Beyond Lines of Code and PR Acceptance Rates

Your team rolled out an AI coding agent three months ago, and leadership wants a number that proves the seat licenses paid off. The dashboard offers two easy ones: lines of code generated, and the share of AI-assisted pull requests that got merged. Both are trivial to pull, both look healthy, and both will steer you wrong.

Why the Easy Metrics Lie

Lines of code has been a discredited productivity measure for decades, but agents make it actively dangerous. An agent will produce 400 lines where 40 would do — boilerplate, defensive checks for inputs that cannot occur, a helper it did not notice already existed three files over. Counting that output as productivity rewards the exact behavior you want to suppress. Teams getting real value from agents often watch their net diff shrink, because the agent is also deleting dead code and collapsing duplicated abstractions.

PR acceptance rate is more seductive, because it sounds like a quality signal. It is not. One figure that circulated in this debate: the KubeStellar project reportedly merged 81% of its AI-assisted pull requests. Read that carefully. It tells you 81% of those PRs cleared review. It tells you nothing about whether they should have been opened, whether they introduced defects found weeks later, how many review rounds each one cost, or whether the merged code was still in the codebase a month on.

An 81% acceptance rate is just as consistent with reviewers rubber-stamping output they did not fully read as it is with genuine quality. AI-assisted PRs are often smaller and more numerous, which inflates acceptance rate while quietly raising the total review burden across the team. The metric measures a reviewer’s willingness to click merge — not the agent’s contribution to the product.

If a metric goes up when an agent produces more code regardless of whether that code was needed, it is a vanity metric. Lines of code, commit count, and raw PR throughput all fail this test. Treat them as activity logs, not scorecards.

What to Track Instead

The useful question is not how much the agent produced, but what its output cost and how long it lasted. Four measurements cover most of that, and you can derive all of them from data already sitting in Git and your incident tracker.

Metric What it catches Where it comes from
Code survival rate Agent output rewritten or deleted within 3-4 weeks git blame history on agent-authored lines
Review rounds per PR Cost shifted from author to reviewer PR review timeline
Change failure rate Whether agent-assisted changes break production more often Incident tracker, PRs tagged
Commit-to-deploy time Whether the agent shortens delivery, not just authoring Deployment pipeline

Code survival rate is the hardest of the four to game. If 60% of an agent’s lines are gone within a month, the agent generated rework, not progress — and rework is invisible to both lines of code and acceptance rate. Change failure rate is one of the four DORA metrics, and commit-to-deploy time maps onto DORA’s lead time for changes, so you can compare AI-assisted changes against a baseline the industry already understands instead of inventing a scale.

Pair the quantitative side with one qualitative measure. The SPACE framework’s central argument is that developer productivity is multidimensional and cannot collapse into throughput. A recurring two-question survey — did the agent reduce or add friction this week — catches problems Git data cannot, like an agent that produces mergeable code while making the codebase harder to reason about.

Before you roll an agent out team-wide, record two weeks of baseline numbers without it. A metric with no “before” value can be argued into meaning almost anything. The baseline is what turns your post-rollout numbers into evidence.

Running the Measurement Without Drowning in Dashboards

You do not need a metrics platform. Pick two measurements — code survival rate and review rounds per PR make a strong starting pair — and track them in a spreadsheet or shared doc for one quarter. Tag the PRs that used an agent so you can compare cohorts cleanly. Resist adding a third and fourth metric until the first two have told you something, because every metric you track is a number someone has to interpret, defend, and argue about in a review meeting.

Keep the comparison fair. The honest baseline is not the agent versus no tooling — it is the agent versus a developer with ordinary IDE autocomplete and a linter. Copilot, Cursor, and Claude Code also behave differently enough that blending them into one “AI” bucket hides the answer: an inline-completion tool, an editor-native agent, and a terminal agent each shift work to a different stage of the cycle. Measure each as its own cohort.

One trap deserves a name. Do not let the agent write the tests that validate its own code without a human reading them. An agent that generates both the implementation and a passing test suite can post a flawless acceptance rate while testing nothing real. Code survival rate will expose that eventually; a reviewer who actually reads the tests exposes it on day one.

None of this is about policing the agent. It is about learning, with evidence, where the agent genuinely helps your team and where it quietly shifts cost downstream — so the next renewal decision rests on data instead of a lines-of-code chart that was never measuring the right thing.

Originally published at pickuma.com. Subscribe to the RSS or follow @pickuma.bsky.social for new reviews.

Recruiters do not care about your tools list

Your impressive list of JavaScript frameworks and libraries is probably gathering dust.

That’s right. While we developers obsess over the perfect build tool setup or the latest CSS-in-JS solution, the folks reviewing your resume often couldn’t care less. It’s a tough pill to swallow, but let’s break down why.

Recruiters are scanning for keywords, sure, but their primary goal is to see if you can solve problems. They’re not trying to hire a JavaScript framework connoisseur. They’re trying to fill a role that requires specific skills to deliver a product. A list of technologies without context is just noise.

Think about it. If you list “React, Vue, Angular, Svelte, Next.js, Nuxt.js,” what does that really tell them? That you’ve dabbled? That you’re indecisive? Or that you’re a master of all? It’s vague. Instead, focus on what you built with those tools.

Imagine this scenario: A job post asks for experience building e-commerce sites with a focus on performance. Instead of:

  • React, Redux, Webpack, Babel
  • Node.js, Express
  • PostgreSQL

Try something like:

  • Developed a high-performance e-commerce platform using React and Next.js, resulting in a 30% improvement in page load times.
  • Implemented server-side rendering with Node.js and Express to optimize SEO and initial load.
  • Managed product data and user interactions with a PostgreSQL database.

See the difference? It’s about impact and accomplishment, not just a toolkit dump.

Even the code samples you showcase should tell a story. For instance, a snippet demonstrating efficient state management or a well-structured API endpoint speaks volumes more than just listing “state management” or “API integration.”

// Instead of just listing "state management"
function UserProfile({ userId }) {
  const { data: user, isLoading, error } = useFetchUser(userId);

  if (isLoading) return <p>Loading...</p>;
  if (error) return <p>Error: {error.message}</p>;

  return (
    <div>
      <h2>{user.name}</h2>
      <p>{user.email}</p>
    </div>
  );
}

This shows how you handle asynchronous data and potential loading/error states, which is far more valuable.

The takeaway? Focus on demonstrable achievements and the problems you’ve solved. Your resume is your highlight reel, not your entire toolbox. Recruiters want to see what you can do, not just what you know how to spell.

As a freelancer myself, I build websites and focus on delivering tangible results for clients. If you’re looking for someone who translates technical skills into business value, you can check out my services at https://hire-sam.vercel.app/.

Save this if useful.

resumetips #careertips #webdevelopment #devlife

Building a Monte Carlo Retirement Simulator in Python

A retirement projection built on a single number — “assume 7% per year” — answers the wrong question. It tells you what happens on one perfectly smooth path that the market has never actually delivered. Real returns arrive jagged: a strong decade, a flat stretch, a crash three years before you plan to stop working. A Monte Carlo simulation replaces that single path with thousands of them, and the output stops being a number and becomes a distribution. This walks through building one in Python and, more importantly, understanding what it can and cannot tell you.

Why a Single Average Return Lies to You

The standard projection uses the deterministic compound-growth formula: start with a balance, multiply by (1 + r) every year, subtract withdrawals. It is easy to put in a spreadsheet and it produces a clean curve. The problem is that the clean curve corresponds to a sequence of identical annual returns, and no such sequence has ever occurred.

The full set of returns over 30 years does determine your ending balance if you never withdraw — multiplication is commutative. But the moment you take money out, the order of returns matters. A bad year early in retirement forces you to sell more shares to fund the same withdrawal, and those shares are gone before any recovery can compound them. Two retirees with the identical 30-year average can end up with wildly different outcomes depending on when the bad years landed. A single-average projection cannot see this. It computes one path and hides the distribution of paths around it.

What a Monte Carlo Simulation Actually Does

The technique is mechanically simple. You assume a distribution for annual returns — for example, a mean and standard deviation estimated from long-run historical data. Then you:

  1. Draw a random return for each year of the projection horizon.
  2. Run your withdrawal logic year by year on that random sequence.
  3. Record whether the portfolio survived and what it ended at.
  4. Repeat thousands of times.

The result is not “your portfolio will be worth X.” It is “across 10,000 simulated futures, the portfolio survived in 87% of them, and here is the spread of ending balances.” That success rate, and the shape of the distribution, is the actual deliverable.

A Minimal Simulator in Python

The core is about 20 lines of NumPy. Everything else is interpretation.

import numpy as np

def simulate(start, withdrawal, years, mean, std, trials=10_000):
    # Draw a (trials x years) matrix of random annual returns
    returns = np.random.normal(mean, std, size=(trials, years))
    balances = np.full(trials, float(start))
    survived = np.ones(trials, dtype=bool)

    for y in range(years):
        balances = balances * (1 + returns[:, y]) - withdrawal
        survived &= balances > 0
        balances = np.clip(balances, 0, None)

    return {
        "success_rate": survived.mean(),
        "p10": np.percentile(balances, 10),
        "p50": np.percentile(balances, 50),
        "p90": np.percentile(balances, 90),
    }

result = simulate(
    start=1_000_000, withdrawal=45_000, years=30,
    mean=0.05, std=0.12,            # illustrative real-return assumptions
)
print(result)

The numbers passed in here are illustrative, not a recommendation. A real run should use return and volatility assumptions you can defend, expressed in real (inflation-adjusted) terms so the withdrawal stays in constant dollars.

Working in real returns — subtracting expected inflation from the nominal mean — lets you hold the withdrawal constant across years. The alternative is to model nominal returns and inflate the withdrawal each year. Pick one convention and apply it consistently; mixing them is the most common bug in homemade simulators.

Reading the Output: Percentiles, Not Averages

The instinct is to look at the median ending balance and call it the answer. Resist it. The two outputs that matter are the success rate and the lower percentiles.

The success rate is the fraction of simulated paths where the portfolio never hit zero. A 95% success rate means 1 in 20 simulated futures ran out of money. Whether that is acceptable is a personal judgment, not a technical one — but you cannot make the judgment without the number.

The lower percentiles describe the bad-but-not-impossible cases. The P10 ending balance is the outcome that 90% of paths beat. If the P10 is a comfortable cushion, the plan is robust. If the P10 is zero, the plan depends on the market cooperating, and the median balance is cold comfort. This is the same reason you look at P99 latency instead of average latency when you operate a service: the average hides the tail, and the tail is what hurts.

Run the simulation twice with the withdrawal as the only variable. The gap between, say, a 4% and a 4.5% withdrawal rate often moves the success rate more than any plausible change in your return assumptions. Spending is the lever you actually control.

Where the Model Is Wrong

A simulator is only as honest as its assumptions, and the minimal version above makes several that are convenient rather than accurate.

Normal distributions understate tail risk. Real market returns have fatter tails than a normal distribution — extreme years happen more often than the bell curve predicts. Drawing from np.random.normal produces crashes that are too mild and too rare. Using a Student’s t-distribution, or resampling from actual historical years (bootstrap), gives a more realistic tail.

Returns are not independent. The model treats each year as an independent draw. Real markets show some mean reversion over long horizons and volatility clustering over short ones. Independent draws miss both.

Fixed withdrawals are unrealistic. Almost nobody spends an identical inflation-adjusted amount through a 25% drawdown. Modeling a flexible rule — spending less in bad years — changes the success rate substantially and reflects how people actually behave.

Taxes and fees are missing. The minimal model ignores both. A 0.5% annual fee and the tax drag on a taxable account are real subtractions from the return every single year.

A Monte Carlo simulator produces precise-looking numbers from imprecise inputs. An 87.3% success rate carries false authority — the third digit is noise. Treat the output as a way to compare scenarios and stress-test assumptions, not as a forecast. The value is in the relative comparison, not the absolute figure.

The point of building your own simulator is not that it beats established tools like cFIREsim or the research behind the 4% rule. It is that writing the loop forces you to make every assumption explicit. You cannot hand-wave the return distribution when you have to type it into np.random. That explicitness — seeing exactly which inputs the answer depends on — is worth more than the answer itself.

Originally published at pickuma.com. Subscribe to the RSS or follow @pickuma.bsky.social for new reviews.

ShareBox: self-hosted file sharing with video streaming in pure PHP

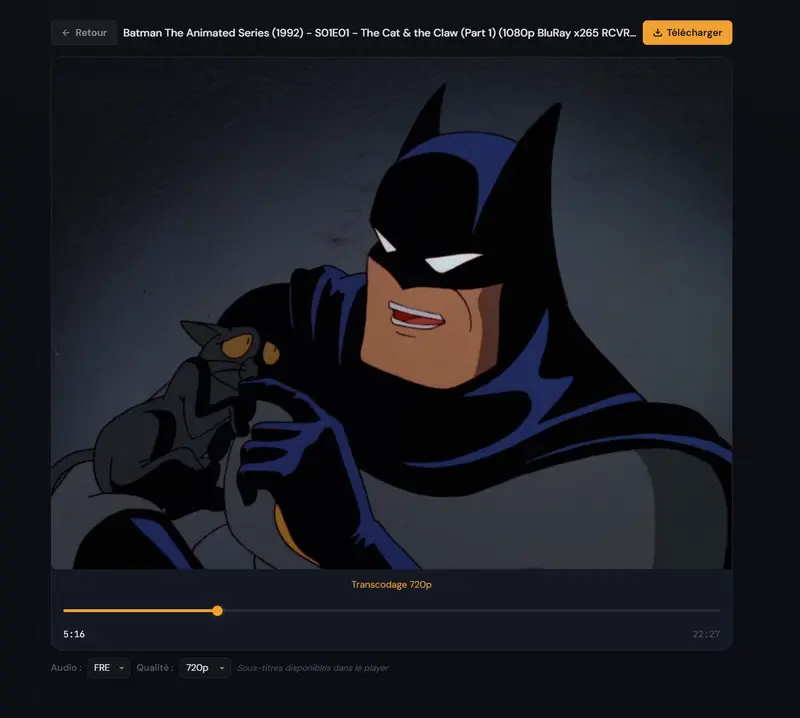
ShareBox integrated video player with seek, quality selection and WebVTT subtitle support

The need was straightforward: share large files — tens of gigabytes of raw footage, project archives, training videos — without going through a third-party cloud. No Google Drive, no WeTransfer, no Dropbox. A dedicated server, files you control, links that expire when you want them to. The result: ShareBox, a self-hosted file sharing platform with integrated video streaming, written in pure PHP 8.1 with no framework.

The repo is on GitHub.

Zero runtime dependencies

The first decision — and the most consequential — was to avoid any framework. No Symfony, no Laravel. Pure PHP, native stdlib, SQLite auto-created on first boot. Composer is present, but only as a dev dependency for PHPUnit. In production, no vendor/ directory is needed.

This constraint is clarifying. Every feature must justify its real implementation cost — not outsourced to a package that does ten times what you need. Manual routing in a few dozen lines, native PHP session handling, SQLite queries via PDO: these are things you implement once and understand completely.

SQLite followed the same logic — no server to configure, no complex migrations, the database file lives next to the code and backs up with a simple cp. For a single-instance tool, it’s more than enough.

The installer follows the same principle — a one-liner for Debian/Ubuntu:

curl -sSL https://raw.githubusercontent.com/ohugonnot/sharebox/main/install.sh | bash

A script that installs system dependencies, configures Apache or nginx, creates the SQLite database, and sets correct permissions. No Docker required, no registry to contact.

The real challenge: video streaming

Sharing a text file or a ZIP archive is trivial. Sharing a video and letting someone watch it directly in the browser — with seek, audio track selection, subtitles — is a different problem.

The first decision was to avoid systematic transcoding. If the file is already in a browser-compatible format (H.264/AAC in an MP4 or MKV container), we do a remux on the fly: repackage the existing streams without re-encoding. FFmpeg takes a few seconds, CPU usage is near zero, and quality is identical to the source.

Full transcoding only kicks in when necessary — typically for HEVC/x265 files, which very few browsers decode natively. In that case, FFmpeg transcodes to H.264 on the fly, with quality selection: 480p, 720p, or 1080p.

Seek in a live-transcoded stream is the trickiest part. A Range: bytes=... request on a classic HLS stream works because segments are pre-generated. Here, the stream is generated in real time — so seek means restarting FFmpeg with -ss at the right timecode, rather than seeking a byte offset in an already-generated file. The code orchestrating this in stream.php is worth reading if you’re tackling a similar problem.

ShareBox integrated video player with seek, quality selection and WebVTT subtitle support

The integrated video player: native seek, quality selection, WebVTT subtitles.

Human-readable slugs

A UUID to identify a share is secure but unusable by humans. Getting /dl/3f7a2c1d-8b4e-4f9a-b2d6-1c5e8f3a7b2c in an email is opaque. ShareBox generates slugs from the filename:

batman-begins-2005.mkv  →  /dl/batman-begins-2005-x7k2

The 4-character random suffix is enough to avoid collisions without sacrificing readability. batman-begins-2005-x7k2 tells you immediately what it contains, is easy to copy by hand, and survives a message or URL without issues.

Slug generation normalizes the string: accent transliteration, lowercase conversion, replacement of spaces and special characters with hyphens, removal of consecutive hyphens. The result is then checked against the database for uniqueness before insertion.

Security without a framework

A framework quietly handles a lot of security concerns — often without the developer being aware of it. Without a framework, these concerns must be addressed explicitly. Four stood out as needing careful attention.

Directory traversal. When serving files from disk, you have to ensure a parameter like ../../../etc/passwd doesn’t get through. The solution: realpath() on the resolved path, then verify the result is a subpath of the allowed upload directory. If the resolved path escapes the target directory, the request is rejected.

CSRF protection. The admin panel exposes destructive actions (file deletion, link revocation). Every POST form includes a CSRF token stored in session, regenerated after each sensitive action.

Session fixation. After authentication, session_regenerate_id(true) is called to invalidate the old session identifier and issue a new one. Without this, an attacker who knows the session ID of an unauthenticated visitor can reuse it after login.

Mail header injection. The email sharing form accepts a destination address. Without strict validation, an attacker can inject additional SMTP headers into the email field and hijack the outgoing message. All user inputs destined for mail headers are filtered to strip newlines before being passed to sending functions.

ShareBox admin panel with list of shared files, stats and management actions

The admin panel: share management, expiration, password protection.

Tests: what’s actually worth covering

44 PHPUnit tests, no mock framework, no external test dependency. The question wasn’t “how to test everything” — it was “what breaks silently if we don’t test it.”

Three categories stood out as particularly valuable:

Slugs. Slug generation is a pure function with many edge cases: names with accents, multiple spaces, Unicode characters, collisions, filenames without extensions. Thorough tests on this function are worth their weight in gold — it’s exactly the kind of code that looks trivial and breaks unexpectedly on real input.

Format detection. The logic deciding whether a video can be remuxed or must be transcoded relies on reading FFprobe metadata. Testing with FFprobe output fixtures for different codecs (H.264, HEVC, VP9, AV1) ensures the remux/transcode decision is correct without needing actual video files in the test suite.

Security. Directory traversal tests, header injection tests, and CSRF token validation tests are the most valuable. These are well-documented attack vectors, easy to test with known payloads, and missing an edge case has direct consequences.

ShareBox folder sharing view with file list and ZIP download button

Folder sharing: file browsing, one-click ZIP download.

Conclusion

The “zero runtime dependencies” philosophy isn’t a stance. It’s a commitment to understanding and maintaining what you build. Every line of code in ShareBox has an explicit reason to exist — no magic hidden in a third-party component whose source you’ve never read.

The concrete lesson from this project: PHP is capable of adaptive video streaming, seek in live transcoding, and correct security — with no framework whatsoever. The difficulty isn’t in the language; it’s in understanding what you’re building.

The code is available at github.com/ohugonnot/sharebox.

XSLT performance tuning without losing readability

Performance problems in XSLT are sneaky. The stylesheet looks clean, the output is correct, but the transform slows down as the input grows. Most of the time this is caused by expensive selections that are repeated in loops, or by deep // searches that scan the entire tree more often than you expect. The good news is that you can usually fix these issues without turning the stylesheet into unreadable micro-optimizations.

The first step is to examine where you are traversing the document. XSLT processors are optimized for template matching, so prefer xsl:apply-templates and specific match patterns over xsl:for-each with // in the select. When you do need a search, limit it to the smallest possible subtree. A single // at the top-level becomes a full-tree scan each time it runs. If it runs inside another loop, the cost can explode.

Keys are the most important performance feature, and they also improve readability. When you define an xsl:key, you turn a repeated search into a fast lookup. This is especially critical for join-like operations where you match a reference value to another document or a secondary section of the same document. Build the key once, and then use key('id', $value) everywhere. The intent becomes clear: you are doing a lookup, not a scan. If you only use keys occasionally, it can feel like overkill, but it is often the biggest win.

Modes are another useful tool. If you use the same templates in multiple contexts, you may end up doing extra work or firing templates that you do not need. A dedicated mode lets you create a focused processing pipeline that touches only the nodes relevant to that output section. This can reduce both runtime and mental overhead. It also makes it easier to reason about precedence: within a mode, you can define more specific templates without worrying about side effects on unrelated parts of the transform.

Consider caching computed values in variables. XSLT variables are immutable, so they are safe to reuse without unintended side effects. If you are computing a complex string or a filtered node set repeatedly, store it once per relevant scope. Just be careful not to define a variable at the top of the stylesheet if it depends on the context; keep it as close as possible to where it is used to avoid confusion.

If you are working in XSLT 2.0 or 3.0, you gain access to xsl:for-each-group and higher-order functions. These can be faster and clearer than manual grouping with keys. For XSLT 1.0, the Muenchian grouping pattern is still effective, and when combined with keys it remains a strong choice. Either way, focus on minimizing passes over large node sets.

Also consider the output method. Serializing large outputs can be a significant part of the runtime. If you do not need pretty-printed XML, avoid indentation to reduce the amount of whitespace and processing time. Similarly, if you are generating text or JSON, use method="text" or structured XSLT 3.0 serialization options rather than building a text string node by node.

I recommend using realistic test data when tuning performance. A transform that runs in 100 milliseconds on a tiny input may take seconds on real data. Use a handful of real documents and measure changes as you apply each improvement. This keeps the optimization process grounded and prevents you from making the code worse without a measurable gain.

Finally, keep a balance between speed and clarity. The fastest stylesheet is useless if it is too hard to maintain. Use a few consistent patterns: keys for lookups, modes for pipelines, variables for repeated values, and limited selection scope. With those in place, the performance usually becomes acceptable without heroics.

If you want a quick way to benchmark different approaches with the same input set, try the online editor at https://xsltplayground.com. It is a convenient place to experiment with keys, modes, and alternative match patterns while keeping your transform readable.

Build a Smart Sport Predictor with Data Science

Predicting the Game: Building a Smart Sport Prediction App with Data Science

The roar of the crowd, the tension of a close match, the unpredictable brilliance of athletes – sports capture our imagination like few other things. But beneath the surface of passion lies a rich tapestry of data, a goldmine for those seeking to forecast outcomes. A sport prediction app, powered by past data and the current form of teams, represents a fascinating intersection of data science, machine learning, and software engineering. This article delves into the technical journey of constructing such an application, exploring its architecture, data challenges, model selection, and practical implementation.

The Predictive Powerhouse: Core Components

At its heart, a sport prediction app aims to leverage historical performance metrics and real-time indicators to estimate the probability of various match outcomes (e.g., Home Win, Draw, Away Win, or specific scorelines). This process demands a robust data pipeline, sophisticated feature engineering, and carefully chosen machine learning models.

Data Acquisition & Preprocessing: The Foundation

The quality of predictions hinges entirely on the quality and breadth of the input data. For sports, this typically includes:

  • Match Results: Historical scores, dates, leagues, participating teams, and outcomes.
  • Team Statistics: Home/away win rates, average goals scored/conceded, clean sheets, disciplinary records (red/yellow cards), possession statistics.
  • Player Statistics: Individual goals, assists, injuries, suspensions, minutes played, form ratings.
  • Head-to-Head Records: Performance of two specific teams against each other.
  • Environmental Factors: Venue, weather conditions (less critical for indoor sports, but vital for outdoor ones).
  • Betting Odds: Historical pre-match odds can serve as a strong baseline predictor and an indicator of public/professional sentiment.

Sources: Dedicated sports data APIs (e.g., Sportradar, Opta, Football-Data.org) are ideal for reliable, structured data. Web scraping can supplement this, though it requires more maintenance.

Preprocessing: Raw data is rarely ready for model consumption. Key steps include:

  • Cleaning: Handling missing values (imputation, removal), correcting inconsistencies (e.g., team name variations).
  • Normalization/Scaling: Ensuring features are on a comparable scale, which is crucial for many ML algorithms.
  • Feature Engineering: This is where the magic truly begins.

Feature Engineering: Beyond Raw Numbers

Effective feature engineering transforms raw data into meaningful predictors. The goal is to capture the underlying dynamics that influence match outcomes.

Examples of powerful features:

  1. Recent Form: How has a team performed in its last N games?

    • HomeTeam_WinRate_Last5: (Wins in last 5 home/all games) / 5
    • AwayTeam_GoalDiff_Last3: Sum of (GoalsFor – GoalsAgainst) in last 3 away/all games.
    • Pseudocode: form_metric = (sum(wins) * 3 + sum(draws) * 1) / total_games_played (weighted points)
  2. Home/Away Advantage: Teams often perform better at their home ground.

    • HomeTeam_HomeWinRate: Win rate specifically for home matches.
    • AwayTeam_AwayWinRate: Win rate specifically for away matches.
  3. Head-to-Head Statistics: The historical rivalry between two specific teams.

    • H2H_HomeTeam_Wins_Against_AwayTeam: Number of times HomeTeam beat AwayTeam in past encounters.
  4. Elo Ratings: A common ranking system in competitive games, constantly updated based on win/loss against opponents of varying strengths. It’s a powerful dynamic feature.

    • Elo_Rating_HomeTeam_Difference: HomeTeam’s Elo rating minus AwayTeam’s Elo rating.
  5. Player Availability/Injuries: Presence or absence of key players can significantly shift probabilities. This requires more dynamic, often text-based, data processing.

  6. Tactical Consistency: Tracking manager changes, consistent formations.

These engineered features provide a richer context than raw match scores, allowing models to learn more nuanced patterns.

Machine Learning Models: The Prediction Engine

With well-engineered features, various supervised learning models can be employed. The task is typically a classification problem (predicting Home Win, Draw, Away Win) or a regression problem (predicting goal difference or exact scores).

Candidate Models:

  1. Logistic Regression: A good baseline for classification, providing probabilities for each outcome. It’s interpretable and computationally efficient.
  2. Random Forests: An ensemble method that builds multiple decision trees. It handles non-linear relationships, is robust to overfitting, and provides feature importance.
  3. Gradient Boosting Machines (XGBoost, LightGBM): Highly powerful and often top-performing algorithms in tabular data challenges. They build trees sequentially, correcting errors of previous trees, leading to strong predictive power.
  4. Support Vector Machines (SVMs): Effective for finding optimal hyperplanes to separate classes, though sometimes less interpretable.
  5. Neural Networks (e.g., Multi-layer Perceptrons): Can capture complex non-linear patterns, especially useful with a large number of features or when combined with embedding techniques for categorical data.

Model Selection & Evaluation:
Models are trained on historical data and evaluated using metrics like accuracy, precision, recall, F1-score, and ROC AUC for classification tasks. Cross-validation is crucial to ensure generalization performance. Often, an ensemble of multiple models (e.g., stacking or blending) can yield superior results by combining their strengths.

Building the App: From Model to User Interface

A predictive model is only valuable when integrated into an accessible application. This requires careful consideration of backend infrastructure, frontend design, and deployment strategy.

Backend Architecture: Serving Predictions

The backend serves as the brain of the operation, managing data, running models, and exposing predictions via an API.

  • Data Lake/Warehouse: A robust storage solution (e.g., PostgreSQL, MongoDB, or a cloud data warehouse like Snowflake) for storing vast amounts of historical match data, player stats, and processed features.
  • ETL Pipeline: Automated scripts (e.g., Python with Airflow or Prefect) to regularly extract new data, transform it into features, and load it into the prediction service. This pipeline also handles model retraining at scheduled intervals (e.g., daily, weekly).
  • Prediction Service: A microservice (e.g., built with Flask, FastAPI, or Node.js) that hosts the trained machine learning models. It receives requests (e.g., for an upcoming match), generates predictions, and returns them.
  • API Gateway: A RESTful API interface that allows frontend applications to query for predictions.
+----------------+     +------------------+     +--------------------+
| Data Sources   | --> | ETL Pipeline     | --> | Feature Store/     |
| (APIs, Scraping)|     | (Ingest, Clean, FE)|     | Data Warehouse     |
+----------------+     +------------------+     +--------------------+
                              |                          |
                              v                          v
                     +--------------------+     +--------------------+
                     | Model Training     | <--- | Historical Data    |
                     | (Scheduled)        |      | (for training)     |
                     +--------------------+      +--------------------+
                              |
                              v
                     +--------------------+
                     | Prediction Service | <---- Requests from API
                     | (Hosts ML Models)  |
                     +--------------------+
                              |
                              v
                     +--------------------+
                     | API Gateway        | <---- Frontend App
                     +--------------------+

Frontend Considerations: User Experience

The frontend is the user’s window into the predictions. It needs to be intuitive, responsive, and capable of visualizing complex data clearly.

  • Platform Choice: Cross-platform frameworks like Flutter or React Native are excellent for developing mobile apps that run on both iOS and Android from a single codebase. Web applications (React, Angular, Vue.js) offer broader accessibility.
  • UI/UX Design:
    • Clear Prediction Display: Show predicted outcomes with confidence scores (e.g., “Home Win: 65%”, “Draw: 20%”, “Away Win: 15%”).
    • Insights & Rationale: Where possible, provide insights into why a prediction was made (e.g., “Home team has strong recent form,” “Away team’s key striker is injured”). This often involves leveraging model interpretability techniques (e.g., SHAP values).
    • Historical Performance: Allow users to review past predictions and their accuracy.
    • Interactive Visualizations: Graphs showing team form over time, head-to-head performance comparisons, or player statistics.

Deployment and Scalability

Deploying such an application requires a cloud-based infrastructure (AWS, GCP, Azure). Services like EC2/Compute Engine for VMs, S3/Cloud Storage for data, RDS/Cloud SQL for databases, and Kubernetes for container orchestration provide the necessary scalability and reliability. Monitoring tools are essential to track application performance, data pipeline health, and model drift.

Challenges and Considerations

Building a sports prediction app is not without its hurdles:

  • Data Quality and Availability: GIGO (Garbage In, Garbage Out) is paramount. Missing or inaccurate data will directly degrade prediction accuracy. Sourcing comprehensive and reliable data can be expensive.
  • Overfitting: Models can become too specialized to the training data, failing to generalize to new, unseen matches. Robust validation techniques are crucial.
  • Dynamic Nature of Sports: Player injuries, manager changes, psychological factors, and unexpected events (e.g., controversial referee decisions) are difficult to quantify and can drastically alter outcomes in ways not easily captured by historical data. Models need frequent retraining and updates to reflect current realities.
  • Ethical Considerations: Such apps border on gambling tools. Developers must be mindful of promoting responsible use and clearly state that predictions are statistical probabilities, not guarantees.
  • Feature Creep: The temptation to add an ever-increasing number of features can complicate models without necessarily improving accuracy. A balance must be struck between complexity and predictive power.

Real-World Applications & Future Enhancements

Beyond direct match prediction, the underlying technology has broader applications:

  • Fantasy Sports Optimization: Providing insights for drafting players and managing teams.
  • Sports Betting Analytics: Offering data-driven insights to inform betting strategies (with appropriate disclaimers).
  • Team Performance Analysis: Helping sports analysts and coaches identify strengths, weaknesses, and potential opponents’ strategies.
  • Live Prediction Updates: Integrating real-time match events to dynamically update probabilities during a game.
  • Advanced Player Tracking: Combining prediction models with computer vision techniques to analyze player movements and actions in real-time, potentially predicting immediate game flow (a sophisticated extension of concepts like “counting exercise repetitions using camera”).
  • Sentiment Analysis: Leveraging NLP to analyze sports news and social media for sentiment around teams and players, integrating qualitative data.

Conclusion

Building a sport prediction app is an exciting venture into the world of data science and machine learning. It demands a systematic approach to data acquisition, rigorous feature engineering, thoughtful model selection, and robust application architecture. While challenges like data quality and the inherent unpredictability of human performance persist, the power of data-driven insights offers a compelling advantage over purely subjective predictions. As data sources become richer and ML models more sophisticated, these applications will continue to evolve, offering increasingly accurate and nuanced perspectives on the beautiful game and beyond. The future of sports analysis is undeniably intelligent, data-powered, and predictive.

Tekirdağ En İyi Oto Expertiz Firmaları – 2026

Tekirdağ’da güvenilir oto ekspertiz hizmeti almak isteyenler için 2026 yılının öne çıkan firmalarını bir araya getirdik. Araç satın almadan önce detaylı kontrol yaptırabileceğiniz en iyi ekspertiz merkezlerini bu listede bulabilirsiniz.