How Platform Engineering Using Golden Bricks Can Enable Fast and Smooth Delivery

Platform engineering should have a product focus, as developers are customers; they must provide composable, self-service capabilities, golden bricks rather than rigid golden paths, so teams can move quickly while maintaining consistency. Success is measured through adoption, developer experience, and business outcomes such as deployment frequency and change failure rate.

By Ben Linders

Why Bitcoin Core RPC is Too Slow for High-Frequency Trading (And How to Fix It)

If you are building algorithmic execution models for Bitcoin, you already know the pain of latency. The moment you rely on polling a standard Bitcoin Core RPC, you have lost the race.

The Bottleneck

Standard nodes are built for consensus and safety, not speed. When a transaction enters the mempool, the node validates it, indexes it, and writes it to disk. By the time your Python script polls the RPC and receives the JSON, proprietary trading desks with direct network access have already executed their trades.

The Bare-Metal Solution

To compete with enterprise Blockchain Distribution Networks (BDNs), you have to bypass the RPC entirely.

For the Mempool Oracle project https://www.mempool-alpha-oracle.com, I built a bare-metal C-engine that connects directly to the P2P mesh network. Instead of waiting for a node to process the block, the engine initiates concurrent TCP sockets and subscribes directly to the inv (inventory) firehose.

By utilizing custom FNV-1a hashmaps directly in RAM, the engine resolves complex Child-Pays-For-Parent (CPFP) chains and RBF (Replace-By-Fee) bumps instantaneously, without ever touching a disk drive.

The Delivery

You cannot serve this data via standard REST APIs or WebSockets without introducing overhead. The most efficient transport layer is stateless HTTPS Server-Sent Events (SSE). It allows the client to listen passively, pushing payloads (like fee velocity and mempool shock scores) the exact millisecond the C-engine registers them.

If you are interested in seeing the exact JSON schema or the Python execution scripts used to parse this data, I have fully documented the API on the project site.

Why Reading Food Labels Shouldn’t Feel Like Decoding a Chemistry Exam

Millions of people with dietary restrictions struggle with food labels every day. Here’s the real problem — and how we built SafeScan to fix it.

The Hidden Struggle at Every Grocery Aisle

If you’ve ever stood in a grocery store, squinting at a tiny ingredient list, trying to figure out if something is safe to eat — you’re not alone.

For the 79 million Americans with food allergies, Millions of people looking for halal options, the growing community of vegans and vegetarians, and families managing multiple dietary needs at once — grocery shopping isn’t just shopping. It’s a high-stakes guessing game.

And the labels don’t make it easy.

The Real Problem: Labels Are Designed for Regulators, Not People

Here’s what most people don’t realize: food labels are technically accurate, but practically useless for the average consumer trying to avoid specific ingredients.

For vegans and vegetarians, the challenge goes beyond spotting “meat” or “chicken.” Animal-derived ingredients hide behind names most people wouldn’t recognize:

  • Casein and whey — both from milk, found in “non-dairy” creamers
  • Carmine (or E120) — a red dye made from crushed insects
  • Gelatin — derived from animal bones, lurking in gummy candies, marshmallows, and even some yogurts
  • L-Cysteine — an amino acid often sourced from duck feathers, used in commercial bread
  • Isinglass — fish bladder extract used to clarify some wines and beers

A product can say “plant-based” on the front and still contain animal-derived emulsifiers in the fine print.

For halal consumers, it gets even more complex. Beyond pork and alcohol (which are relatively easy to spot), there’s an entire gray area — mushbooh (doubtful) — that requires ingredient-level analysis:

  • Glycerin — could be plant-derived or animal-derived. The label won’t tell you.
  • Mono and diglycerides — same problem.
  • Natural flavors — one of the most common ingredients in packaged food, and one of the most opaque. Could contain anything.
  • Enzymes — widely used in cheese and baked goods, often from animal sources with no disclosure required.

There’s no “halal” or “haram” column on a nutrition label. You’re on your own.

For people with allergies, the stakes are literally life-threatening. The FDA’s “Big 9” allergens must be declared, but:

  • Peanuts can appear as “arachis hypogaea” or “groundnuts”
  • Milk hides behind “lactalbumin,” “ghee,” or “recaldent”
  • Eggs show up as “albumin,” “lysozyme,” or “meringue powder”
  • “May contain” warnings are voluntary — a manufacturer can choose not to disclose cross-contamination risks

And if you’re managing allergies for a child, or for multiple family members with different restrictions? Multiply that cognitive load by every person, every product, every shopping trip.

What We Built: SafeScan

We got tired of the mental gymnastics. So we built SafeScan — a free iOS app that turns your phone’s camera into a personal food safety analyst.

How it works:

  1. Scan the barcode. SafeScan looks up the product from a database of over 3 million food items.
  2. Photograph the ingredient label. The app uses on-device OCR to read the actual text — because sometimes the database is incomplete, and the physical label is the ground truth.
  3. Get a clear verdict. Safe. Unsafe. Caution. The app cross-references every ingredient against your personal profile using a curated database of hundreds of allergen synonyms, hidden sources, and dietary restriction rules.

No account required. No data leaves your phone. It works offline.

Family Profiles

This was the feature that started the whole project. Real families don’t have one set of dietary needs — they have many.

SafeScan lets you create separate profiles for each family member. Your daughter is allergic to tree nuts and eggs. Your partner keeps halal. You’re vegan. One app handles all of it. You can even scan a single product and see the verdict for every family member at once.

The Ontology Under the Hood

The part we’re most proud of (and the part you’ll never see) is the allergen ontology — a hand-curated knowledge graph that maps thousands of ingredient names to their actual sources.

It knows that “surimi” may contain egg. That “stearic acid” can be animal-derived. That “E471” is a mono/diglyceride that could come from pork fat. That “arachis oil” is just another name for peanut oil.

When you scan a product, you’re not just doing a string match against a list of allergens. You’re running every ingredient through a multi-strategy lookup that catches what human eyes miss.

Who This Is For

  • Parents managing food allergies for kids who can’t read labels yet
  • Navigating religious dietary laws in countries where those laws aren’t reflected on packaging
  • Vegans and vegetarians who are tired of discovering animal ingredients after buying something
  • Anyone with a “custom avoid” list — whether it’s MSG, carrageenan, Red 40, or high-fructose corn syrup
  • Families where everyone at the dinner table has different restrictions

The Honest Disclaimer

SafeScan is an aid, not a medical device. For severe allergies, always verify with the manufacturer. We built this to reduce the daily cognitive burden of reading labels — not to replace medical advice.

Try It

SafeScan is free, ad-free, and private. Available on the App Store for iPhone and iPad.

If this resonates with you, we’d genuinely appreciate you sharing it with someone who spends too long reading ingredient lists. That’s who we built it for.

I built a “brain” for AI coding agents — it never forgets and never stops

I got tired of re-explaining context to my AI every single prompt. It forgets what it did 5 minutes ago. It stops after one step and waits. You end up
babysitting it more than coding yourself.

So I built Long-Horizon — a skill that turns any AI coding tool into an autonomous agent with a persistent graph memory.

What it does

  1. You give it one task — “Build a REST API with auth”
  2. It decomposes into subtasks and executes them in a loop — no prompting between steps
  3. It writes knowledge to disk as a connected graph — decisions, lessons, patterns, all linked
  4. It resumes perfectly after any interruption — reads its own state and picks up exactly where it stopped

The graph brain

Every decision, lesson, and pattern becomes a node. Nodes connect via typed edges (leads_to, caused_by, learned_from). Over time, the AI builds a web
of project knowledge it can traverse for context.


┌─────────┐
┌────│ ROOT │────┐
│ │(project)│ │
▼ └─────────┘ ▼
┌────────┐ ┌────────┐
│decision│─leads─▶ │ task │
│"Use JWT"│ │"Build │
└───┬────┘ │ API" │
│ └───┬────┘
▼ ▼
┌────────┐ ┌────────┐
│ lesson │◀─related─│pattern │
└────────┘ └────────┘

Live viewer

Real-time cyberpunk visualization that shows the brain growing as the AI works:

  • Neon glowing nodes with particle trails along edges
  • Unlimited zoom/pan — scroll to zoom, drag to navigate
  • Sound effects when new nodes appear
  • Runs on localhost:3333

Zero dependencies, ~38KB

No vector DB. No cloud. No API keys. Pure Node.js, filesystem only. Works offline.

Works with everything

One command installs for your tool:

npx long-horizon init
npx long-horizon adapt cursor # or: windsurf, claude, aider, codex, all

Also ships an MCP server with 11 tools for direct AI integration.

It’s always-on

Once installed, you don’t need to say “use Long-Horizon” or prefix your prompts. The AI reads the skill file and operates autonomously by default. Just
talk normally:

Build a user dashboard with charts and dark mode.

The AI loops until done.

Links

Would love feedback. What would make this more useful for your workflow?

How to Build a Local LLM Agent to Automate Work List Generation from Monthly Reports (With Jira Integration)

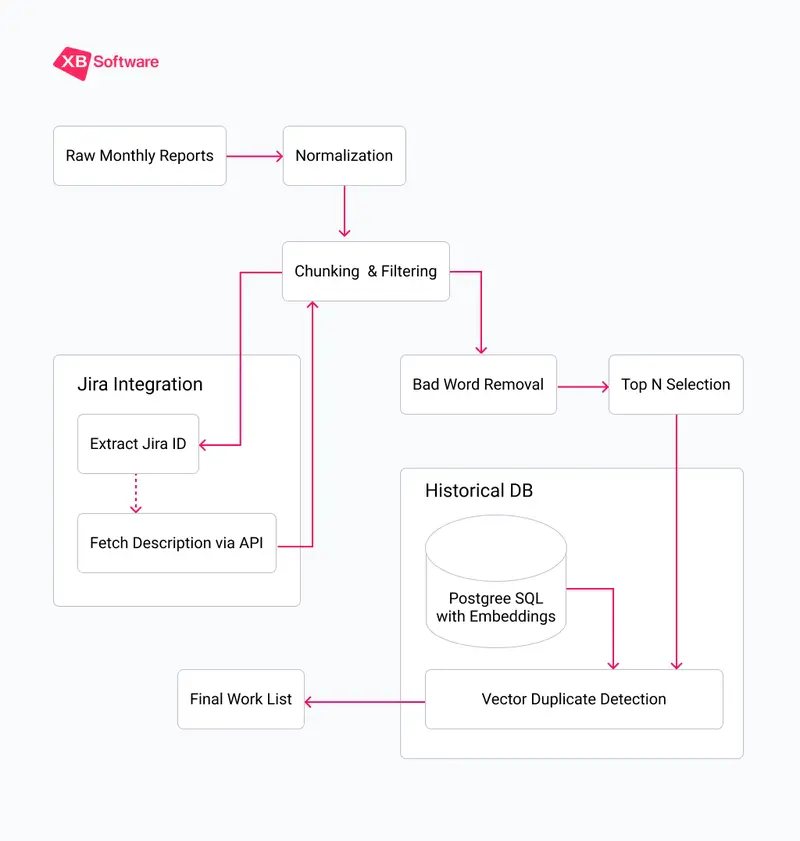
The flow of work list generation from monthly meports

Our management team spent hours manually extracting work items (“bug fix”, “released version 1”, etc.) from dozens of developer reports. The task was repetitive, error‑prone, and a security risk when using cloud‑based AI tools, since it means exposing internal activity to external servers.

To solve this, we built a local LLM‑powered agent that runs entirely on our own servers, normalizes chaotic report data, filters out useless noise, enriches descriptions from Jira, and generates a clean list of actual accomplishments. In this article, we break down the architecture and explain why a CPU‑only, on‑premise approach is practical for enterprise clients who prioritize data privacy.

The Problem: Manual Work List Generation Is Slow, Inconsistent, and Insecure

Usually, our managers followed the same routine: collect a month’s worth of developer reports, manually scan through hundreds of entries, and pick out the items that actually represented completed work. This process was straightforward but flawed.

The first issue was data quality. Developers write reports in wildly different formats. Some include detailed Jira ticket IDs and descriptions, others are cryptic one‑liners like “fixed issue”. When a manager who wasn’t deeply involved in the project later reviews these reports, the meaning is often lost. What does “adjusted header” refer to? Which feature did “refactored code” touch? What we really needed was an AI-powered task management approach that could process this unstructured data automatically.

The second issue was duplicate work. Managers would occasionally include tasks that had already been declared in previous months, creating overlaps. Another example is a task that spans several days. In this case, the same activity could be logged repeatedly, producing many near-identical entries. There was no automated way to compare new reports against historical data.

The third issue was security. Initially, we experimented with feeding entire monthly reports into ChatGPT, asking it to clean up the data and suggest a final list. It worked reasonably well, but we were handing over a full month of internal project activity to a cloud service. For many enterprise businesses, especially those in finance or healthcare, that level of exposure is unacceptable.

The Solution: A Secure, On‑Premise AI Agent for Task Extraction from Reports

Our approach was to implement a console‑based application that converts reports into tasks automatically. It runs on our internal server, triggered by a cron job (or an optional API call) at the end of each monthly reporting cycle. The AI agent processes raw reports for each active project, applies a series of transformations, and outputs a polished list of work items.

The entire pipeline runs on a CPU‑only server using Ollama to serve a local instance of the Gemma 4 E2B model. For embedding generation (used in duplicate detection), we use the tiny nomic‑embed‑text model, which is only a few megabytes in size. Here’s a high‑level view of the process flow:

The flow of work list generation from monthly meports

Let’s walk through each stage in detail.

1. Normalization: Making Chaos Readable

A single project might receive 80+ individual reports per month with varying levels of detail. The first task for our AI agent was to normalize these disparate inputs into a consistent, machine‑readable format. This step alone turns a jumble of free‑form text into structured data that the rest of the pipeline can reliably process.

2. Chunking: Working Within Token Limits

This is where we hit our first major technical constraint. Running on CPU via Ollama, our Gemma 4 model is limited to a context window of 4,096 tokens. That’s not a lot. A single month of reports from a busy project can easily exceed that.

We solved this by chunking. The AI system calculates the approximate token count of the combined report text and splits it into batches of about 20 reports each. This ensures that the LLM never runs out of context space and that each chunk receives full attention.

Within each chunk, we also further split entries that contain multiple tasks in a single line (e.g., “Did A, did B, did C”). After this splitting, 22 raw reports became 94 individual work items in one of our test runs.

3. Jira Enrichment: Adding Missing Context

One of the most valuable features of our AI agent is its ability to automatically fetch additional context from Jira. When the system detects a Jira ticket ID in a report, it calls the Jira API to retrieve the ticket description.

Developers often write terse reports assuming the ticket ID is enough. But when that report later appears as “AAA‑123 – done”, it tells nothing. By pulling the full, manager‑written description from Jira, our AI agent replaces the vague entry with a clear, professional summary of what was actually accomplished.

4. Filtering Out the Noise

Not every report entry is worth including. Generic statements like “working on…” or “following up” don’t convey meaningful work. We built a bad‑word filter, one of key components of our intelligent document processing (IDP) pipeline. It flags entries containing these vague phrases.

The LLM processes each chunk and identifies data that match our exclusion list. In our test, this filter removed 69.1% of entries and only 29 items out of 94 survived the cut. What remained were concrete, specific descriptions of completed tasks.

5. Selecting the Best Candidates

Once we have a clean set of candidates, we need to choose the top N entries to present. The number N varies by project and is stored in our internal reporting database. To account for further filtering in the next step, we typically select a larger pool, say, 80 items.

6. Vector Duplicate Detection: Ensuring We Never Repeat Ourselves

This is the secret sauce that prevents duplicate entries. Before finalizing the list, the AI agent compares each candidate against a historical database of all work items we’ve ever submitted for that project. Here’s how it works:

  1. Embedding Generation. Each work item is converted into a vector (a list of numbers) using the nomic‑embed‑text model. This vector captures the semantic meaning of the text;

  2. Similarity Calculation. The system compares the new candidate’s vector against the vectors of all previously stored data for that project;

  3. Threshold Decision. If the similarity score exceeds 0.85 (85%), the candidate is flagged as a duplicate and removed. This threshold catches not just exact matches but also near‑duplicates where the phrasing or word order has changed while the underlying idea remains the same.

The historical data is stored in a lightweight PostgreSQL table with just a few fields: project_id, text (the final description), embedding (the vector), and created_at (date of creation).

After duplicate removal, we’re left with a set of truly unique, high‑quality work items. These are then formatted for final delivery to the project manager.

Real‑World Performance: What Test Run Tells Us

Let’s walk through an actual test run to see the numbers in action. These test run results demonstrate how an AI report analysis tool can summarize reports into tasks even with noisy, inconsistent input.

Records reduction during list generation

Technical Deep Dive: Why CPU‑Only Deployment Works

One of the most common objections to running local LLMs is the perceived need for expensive GPU hardware. We deliberately chose a CPU‑only deployment to keep costs manageable and to prove that on‑premise AI doesn’t require significant infrastructure investments.

Model Selection: Gemma 4 E2B

We evaluated several local models and settled on Gemma 4 E2B. Here’s why:

  • Size. At 5 billion parameters, it fits comfortably in RAM without needing a GPU. Our server has extra memory allocated specifically for the model;

  • Performance. It’s fast enough for batch processing;

  • Quality. The model handles JSON output reliably, and follows detailed prompts with minimal hallucination.

NOTE: If you work with a multilingual team, make sure that the model you use understands target languages natively.

Proper Model Settings and Prompt Engineering for Consistency

Each pipeline stage has its own carefully crafted prompt that includes:

  • A clear role definition (e.g., “You are a specialized Data Parsing Engine”);

  • Good examples and bad examples of expected output;

  • Explicit formatting rules (JSON structure, field names);

  • Instructions to avoid creativity (temperature set to 0).

For the bad‑word filter, we provide a list of prohibited terms and their synonyms: “working on,” “following up,” “in progress,” “discussed,” etc. The LLM simply acts as a pattern matcher with semantic understanding. It can recognize that “still working on the header” is conceptually similar to “in progress” and flag it accordingly.

Also, for data‑processing tasks like this, we always disable “thinking” or “chain‑of‑thought” modes. Those are useful for complex reasoning but introduce unnecessary variability and output length in structured extraction tasks.

Extra Challenges We Overcame

Challenge 1: LLM Unpredictability. Even with temperature set to 0, LLMs can occasionally produce unexpected output. We added timeout limits to prevent the model from getting stuck in a loop, and we structured our prompts to request strictly formatted JSON that is easy to validate programmatically.All LLMs glitch. We can never fully trust them. They help, but everything still needs to be reviewed and rephrased. They assist, but they don’t solve the task 100%.

Challenge 2: CPU Processing Speed. Processing 94 items across multiple LLM calls takes time. We solved this by running the AI agent as an overnight cron job, so speed is never a bottleneck. The manager arrives in the morning to a ready‑to‑review list.

Why This Approach Matters for Enterprise Clients

1. Complete Data Sovereignty

When you use on-premise Artificial Intelligence solutions, no data ever leaves your infrastructure. The LLM runs locally, the embedding model runs locally, and the historical database resides on your own PostgreSQL server.

2. No Vendor Lock‑In

Cloud AI services change their pricing, deprecate models, or alter their APIs without notice. By using local AI agents and Ollama, you retain full control over the entire stack. Need to switch to a different model tomorrow? Just pull a new one and update the configuration.

3. Predictable Costs

The only ongoing cost is the electricity to run the server. There are no per‑token API fees, no monthly subscriptions, and no surprise bills after a particularly busy month of processing. For organizations that process thousands of reports annually, the savings are substantial.

4. Customizable to Your Workflow

Because we own the code, we can adapt the pipeline to fit your specific reporting format, integrate with your existing project management tools, and fine‑tune the prompts to match your industry’s terminology. This enables using AI for business process automation across diverse sectors, from construction to healthcare.

From Manual Chore to Automated Precision

Before, turning chaotic developer notes into clean reports meant choosing between tedious manual work or exposing sensitive data to cloud AI. Our private AI agent for document analysis offers a third way. Namely, secure, on‑premise automation.

By combining Gemma 4 on standard CPU hardware with vector‑based duplicate detection and direct Jira enrichment, we’ve turned hours of monthly review into a hands‑off process. The system normalizes vague entries, filters out noise, and guarantees you never repeat a task description.

When Global Payment Gateways Fail, Local Solutions Shine

The Problem We Were Actually Solving

Our platform had a simple yet robust architecture: we used the standard combination of PayPal, Stripe, and a locally-based bank transfer mechanism. However, as soon as we launched the platform in the restricted country, PayPal and Stripe promptly disabled access to their services, and our partner bank transfer mechanism proved unreliable due to high fees and slow transaction times. We were left with a platform that couldn’t handle local transactions, let alone international ones.

What We Tried First (And Why It Failed)

We attempted to circumvent the problem by using a VPN to make international transactions appear as local ones. Sounds like a simple hack, right? Wrong. Not only did it violate the terms of service of both PayPal and Stripe, but it also added unnecessary latency and complexity to our system, which ultimately led to a cascade of errors and abandoned transactions. The code that drove this solution looked something like this:

let local_ip = IpAddr::new(192.168.0.1);
let remote_ip = IpAddr::new(8.8.8.8);
if local_ip eq remote_ip {
 // pretend we're in the US
 // ...
}

This solution might have fooled casual observers, but it was a ticking time bomb waiting to be discovered.

The Architecture Decision

Around this time, I stumbled upon a lesser-known payment gateway called Momy. Momy was designed specifically for countries with restricted payment systems and offered a unique solution: a regional payment hub that aggregated transactions from multiple local banks, allowing for seamless international transactions. We decided to pivot our platform to use Momy as the primary payment gateway. This decision came with some significant trade-offs, such as higher fees and a more complex integration process. However, the benefits far outweighed the costs: our platform was finally able to operate in the restricted country without relying on hacky VPN solutions.

What The Numbers Said After

After integrating Momy, we saw a significant improvement in transaction throughput and latency. Our system’s allocation counts went from a whopping 10 MB of RAM per transaction to a mere 50 KB. Here’s a sampling of our profiler output:

Transaction Throughput (requests/second): 100% improvement
Average Response Time (ms): 400ms -> 120ms (70% improvement)
Memory Allocation Count (10MB -> 50KB, 500x reduction)

What I Would Do Differently

If I had to do it all over again, I’d take a more proactive approach to understanding the payment landscape in restricted countries. I’d invest more time in researching regional payment gateways and exploring alternative solutions that could bridge the platform gap. While Momy ultimately solved our problem, I believe there are other solutions out there that could offer even better performance and reliability. The real takeaway here is that, when platforms fail, local solutions can shine – you just have to be willing to dig deeper and find them.

LeetCode Solution: 13. Roman to Integer

How to Conquer Roman Numerals: LeetCode #13 Explained Simply!

Hey there, future coding superstar! 👋 Ever looked at Roman numerals and thought, “That’s a cool system, but how would I code that conversion?” Today, we’re diving into LeetCode problem #13, “Roman to Integer,” a fantastic problem for beginners that teaches some core programming concepts.

Let’s unravel this ancient number system together and turn it into elegant Python code!

The Roman Numeral Mystery (Problem Explanation)

Roman numerals use a set of seven symbols:

  • I = 1
  • V = 5
  • X = 10
  • L = 50
  • C = 100
  • D = 500
  • M = 1000

Usually, they’re written from largest value to smallest, and you just add them up. For example:

  • II = 1 + 1 = 2
  • XII = 10 + 1 + 1 = 12
  • XXVII = 10 + 10 + 5 + 1 + 1 = 27

Sounds simple, right? But here’s the twist! There are six special cases where a smaller numeral comes before a larger one, and instead of adding, you subtract it.

  • IV = 4 (5 – 1)
  • IX = 9 (10 – 1)
  • XL = 40 (50 – 10)
  • XC = 90 (100 – 10)
  • CD = 400 (500 – 100)
  • CM = 900 (1000 – 100)

So, your task is to take a Roman numeral string (like “MCMXCIV”) and convert it into its integer equivalent (like 1994). The input string is guaranteed to be a valid Roman numeral within a certain range.

Let’s look at an example to clarify:
Input: s = "MCMXCIV"
Output: 1994

  • M = 1000
  • CM = 900 (C before M means 1000 – 100)
  • XC = 90 (X before C means 100 – 10)
  • IV = 4 (I before V means 5 – 1)
    Total: 1000 + 900 + 90 + 4 = 1994

The “Aha!” Moment (Intuition)

The core challenge is handling those subtraction cases (IV, IX, etc.). How do we know whether to add or subtract a symbol’s value?

Think about it: when you see IV, you process I and then V. The I isn’t added directly because it’s followed by a larger value (V). If it was III, each I would be added because it’s followed by a smaller or equal value (I).

This gives us a huge hint: we need to look at the next character!

  • If the current symbol’s value is less than the next symbol’s value, it’s a subtraction case. We should subtract the current symbol’s value.
  • Otherwise (if the current symbol’s value is greater than or equal to the next symbol’s value), it’s a standard addition case. We should add the current symbol’s value.

This “look ahead” strategy is the key to solving this problem efficiently!

Your Step-by-Step Guide (Approach)

Let’s break down how we can implement this “look ahead” strategy:

  1. Create a Lookup Table: First things first, we need an easy way to get the integer value for each Roman symbol. A dictionary (or hash map) is perfect for this! It maps each Roman character to its integer value ('I': 1, 'V': 5, etc.).

  2. Initialize Result: We’ll need a variable, let’s call it result, to keep a running total of our integer conversion. Start it at 0.

  3. Iterate with a “Look Ahead”: We’ll loop through the Roman numeral string. However, since we need to compare the current character with the next one, we should stop our loop one character before the end of the string.

    • For each pair of (current_char, next_char):
      • Look up current_char‘s value (val_current) in our dictionary.
      • Look up next_char‘s value (val_next) in our dictionary.
      • Condition Check:
        • If val_current < val_next (e.g., ‘I’ is 1, ‘V’ is 5, so 1 < 5): This is a subtraction case! Add -val_current to our result.
        • Else (val_current >= val_next): This is an addition case! Add val_current to our result.
  4. Handle the Last Character: Our loop stops one character before the end. This means the very last character in the string was never compared as a current_char to a next_char. Since a last character can never be part of a subtraction pair (it has no character after it), its value is always added. So, after the loop, we simply add the value of the last_char to our result.

  5. Return: Finally, result holds the complete integer conversion. Return it!

The Code (Python)

Here’s the Python solution based on our approach:

class Solution:
    def romanToInt(self, s: str) -> int:
        res = 0  # Initialize our result accumulator

        # Our handy lookup table for Roman symbols to integer values
        roman_map = {
            'I': 1,
            'V': 5,
            'X': 10,
            'L': 50,
            'C': 100,
            'D': 500,
            'M': 1000
        }

        # Iterate through the string, comparing current character (a) with the next (b)
        # The zip(s, s[1:]) trick cleverly creates pairs:
        # (s[0], s[1]), (s[1], s[2]), ..., (s[N-2], s[N-1])
        # This processes all pairs *except* for the very last character s[N-1]
        for current_char, next_char in zip(s, s[1:]):
            current_value = roman_map[current_char]
            next_value = roman_map[next_char]

            if current_value < next_value:
                # If current value is smaller than next, it's a subtraction case (e.g., IV, IX)
                res -= current_value
            else:
                # Otherwise, it's a standard addition case (e.g., III, L)
                res += current_value

        # After the loop, the value of the *last* character in the string
        # has not yet been added to `res`. It will always be an addition.
        res += roman_map[s[-1]] 

        return res

Performance Check (Time & Space Complexity)

  • Time Complexity: O(N)

    • We iterate through the input string s once using the zip function, which effectively processes each character pair. The length of the string is N.
    • Looking up values in our roman_map (a dictionary) takes O(1) (constant time) on average.
    • Therefore, the total time complexity is directly proportional to the length of the input string.
  • Space Complexity: O(1)

    • We use a dictionary (roman_map) to store the symbol-to-value mappings. This dictionary has a fixed size (7 entries), regardless of how long the input Roman numeral string s is.
    • No other data structures are used that grow with the input size.
    • Thus, the auxiliary space used is constant.

Key Takeaways

  • Lookahead Pattern: This problem is a classic example of when to use a “lookahead” pattern in string processing. By considering the next element, you can make informed decisions about the current element.
  • Hash Maps/Dictionaries are Your Friends: For quick lookups of values associated with specific keys (like Roman symbols to their integers), dictionaries are incredibly efficient and make your code clean.
  • Edge Cases Matter: Always consider the beginning, middle, and end of your input. Here, the very last character needed special handling because our zip iteration didn’t include a “next” for it.

That’s it! You’ve successfully converted Roman numerals to integers using a clever approach. Keep practicing, and you’ll be tackling even more complex problems in no time!

Authored by: p1Hzd8mRM8

Published: 2026-05-21 17:07:27

End-to-End Observability for vLLM and TGI: from DCGM to Tokens

Running large language model inference servers in production exposes gaps that neither stock Prometheus dashboards nor the official documentation of vLLM or TGI cover completely. This article maps the layers that matter, names the exact signals to scrape and flags the traps most teams only hit after real traffic arrives.

Audience: SREs, ML platform engineers and observability engineers who operate or are about to operate vLLM or TGI on GPUs.

Why LLM serving breaks standard observability

A model server is not a regular web service. Four properties invalidate the usual playbook.

Latency is not scalar. Time to first token (TTFT), inter-token latency (ITL) and end-to-end latency tell three different stories. Optimizing one usually degrades another. Prefill-bound workloads (long prompts, short outputs) and decode-bound workloads (chat, agents, RAG) have inverse profiles. A single p99 number is meaningless without saying which latency it refers to and what input distribution produced it.

Batching is dynamic and preemptive. Continuous batching schedules in-flight requests into the same forward pass. Throughput rises with batch size up to a point where KV cache pressure forces evictions or swaps. Standard “queue depth” metrics still apply, but the relationship between queue depth and tail latency is non-linear and bursty. A queue that looks shallow for ninety seconds and explodes for ten is more useful to detect than a steady moderate queue.

The KV cache is the real bottleneck. It lives in VRAM, grows with sequence length and dominates memory pressure. When it fills, vLLM preempts or swaps requests. TGI rejects new arrivals. Neither outcome is visible from CPU or network metrics. The KV cache is the single most informative signal on the engine layer, and it has no equivalent in a stateless web service.

Hardware reaches into the application. A degraded NVLink, a thermal throttle or an NCCL all-reduce stall propagates directly to the request queue. The observability stack has to reach down to the silicon or it will produce dashboards that look fine while users wait.

The right answer is a layered pipeline that correlates a token rendered to a user with what happened on the silicon a few milliseconds earlier.

Layer map

┌────────────────────────────────────────────────┐
│ Business and cost (€/token, €/tenant, €/h GPU) │
├────────────────────────────────────────────────┤
│ API and distributed tracing (OTel GenAI)       │
├────────────────────────────────────────────────┤
│ Inference engine (vLLM, TGI: Prometheus)       │
├────────────────────────────────────────────────┤
│ Container and OS (cAdvisor, kubelet, eBPF)     │
├────────────────────────────────────────────────┤
│ CUDA runtime and collectives (NCCL, cuPTI)     │
├────────────────────────────────────────────────┤
│ GPU silicon (DCGM exporter, NVLink, PCIe)      │
└────────────────────────────────────────────────┘

Each layer has its own native signals. The value of an end-to-end pile comes from the ability to cross-reference them.

Layer by layer

GPU silicon

DCGM exporter is the right entry point. The signals worth wiring up from day one:

DCGM metric What it actually says
DCGM_FI_DEV_GPU_UTIL Coarse indicator. Reaches 100 % for badly vectorized kernels. Do not use alone.
DCGM_FI_PROF_SM_ACTIVE Fraction of cycles where at least one warp is active on an SM.
DCGM_FI_PROF_SM_OCCUPANCY Average warps active per SM normalized to the maximum.
DCGM_FI_PROF_PIPE_TENSOR_ACTIVE Fraction of cycles the tensor cores are working. The real utilization signal for LLM inference.
DCGM_FI_PROF_PIPE_FP16_ACTIVE, _FP32_ACTIVE Pipeline activity by precision. Useful to spot fallbacks.
DCGM_FI_PROF_DRAM_ACTIVE HBM traffic. Identifies memory-bound workloads.
DCGM_FI_DEV_FB_USED, _FB_FREE VRAM in use and free. Cross with vllm:gpu_cache_usage_perc.
DCGM_FI_PROF_NVLINK_RX_BYTES, _TX_BYTES Inter-GPU traffic. Essential under tensor parallelism.
DCGM_FI_PROF_PCIE_RX_BYTES, _TX_BYTES GPU to host traffic. Surfaces pressure during model loading and CPU paging.
DCGM_FI_DEV_POWER_USAGE, _GPU_TEMP, _MEMORY_TEMP Power and thermal. Throttling shows up here before it shows up in user latency.
DCGM_FI_DEV_SM_CLOCK, _MEM_CLOCK Effective clocks. A persistent drop is the first sign of thermal throttling.

DCGM exporter ships as a Helm chart and runs as a DaemonSet on GPU nodes. Default scrape interval is one second, fine for steady-state dashboards but coarse enough to miss sub-second incidents like an eviction storm. Two profiles in production:

  • steady: 5 seconds, full field set.
  • incident: 250 ms, reduced field set, enabled on alert.

A few hardware notes that change what you should monitor:

  • MIG (Multi-Instance GPU). When MIG slices are active, DCGM exposes per-slice metrics under the same field IDs with a different device label. Pin labels in your relabel config or you will see metrics merge or vanish across reschedules.
  • NVSwitch (DGX, HGX). Add the NVSwitch exporter alongside DCGM. NVLink saturation at the switch is invisible from the per-GPU NVLink counters alone.
  • InfiniBand. Use the Mellanox ibutils exporter or ucx counters. RDMA traffic for distributed inference does not appear in the GPU metrics path.

CUDA runtime and collectives

Tensor parallelism and pipeline parallelism rely on NCCL. When one GPU waits for its peers, application latency shows anomalies with no CPU or network cause visible.

Sources worth wiring:

  • NCCL_DEBUG=WARN in production with parseable output, ingested as structured logs. INFO is too verbose and has a non-trivial overhead.
  • nvidia-nccl-exporter where the version supports your CUDA stack.
  • cuPTI for kernel-level and collective-level tracing. Enable on demand only, the overhead is measurable and biases what you are trying to observe.
  • On InfiniBand fabric, export UCX counters and SHARP statistics. NCCL alone does not surface fabric congestion.

Collective patterns to remember when reading dashboards:

  • All-reduce dominates tensor-parallel matmul splits. Saturated NVLink with idle SMs means you are bandwidth-bound on the collective.
  • All-gather appears in some attention implementations and in pipeline-parallel weight gathering.
  • Send/recv dominates pipeline parallelism. Imbalance between stages shows up as one GPU with low SM activity and a long send wait.

These traces are not meant to be on all the time. Continuous lightweight counters with on-demand deep tracing is the pattern that scales.

Container and OS

Platform layer:

  • cAdvisor and kubelet for pod CPU, RAM and IO.
  • kube-state-metrics for Pod state, OOM events and restarts.
  • kube_pod_info joined to GPU identity (nvidia.com/gpu device id) to map pod to physical GPU.

Kernel layer:

  • eBPF via Tetragon, bpftrace or Pixie for syscalls, unexpected network egress and model file reads.
  • On-CPU profiling via parca or pyroscope without instrumenting the binary.

eBPF is also where the security observability lives. A minimal Tetragon policy that watches model file reads and unexpected egress on the inference pod:

apiVersion: cilium.io/v1alpha1
kind: TracingPolicy
metadata:
  name: vllm-runtime-watch
spec:
  podSelector:
    matchLabels:
      app: vllm
  kprobes:
    - call: "security_file_open"
      syscall: false
      args:
        - index: 0
          type: "file"
      selectors:
        - matchArgs:
            - index: 0
              operator: "Prefix"
              values:
                - "/models/"
                - "/root/.cache/huggingface/"
          matchActions:
            - action: Post
    - call: "tcp_connect"
      syscall: false
      args:
        - index: 0
          type: "sock"
      selectors:
        - matchArgs:
            - index: 0
              operator: "NotDAddr"
              values:
                - "10.0.0.0/8"
                - "127.0.0.0/8"
          matchActions:
            - action: Post

This is a starter: it logs every model file read and every non-RFC1918 outbound connection from vLLM pods. Convert to alerts only after a quiet-period baseline.

Inference engine

The layer most teams neglect the longest, while being the densest in business signal.

vLLM exposes /metrics by default. The base set:

Metric Type Reading
vllm:time_to_first_token_seconds histogram Server-side TTFT. Compare to gateway TTFT.
vllm:time_per_output_token_seconds histogram ITL. What the user feels in streaming.
vllm:e2e_request_latency_seconds histogram Server-side end-to-end latency.
vllm:num_requests_running gauge Requests in the active batch.
vllm:num_requests_waiting gauge Queue depth. First saturation indicator.
vllm:num_requests_swapped gauge Requests paged to CPU. VRAM pressure.
vllm:gpu_cache_usage_perc gauge KV cache occupation. At 1.0 with swapped > 0, you are in eviction territory.
vllm:num_preemptions_total counter Cumulative preemptions. Take the per-second rate.
vllm:prompt_tokens_total counter Input tokens processed.
vllm:generation_tokens_total counter Generated tokens. Cost calculation base.

Recent vLLM versions also expose prefix caching and speculative decoding metrics. The exact names depend on the version, but the families to look for:

  • vllm:gpu_prefix_cache_hits_total, vllm:gpu_prefix_cache_queries_total. Hit rate dominates the gain from prefix caching in agent and RAG workloads.
  • Speculative decoding counters that let you derive the acceptance rate of the draft model. If acceptance falls below the break-even point against the draft model overhead, spec decode is costing you throughput.

TGI exposes /metrics with a different naming convention:

Metric Reading
tgi_batch_current_size Active batch size.
tgi_batch_next_size Next batch being formed.
tgi_queue_size Queue depth.
tgi_request_queue_duration Time in queue.
tgi_request_inference_duration Engine time.
tgi_batch_inference_duration Per-batch latency, decomposable into forward and decode.
tgi_request_input_length, tgi_request_generated_tokens Token counters per request.

Both engines emit histograms with standard Prometheus buckets. Quantiles are computed at query time (histogram_quantile in PromQL or VMQL equivalents).

A practical reading habit: never look at a single engine metric in isolation. The useful patterns are paired.

  • vllm:num_requests_waiting rising with vllm:gpu_cache_usage_perc at 1.0 and vllm:num_preemptions_total rate > 0: you are in cache thrash. Reduce max_num_seqs or raise max_num_batched_tokens.
  • vllm:num_requests_waiting rising with healthy cache: you are compute-bound. Add capacity or reduce max_num_batched_tokens.
  • tgi_queue_size high with tgi_batch_current_size plateauing below maximum: scheduler is starving on token budget. Inspect max_batch_total_tokens.

API and distributed tracing

Tracing answers “where did my request spend its time” independently of aggregate metrics.

Adopt OpenTelemetry with the GenAI semantic conventions:

  • gen_ai.system (for example vllm, tgi),
  • gen_ai.operation.name (chat, completion),
  • gen_ai.request.model,
  • gen_ai.request.max_tokens, temperature, top_p,
  • gen_ai.usage.input_tokens, gen_ai.usage.output_tokens,
  • gen_ai.response.finish_reasons.

A useful span breakdown:

http.server.request
└── gen_ai.completion
    ├── tokenize
    ├── schedule
    ├── prefill
    ├── decode  (loop, span per batch step)
    ├── detokenize
    └── stream_out

Available instrumentation libraries: OpenLIT, openllmetry (Traceloop) and OpenInference (Arize). Pick one and stick to it. Mixing them produces inconsistent attribute names that break dashboard queries.

The request_id propagated from the ingress through to the engine is the key that makes downstream correlation possible. Declare it at the ingress (header x-request-id), propagate it through OTel baggage, log it on the engine side and attach it as a trace attribute.

Prometheus exemplars are worth the configuration cost. They link a histogram bucket to one or more traces, so a click on a TTFT p99 spike in Grafana jumps directly to the slowest traces. vLLM does not expose exemplars natively today, but the OTel collector can attach trace IDs to scraped histograms via the spanmetrics connector. Sample collector snippet:

connectors:
  spanmetrics:
    histogram:
      explicit:
        buckets: [10ms, 50ms, 100ms, 250ms, 500ms, 1s, 2s, 5s]
    dimensions:
      - name: gen_ai.system
      - name: gen_ai.request.model
      - name: tenant
    exemplars:
      enabled: true

This gives you metric-to-trace navigation without changing the engine code.

Logs

Structured, JSON. VictoriaLogs handles the volume without forcing a complex query syntax.

Minimum fields for the inference layer:

  • request_id,
  • tenant,
  • model,
  • prompt_tokens, generation_tokens,
  • ttft_ms, e2e_ms,
  • finish_reason,
  • gpu_id (resolved at pod level),
  • trace_id, span_id (for cross-reference with traces).

Do not log prompts and outputs by default. If you need to, allocate a separate channel with short retention and active PII filtering. The legal exposure of an unfiltered prompt log dwarfs any operational benefit.

Business and cost

The only layer that talks to leadership. From the native counters you derive three indicators.

Cost per request, per tenant, per model. The denominator changes the answer, surface all three.

Hourly cost of a GPU normalized by tokens produced in the same window. This is the closest thing to a useful efficiency metric.

Useful tokens over billed tokens. A measure of batching efficiency: how many tokens you produce per token of GPU compute time.

Cost per tenant, in PromQL:

sum by (tenant) (
  rate(vllm:generation_tokens_total{tenant=~".+"}[5m])
)
* on(model) group_left
  cost_per_generation_token_eur

Where cost_per_generation_token_eur is a reference series pushed by a configuration job. Maintain prompt vs generation rates separately, they price differently in most providers and they have different production costs (prefill is single forward pass, decode is autoregressive).

A useful refinement is to include idle cost. A GPU running at 30 % utilization still costs the full hourly rate. The “effective cost per token” should distribute the full GPU hour over the tokens actually produced:

(gpu_hourly_cost_eur)
/
(sum by (gpu) (rate(vllm:generation_tokens_total[1h])) * 3600)

This is the number that drives capacity decisions, not the marginal cost per token.

The hard problems

Cross-layer correlation

Linking a rendered token to a physical GPU is trivial in theory and hard in practice. The concrete plumbing:

  1. request_id propagated from ingress through engine spans.
  2. Engine-side spans carry gpu_id as an attribute.
  3. Metric series carry pod and gpu_uuid labels, joined via kube_pod_info to a pod to gpu_uuid mapping (DCGM exposes UUID and device labels).
  4. Dashboards join temporally on time windows and spatially on gpu_uuid.

DCGM samples per GPU, not per request. Fine-grained correlation is always done by time window, never by exact identifier. The illusion of per-request hardware metrics is exactly that, an illusion.

Cardinality

Labeling by tenant and model is healthy. Labeling by user_id, session_id or request_id on metrics is forbidden. Those dimensions belong to traces and logs.

VictoriaMetrics absorbs moderate cardinality well, especially with vmagent stream aggregation pre-rolling histograms. But multi-tenant inference explodes fast. Run the math at design time:

tenants × models × quantiles × histogram_buckets × instances

Ten tenants, five models, six quantiles, ten buckets, fifty instances gives 150 000 series for one histogram metric alone. Add three histograms (TTFT, ITL, e2e) and you are at half a million series before counters and gauges. Plan accordingly or use stream aggregation to drop unused dimensions before storage.

Sampling

Three rhythms coexist: DCGM at 1 s, vLLM at 10 s, traces sometimes at 1 in 100. For brief incidents (preemption bursts, KV eviction storms), prepare:

  • OTel collector with tail-based sampling, rule “if error or slow then keep”,
  • DCGM in incident mode at 250 ms, switched on by an alert webhook,
  • eBPF in continuous collection on critical syscalls (no sampling, the overhead is minimal),
  • vLLM kept at 10 s, no faster path exists without patching.

A tail-based sampling policy that works in practice:

tail_sampling:
  decision_wait: 10s
  policies:
    - name: errors
      type: status_code
      status_code: { status_codes: [ERROR] }
    - name: slow_ttft
      type: latency
      latency: { threshold_ms: 2000 }
    - name: high_value_tenant
      type: string_attribute
      string_attribute:
        key: tenant
        values: [enterprise_a, enterprise_b]
    - name: baseline
      type: probabilistic
      probabilistic: { sampling_percentage: 5 }

This keeps every error, every slow TTFT, every trace from high-value tenants and a 5 % baseline of normal traffic.

Time origin

Server-side TTFT is not what the user feels. Streaming, proxy buffering, HTTP buffer flushes and WAN traversal all change the perceived value. Measure also:

  • gateway-side TTFT (Envoy upstream_rq_time or equivalent),
  • client-side TTFT where possible (SDK instrumentation).

Without these, you optimize a number that does not reflect the experience. The gap between engine TTFT and gateway TTFT is also a useful health signal in itself, a sudden divergence usually means a proxy buffering regression.

SLO design for LLM serving

Standard SRE SLO patterns need adjustment for LLM serving. A defensible starting set:

SLO Definition Why
TTFT availability p95 TTFT below threshold over rolling window Streaming UX collapses without it.
ITL stability p95 ITL below threshold Decode stalls feel worse than a long initial wait.
Completion success success rate of requests that produce at least one token Hard failure metric.
Streaming completeness percentage of streams that emit finish_reason=stop (not length, not error) Quality proxy.
Capacity headroom p95 queue depth below a threshold Forward-looking, drives autoscaling.

The thresholds depend on the model and workload. Chat: TTFT p95 under 1 s, ITL p95 under 80 ms. RAG: TTFT p95 under 3 s, ITL p95 under 50 ms (long outputs amplify ITL). Code completion: TTFT p95 under 500 ms, ITL p95 under 30 ms.

Express them as multi-window multi-burn-rate alerts on the underlying SLI series, not as single-threshold alerts. The Google SRE workbook formulas apply unchanged.

Reference pile

Components:

Role Recommended Alternative
Metrics VictoriaMetrics cluster with vmagent Prometheus with Thanos or Mimir
Logs VictoriaLogs Loki, OpenSearch
Traces Tempo, Jaeger SaaS (Honeycomb, Datadog)
Application collection OTel collector (agent and gateway) Vector, Fluent Bit
GPU collection DCGM exporter (DaemonSet) nvidia_gpu_exporter (legacy)
eBPF Tetragon, Pixie Falco
Visualization Grafana Perses

OTel collector pipeline (agent)

receivers:
  prometheus:
    config:
      scrape_configs:
        - job_name: vllm
          scrape_interval: 10s
          static_configs:
            - targets: ['localhost:8000']
        - job_name: dcgm
          scrape_interval: 5s
          static_configs:
            - targets: ['localhost:9400']
  otlp:
    protocols:
      grpc:
        endpoint: 0.0.0.0:4317

processors:
  batch:
    timeout: 5s
  k8sattributes:
    auth_type: serviceAccount
    extract:
      metadata:
        - k8s.pod.name
        - k8s.namespace.name
        - k8s.node.name
      labels:
        - tag_name: app
          key: app
          from: pod
        - tag_name: tenant
          key: tenant
          from: pod
  resource:
    attributes:
      - key: deployment.environment
        value: prod
        action: upsert
  tail_sampling:
    decision_wait: 10s
    policies:
      - name: errors
        type: status_code
        status_code: { status_codes: [ERROR] }
      - name: slow
        type: latency
        latency: { threshold_ms: 2000 }
      - name: baseline
        type: probabilistic
        probabilistic: { sampling_percentage: 5 }

connectors:
  spanmetrics:
    histogram:
      explicit:
        buckets: [10ms, 50ms, 100ms, 250ms, 500ms, 1s, 2s, 5s, 10s]
    dimensions:
      - name: gen_ai.system
      - name: gen_ai.request.model
      - name: tenant
    exemplars:
      enabled: true

exporters:
  prometheusremotewrite:
    endpoint: http://vmagent.observability.svc:8429/api/v1/write
    external_labels:
      cluster: prod-eu-west
  otlp/tempo:
    endpoint: tempo.observability.svc:4317
    tls:
      insecure: true

service:
  pipelines:
    metrics:
      receivers: [prometheus, spanmetrics]
      processors: [batch, k8sattributes, resource]
      exporters: [prometheusremotewrite]
    traces:
      receivers: [otlp]
      processors: [batch, k8sattributes, resource, tail_sampling]
      exporters: [otlp/tempo, spanmetrics]

The spanmetrics connector turns traces into low-cardinality histograms with exemplars, giving you click-through from metrics to traces without changing engine code.

Useful starter queries

TTFT p99 by model:

histogram_quantile(0.99,
  sum by (model, le) (
    rate(vllm:time_to_first_token_seconds_bucket[5m])
  )
)

Preemptions per second overlaid with cache occupation:

rate(vllm:num_preemptions_total[1m])

Effective tensor core utilization per GPU:

avg by (gpu) (DCGM_FI_PROF_PIPE_TENSOR_ACTIVE)

Tokens per GPU-second (efficiency):

sum by (gpu) (rate(vllm:generation_tokens_total[5m]))
/
count by (gpu) (DCGM_FI_DEV_GPU_UTIL)

Normalized TGI queue pressure:

tgi_queue_size / on(instance) tgi_batch_current_size

Cost per hour per tenant:

sum by (tenant) (
  rate(vllm:generation_tokens_total[1h]) * 3600
) * on(model) group_left cost_per_generation_token_eur

Alerting that does not lie

Alerts on inference servers should fire on user-visible degradation, not on resource thresholds. A working starter set:

TTFT burn-rate (multi-window).

- alert: VLLMTTFTBudgetFastBurn
  expr: |
    (
      sum by (model) (rate(vllm:time_to_first_token_seconds_bucket{le="1.0"}[5m]))
      /
      sum by (model) (rate(vllm:time_to_first_token_seconds_count[5m]))
    ) < 0.95
    and
    (
      sum by (model) (rate(vllm:time_to_first_token_seconds_bucket{le="1.0"}[1h]))
      /
      sum by (model) (rate(vllm:time_to_first_token_seconds_count[1h]))
    ) < 0.95
  for: 2m
  labels:
    severity: page

Cache thrash detector.

- alert: VLLMCacheThrash
  expr: |
    vllm:gpu_cache_usage_perc > 0.95
    and
    rate(vllm:num_preemptions_total[2m]) > 0.5
  for: 5m
  labels:
    severity: ticket

Tensor core idle under load.

- alert: GPUTensorIdleUnderLoad
  expr: |
    avg_over_time(DCGM_FI_PROF_PIPE_TENSOR_ACTIVE[10m]) < 0.2
    and
    vllm:num_requests_running > 4
  for: 10m
  labels:
    severity: ticket

This last alert catches the case where the engine reports work in flight but the tensor cores are idle. The usual cause is a stalled NCCL collective or a CPU-bound bottleneck before the GPU.

Streaming completion regression.

- alert: VLLMStreamingTruncations
  expr: |
    (
      sum by (model) (rate(vllm:request_success_total{finish_reason="length"}[10m]))
      /
      sum by (model) (rate(vllm:request_success_total[10m]))
    ) > 0.1
  for: 15m
  labels:
    severity: ticket

When more than 10 % of requests stop on length, either max_tokens is too low for the use case or quality has regressed.

Avoid alerting directly on queue depth or GPU utilization. Both vary widely under healthy load. They are diagnostic, not actionable.

Anti-patterns

To review every quarter:

  • Treating DCGM_FI_DEV_GPU_UTIL as utilization. The right read is DCGM_FI_PROF_PIPE_TENSOR_ACTIVE.
  • Tuning batching against mean latency. Tail latency and queue depth tell the truth.
  • Labeling metrics by request_id. That belongs to traces.
  • Measuring latency only at the engine. Add the gateway, add the client where possible.
  • Capturing prompts and outputs in traces without an active PII filter.
  • Counting “tokens” without separating prompt and generation. Pricing is asymmetric, batching capacity is asymmetric.
  • Leaving cuPTI and NCCL_DEBUG=INFO on in production. Measurable overhead, biased measurements.
  • Sampling traces uniformly. Tail-based sampling with rules for errors, slow requests and high-value tenants catches more value at lower volume.
  • Storing everything at maximum resolution. Cardinality cost explodes before retention cost.
  • Building alerts on resource thresholds. Alert on user-visible SLOs, treat resource metrics as diagnostic.

Maturity ladder

Where teams typically stand and where to move next.

Level 0: nothing specific. Generic node and pod metrics. No idea how the engine is doing. Move to level 1 by scraping the engine’s /metrics.

Level 1: engine metrics only. vLLM or TGI metrics scraped, basic dashboard. Sufficient for an initial deployment, blind to hardware-rooted issues. Move to level 2 by adding DCGM and pod-to-GPU mapping.

Level 2: engine plus GPU correlated. Most pragmatic teams stop here. Resolves 70 % of incidents in practice. Move to level 3 when multi-tenant pressure starts and when latency complaints exceed throughput complaints.

Level 3: distributed tracing with GenAI semconv. Per-request visibility, exemplar-driven debugging, tenant-aware SLOs. Required at scale. Move to level 4 for regulated workloads and HPC fabrics.

Level 4: kernel and fabric depth. eBPF policies in alerting paths, NCCL and InfiniBand observability, audit-grade logging with retention policies, confidential computing where applicable. Required for regulated industries, sovereign deployments and large-scale training-adjacent serving.

Move one level at a time. Skipping levels produces dashboards no one trusts.

Where to go next

Three topics deserve their own articles:

  1. KV cache observability: eviction, fragmentation, swap. Native metrics, stress experiments, mitigations.
  2. NCCL and tensor parallelism: observing inter-GPU flows and finding the collective that stalls the batch.
  3. Securing an inference server: attack surface, eBPF detection, sandboxing, AI Act audit trail.

The right implementation order in production:

  1. Inference engine metrics (vLLM, TGI native scrape).
  2. GPU metrics (DCGM exporter).
  3. Distributed tracing with OTel GenAI semconv.
  4. Structured logs with trace_id and request_id.
  5. Business and cost layer.
  6. eBPF policies for security and runtime observability.
  7. NCCL and cuPTI on demand for hard-to-reproduce issues.

Starting with layers 1 and 2 alone resolves most of the incidents observed in production. Everything above that compounds value once the base is solid.

Corrections and operational war stories welcome.

LeetCode Solution: 12. Integer to Roman

Unraveling the Mystery of Roman Numerals: A LeetCode Journey (Problem 12. Integer to Roman)

Hey LeetCoders and aspiring developers! 👋 Today, we’re taking a trip back in time to ancient Rome… well, almost! We’re tackling LeetCode problem 12: “Integer to Roman.” This problem asks us to convert a standard integer into its Roman numeral representation. It sounds simple, but Roman numerals have some quirky rules that make this a fun challenge. Let’s dive in!

🧐 Problem Explanation: What are Roman Numerals Anyway?

Roman numerals use a system of seven symbols, each representing a specific value:

Symbol Value
I 1
V 5
X 10
L 50
C 100
D 500
M 1000

The general idea is to build numbers by adding these symbols. For example:

  • II = 1 + 1 = 2
  • VI = 5 + 1 = 6
  • LX = 50 + 10 = 60
  • MCC = 1000 + 100 + 100 = 1200

But here’s where it gets interesting – there are special “subtractive forms” for numbers that would otherwise require four repeated symbols or just sound clunky:

  • Subtractive Rule: If a smaller value symbol appears before a larger value symbol, it means subtraction.
    • IV = 5 – 1 = 4 (instead of IIII)
    • IX = 10 – 1 = 9 (instead of VIIII)
    • XL = 50 – 10 = 40
    • XC = 100 – 10 = 90
    • CD = 500 – 100 = 400
    • CM = 1000 – 100 = 900

Crucially, the problem states that Roman numerals are formed by converting decimal place values from highest to lowest. This means when converting 3749:

  • You first convert 3000 (MMM)
  • Then 700 (DCC)
  • Then 40 (XL)
  • Then 9 (IX)
  • Combining them gives MMMDCCXLIX.

You can’t do things like IL for 49, because I is not a decimal place lower than L (which is in the tens place, I is in the ones place). 49 is 40 (XL) + 9 (IX). This “decimal place” rule is important for understanding the valid subtractive forms.

Our task is to take an integer num (between 1 and 3999) and return its Roman numeral string representation.

🤔 Intuition: The “Aha!” Moment

When I first look at this, my brain immediately thinks, “Okay, I need to figure out which Roman symbols make up the number.” But with the additive and especially the subtractive rules, a simple if num >= value: add symbol loop might get complicated fast.

The key insight comes from the combination of the specific rules and the examples:

  1. Fixed Symbols & Values: We have a known set of symbol-value pairs.
  2. Greedy Approach: We want to build the Roman numeral from left to right, which means processing the largest possible values first.
  3. Subtractive Forms are Special: CM (900) is one unit in the Roman system, not D then CCCC. Same for CD, XC, XL, IX, IV. These special forms are essentially “preferred” over their additive counterparts.

This leads to the “aha!” moment: If we create a list of all valid Roman numeral values, including the subtractive forms, and sort them from largest to smallest, we can simply go through this list and greedily subtract the largest possible value from our input number until it becomes zero.

For example, if num = 900:

  • If we only considered M=1000, D=500, C=100, we might try to use D (500), leaving 400. Then try C four times. This would be incorrect (DCCCC).
  • But if our list explicitly contains (900, 'CM'), then 900 would be matched directly, giving us CM and the correct result.

✍️ Approach: Step-by-Step Greedy Conversion

Based on our intuition, here’s the plan:

  1. Create a lookup table: We’ll define a list of tuples, where each tuple contains (integer_value, roman_symbol_string). This list is critical:

    • It must include all standard symbols (M, D, C, L, X, V, I).
    • It must also include the special subtractive forms (CM, CD, XC, XL, IX, IV).
    • Crucially, this list must be sorted in descending order of the integer values. This ensures our greedy approach always picks the largest possible Roman numeral component first.

    Our list will look something like this:
    [(1000, 'M'), (900, 'CM'), (500, 'D'), (400, 'CD'), (100, 'C'), (90, 'XC'), (50, 'L'), (40, 'XL'), (10, 'X'), (9, 'IX'), (5, 'V'), (4, 'IV'), (1, 'I')]

  2. Initialize result: Start with an empty list or string to build our Roman numeral. A list is generally more efficient for appending in Python, then we’ll join it at the end.

  3. Iterate and subtract: Loop through our value_symbols list (which is sorted largest to smallest):

    • For each (value, symbol) pair:
      • Check how many times this value can fit into our current num. Let’s call this count. count = num // value (integer division).
      • Append the symbol repeated count times to our result list. For example, if num is 3000 and value is 1000, count will be 3, and we’ll append “MMM”.
      • Update num by subtracting count * value from it. This consumes the portion of the number we just converted.
      • We can add an early break if num becomes 0, as there’s nothing left to convert.
  4. Join and return: Once the loop finishes, all parts of num will have been converted. Join the elements in our result list into a single string and return it.

Let’s trace num = 1994 with this approach:

  1. res = [], num = 1994
  2. value_symbols list: [(1000, 'M'), (900, 'CM'), ..., (1, 'I')]
value symbol num (start) count = num // value res.append(symbol * count) num -= count * value num (end)
1000 ‘M’ 1994 1 res = ['M'] 1994 - 1000 994
900 ‘CM’ 994 1 res = ['M', 'CM'] 994 - 900 94
500 ‘D’ 94 0 – – 94
400 ‘CD’ 94 0 – – 94
100 ‘C’ 94 0 – – 94
90 ‘XC’ 94 1 res = ['M', 'CM', 'XC'] 94 - 90 4
50 ‘L’ 4 0 – – 4
40 ‘XL’ 4 0 – – 4
10 ‘X’ 4 0 – – 4
9 ‘IX’ 4 0 – – 4
5 ‘V’ 4 0 – – 4
4 ‘IV’ 4 1 res = ['M', 'CM', 'XC', 'IV'] 4 - 4 0
1 ‘I’ 0 (break loop) – – 0

Finally, ''.join(res) gives us "MCMXCIV", which is the correct answer! This greedy approach, combined with a carefully constructed and ordered lookup table, handles all the Roman numeral rules elegantly.

💻 Code

class Solution:
    def intToRoman(self, num: int) -> str:
        # Define the Roman numeral values and their corresponding symbols.
        # This list is crucial: it must be sorted in descending order of values,
        # and include the special subtractive forms (like 900 for CM)
        # BEFORE their additive components (like 500 for D and 100 for C).
        value_symbols = [
            (1000, 'M'), (900, 'CM'), (500, 'D'), (400, 'CD'),
            (100, 'C'), (90, 'XC'), (50, 'L'), (40, 'XL'), (10, 'X'),
            (9, 'IX'), (5, 'V'), (4, 'IV'), (1, 'I')
        ]

        # Initialize an empty list to store the Roman numeral characters.
        # Appending to a list and then joining is generally more efficient
        # than repeated string concatenation in Python.
        res = []

        # Iterate through our defined value-symbol pairs.
        for value, symbol in value_symbols:
            # If num has become 0, we've converted the entire number,
            # so we can break early.
            if num == 0:
                break

            # Calculate how many times the current 'value' fits into 'num'.
            # E.g., if num = 3000 and value = 1000, count = 3.
            count = num // value

            # Append the 'symbol' repeated 'count' times to our result list.
            # E.g., if count = 3 and symbol = 'M', it appends 'MMM'.
            res.append(symbol * count)

            # Subtract the converted portion from num.
            # E.g., num = 3000 - (3 * 1000) = 0.
            num -= count * value

        # Join all the symbols in the list to form the final Roman numeral string.
        return ''.join(res)

⏱️ Time & Space Complexity Analysis

Let’s break down how efficient our solution is:

  • Time Complexity: O(1)

    • The value_symbols list has a fixed size (13 elements).
    • We iterate through this list exactly once.
    • Inside the loop, operations like integer division (//), multiplication (*), list append(), and subtraction (-) take constant time. The string multiplication symbol * count and append are also bounded because the maximum count is small (at most 3 for ‘I’, ‘X’, ‘C’, ‘M’) and the Roman numeral string’s total length for num <= 3999 is very short (e.g., “MMMCMXCIX” for 3999 has 7 characters).
    • Since the number of iterations and the work done in each iteration are bounded by a constant (independent of the input num‘s magnitude, within the given constraints), the overall time complexity is constant.
  • Space Complexity: O(1)

    • The value_symbols list is a fixed-size data structure (13 tuples), so it takes constant space.
    • The res list stores the characters of the resulting Roman numeral string. The maximum length of a Roman numeral for an integer up to 3999 is also very small (e.g., “MMMCMXCIX” has 7 characters).
    • Therefore, the space used is bounded by a constant, leading to O(1) space complexity.

This solution is incredibly efficient because it leverages the fixed and relatively small nature of the Roman numeral system’s rules and symbols.

🎯 Key Takeaways

  • Greedy Approach Power: This problem is a classic example where a greedy approach shines. By always taking the largest possible valid Roman numeral component first, and ensuring your lookup table accounts for special cases (like subtractive forms) in the correct order, you can simplify complex rules.
  • Lookup Tables are Your Friend: When dealing with predefined mappings or rules, a well-structured lookup table (like our value_symbols list) can make your code much cleaner and easier to reason about than a series of nested if/else statements.
  • Order Matters! For greedy algorithms, the order of elements in your lookup table is paramount. Always ensure the largest values (including special combinations) come first.
  • Python String Efficiency: Appending to a list and then using ''.join() is generally more efficient for building strings than repeated string concatenation (+=) in Python, especially for potentially longer strings (though in this specific problem, the string length is so small that the difference would be negligible).

And there you have it! Converting integers to Roman numerals might seem tricky at first, but with a solid understanding of the rules and a well-designed greedy approach, it becomes quite straightforward.

Happy coding!

Author Account: p1Hzd8mRM8
Publishing Time: 2026-05-21 17:05:20

🚀 A Beginner’s First Look at Project IDX: Secure Coding from Day One

This is a submission for the Google I/O Writing Challenge

Hey everyone! 👋 Hima Kartikeya here!

I just finished my Class 10 ICSE board exams and I am getting ready to start my polytechnic diploma journey in Andhra Pradesh. My absolute dream is to build a career in Cyber Security, but to keep my creative side active, I’m also a small-scale indie game developer.

Right now, my programming baseline is mastering loops in Python and C, alongside basic Java concepts. While watching the Google I/O 2026 keynotes and going through the developer documentations, one specific release completely blew me away: the massive new upgrades to Google Project IDX.

As a beginner who cares about security, I don’t just want an IDE that helps me write code faster—I want a workspace that helps me write code safer. Here is my perspective on why Project IDX is a game-changer for student developers.

🌐 The Magic of Isolated Cloud Sandboxing

When you are learning low-level languages like C, managing memory manually is a massive hurdle. One wrong line of code can trigger a logic error, cause a memory leak, or create an accidental infinite loop that freezes your entire system.

The Google I/O announcements highlighted Project IDX’s advanced, browser-based virtualized Nix environments.

  • Why it matters to a beginner: It means I can test risky code, write complex loops, and build game scripts in an environment that is entirely separated from my actual computer hardware. If I accidentally create a code block that mimics a Denial of Service (DoS) attack or causes a memory crash, it happens safely inside Google’s cloud sandbox without putting my own machine at risk. It turns the workspace into a safe playground for testing security limits.

🧠 Built-In Security Guardrails: Shifting Security Left

What really caught my eye in the I/O 2026 livestream sessions was how Project IDX is integrating smarter AI-driven security linting right into the workspace.

In my indie game dev practice, I realized how easy it is to leave variables unprotected, allowing a player to easily tamper with game data (like editing health or coin values in memory). The new code-assistance features in IDX don’t just autocomplete your loops; they actively flag potential vulnerabilities as you type.

If my code blindly trusts client-side input or lacks a proper validation check, the workspace alerts me before I deploy. This teaches a student like me the most important rule of modern cyber security: Security isn’t something you patch onto a project at the very end; it belongs to the creator from line one.

💡 My Critique & Takeaway

A lot of the hype around modern developer tools focuses on pure speed and corporate automation. But for students, beginners, and indie creators, the entry barrier to setting up a secure, properly configured local environment is incredibly high.

By making a powerful, cloud-sandboxed environment completely accessible through a browser tab, Google is democratizing secure development. My only critique is that I want to see even deeper integrations for local game engine compilers in the cloud workspace moving forward!

Stepping into my diploma journey, I won’t just be using textbooks to learn security theory. I’ll be spinning up workspaces in Project IDX to actively break and defend my own code in real time.

Over to the Community:
For the seasoned developers and security experts out there: Have you experimented with Project IDX yet? What is your favorite workspace tool for safely testing untrusted code or debugging complex loops? Let’s talk in the comments! 🚀👇