Mert
GPU tamam, sırada CPU var: Nvidia, dünyanın en büyük CPU üreticilerinden olacak
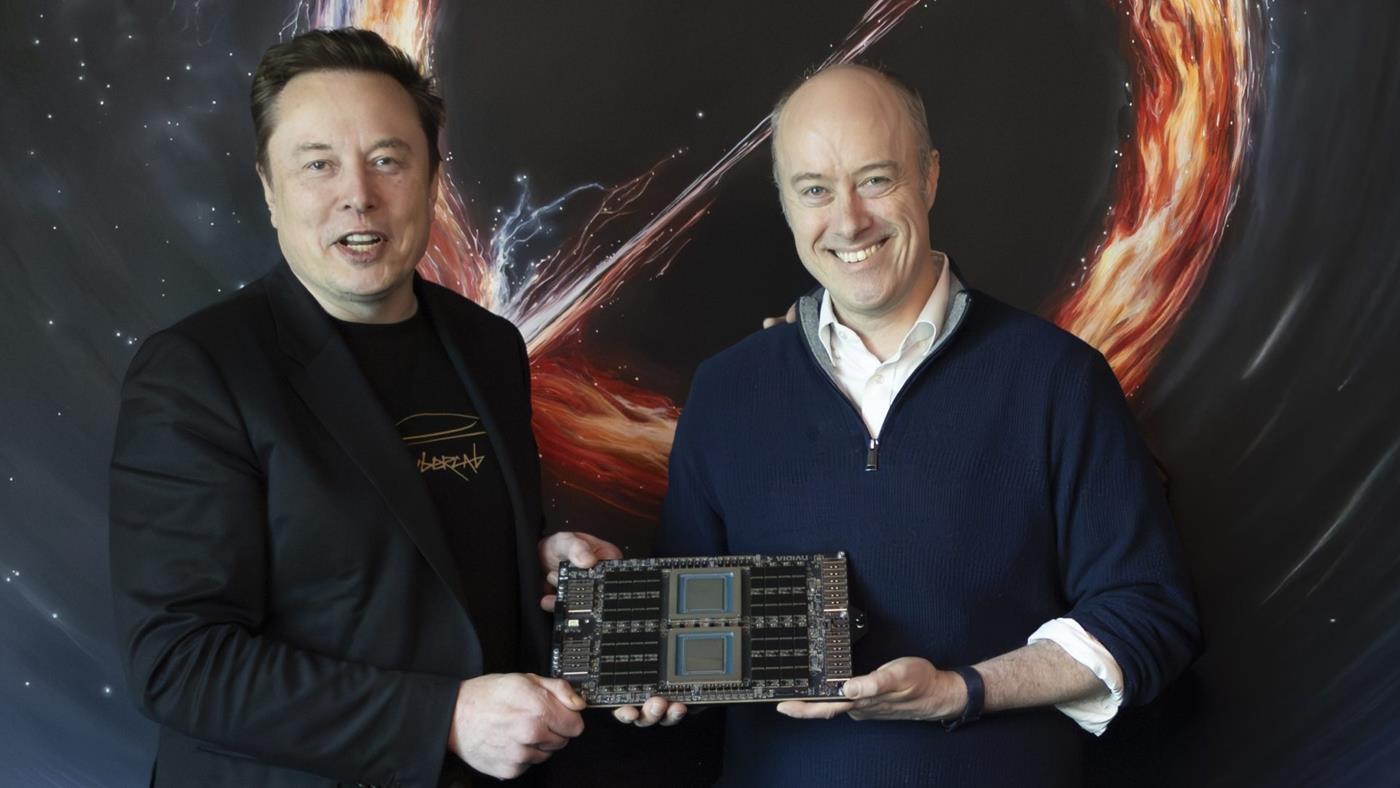
Nvidia şimdi de CPU pazarında liderliği hedefliyor. Şirket, yeni Vera işlemcileriyle bu yıl 20 milyar dolarlık CPU geliri beklerken 200 milyar dolarlık yeni bir pazara girdiğini açıkladı.ASML doğruladı: Yeni nesil High-NA EUV çipleri geliyor
ASML, yeni nesil High-NA EUV makineleriyle üretilen ilk silikonların birkaç ay içinde hazır olacağını açıkladı. Teknoloji, daha küçük ve güçlü çiplerin önünü açabilir.AMD, Nvidia’ya karşı büyük oynadı: Ryzen AI Halo ve Ryzen AI Max 400
AMD, Ryzen AI Halo sisteminin fiyatını açıklarken 192 GB birleşik belleğe sahip yeni Ryzen AI Max 400 işlemcilerini de tanıttı. Şirket, yerel yapay zeka performansında Nvidia’yı hedef alıyor.Accessibility – This looks like a job for a developer advocate!
At the beginning of last year, I started a new role as an accessibility-focused frontend engineer. Tech accessibility (or a11y for short) became my dream career while studying that field during the pandemic and also talking to accessibility professionals on social media.
In particular, a11y drew me in as I learned how designing with a11y in mind doesn’t only help disabled and neurodivergent people, but in fact regularly leads to tech that makes everyone’s lives better. One of the most popular examples of that is how a lot of the early motivation for inventing the typewriter was to facilitate writing for people who are blind and low-vision, and now we’re all typing! Likewise, by designing a web app to keyboard-operable, in addition to being usable for someone with motor disabilities that make using a mouse difficult, that also benefits power-users who love a good keyboard shortcut.
But one of the biggest surprises as I got onboarded to the job and as I started going to a11y conferences, was how the skills that I use as an accessibility professional, are almost exactly the same ones I had cultivated toward what my dream career previously was: Developer Relations (devrel).
Accessibility and developer relations are surprisingly similar fields of tech; just about any skill that helps a developer advocate thrive, can also be applied in an accessibility role! To see what I mean, let’s take a look at a few of my favorite similarities between a11y and devrel. If you’re in, or interested in, either devrel or accessibility, this post is for you!
Community building
What made me want to be a developer advocate in 2017 wasn’t just the romanticized parts about globe-trotting between conferences (but let’s be real, that didn’t hurt). More than that, it was how much of devrel work is centered around building a supportive community. And as I got interested in accessibility, I quickly found out a11y is also somewhere community-builders really shine.
A successful devrel program is one that not only helps people solve problems with your tech, it also creates a community around that technology. That goes from holding workshops, to explaining concepts that are new for nearly everyone (particularly true in fast-changing fields like AI and agents!), to writing well-maintained API documentation, to artwork that brings your programming language to life with a silly cartoon mascot that everyone loves to draw their own versions of. All of that both helps developers solve their problems with your tech, and gets them excited for whatever you and your team are building next.
Accessibility is just as much about community as devrel is. One of the first things you hear about as you start participating in accessibility discourse, is about just how interdisciplinary the field is. Just about every role in a company, from UX design, to UI engineering, to product management, to customer support, to documentation writing, all the way up to the C-suite, has a role to play in making a product accessible. A winning accessibility program is less a single team, and more a community that spans many different teams and roles.
In both fields, part of that community building is encouraging contributions from your community. The best devrel professionals make people feel appreciated for things like contributing to their open source projects and inviting their friends to the community. Similarly, the best accessibility professionals are great at showing people from different roles what exactly they can do from their own role to prevent accessibility issues and build accessible products.
So whether accessibility or devrel is your thing, any community-building skills you’ve got or you’re honing will help you do impactful work.
Communication
At the center of community building for both devrel and a11y professionals, is being a great communicator, both within your own team, and with people who might have very different context, expertise, and priorities from your own role, both within your company and with customers.
A developer advocate might on one day be working with their teammates to build a demo app in their framework with realistic examples. Or be writing a tutorial to highlight exactly how to solve problems with it. Or on another day they might be hearing about pain points customers are having with using that tool, and then integrating that feedback into features for the tool they’re building or into more robust documentation.
Similarly, accessibility work on some days might be reviewing designs and prototypes to distill accessibility requirements alongside designers. On other days it might be translating that to code requirements for engineering teammates. It can be evaluating accessibility tools to figure out their strengths and limitations so they know which problems a tool does or doesn’t solve, and then sharing a write-up about that with stakeholders. Or it might be testing a web app for accessibility bugs and writing the results of that in enough detail for a bug report to be actionable.
Just about any communication skill can be either a devrel or an a11y skill, whether that’s writing, giving tech talks, drawing diagrams, or talking to customers. So if you’re interested in either field, keep growing as a communicator.
By the way, although both accessibility and developer relations are “people jobs”, you don’t have to be an extrovert to be a “people person”. Many talented communicators in both fields are introverts. What matters more than which social style you have, is knowing how to meet people where they are.
Meeting people where they are
If you’ve ever coded in a community where even as a newcomer, you felt supported and could ask a question without feeling talked down to when someone answers it, that’s a prime example of the impact of meeting people where they are in devrel. In fact it’s precisely why the really supportive Go community is where I fell in love with devrel! Both within and outside of devrel, the Gophers are a community where there’s no “noob questions”.
Likewise, meeting people where they are is a critical accessibility skill because of how integral it is to cross-role coordination. People in different roles have different problems they are trying to solve, use different terminologies, and even people within the same role can have very different accessibility skill sets. Someone might have a strong grasp of color contrast but be new to screen reader testing, for example. They might have learned about designing their animations to prevent seizures, while being new to understanding how to design an app’s layout to make it intuitive for autistic people to navigate, which is a conversation where the best-practices are still emerging.
And when it comes to meeting people where they are, that “where they are” can sometimes be in a stressful, frustrating place. A developer advocate who can write clear documentation with real-world examples, is a lifesaver for someone onboarding to a framework while they’re on a tight deadline. Likewise, the amount of work to get a product accessible, often with having to learn new skills for the first time, can be really demoralizing. So if you can take the lead with ideas of what someone in another role might do first to solve an accessibility problem, that gives your teammates some momentum and problem-solving intuition to work with.
That is why emotional intelligence travels well between both fields. While that’s often called a “soft skill”, I prefer the term April Wensel uses, “catalytic skills“. Both in a11y and devrel, if you can teach from where people are, in different roles or different learning styles, you’re catalyzing someone else’s success!
Sense of fun
Finally, accessibility and devrel are both great fields to bring your sense of fun to. As I mentioned, community-building is at the core of both successful a11y programs and successful devrel programs. A significant aspect of that, is helping people see themselves as part of the community you’re helping to build. And making the community fun to participate in goes a long way on giving that welcoming feeling!
In devrel, probably the most saliently-recognizable example of that to someone outside the field, would be the stickers and swag that developer advocates give out at tech events. But there’s also a lot of intangible ways to make a tech community fun that are just as important. One of the best pieces of advice on tech public speaking that I’ve gotten, from a video by the founder of #CodeNewbie Saron Yitbarek, was about how the secret to an engaging, memorable talk is to approach it from the perspective of storytelling, rather than a college lecture.
The #CodeNewbie community itself, by the way, is an excellent example of both fun and supportiveness in devrel, facilitating a lot of great conversations with people studying and working in every field of tech. Just as the Gophers got me interested in devrel, talking to a11y professionals on the #CodeNewbie chats helped sow my interest in accessibility!
On accessibility, a sense of fun likewise inspires both curiosity about a11y in general, and the curiosity that leads to great innovations. For example, at the last CSUN Assistive Tech conference, my favorite talk outside of my job, was about making computer games that are entirely audio-based. That was my first time hearing about audio gaming, and it made me curious both about trying those games myself, and about how else that technology can be used to create web experiences that feel lively whether you’re sighted or blind/low-vision. I also lately have been thinking that a game around screen reader and keyboard navigation could help get more developers familiar with both those modes of navigation.
I hope this post showed you how accessibility and devrel are two peas in a pod. Now I’d love to know, what similarities between a11y and devrel do you see? Or if you’re a career-changer into either of those fields, what similarities do you see between a11y/devrel and your old field?

I built a Mac app that turns web pages into live widgets
I’m the developer of Kepo, a Mac app I started building because I kept checking the same web pages over and over again.
Product Hunt launches. Reddit threads. GitHub releases. YouTube channels. Docs. Small dashboards. Status pages.
Each check only takes a few seconds, but the workflow is surprisingly expensive:
- switch back to the browser
- find the right tab
- refresh or scroll
- read one small piece of information
- switch back to what I was doing
After repeating this enough times, I started wondering if some web pages should not be tabs at all. Some of them feel more like small pieces of state that should sit closer to the desktop.
That was the starting point for Kepo.
The product idea
Kepo turns web pages into live Mac desktop widgets.
The goal is not to recreate a whole browser inside a widget. The goal is to take the part of a page that you repeatedly care about and make it available in a small, glanceable interface.
For example:
- today’s Product Hunt launches
- a Reddit thread you are following
- GitHub releases or issues
- a YouTube channel update
- a docs page section
- a small internal dashboard
- a checklist, timer, formatter, or monitor
Kepo lives in a floating desktop panel that can be opened with a shortcut, closer to the way Raycast fits into a developer workflow. You bring it up, check or use a widget, then go back to your work.
The tricky part: web pages are not APIs
At first, this sounded simple: take part of a page and render it as a widget.
In practice, web pages are messy.
A page can depend on login state. It can lazy-load content. The DOM can change. Some sites expose a feed or API, while others only expose rendered HTML. Some pages are stable enough to parse directly, while others need a browser context to understand what the user actually sees.
So the hard part is not only “extract data from a page”.
The harder questions are:
- what is the smallest useful version of this page?
- what should happen when the page fails to load?
- how often should it refresh?
- what information should be hidden in a small widget?
- when should the widget open the original page instead of trying to replicate it?
This is where I started thinking of widgets less as small UIs and more as small contracts.
A good widget has a clear promise: “I will show you this specific piece of information in this specific shape, without forcing you to open the full page every time.”
Where AI fits
Kepo includes an AI creation flow. You can point it at a page and ask it to build a widget from it.
AI is useful here because the first version of a widget is often structural work:
- inspect the page
- decide which data matters
- sketch the UI
- generate the widget code
- adjust the layout for small sizes
But I do not think AI removes the design problem.
The human part is still deciding what the widget should mean. For a Product Hunt page, do you want the full feed, the top launches, vote counts, comments, or just a launch checklist? For a GitHub page, do you want releases, issues, pull requests, or a status monitor?
AI can help build the first version faster. It cannot automatically know what deserves to stay on your desktop.
Making it useful for developers
I also did not want custom widget creation to be locked entirely behind the built-in AI flow.
So Kepo has a free Skills-based development path for developers who already use local coding agents like Claude Code or Codex.
You can install the Skill with:
npx skills add Enivel/kepo-plugin-dev-skill
That lets developers build and run custom widgets locally. The built-in AI creation flow is paid, but the Skills path is free to use.
This makes the product feel closer to a small desktop platform than a fixed widget gallery. There are ready-to-use widgets, but developers can also build their own.
What I am still trying to figure out
The biggest open question is not whether the technology works. It is where this belongs in a developer’s daily workflow.
Some widgets clearly make sense:
- CI status
- server health
- GitHub releases
- launch pages
- docs snippets
- feed monitors
- small local tools
Other cases probably still belong in the browser.
That boundary is what I am trying to learn from real users.
If you are a developer, what web page would you actually want to turn into a desktop widget?
Not in a “this looks cool” way, but in a “I check this often enough that I would save time if it lived one shortcut away” way.
How to Teach Source Evaluation When Your Students Use ChatGPT
The classroom has changed. Students don’t come to research sessions empty-handed anymore. They arrive with answers — polished, confident, plausible-sounding answers that ChatGPT or Copilot or Gemini produced in under ten seconds.
Your job used to be teaching them how to find information. Now it’s teaching them what to do with information they’ve already found — and why that second step is harder than it looks.
The good news: source evaluation has never been more urgent, more teachable, or more relevant to students’ actual lives. The challenge is redesigning instruction for learners who’ve already outsourced the first step of research to a machine.
Here’s what’s working.
The “Don’t Use AI” Policy Doesn’t Work. Here’s What Does.
Let’s skip past the policy debate. Students are using AI tools whether your school has a ban or not. The question isn’t whether they’ll encounter AI-generated content — it’s whether they’ll know how to interrogate it.
The librarians and educators getting traction right now aren’t fighting the tools. They’re turning them into teaching material.
5 Strategies That Actually Work in the Classroom
1. The AI Audit Assignment
Ask students to submit two versions of a research summary: one generated by an AI tool (ChatGPT, Copilot, Gemini — their choice), and one they wrote themselves after conducting their own source investigation.
Then ask them to annotate the differences.
Where did the AI get it right? Where did it oversimplify, hallucinate, or omit critical context? What sources did the AI cite — and do those sources actually say what it claims?
This assignment does several things at once: it validates that students can use AI (no performative bans needed), it builds metacognitive awareness about AI limitations, and it forces direct comparison between machine output and human-verified research. Students who do this exercise once tend to permanently recalibrate their trust in AI-generated content.
2. Lateral Reading Exercises — With AI Claims
Lateral reading is the practice fact-checkers use: instead of reading a source deeply and trying to evaluate it from the inside, you open multiple tabs and find out what other credible sources say about it.
Apply this directly to AI output. Give students a specific claim from a ChatGPT response and a 10-minute timer. Their task: verify or refute that claim using at least three independent sources. No AI assistance during the exercise.
The results are often striking. Students find outdated statistics, misattributed quotes, and confident-sounding claims that don’t survive five minutes of lateral reading. It’s not about gotcha moments — it’s about building the reflex to check before trusting.
3. Source Comparison: AI Summary vs. Primary Source
Pick a topic your students are already studying. Run a ChatGPT query on it and print the response. Then pull the peer-reviewed article, government report, or primary source document that AI should have been drawing from.
Put both in front of students. Ask them to identify: What did the AI include? What did it leave out? Did it introduce claims not supported by the original? Did it accurately represent the author’s conclusions?
This exercise is particularly effective because students can see the compression and distortion that happens when a large language model summarizes complex material. The primary source becomes legible in a new way — not as intimidating academic text, but as the thing the AI was approximating.
4. The “Prove It” Protocol
Simple, portable, and works at any grade level.
Every AI-sourced claim in a student’s work requires a primary source citation before it can stay. No primary source? The claim comes out.
Students using this protocol quickly discover two things: (1) AI often can’t tell them where it got something, and (2) when it does cite sources, those sources don’t always say what AI claimed. The protocol isn’t punitive — it’s a habit-forming discipline. Researchers who ask “prove it” of every unverified claim are more rigorous, full stop.
5. An Evaluation Rubric That Accounts for AI
Most source evaluation rubrics — including the venerable CRAAP Test — were designed before generative AI existed as a research tool. They need updating.
When adapting your rubric for AI-era research, add explicit checks:
- Traceability: Can every specific claim be traced to a named, verifiable source?
- Currency of underlying sources: When was the AI’s training data current? (Most models have a knowledge cutoff that may be 1-2 years behind.)
- Consistency across tools: Does a different AI tool, or a direct source search, return the same information?
- Synthesis transparency: Has the student verified the sources an AI cites, rather than trusting the citation?
A rubric that rewards this kind of verification teaches evaluation as a process, not a checkbox.
Where Sabia Librarian Fits In
Part of the challenge with AI literacy instruction is that it can feel abstract until students try it with real tools. Sabia Librarian is designed to function as a demonstration of AI that’s built for verification — it surfaces primary sources, flags claims that need corroboration, and models the kind of cite-before-you-trust behavior we’re trying to teach.
Several educators are using it as a classroom example: “Here’s an AI tool. Here’s how it approaches a research question differently than a general-purpose chatbot. What do you notice?”
It’s not the only tool that fits this kind of lesson. But it’s one that was designed with information literacy built in, not bolted on.
The Bigger Picture
Teaching source evaluation in 2026 isn’t about convincing students that AI is bad. It’s about giving them the judgment to use it well — and the skills to catch it when it’s wrong.
The strategies above aren’t new pedagogy. Lateral reading, primary source comparison, and citation verification are foundational information literacy practices. What’s new is the urgency. Students without these skills aren’t just writing weaker papers. They’re navigating a world where machine-generated misinformation is indistinguishable from credentialed expertise at first glance.
That’s the librarian’s problem now. Which means it was always ours to solve.
Looking for a tool built around these principles? Visit sabialibrarian.com.
RAG Series (24): Code RAG — Teaching AI to Understand Your Codebase
The Difference Between Code and Documents
Split a Python file into 1000-character chunks with RecursiveCharacterTextSplitter, embed them, run vector search — this is the most common “code RAG” implementation. The problem is that it treats code as text:
def evaluate_rag(questions, answers, contexts):
"""Evaluate RAG system quality"""
...(50 lines of code)...
Character-based chunking will:
- Split functions in half (first half in chunk A, second half in chunk B)
- Lose function boundary information (this IS
evaluate_rag, not random text) - Ignore call relationships (what this function calls, who calls it)
- Destroy structural hierarchy (this is a method of
RAGPipeline)
Code carries three layers of information: semantics (what it does), structure (function/class/module boundaries), call relationships (who calls whom). Good code RAG models all three.
This article uses llm-in-action as the target and builds a code RAG system capable of answering “how is this function used?” and “show me all call chains through this function.”
Parse Code with AST, Not Character Offsets
Python’s ast module parses source files into syntax trees. A function definition is a node (ast.FunctionDef) with its exact start line, end line, and decorator list. Chunking at AST boundaries guarantees splits at function edges:
class _FuncExtractor(ast.NodeVisitor):
def __init__(self, source: str, rel_path: str):
self._lines = source.splitlines()
self._rel_path = rel_path
self._class_stack: list[str] = []
self.units: list[CodeUnit] = []
def visit_ClassDef(self, node: ast.ClassDef):
# Track current class so methods know their parent_class
self._class_stack.append(node.name)
self.generic_visit(node)
self._class_stack.pop()
def _visit_func(self, node):
# Extract source by line number, not character offset
src = "n".join(self._lines[node.lineno - 1 : node.end_lineno])
unit = CodeUnit(
name = node.name,
kind = "method" if self._class_stack else "function",
file = self._rel_path,
start_line = node.lineno,
end_line = node.end_lineno,
source = src,
docstring = ast.get_docstring(node) or "",
parent_class = self._class_stack[-1] if self._class_stack else "",
calls = self._extract_calls(node),
)
self.units.append(unit)
self.generic_visit(node)
visit_FunctionDef = _visit_func
visit_AsyncFunctionDef = _visit_func
Call relationships are extracted from ast.Call nodes:
def _extract_calls(self, node) -> list[str]:
calls: set[str] = set()
for child in ast.walk(node):
if isinstance(child, ast.Call):
if isinstance(child.func, ast.Name):
calls.add(child.func.id) # direct call: foo()
elif isinstance(child.func, ast.Attribute):
calls.add(child.func.attr) # attribute call: self.foo()
return sorted(calls)
Extraction results on llm-in-action
Scanned: /mnt/hdd/Database/03_Projects/LLM/llm-in-action
Time: 0.13 seconds
Python files: 22
Functions: 188 (top-level)
Methods: 37 (class methods)
Total units: 225
Article dirs: 18
0.13 seconds to scan the entire codebase. AST parsing doesn’t execute code, so there are zero side effects.
Call Graph: Understanding Who Calls Whom
Once function call relationships are extracted, build a bidirectional adjacency map — queryable in both directions:
class CallGraph:
def __init__(self, units: list[CodeUnit]):
self.callees: dict[str, set[str]] = defaultdict(set) # caller → called
self.callers: dict[str, set[str]] = defaultdict(set) # callee → caller
known = {u.name for u in units}
for u in units:
for callee in u.calls:
if callee in known: # intra-repo edges only
self.callees[u.name].add(callee)
self.callers[callee].add(u.name)
def downstream(self, name: str, depth: int = 4) -> list[str]:
"""All functions transitively called by name (BFS)."""
return self._bfs(name, self.callees, depth)
def upstream(self, name: str, depth: int = 4) -> list[str]:
"""All functions that transitively call name (BFS)."""
return self._bfs(name, self.callers, depth)
def shortest_path(self, start: str, end: str) -> Optional[list[str]]:
"""Shortest call path from start → end."""
queue: deque[list[str]] = deque([[start]])
visited: set[str] = {start}
while queue:
path = queue.popleft()
if path[-1] == end:
return path
for nxt in self.callees.get(path[-1], set()):
if nxt not in visited:
visited.add(nxt)
queue.append(path + [nxt])
return None
Call graph analysis results
Call graph statistics:
Functions with outgoing edges: 78 (they call others)
Functions with incoming edges: 92 (they are called)
Total edges: 168
Most-called functions (the codebase’s core utilities):
get ← called from 48 places (cache reads throughout all articles)
set ← called from 10 places (cache writes)
split_documents ← called from 5 places (shared chunking helper)
build_embeddings ← called from 4 places
query ← called from 4 places
get appearing 48 times reflects Python duck typing — cache .get() calls across SemanticCache, InMemoryCache, and similar types all collapse to the same name in static analysis.
Functions with the most outgoing calls (orchestrators):
main → 54 direct calls
build_self_rag_graph → 6 direct calls
build_index → 5 direct calls
build_ragas_dataset → 5 direct calls
main calling 54 functions is the signature of an entry point — it orchestrates the full pipeline by calling every sub-step.
Call chain traversal
build_self_rag_graph (14-self-rag/self_rag.py) full downstream:
build_self_rag_graph
├── make_retrieve_node
├── make_filter_node
├── make_decide_node
├── make_support_node
├── make_rag_generate_node
└── make_direct_generate_node
This is exactly the Self-RAG StateGraph builder pattern: one factory function assembles all graph nodes, each node is an independent small function. The call graph makes this structure immediately visible.
build_index (08-ragas-eval/rag_pipeline.py) downstream chain:
build_index
→ load_documents
→ build_llm
→ build_embeddings
→ split_documents
→ get (cache)
A canonical RAG initialization sequence: load docs → build LLM → build embeddings → chunk → cache.
Vector Store: Semantic Code Search
Code vectorization has one engineering constraint: function source can be long (50–200 lines), but embedding APIs commonly have a 512-token limit.
Solution: separate the retrieval unit from the Q&A context.
- Embedding content: function name + docstring (short, semantically precise, fits in token budget)
- Metadata: complete source code (stored in Chroma’s metadata field, read at Q&A time for LLM context)
sig_line = u.source.splitlines()[0]
embed_content = f"{full_name}: {u.docstring or sig_line}"[:400]
Document(
page_content = embed_content, # vectorized — used for retrieval
metadata = {
"name": u.name,
"file": u.file,
"start_line": u.start_line,
"source_code": u.source[:2000], # not vectorized — used for LLM context
},
)
At Q&A time, retrieval finds relevant functions, then the full source is read from metadata:
docs = vs.similarity_search(question, k=4)
context = "nn---nn".join(
d.metadata.get("source_code", d.page_content)[:600] for d in docs
)
Semantic search results
Query: "RAGAS evaluation metrics calculation"
0.488 RAGPipeline.build_index (08-ragas-eval/rag_pipeline.py:95)
0.476 create_ragas_embeddings (08-ragas-eval/evaluate.py:50)
0.467 RAGPipeline.query (08-ragas-eval/rag_pipeline.py:141)
Query: "rate limiting and access control in enterprise RAG"
0.504 RAGPipeline.__init__ (08-ragas-eval/rag_pipeline.py:78)
0.497 RateLimiter.__init__ (20-enterprise-rag/enterprise_rag.py:118)
Query: "incremental document indexing with record manager"
0.296 generate_testset (08-ragas-eval/generate_qa.py:51)
Query: "conversational history aware retriever"
0.400 make_ds (18-conversational-rag/conversational_rag.py:428)
RAGAS and enterprise RAG rate limiting queries found the right files. Incremental update didn’t — because the functions in 19-incremental-update/ don’t mention “record manager” in their docstrings, only in their source code bodies. This is the core limitation of docstring-only embedding: search quality is bounded by docstring quality.
Choosing a Code Embedding Model
General-purpose text embedding models (BGE, text-embedding-3) are “adequate but not great” for code. They can retrieve by docstring, but don’t understand that for i in range(n): acc += arr[i] is an accumulation.
Specialized code embedding models:
| Model | Characteristics |
|---|---|
microsoft/codebert-base |
Code + documentation dual-tower; understands variable names and signatures |
Salesforce/codet5-base |
Generative model; suited for code completion + retrieval |
nomic-ai/nomic-embed-text-v1.5 |
General model with strong code performance; 8192-token limit |
voyage-code-2 |
Voyage AI’s code-specialized model; among the best available |
Recommended: if token limits aren’t a concern (e.g., nomic-embed-text-v1.5 supports 8192 tokens), embed the complete function source directly — no need to split docstrings from source.
The Complete Code RAG Pipeline
# Build a code RAG system
# 1. AST extraction: all functions and methods
units = extract_repo(repo_dir)
# 2. Call graph: bidirectional adjacency
cg = CallGraph(units)
# 3. Vector store: docstrings for retrieval, source_code in metadata for Q&A
vs = build_vectorstore(units, embeddings)
# Three query modes
# A: Semantic search — find functions by meaning
hits = vs.similarity_search("embedding caching", k=5)
# B: Call chain — given a function name, find all upstream/downstream
callers = cg.upstream("build_embeddings") # → who calls it
callees = cg.downstream("main") # → what it calls
path = cg.shortest_path("main", "get") # → how main reaches get
# C: LLM Q&A — retrieve context, generate answer
answer = llm_code_qa("How is incremental update implemented?", vs, llm)
Results Summary
| Metric | Value |
|---|---|
| Python files | 22 |
| Code units extracted | 225 (188 functions + 37 methods) |
| AST parse time | 0.13 seconds |
| Call graph edges | 168 |
| Vectorization time | 5.8 seconds |
| Most-called function |
get (48 places) |
| Widest caller |
main (54 direct calls) |
Full Code
Complete code is open-sourced at:
https://github.com/chendongqi/llm-in-action/tree/main/24-code-rag
Key file:
-
code_rag.py— AST extraction, call graph, vectorization, search, report
How to run:
git clone https://github.com/chendongqi/llm-in-action
cd 24-code-rag
cp .env.example .env
pip install -r requirements.txt
python code_rag.py
Summary
The core difference between code RAG and document RAG:
| Document RAG | Code RAG | |
|---|---|---|
| Chunk unit | Fixed-size text blocks | Functions/methods (AST boundaries) |
| Structure | None | Class hierarchy, module hierarchy |
| Call relationships | None | Call graph (bidirectional) |
| Embedding content | Full text | Docstring + signature (or full source) |
| Query types | Semantic search | Semantic search + call chain traversal |
Three key tradeoffs:
- AST vs text chunking: AST cuts at function boundaries and preserves complete units. Text chunking is faster but destroys structure. For production code RAG, use AST — there’s no reason not to.
- Docstring vs full source embedding: Under token constraints, embed docstrings (short and semantically focused) — but quality depends on docstring completeness. With a long-context embedding model, embed the full source directly.
- Call graph vs pure vector retrieval: Vector retrieval finds semantically similar functions; the call graph answers “what does X call?” and “who uses X?” — they’re complementary, not interchangeable.
This is the final article in the RAG series. Twenty-four articles covering the complete path from “what is RAG?” to “how do you teach AI to understand a codebase?” All code is open-sourced at llm-in-action — every article has a runnable demo and a real benchmark report.
References
Past the JVM
Learning Java got me thinking how exactly does things word under the hood.. I’m not talking about Java in Particular I’m mentioning programming in General how does a command I Write on my shell or bash terminal get executed in the machine
- What role does the kernel play in all of this
- And who does all the heavy lifting internally is it the kernel or the hardware
I did research on all of this let me walk you through it

The user and the shell
When I type a command, the shell interprets it and decides which actions to take.
System Calls
The shell issues system calls eg fork(), execve(), and open() to request services from the kernel.
Kernel to Hardware
The kernel handles the system calls, communicates with device drivers, and interacts with hardware safely and in a controlled way.
Back to user
The output appears in the terminal all of this happens in milliseconds
What so great about all this is how every user program, not just the shell, uses system calls to communicate with the kernel. It’s like a controlled gateway to the operating system
I’d like to do more research about this Java in particular this time we’ll go under the
Design decisions behind my “Irregular German Verbs” iOS app
A pet project is, first of all, a way to learn something new in your own field. I have a 9–5 job, but I almost always work on some side projects as well. The difference is that until now I had never actually brought one to the App Store like my current app — Irregular German Verbs. Why did I finish this one? And why exactly this topic?
Thanks to my wife — a university German language teacher with 25 years of experience. She clearly understood which topic should become a standalone app and how exactly it should be presented. The app is based on my wife’s educational ideas, and the app itself clearly states whose educational methodology it is based on.
You can find the full list of product decisions on the product page. In this article, I want to explain why these particular decisions were made.
One problem, One tool
Irregular German Verbs is a very narrow topic. The app contains only 191 verbs that simply have to be memorised. At first glance, it may seem more logical to build something larger and more universal. We discussed that option as well. But when I suggested making something bigger, I received a categorical “no”. And the reasons were purely educational:
- this topic should not be mixed with any other;
- Irregular German Verbs is difficult because these verbs simply need to be memorised — there are no rules here;
- a proper memorisation system is required, a simple table is not enough.
That is exactly the approach I started development with.
No ads, No tracking, No subscriptions
Learning requires concentration. Ads and tracking create unnecessary distraction and stress. As a developer, I tried to argue for ads a little. But my wife, as a teacher, responded with a very clear “no”. When she teaches students, distractions are not acceptable.
And when it comes to subscriptions, I personally dislike them as well and try to avoid them whenever possible. If translated into the educational process, this app should feel more like buying a book: you pay once and continue using it peacefully afterwards. Which feels honest and familiar for students.
Free A1-A2
The app includes a decision that is not very obvious and definitely not very profitable for a developer — A1-A2 levels are completely free. And that is basically one third of all verbs in the app. But this decision also comes from educational principles. Everyone learns differently:
- some people prefer video;
- some prefer audio;
- some prefer books.
A student should be able to calmly try the material and understand whether this format works for them.
A1-A2 levels are designed specifically for beginners learning German. If a student decides to continue further, unlocking all verbs requires a one-time $2.99 purchase, which is a very reasonable price for educational material of this level.
After the purchase, all learning levels and extended testing options become available.
No aggressive gamification
I am a native iOS developer, but my background is strongly connected to games. Naturally, I know Game Center very well, and almost immediately I suggested adding gamification features:
- achievements;
- visit streaks;
- different progress rewards.
At one point I even suggested implementing streaks without Game Center.
But none of these ideas passed the teacher’s approval. All of this distracts from a difficult topic and serious educational material. That is why the app only includes progress tracking — simply as statistics for the student. Nothing more.
Code and architectural decisions
For me, a pet project is also a great opportunity to learn something new, build a clean architecture, and experiment with code. At the same time, I have a regular 9–5 job, so I can dedicate maybe a couple of hours per day to the project, and not even every day. Sometimes the main job simply wins.
Taking all of this into account, the project took 2 years to develop. For an app like this, that is still quite a long time. But as a developer, I am happy with:
- the architecture;
- the code;
- and the knowledge I gained during development.
What’s next
During development, we barely looked at competitors. This is a specific educational system created by a specific teacher — Ecaterina Niculchea. So for us, it was not that important what other apps were doing. After releasing the app, we finally decided to take a closer look at competitors — and honestly, we were very happy with our own solution.
In any case, what I released was an MVP. Even before release, I already had a long list of ideas: interface improvements, new settings, testing improvements, and overall UX polishing. All of these are new and interesting product decisions for the future development of the app.
I also noticed some interesting ideas in competitor apps — and that is completely normal. So the next step is gradual improvement and polishing the product as much as possible. After that, I will probably try submitting it for an App Store feature. I hope the product will be strong enough for that by then.
One of the strategic product design decisions was the desire to gradually polish the app and bring the project to the best possible state. This is exactly what I am working on now, and almost every new update brings new product decisions.
What about you? What difficult product or architectural decisions did you make in your own pet projects?