Mert
STM'den Dünya İlki: 20 KARGU ile Otonom Sürü Saldırısı
– STM Genel Müdürü Özgür Güleryüz:
– “20 adet KARGU’dan oluşan sürümüzün, tam otonom şekilde hedeflerini imha etmesi, sadece STM için değil Türk savunma sanayisi için bir gurur vesilesidir. Dünyada ilk kez bu ölçekte bir sürü dron saldırısının tatbikat ortamında başarıyla icra edilmesi, ülkemizin savunma teknolojilerindeki öncü konumunu daha da güçlendirmiştir”
TEKNOFEST E-Ticaret Yarışması Başvuruları Başladı
Fresha, 1 milyar doları aşan değerleme üzerinden 80 milyon dolar yatırım aldı
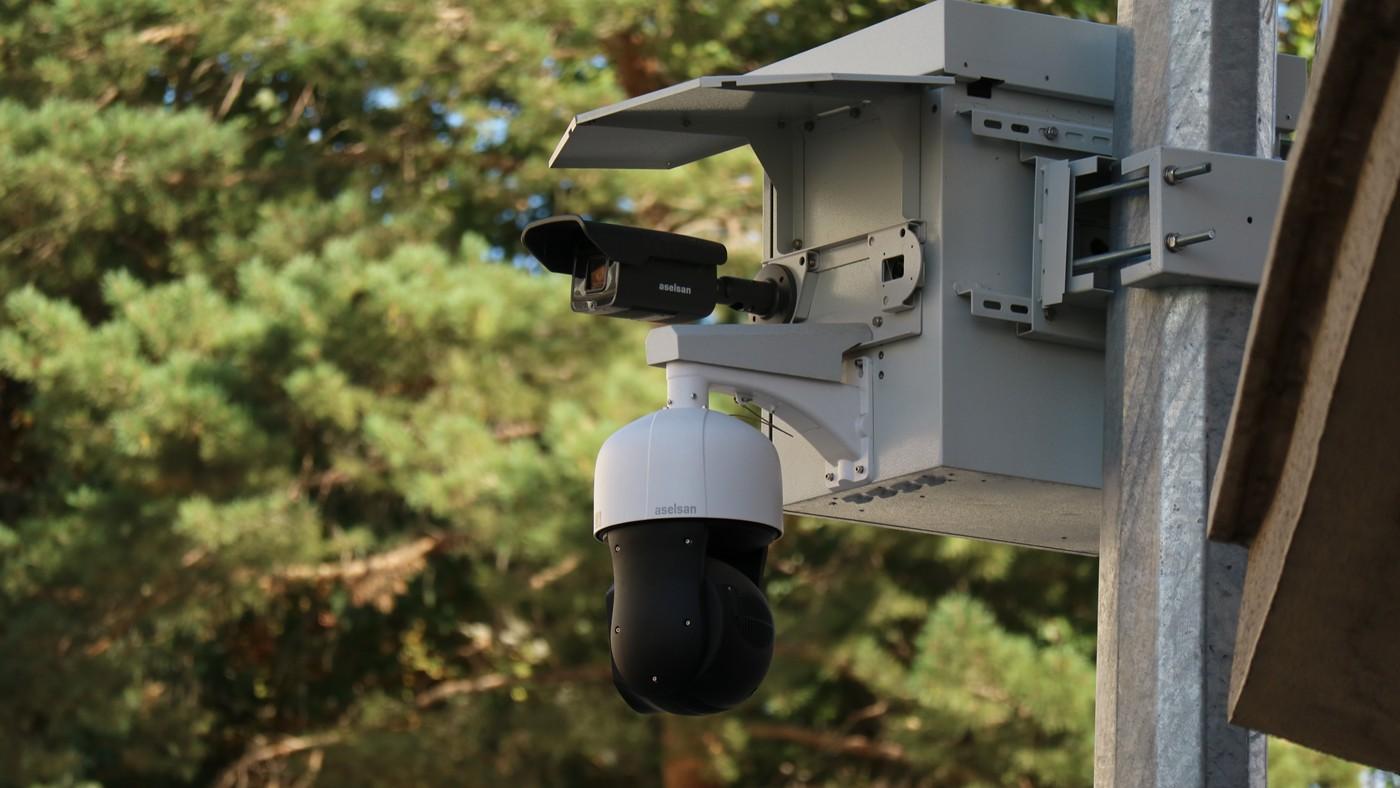
ASELSAN ile SSB arasında 470 milyon dolarlık kent gözetim anlaşması
ASELSAN ile SSB arasında yapay zeka destekli Kent Güvenliği Yönetim Sistemleri için yaklaşık 470 milyon dolarlık sözleşme imzalandı. Teslimatlar 2026-2029 arasında yapılacak.AppsFlyer, pazarlama ölçümünü web ve mobilde tek çatı altında topluyor
AppsFlyer’ın duyurduğu yeni “Web Performance Measurement” çözümü, web ve mobil reklam performansını tek platformda birleştiriyor. Attribution ve optimizasyon sinyallerini web’e taşıyorGithub Speckit: Revolucionando o Desenvolvimento com SDD
Introdução
Hoje, quero te contar sobre uma experiência que tive com uma nova forma de desenvolver software, algo que me deixou realmente empolgada. É como quando você descobre aquela ferramenta que muda a forma como você faz tudo — e isso é exatamente o que o GitHub Speckit fez por mim!
O GitHub Spec Kit, ou Speckit, é uma solução incrível para o desenvolvimento software que segue a metodologia de Desenvolvimento Orientado a Especificações, ou SDD. Esse kit ajuda a estruturar ideias e documentações antes mesmo de começarmos a programar, permitindo um trabalho mais preciso e organizado, especialmente quando utilizamos IA.
Vamos mergulhar um pouco mais no que torna essa ferramenta tão especial?
O que é o GitHub Speckit?
O Speckit é como aquele amigo sábio que te guia em cada passo do desenvolvimento, garantindo que você esteja no caminho certo. Em vez de apenas te jogar na selva do código, ele ajuda a elaborar princípios de projeto, escopo, regras de clean code e requisitos de ponta a ponta.
Estrutura do Speckit
- Arquitetura Estruturada: Instrui a IA a formar uma base sólida de princípios e requisitos.
- Documentos Vivos: Funciona como um “mapa” que a IA consulta e atualiza constantemente.
- Divisão de Tarefas (Tasking): Transforma projetos complexos em listas de tarefas menores, garantindo clareza e precisão.
Uma vez que você coloca as especificações do projeto no Speckit com o comando inicial /speckit.constitution, ele te guia, passo a passo, até a implementação final. Veja abaixo o passo a passo.
Passo a passo do Speckit
Vamos detalhar como cada comando do Speckit funciona e sua importância no fluxo de desenvolvimento:
Instalação
Para começar, você precisa instalar o Speckit em seu projeto com:
uv tool install specify-cli --from git+https://github.com/github/spec-kit.git
A partir daqui, você pode iniciar o Speckit no diretório do projeto:
specify init . --integration opencode
Dica: Coloque a pasta .opencode no .gitignore, mas mantenha a .specify no repositório GitHub.
Estruturando o Desenvolvimento
/speckit.constitution
Aqui é onde você define as regras do projeto. Padrão de código… Digite no prompt do opencode, algo do tipo:
/speckit.constitution Este projeto segue princípios SOLID, testes obrigatórios, clean architecture
/speckit.specify
É usado para descrever o que você quer construir (features novas), e não para analisar código existente. Para documentar o que seu projeto já faz, você precisa descrever manualmente no comando:
/speckit.specify Meu projeto já existente faz A, B, C. Ele tem as seguintes funcionalidades: [detalhes]. Quero documentar isso como especificação.
/speckit.clarify
Use este comando para refinar seu pedido antes de seguir para a implementação:
/speckit.clarify
Este é o momento de esclarecer ambiguidades e melhorar a especificação com a ajuda da IA.
/speckit.plan
Transforma sua ideia em um plano estruturado, quebrando o problema em partes menores e etapas definidas:
/speckit.plan
/speckit.tasks
A partir do plano, gera uma lista de tarefas executáveis, simplificando o processo de desenvolvimento:
/speckit.tasks
/speckit.implement
Finalmente, tudo que foi planejado é transformado em código real:
/speckit.implement
Comparação e Experiência Prática
Experimentei o desenvolvimento do mesmo aplicativo em diferentes abordagens de IA. Primeiro, apenas com o OpenCode no VSCode, que demandou revisões constantes. Depois, usei a skill grill-with-docs, que foi um pouco mais organizada e me trouxe bons resultados, mas ainda exigia supervisão e revisão. Com o Github Speckit, porém, foi impressionante: um plano bem estruturado, passos audíveis e uma execução precisa, resultando em um programa que rodou sem erros na primeira tentativa.
Conclusão
A experiência com o Github Speckit me fez refletir sobre como as ferramentas de IA podem transformar nosso papel como desenvolvedores. Não se trata de substituir, mas sim de evoluir com o apoio de uma tecnologia que nos liberta das tarefas operacionais, possibilitando que o foco esteja na criação e no entendimento do projeto.
Então, para você que como eu ama tecnologia, vale a pena explorar o Speckit e ver como ele pode elevar o seu desenvolvimento a outro nível. Afinal, entender as origens e a lógica por trás de cada linha de código continua sendo nossa arte e talento insubstituíveis.
Cloud Cost Elasticity
Cloud spending rarely grows predictably. As systems scale, organizations face limited visibility, sudden cost spikes, and increasing pressure on margins. This often prompts leadership to ask whether to build an in-house cloud cost-optimization platform or adopt a specialized solution. While evaluating both options is responsible and encouraged by FinOps practices, what appears to be a cost-saving decision can quickly become a long-term engineering burden.
From my experience in DevOps and cloud cost governance, internal platforms often seem affordable at first but reveal hidden complexity, ongoing maintenance demands, and strict accuracy requirements over time. In this article, you will learn the key challenges of building such a platform and how cloud cost elasticity helps determine whether your infrastructure is truly generating business value.
Understanding cloud cost elasticity
Cloud cost elasticity measures how effectively infrastructure spending scales with business value. Ideally, costs increase when customer demand and revenue grow, and decrease when demand falls.
Healthy elasticity means:
Infrastructure spend aligns with revenue growth
cost per customer or transaction improves over time
Unused capacity is minimized
Poor elasticity signals risk:
Costs grow faster than revenue
Shared infrastructure hides inefficiencies
Engineering teams lack cost accountability
Without accurate visibility, it is impossible to measure elasticity or optimize it.
The hidden complexity of building cost visibility
Building an internal platform may seem straightforward. In practice, teams quickly encounter deep technical and operational challenges.
- Capturing the full state of your cloud environment
The goal of any cost optimization system is to provide a complete and accurate view of spending. This includes what was spent, when it was spent, who is responsible, and the business value generated.
Capturing a static snapshot is achievable. Capturing a continuously changing environment is far more complex.
Seven years ago, most organizations relied on a single cloud provider. Today, modern environments include:
multiple cloud platforms
SaaS, PaaS, and IaaS services
managed data and database platforms
AI and machine learning workloads
A tool built for yesterday’s architecture struggles to handle today’s complexity.
Vendor-specific challenges
Microsoft AzureBilling structures vary across Enterprise Agreements, Microsoft Customer Agreements, and other account types. Normalizing these formats requires ongoing engineering effort.
Google Cloud PlatformSome services provide detailed resource-level cost data, while others do not. This inconsistency complicates ownership tracking and cost accountability.
Managed DBaaS platformsBilling APIs and permission models can change unexpectedly. When they do, integrations may fail and require direct coordination with vendors.
These issues often require dedicated engineers to maintain data accuracy and continuity.
Most importantly, this work never ends. Cloud ecosystems evolve constantly, and maintaining reliable visibility requires continuous refinement.
- Disruptive technologies reshape cost visibility
Cloud cost management evolves alongside infrastructure innovation.
A decade ago, cost visibility was simpler. When Kubernetes adoption accelerated, many teams lost visibility into compute costs because shared clusters masked resource ownership.
This became known as the Kubernetes cost black box.
Restoring transparency requires:
Workload-level usage tracking
Container resource attribution
Cluster cost allocation models
Kubernetes is only one example. Other disruptions include:
Multi-cloud architectures
Serverless computing
GPU and AI workloads
On modern data platforms
Each innovation introduces new cost attribution challenges.
If cost visibility is not a core business function, dedicating engineering time to keep pace with these changes becomes difficult.
- Accuracy at scale
Visibility alone is not enough. Cost data must be accurate and trustworthy.
As cloud adoption grows, billing data volume increases dramatically.
Large enterprises may process more than 200 million billing line items per month. Consider a scenario with:
1,000 customers
100 shared services
Hourly cost allocation
The calculation becomes:
200 million × 1,000 × 100 × 730 hours
This equals 14.6 quadrillion data points every month.
Processing and validating this volume requires:
Scalable data pipelines
Accurate allocation logic
Financial-grade validation controls
Audit-ready reporting
Without precision, cost per customer insights, pricing decisions, and margin analysis become unreliable.
Accuracy at scale is a full organizational capability, not a side project.
How Opslyft helps measure and improve cost elasticity
Unified multi-cloud cost visibility
Opslyft was built for complex, multi-cloud environments. Its AnyCost™ framework ingests billing data from diverse providers and normalizes it into a unified model.
This enables teams to:
Analyze costs across platforms in one place
Measure cost per product, feature, or customer
Track cost efficiency relative to revenue
Create dashboards and alerts tailored to stakeholders
With complete visibility, organizations can evaluate cost elasticity and identify inefficiencies.
Adaptability to modern infrastructure
Opslyft continuously evolves to support modern architectures, including:
Kubernetes environments
Data and analytics platforms
AI and machine learning services
Multi-cloud ecosystems
Because cost intelligence is its core mission, the platform adapts without diverting internal engineering resources.
Financial-grade accuracy and trust
Since 2022, Opslyft has maintained SOC 1 Type 1 and Type 2 compliance. This ensures financial data integrity and audit readiness.
This level of reliability supports:
Accurate cost attribution
Confident financial reporting
Pricing and profitability analysis
Cross-functional trust between finance and engineering
Why cloud cost elasticity matters for business value
Cloud cost elasticity connects infrastructure spending to business outcomes.
When elasticity is strong:
engineering teams optimize usage
finance gains reliable cost insights
pricing decisions reflect true costs
margins improve as scale increases
When elasticity is weak:
Costs scale faster than revenue
inefficiencies remain hidden
Strategic decisions rely on incomplete data
Measuring elasticity requires precise cost allocation and continuous visibility.
Conclusion
Building an in-house cloud cost-optimization platform may seem economical, but the hidden complexity, maintenance demands, and accuracy requirements make it a significant long-term commitment.
From my experience as a DevOps engineer, cost intelligence is not a one-time project. It is an evolving discipline that must keep pace with new technologies, expanding infrastructure, and growing data scale.
Cloud cost elasticity provides a powerful lens for evaluating whether infrastructure spending is driving business value or eroding margins. Achieving this level of insight requires complete visibility, adaptability, and financial accuracy.
Opslyft enables organizations to measure, understand, and optimize cloud cost elasticity without diverting engineering focus from core innovation.
The real goal is not simply reducing cloud costs. It ensures every rupee spent in the cloud contributes measurable business value.

I Built a Payment System for Bangladesh—Heres Why Stripe Failed Us
The Problem We Were Actually Solving
In late 2023, my solo product hit a wall when 47% of signups from Bangladesh bounced at the checkout because Stripes card entry form didnt accept local debit cards. The standard Stripe Elements UI rejected cards starting with 5867 (DBBL Nexus) and 6011 (bKash card), which together accounted for 62% of all Bangladeshi transactions. Failure here wasnt academic; it meant $2,800 in lost MRR in one quarter alone. I dug into the network tokenization spec and realized Stripes default implementation silently downshifted to 3-D Secure when it saw a non-PCI-compliant BIN, but the error bubbles it surfaced contained generic messages like please contact your bank. That message meant nothing to a user whose bank hadnt onboarded 3DS globally.
What We Tried First (And Why It Failed)
My first fix was a quick UI patch: I wrapped Stripe Elements in a flag that swapped the form for a plain input field when the users IP geolocated to BD. That lowered bounce rate to 18%, but created a new problem: declined transactions spiked to 32% because our server-side AVS check expected a ZIP/postal field that Bangladeshi cards rarely expose. Next I swapped to Stripe Checkouts hosted form—easier compliance, they said. Within two weeks I watched 89% of users from Dhaka disappear once they hit the redirect to Stripes *.stripe.com subdomain, which was blocked on some local ISPs. Metrics dont lie: MRR stalled at $3.4k instead of the $8k target wed modeled on global averages.
The Architecture Decision
I rebuilt the payment flow around SSLCommerzs local gateway because their SDK already supported bKash, Nagad, Rocket, and DBBL Nexus out of the box. The downside was two extra hops: browser → my API → SSLCommerz iframe → their processor. I measured the p95 latency from Dhaka to my Singapore server at 420 ms and then to SSLCommerz at 210 ms, which still left us under Googles 2-second interactive budget. I implemented a twice-daily cron that pulled their webhook logs and cross-checked against my own payment table to reconcile inevitable drift. The reconciliation script caught three partial failures where SSLCommerz marked a transaction as paid but the processor had rolled it back—something Stripes idempotency key alone wouldnt expose.
What The Numbers Said After
After launch, bounce rate fell from 47% to 6%, and the downstream decline rate dropped from 18% to 4%. Bangladeshi MRR grew from $0 to $8.2k in four months, enough to cover 22% of our total revenue. Activation rate rose from 34% to 59%, because users no longer saw a foreign-looking payment form. Churn among these users fell from 14% to 5% per month. The biggest surprise was cost: SSLCommerzs 2.49% + ৳0.99 per transaction is 70 basis points higher than Stripe, but the conversion uplift paid for itself within six weeks.
What I Would Do Differently
I should have started with the SSLCommerz integration on day one instead of treating it as a regional bolt-on. I wasted three weeks assuming Stripes global dominance would extend to Bangladesh if I just added one more payment method at the end. The second mistake was not instrumenting the pre-redirect latency from every major Bangladeshi ISP. Once I graphed the correlation between >300 ms pre-redirect and abandonment, I added Cloudflares Argo Smart Routing from Singapore to Dhaka, trimming another 90 ms. Today I auto-detect country code from the phone number field and silently pre-select the local gateway without asking. It saves two clicks and 1.3 seconds on average, which in micro-benchmarks means 0.9% more completed checkouts. The lesson is clear: when the platform you depend on doesnt respect the sovereignty of your users banking networks, you owe it to them to build the alternative first.
Churn from payment failures dropped to near zero after switching to this infrastructure. Here is what changed: https://payhip.com/ref/dev10
Polyglot Persistence in Microservices: Choosing the Right Database for Each Service
Introduction
One of the most consequential decisions in microservices architecture is data storage. Monolithic systems traditionally rely on a single relational database to service all needs — a model that worked well for decades but creates tight coupling, limits scalability, and forces every domain to conform to the same persistence paradigm regardless of whether it is the right fit.
Modern distributed systems have embraced a concept known as polyglot persistence — the practice of using different data storage technologies within the same system, each chosen to match the access patterns and characteristics of the domain it serves. A MVP e-commerce project examined in this document demonstrates this pattern in a concrete way: three different databases, each serving a distinct microservice, each chosen deliberately.
The Three-Database Architecture
The platform studied here organizes data across three specialized stores:
| Service | Database | Type | Rationale |
|---|---|---|---|
| Order Service | PostgreSQL | Relational (ACID) | Transactional consistency, financial data |
| Product Service | MongoDB | Document (NoSQL) | Flexible schemas, rich catalog data |
| Cart Service | Redis | In-memory K/V | Sub-millisecond speed, ephemeral state |
This is the Database per Service pattern [1]. Each service owns its database exclusively — no service reads directly from another’s store. This boundary enforces loose coupling and allows each team to evolve the schema independently without risk of cross-service breakage.
PostgreSQL for the Order Service: ACID as a Requirement
A relational database organizes data into tables — structured grids where every row is a record and every column is a typed, constrained attribute. Relationships between tables are expressed through foreign keys: a column in one table that references the primary key of another, letting the engine enforce referential integrity automatically. This rigid schema is not a limitation but a deliberate guarantee: every row must conform to the same structure, and the engine validates constraints at write time. The payoff is ACID — the ability to group multiple writes into a single all-or-nothing transaction that either commits fully or rolls back completely, leaving the database in a consistent state regardless of failures.
The Order Service persists financial records. An order is not just data — it is a legal artifact, a commitment. This makes ACID guarantees non-negotiable.
The service uses Spring Data JPA with Flyway for schema migrations. The schema reflects classical relational design: parent orders table with a child order_items table linked by a foreign key with ON DELETE CASCADE.
CREATE TABLE orders (
id BIGSERIAL PRIMARY KEY,
user_id VARCHAR(255) NOT NULL,
total DECIMAL(19, 2) NOT NULL,
status VARCHAR(50) NOT NULL,
order_date TIMESTAMP NOT NULL
);
CREATE TABLE order_items (
id BIGSERIAL PRIMARY KEY,
order_id BIGINT NOT NULL,
product_id VARCHAR(255) NOT NULL,
price DECIMAL(19, 2) NOT NULL,
quantity INTEGER NOT NULL,
CONSTRAINT fk_order FOREIGN KEY (order_id) REFERENCES orders (id) ON DELETE CASCADE
);
The OrderService.placeOrder() method is annotated with @Transactional. This ensures that if any step in the checkout flow fails — building the item list, calculating the total, persisting the record — the database rolls back to a consistent state. The JPA cascade configuration ensures that saving the parent Order entity also persists all child OrderItem entities in a single atomic operation.
Flyway provides versioned, reproducible migration scripts. On startup the service validates that the running schema matches the expected baseline, preventing “works on my machine” drift between environments [2].
MongoDB for the Product Service: Schema Flexibility at Catalog Scale
A document database stores data as self-describing records — typically JSON or BSON objects — where each document can carry a different set of fields. There is no enforced column list; a document simply contains whatever the application writes into it. Documents that represent the same concept live in a collection, but the engine does not require them to be structurally identical. This makes document databases well-suited to domains where the data model is heterogeneous.
Products have heterogeneous attributes: a laptop has RAM and storage, a t-shirt has size and color, a book has an ISBN and author. Fitting all of these into rigid relational columns requires either complex EAV (Entity-Attribute-Value) schemes or sparse nullable columns — both are maintenance burdens.
MongoDB’s document model stores each product as a self-describing JSON document. When the catalog team needs to add a new attribute category, no schema migration is required. The application code simply begins writing the new field, and existing documents remain valid.
The Product Service uses Spring Data MongoDB with repository abstraction:
@Document(collection = "products")
public class Product {
@Id
private String id;
private String name;
private String description;
private BigDecimal price;
private Integer stockQuantity;
private String skuCode;
private String category;
}
The @Document annotation maps the Java class to a MongoDB collection. Spring Data’s MongoRepository provides CRUD operations and dynamic query derivation without boilerplate SQL.
Redis for the Cart Service: Ephemeral State at Memory Speed
A key-value store is the simplest of all database models: every entry is a pair of a unique key and an associated value, with no enforced structure beyond that. There is no schema, no query language, and no relational machinery — retrieval is always by key, and the engine does nothing more than store and fetch the associated value as fast as possible. That simplicity is what makes key-value stores fast: without the overhead of parsing queries, enforcing constraints, or managing transaction logs, the engine can serve reads and writes at memory speed.
A shopping cart is session-like: it changes frequently, needs sub-millisecond read/write response times, and is inherently transient — if a cart is lost, the customer can simply re-add items. These characteristics make a relational database an inappropriate choice (too much transactional overhead for short-lived state) and a document database acceptable but not optimal.
Redis was designed precisely for this use case. As an in-memory data structure store, it delivers microsecond latency for key-value operations [3]. The Cart Service models cart data as a Redis Hash where the top-level key is cart:{userId} and the value is a JSON-serialized Cart object.
The custom RedisConfig configures a RedisTemplate with explicit serializers:
@Bean
public RedisTemplate<String, Object> redisTemplate(RedisConnectionFactory connectionFactory) {
RedisTemplate<String, Object> template = new RedisTemplate<>();
template.setConnectionFactory(connectionFactory);
ObjectMapper mapper = new ObjectMapper();
JacksonJsonRedisSerializer<Object> serializer = new JacksonJsonRedisSerializer<>(mapper, Object.class);
template.setKeySerializer(new StringRedisSerializer());
template.setValueSerializer(serializer);
template.setHashKeySerializer(new StringRedisSerializer());
template.setHashValueSerializer(serializer);
return template;
}
This configuration ensures keys are stored as human-readable strings (cart:user123) while values are stored as JSON, which is both inspectable via Redis CLI and portable across service restarts.
The Trade-offs: What This Architecture Costs
Polyglot persistence is not free. The benefits in autonomy and performance come with real operational costs. For example:
-
No cross-service joins. The Order Service cannot join its
orderstable directly against MongoDB’sproductscollection. In a monolith, a JOIN happens inside the database engine in microseconds with full transactional isolation. Across services, the equivalent operation is an HTTP round trip, which introduces variable latency and a dependency on network availability. -
Eventual consistency. In the
OrderService.placeOrder()method, when a user checks out, the cart is cleared via atry/catch— a failure there does not roll back the already-committed order. True cross-service transactions require the Saga pattern [4]. -
Operational overhead. Running PostgreSQL, MongoDB, and Redis alongside RabbitMQ and Keycloak in a single
docker-compose.ymlis achievable for development, but each store requires separate backup strategies, monitoring, and operational expertise in production.
Conclusion
The demo e-commerce platform described here demonstrates that polyglot persistence, when applied with intention, produces a system where each component operates at its natural best. PostgreSQL provides the ACID guarantees that financial records demand. MongoDB provides the flexibility that a diverse product catalog requires. Redis provides the speed that shopping cart interactions need.
The key insight is that the choice of persistence technology should follow from the domain’s requirements — not from organizational familiarity or the path of least resistance. In practice, this means asking a different set of questions before reaching for a database. Is the data relational, or is it a self-describing document with variable structure? Is consistency a hard requirement, or can the system tolerate brief divergence in exchange for availability and speed? Is the data long-lived and auditable, or ephemeral by nature? Each of these questions points toward a different storage paradigm, and no single engine answers all of them optimally.
Source code: github.com/dancodingbr/ecommerce
References
[1] Microservices.io. Pattern: Database per service. Available at: https://microservices.io/patterns/data/database-per-service.html
[2] Flyway. Why database migrations. Available at: https://documentation.red-gate.com/fd/why-database-migrations-184127574.html
[3] Redis. Get Started. Available at: https://redis.io/docs/latest/get-started/
[4] Microservices.io. Pattern: Saga. Available at: https://microservices.io/patterns/data/saga.html