Add Your Own Component to Bombie in 5 Edits

This is the third post in the Bombie series. The first post was an intro, the second covered the architecture. This one is a hands-on walkthrough: take a Material-UI component that isn’t already in Bombie, and wire it up so it appears in the palette, drags onto the canvas, opens a property editor, and renders in the live preview.

The whole change is five small edits across the same five files for every new component. Once you’ve done one, the next one takes about ten minutes.

I’ll use Rating as the running example. It’s a single-leaf component (no children), it has a small but meaningful prop surface (value, max, precision, size, readOnly, disabled), and it’s not already in the catalog.

Prerequisites

Clone and run Bombie locally:

git clone https://github.com/amith-moorkoth/bombie.git
cd bombie
cp .env.example .env
npm install
npm start

You’ll get the builder at http://localhost:8080/generate-component. Open src/Lib/ComponentGenerator/ — every file you’re going to touch lives under there.

Edit 1: register the component in the catalog

The catalog is the source of truth for what Bombie knows about. It lives in two files:

  • Data/element-base.js — display name + tag
  • Data/elements.js — drag-and-drop type info

Add Rating to element-base.js:

// src/Lib/ComponentGenerator/Data/element-base.js
export const ELEMENT_BASE = {
  // …existing entries
  Rating: { tag: "Rating", displayName: "Rating" },
};

And to elements.js:

// src/Lib/ComponentGenerator/Data/elements.js
export const ELEMENTS = {
  // …existing entries
  Rating: {
    type: "leaf",         // it's a leaf, no children
    accept: [],           // it doesn't accept any drops
  },
};

type controls where this component can be dropped (most things accept "leaf"). accept is what this component allows as a child — empty for leaves like Rating, populated for containers like Box / Grid / Stack.

Edit 2: write the builder UI file

This is the only new file you’ll create. It defines two things: the schema (what the property editor shows) and the render (what the canvas draws).

Create src/Lib/ComponentGenerator/Container/UI/Rating.js:

// src/Lib/ComponentGenerator/Container/UI/Rating.js
import Rating from "@mui/material/Rating";
import { makeLeafComponent } from "./Common/make-component";

export default makeLeafComponent({
  tag: "Rating",

  schema: {
    Appearance: {
      size: {
        type: "select",
        options: ["small", "medium", "large"],
        default: "medium",
      },
      max: {
        type: "number",
        default: 5,
        min: 1,
        max: 10,
      },
      precision: {
        type: "select",
        options: [0.5, 1],
        default: 1,
      },
    },
    State: {
      value: {
        type: "number",
        default: 3,
        min: 0,
      },
      readOnly: { type: "boolean", default: false },
      disabled: { type: "boolean", default: false },
    },
  },

  render: ({ props }) => <Rating {...props} />,

  // Optional defaults applied when the component is dropped on the canvas
  defaultProps: { value: 3, max: 5, precision: 1, size: "medium" },
});

A few notes on what’s happening here:

  • makeLeafComponent is a factory from UI/Common/make-component.js. It wraps the renderer with the builder chrome (selection outline, wrench button, delete button) and registers the schema so the property editor knows what controls to show.
  • Schema groups become sections in the property dialog. “Appearance” gets one card, “State” gets another. This is what makes the editor scannable instead of a wall of inputs.
  • Field types the editor knows about: string, number, boolean, select, color. Anything else falls through to a text input.
  • render receives the node’s props (already merged with defaults) and returns plain JSX. No builder logic in this function — that’s what the wrapper handles.

For container components (Box, Grid, Stack, Card, etc.) you’d use makeContainerComponent instead. It accepts the same schema / render shape but also wires up a <DropBox> around the children so things can be dropped inside.

Edit 3: register it in the renderer switch

The canvas uses a central registry to know which builder UI file handles which tag. Add Rating to it:

// src/Lib/ComponentGenerator/Container/element-render.js
import Rating from "./UI/Rating";
// …other imports

export const REGISTRY = {
  // …existing entries
  Rating,
};

This is the registry the recursive renderer (element-recursion.js) consults for every node it walks. node.info.tag looks up its renderer here.

Edit 4: add an icon + put it in a palette category

The palette in the left sidebar groups components by category. Two small additions:

// src/Lib/ComponentGenerator/Elements/icon-map.js
import StarIcon from "@mui/icons-material/Star";
// …

export const ICON_MAP = {
  // …existing entries
  Rating: StarIcon,
};
// src/Lib/ComponentGenerator/Elements/index.js
export const CATEGORIES = {
  Layout:      [/* … */],
  "Form Elements":  ["TextField", "Select", /* …, */ "Rating"], // add here
  "Data Display":   [/* … */],
  Feedback:    [/* … */],
  Navigation:  [/* … */],
};

Categories are just arrays of tags. Pick the one that makes sense — Rating is technically a form input but it’s also a display element. I put it under “Form Elements” because it has a value and a readOnly mode, but “Data Display” is a defensible choice too.

Edit 5: teach the preview about it

The live preview has its own renderer (render-preview.js) that emits clean MUI JSX without builder chrome. It uses a switch keyed by tag — add a branch:

// src/Lib/ComponentGenerator/Preview/render-preview.js
import Rating from "@mui/material/Rating";
// …

const RENDERERS = {
  // …existing entries
  Rating: ({ node }) => <Rating {...node.props} />,
};

That’s it. The preview will now render Rating the same way the canvas does, minus the outline and wrench.

Testing your change

Hot-reload should pick everything up. Open the builder, find “Rating” in the Form Elements category, drag it onto the canvas. You should see five stars with the third one filled in (your defaultProps.value: 3).

Click the wrench. You should see the property dialog with two sections — “Appearance” with size / max / precision, and “State” with value / readOnly / disabled. Flip “readOnly” to true, change value to 4.5 (oh wait — precision is 1; set precision to 0.5 first, then 4.5 works).

Click Preview. The iframe shows your component without any builder chrome. Toggle Mobile / Tablet / Desktop — Rating doesn’t have responsive breakpoints itself, but if you’d dropped it inside a Grid it would reflow correctly.

If something doesn’t render: the most common culprit is forgetting Edit 3 (register in element-render.js) or Edit 5 (register in render-preview.js). One controls the canvas, the other controls the preview, and the symptoms are different — canvas-only failures mean a missing entry in element-render.js, preview-only failures mean a missing entry in render-preview.js.

What about container components?

For containers, two things change:

  1. Use makeContainerComponent instead of makeLeafComponent. It wraps a <DropBox> around the rendered children.
  2. In elements.js, set type: "container" and populate accept with the tags this container will receive (usually ["leaf", "container"] to allow nesting).

The render function for a container gets children it should render the canvas-rendered subtree into. Example skeleton:

makeContainerComponent({
  tag: "MyContainer",
  schema: { /* … */ },
  render: ({ props, children }) => (
    <MyContainer {...props}>{children}</MyContainer>
  ),
});

children here is the already-rendered subtree (with builder chrome on the canvas, plain JSX in the preview).

A note on prop validation

Bombie doesn’t enforce prop validation beyond what MUI itself does at runtime. If you put value: 99 on a Rating with max: 5, MUI will clamp it. The schema’s min/max hints are advisory — the editor uses them for its number input UI, but the property dialog won’t refuse to let you save an out-of-range value.

In practice this hasn’t been a problem because the editor’s controls (select dropdowns, numeric inputs with min/max) make it hard to enter nonsense in the first place. But if you’re adding a component with strict prop constraints, document them in the schema using a description field — the property dialog will surface it as helper text.

Recap

For any new component, the five edits are:

  1. Catalog — Data/element-base.js + Data/elements.js
  2. Builder UI — one new file under Container/UI/
  3. Renderer registry — add to REGISTRY in element-render.js
  4. Palette — add icon to icon-map.js and tag to Elements/index.js
  5. Preview renderer — add a branch in render-preview.js

There’s no central manifest file that needs to be regenerated, no build step that needs to run, no test that needs to pass before the new component shows up. Hot-reload picks everything up in seconds.

The whole architecture is built around making this addition cheap, because the practical value of Bombie scales with how many MUI components it knows about. PRs that add components are exactly the kind of contribution I want.

In the next post — last in this series — I’ll cover the operational lessons: GitHub Pages SPA deep links, the CSP-per-mode setup, and why bombie-three.vercel.app ended up on Vercel even though the repo has a GitHub Pages workflow.

Links

Bintrail: MySQL Time-Travel Queries Using Indexed Binlogs

Bintrail is a recently introduced layer that brings point-in-time queries and row-history lookups to MySQL, the only major relational database lacking native temporal querying. Using indexed binlogs behind ProxySQL and without modifying MySQL or application code, Bintrail supports querying data as of a past timestamp and reviewing change history, primarily for recovery and audit scenarios.

By Renato Losio

Spotify, yapay zekadan güç alan yeni sistemler duyurdu

Spotify, yapay zekadan güç alan yeni sistemler duyurdu

Spotify, yapay zekadan güç alan yeni sistemler duyurduÇevrimiçi müzik alanının lideri Spotify bugün ilk olarak “Studio by Spotify Labs” ile dikkat çekti. Önümüzdeki haftalarda ayrı bir masaüstü uygulaması olarak çıkacak sürüm, kullanıcıların yazılı komutlarla kişiselleştirilmiş günlük özetler, podcast’ler ve çalma listeleri oluşturmasına imkan tanıtacak. Yapay zeka içerikleri, Spotify dinleme geçmişinin yanı sıra bağlanan uygulamalardan alınan bilgilerden yararlanılarak oluşturulacak ve kişisel kütüphaneye kaydedilecek. Bugün buna ek olarak yapay zeka destekli “remiks” altyapısı da duyuruldu. Bunun için Universal Music Group (UMG) ile iş birliği gerçekleştiren şirket, kullanıcıların yalnızca yazılı komutlarla yeni parçalar oluşturmasına imkan tanıyacak. Sanatçılar isterlerse şarkılarının yapay zeka ile remiks’lenmesine izin vermeyecek, izin veren sanatçılara ise ekstra ödeme yapılacak. Bugün, podcast içerikleri hakkında entegre yapay zeka sistemine soru sorulmasına imkan tanıyan bir altyapıyı kullanıma sunmaya başlayan şirket, önümüzdeki aylarda müzik, sesli kitap ve podcast’ler için yapay zeka destekli çalma listesi (Prompted Playlist) özelliğinin kullanıma sunulacağını da aktarıyor.

Spotify, yapay zekadan güç alan yeni sistemler duyurdu yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Why Your OSS Advocacy Strategy Probably Doesn’t Fit

A horizontal double-ended arrow in yellow, representing a spectrum. The left end is labeled “Critical, revenue-generating” and the right end is labeled “Independent.”

Open source is built on community.

That’s not a feel-good platitude. It’s baked into the structure of open source as a whole. The code lives in public. The roadmap is shaped by contributors. The project’s health depends on people outside your company showing up, engaging, and investing their time. Which means that, if your company is participating in open source in any capacity, community engagement isn’t just some nice-to-have. It’s a requirement for doing open source at all.

Every company that does open source needs some form of developer advocacy—whether they have a formal DevRel team or not. The question isn’t ’Should we engage with this community?’ It’s ’How should we engage, given our specific situation?’

And if you’re anything like most companies I’ve seen and worked with, you’ve probably looked at what other companies do in open source and tried to replicate their approach. I’m here to tell you that’s probably not working. And I think I know why.

The standard playbook doesn’t apply here

There’s a well-established developer relations playbook that works great for products: drive awareness, drive adoption, measure signups, measure conversion, grow usage. Profit. Rinse and repeat.

But open source isn’t a product. Open source is a living, breathing thing based on a community. And that community isn’t necessarily your funnel.

So if the standard product developer relations playbook doesn’t apply in this case, what does?

Looking back, I’ve actually spent quite a bit of my career wrestling with this question—at Bloomberg as a software engineer where I found myself advocating for Apache Kafka®, at Confluent as a developer advocate for both Kafka and Apache Flink®, and now at Snowflake where I lead Open Source Developer Relations, working across and setting strategies for more open source projects than I ever dreamed possible.

And honestly, the answer isn’t one playbook.

Instead, what you do is defined by your specific circumstances. Your company’s current situation and how they view a project dictates everything about how you should show up. And what works in one configuration often fails in another.

A diagnostic tool: four factors

Before I introduce the engagement models themselves (those come in the following posts of this series), I want to give you a diagnostic tool. In my experience, there are four main factors that determine where your company sits in its relationship to any given open source project.

As you read through these, think about your own organization and the open source projects you interact with.

1. Commercial dependency

How dependent is your business on the project?

A horizontal double-ended arrow in yellow, representing a spectrum. The left end is labeled “Critical, revenue-generating” and the right end is labeled “Independent.”

Is this open source project something your company’s revenue depends on? Are you building a product around it? Or could your business exist perfectly well without it?

It’s a popular model to build a company around an open source technology, offering a managed version of it—the Confluents or the ClickHouses of the world. That’s one end of the spectrum. But for so many other companies, their goal isn’t to monetize the open source technology directly. Instead, they’re building on top of it and using it somewhere internally. As such, they have a vested interest in that project continuing to exist and evolving in a healthy way. That’s the other end of the spectrum.

Where you sit here fundamentally changes what you need from the community and what the community expects from you.

2. Project and community maturity

How mature is the open source project and its community?

A horizontal double-ended arrow in light red, representing a spectrum. The left end is labeled “Nascent” and the right end is labeled “Established.”

Are you engaging with a project that has thousands of contributors, years of history, established governance, and strong Opinions™ about how things should work? Or are you starting something new where none of that exists yet?

This changes how you’ll engage with the technology and even how you’ll talk about it. With a mature project, your job is to figure out how this community operates and find your place in it—in the least disruptive way possible. With a new project, there’s nothing to discover. Instead, you have to design it and usher it along.

3. Level of ownership

What is your level of ownership over the project?

A horizontal arrow in blue spanning from “Low” on the left to “High” on the right, with four tick marks along its length. Each tick is labeled with an escalating ownership level in diagonal text: “End-user,” “Contributor,” “Steward / Maintainer,” and “Owner.”

Are you an end-user who happens to talk about the project externally? A regular contributor? A maintainer or PMC member shaping the project’s direction? Or did your company literally create this thing and donate it?

Each level comes with different credibility, different expectations from the community, and different responsibilities.

4. Strategic intent

What is your intent in engaging with this project?

Why is your company investing in engaging with this community? Is it to recruit engineers? To grow a product? To build reputation? To demonstrate commitment to a project because your customers are demanding it? … or something else entirely?

There’s no wrong answer here. But it’s critical that you answer this question honestly and that you know exactly why your company is choosing to get involved. Keep in mind that the community will figure it out whether you tell them or not.

Four factors, four archetypes

Four color-coded cards displayed side by side, each representing an open source engagement archetype. From left to right: “Adopter” on a light red background with a code-bracket icon on a computer, “Champion” on a green background with a flag icon, “Business” on an yellow background with a dollar-sign icon, and “Founder” on a blue background with a seedling icon.

Most of these factors—commercial dependency, project maturity, ownership level, strategic intent—are more of a spectrum, meaning there are infinite combinations. But, in my experience, there are four common engagement archetypes that companies tend to align with. Each has distinct tactics, metrics, and pitfalls.

The Adopter A company that uses an open source project and advocates for it externally. They’re not trying to run the project. They’re not selling something based on it. They’re users who have chosen to be vocal.

The Champion A company that serves as a major contributor to a project, and whose core business doesn’t necessarily depend on it. They’re investing heavily because their customers or their ecosystem strategy demands it.

The Business A company that has built a commercial offering around an open source project. Their revenue is directly tied to the project’s success, and every move they make is scrutinized.

The Founder A company that has open-sourced a new project and is building its community from zero. No existing users. No existing contributors. No established norms. Just code and a vision.

These aren’t rigid categories, but they’re common patterns. Some companies shift between them over time (more on that in the final post in this series). Some companies can be in multiple archetypes simultaneously for different projects—and that’s key.

The core thesis

What works in one archetype will not transfer cleanly to another. An Adopter measuring themselves like a Business will waste resources. A Founder engaging like a Champion will wonder why nobody shows up.

The playbook is non-transferrable. But the framework for diagnosing where you are and building your own playbook—that’s what this series is about.

What’s coming next

In the rest of this series, I’ll deep-dive into each archetype. You’ll learn the tactics that work, the metrics that matter (grounded in the CHAOSS project’s community health metrics), and the pitfalls to avoid:

  • Part 2: The Adopter Advocating for OSS you use but don’t own
  • Part 3: The Champion Investing in OSS your business doesn’t depend on
  • Part 4: The Business Building a company around open source
  • Part 5: The Founder Building an OSS community from zero
  • Part 6: Model Drift Why it all breaks when you switch contexts

Before you read on, think about one open source project your company engages with. Where does it sit on each of the four factors? Hold onto those as we go deeper into each model in the posts ahead.

Building an MCP server for a Swiss hosting provider (and what reverse-engineering its manager taught me)

I spent the last six weeks building an unofficial MCP server for Infomaniak — the Swiss hosting provider — that lets Claude (and any MCP client) drive web hosting, mail, kDrive, DNS, SSL certificates and AI tools from natural language. It’s MIT, on npm as infomaniak-mcp-agent, runs locally over stdio. This post walks through what I learned, what’s surprisingly hard, and what I’d do differently.

Repo: https://github.com/Mogacode-ma/infomaniak-mcp-agent

Why an MCP for Infomaniak specifically

I run 200+ websites for clients across Belgium, Luxembourg, France and Morocco. Most live on Infomaniak (managed cloud, shared hosting, mail, DNS). Day-to-day operations are: provision a new site, swap a DNS record, add a mailbox, request an SSL cert, audit which domains expire in the next 60 days.

These tasks are all doable from the manager UI, all doable via the public API — but only one or two clicks/calls each, and they don’t compose. Claude is good at composition: “audit all my DNS zones for missing DNSSEC, list every domain whose certificate expires in the next 30 days, and create a redirect from www.legacy-site.be to legacy-site.be on the production hosting.” That’s three API calls minimum, and the cognitive overhead of remembering the right endpoint each time is the friction I wanted to remove.

MCP is the right shape for this:

  • Tools are typed (Zod → JSON Schema → MCP)
  • Side effects are explicit (idempotent? destructive? confirmation required?)
  • The LLM doesn’t need to know HTTP — it sees a catalogue of named operations

The architecture in one paragraph

A single Node 18+ binary, ESM, stdio transport. 54 tools registered with the MCP SDK, each backed by a thin function calling api.infomaniak.com (Bearer token) or manager.infomaniak.com/proxy/... (cookie-authenticated). A token-bucket throttles to 60 req/min (Infomaniak’s hard cap). Confirmation tokens for destructive operations (TTL 60s by default). Per-tool tests, ESLint, Prettier, gitleaks, CodeQL, vitest with 35% coverage and climbing.

Install: npx -y infomaniak-mcp-agent. Config: one env var (INFOMANIAK_API_TOKEN), generated at https://manager.infomaniak.com/v3/api-token.

The first surprise: the public API is missing half of what the manager does

I started with the public Infomaniak API. Documented at https://developer.infomaniak.com, neat OpenAPI-ish spec, Bearer auth. Within a week I’d wrapped most read operations: list sites, list databases, list domains, list mailboxes.

Then I tried to create a site. The public POST endpoint returned 200 OK with a site ID. The site never appeared in the manager. No error. Just… nothing.

I diffed the network tab of the manager’s “Create site” wizard against what I was sending. The manager wasn’t calling the public API at all. It was calling manager.infomaniak.com/proxy/<int>/v3/api/proxypass_2/1/... with a different payload shape, and with two cookies (SASESSION + MANAGER-XSRF-TOKEN) instead of Bearer auth.

The “public API” silently ignores the operation. The “manager-private API” actually creates the site.

The same pattern holds for: database creation, FTP/SSH user creation, mailbox creation, redirection creation, password rotation. The public API is read-mostly. Real automation requires the manager-private surface.

This is documented honestly in the repo’s REVERSE-ENGINEERING.md. The cookie extraction is done with chrome-cookies-secure in memory only — nothing is written to disk.

The second surprise: Infomaniak’s rate limit is shared per token

60 req/min sounds generous until you write a workflow that iterates over 50 domains and makes 3 calls each. You hit the limit in 30 seconds and Infomaniak starts returning 429 with a 60-second cool-off.

I implemented a token-bucket in src/throttle/:

class TokenBucket {
  private tokens: number;
  private readonly capacity: number;
  private readonly refillPerMs: number;
  private lastRefill = Date.now();

  constructor(capacityPerMinute: number) {
    this.capacity = capacityPerMinute;
    this.tokens = capacityPerMinute;
    this.refillPerMs = capacityPerMinute / 60_000;
  }

  async acquire(): Promise<void> {
    while (this.tokens < 1) {
      this.refill();
      if (this.tokens < 1) await sleep(50);
    }
    this.tokens -= 1;
  }

  private refill(): void {
    const now = Date.now();
    this.tokens = Math.min(this.capacity, this.tokens + (now - this.lastRefill) * this.refillPerMs);
    this.lastRefill = now;
  }
}

Wrapped around every HTTP call. Workflows like audit_dns_zones now run reliably across 50+ domains, just slower (1 second per call instead of 100 ms — but they finish).

The third surprise: destructive operations need a confirmation dance

Claude is enthusiastic. Give it a tool called delete_site and a thread of context saying “let’s clean up old test sites”, and it will happily delete production.

The MCP spec has tool annotations (destructiveHint, idempotentHint) but they’re hints — they don’t enforce anything. I added a requireConfirmation wrapper:

// First call: returns a confirmation token, no destructive action yet.
delete_site({ host_id: 12345 })
// → { confirmation_token: "abc...", expires_in_seconds: 60, "what_will_happen": "Site 'legacy-corp.be' (123 files, 2 databases) will be deleted." }

// Second call (within 60s): actually deletes.
delete_site({ host_id: 12345, confirmation: "abc..." })
// → { deleted: true, host_id: 12345 }

The first call describes what’s going to happen and returns. The LLM has to ask the human (or itself) “are you sure?” before the second call. The token expires after 60s. Multiple in-flight tokens per resource are allowed.

This pattern saved me from production accidents twice already during dogfooding.

The fourth surprise: MCP JSON Schema strictness varies across clients

zod-to-json-schema produces JSON Schema Draft 7. Anthropic API and Claude Desktop are happy with that. The MCP Inspector tool? Stricter. Some clients use Draft 2020-12 and reject exclusiveMinimum: true (Draft 4 syntax) — they want exclusiveMinimum: <number> (Draft 6+).

A community contributor (@ruffzy) sent a PR fixing this by targeting jsonSchema7 explicitly in zodToJsonSchema config. I merged it and shipped 0.8.2 within a day. Open source working as intended.

What’s hard about a hosting-provider MCP that isn’t obvious

  1. Idempotency is the LLM’s responsibility, but the tool author has to surface enough information. The list_hostings tool returns is_locked: bool — if I hid that, the LLM would happily try operations on locked hostings and fail. Verbose output is fine; surprise failures aren’t.

  2. Pagination has to be invisible. Some Infomaniak endpoints page at 25 items, others at 50. The MCP tool always pages through everything and returns the merged list. Letting the LLM do pagination = it forgets, gets the first page only, and reasons over incomplete data.

  3. Error shapes must be normalized. Infomaniak’s public API returns {error: {code, description}}. The manager-private API returns either that or {"errors": [{"code", "description"}]} or raw HTML on auth failure. I wrote InfomaniakError to flatten everything into a consistent {kind, code, message, raw} so tools can handle errors uniformly.

  4. Logs go to stderr, not stdout. stdio transport mixes JSON-RPC and arbitrary writes on stdout, so any console.log corrupts the protocol. I use pino with stderr destination. If you build an MCP server, do this from day one.

  5. npx -y requires bin field + shebang in your built JS. tsup config:

banner: { js: "#!/usr/bin/env node" }

And in package.json:

"bin": { "infomaniak-mcp-agent": "dist/server.js" }

Missing either and npx -y either fails silently or runs the wrong entry point.

What I’d do differently next time

  • Cookie-based manager auth is a maintenance debt. The session cookies expire every few hours. Users have to re-open the manager in Chrome to refresh them. A long-lived service account would be cleaner if Infomaniak ever ships one.
  • Reverse-engineering needs a version pinning strategy. The manager-private endpoints change without notice. I’d add a smoke-test workflow that hits a known set of endpoints daily and opens an issue when something 404s.
  • Start with tests, not tools. I built the tools first and added tests later. Inverted, I’d have caught the rate-limit issue 3 weeks earlier.
  • Make the README the install path. Anyone who lands on the npm page should be able to copy 3 lines and have it running in Claude Desktop. That’s the win condition.

Try it

npx -y infomaniak-mcp-agent

You’ll need an Infomaniak API token (https://manager.infomaniak.com/v3/api-token) and to wire it into your MCP client. Full Claude Desktop / Claude Code config snippets in the repo README.

If you’re on Infomaniak and you hit a bug, open an issue with the exact tool call + response (sanitize tokens). I’ll usually patch within a day.

If you’re building an MCP server for your niche provider, the patterns above (token bucket, confirmation dance, error normalization, stderr-only logging) are reusable. The repo is MIT, fork it as a starting point.

⭐ if it saved you time. PRs welcome.

Does MCP Still Matter in the AI Ecosystem?

Banner

Banner

The AI ecosystem moves fast.
A few months ago, almost every discussion around AI agents included one keyword: MCP (Model Context Protocol).

Today, the conversation feels different.

The hype is quieter.
The excitement is less explosive.
Some developers even started asking:

“Is MCP already declining?”

The short answer is:

Yes, the hype cycle is cooling down. But MCP is still very important.

And in many cases, it may become more valuable precisely because the noise is fading.

The Rise of MCP

MCP was introduced as a standardized way for AI systems to communicate with tools, APIs, databases, and external services.

Instead of building custom integrations for every AI workflow, developers could rely on a common protocol layer.

That idea was powerful.

Very quickly, major companies and tools began adopting it:

  • Anthropic
  • OpenAI
  • Google
  • Cursor
  • Windsurf
  • JetBrains
  • VS Code ecosystem

Many developers compared MCP to:

REST APIs for AI
USB for agent tooling
Kubernetes for interoperability
Those comparisons may sound exaggerated, but they explain why the ecosystem expanded so aggressively.

Why The Trend Feels Slower Now

The downtrend is real — at least socially.

You can observe it across:

X/Twitter discussions
YouTube trends
Hacker communities
startup pitches
The reason is simple:

mcp 1

1. The “MCP wrapper” era is ending

At one point, many startups simply added:

“MCP-compatible”
“AI agents”
“tool orchestration”
…without solving a meaningful problem.

As the market matured, people became more selective.

Infrastructure alone is no longer enough.

2. Security concerns became more visible

As adoption increased, researchers started discovering real vulnerabilities inside MCP ecosystems.

Some problems included:

unsafe tool execution
prompt injection
poisoned MCP servers
weak permission boundaries
This changed the industry mindset.

Companies moved from:

“How fast can we integrate MCP?”

to:

“How safely can we deploy MCP in production?”

That naturally slowed the hype.

3. Too many low-quality MCP servers

A large portion of public MCP projects are abandoned, duplicated, or low-value.

This is a common pattern in every fast-growing ecosystem.

We saw it with:

npm packages
crypto projects
browser extensions
AI wrappers
Rapid growth creates noise before standards mature.

But MCP Is Still Good — And Here’s Why

The important thing is this:

MCP is shifting from “trend” to “infrastructure.”

That is a very different phase.

1. Standardization still matters

AI agents without standardized tooling quickly become messy.

Without MCP:

every integration becomes custom
portability decreases
maintenance costs increase
agent systems become fragile
MCP solves a real engineering problem:

structured context and tool communication.

That problem does not disappear.

2. Enterprise adoption is still growing

While social hype cooled, enterprise usage continued increasing.

This is an important distinction:

consumer hype may decline
infrastructure adoption may continue quietly
Many successful technologies follow this pattern.

For example:

Docker
GraphQL
Kubernetes
gRPC

The loud phase ends.
The real deployment phase begins.

agent-skills

3. AI agents genuinely need interoperability

The future of AI is likely multi-agent and tool-driven.

Agents increasingly need to:

access databases
execute workflows
communicate with SaaS platforms
retrieve contextual memory
coordinate across systems
MCP provides a practical structure for that ecosystem.

Even critics of MCP often admit that the underlying problem is real.

The Real Future of MCP
MCP may not remain the only protocol.

That is important to understand.

We will probably see:

new standards
enterprise variants
secure extensions
protocol competition
orchestration layers above MCP
But even if the implementation changes, the core idea remains valuable:

AI systems need a universal way to interact with tools and context.

That concept is unlikely to disappear.

mcp-2

Final Thoughts

MCP is no longer in its explosive “gold rush” phase.

The market is becoming more realistic:

fewer buzzwords
more production concerns
more focus on reliability and security
That is actually healthy.

A technology becomes durable when:

hype decreases
practical usage increases
standards stabilize
infrastructure matures
So, is MCP still good?

Yes.

But today, it is less about excitement — and more about discipline, architecture, and long-term interoperability.

And honestly, that may be a stronger foundation than hype ever was.

Building a Smart LRU Cache in Java: When Machines Mimic Human Memory 🧠💻

Have you ever wondered why some applications load instantly while others make you stare at a loading screen for 10 seconds? In modern software development, data retrieval speed is everything.

When an application relies purely on fetching data from a massive backend database, it inevitably hits a performance bottleneck. To solve this, software engineers use a high-speed memory layer called a Cache. But here is the catch: Cache memory is physically limited. When it gets full, the system faces a critical choice—which data do we delete?

As a computer engineering student at Çukurova University focusing on data infrastructure, I built a Toy Technical Demo in Java to explore the most elegant solution to this problem: The LRU (Least Recently Used) algorithm.

The Human Experience in Code

What fascinates me most about the LRU algorithm is how it perfectly mirrors human biology. Our brains cannot remember every single detail of our lives. To learn new things, our short-term memory naturally forgets the oldest, least accessed information, while keeping recent and frequently used memories at the forefront.

LRU does exactly this for computers.

To visualize this invisible backend process, I designed a Java Swing simulation using a “Wardrobe” analogy. Imagine a wardrobe with a strict capacity of only 4 hangers.

1. The Standard Allocation 🟢

When you buy a new shirt, you hang it up. It becomes your ‘Most Recent’ item.
 —

2. The Re-prioritization 🔵

If you wear a pair of pants you already own, they don’t just stay in the back. They are moved to the absolute front of the wardrobe because they are popular again. This protects them from being deleted.

3. The Eviction (The Magic of LRU) 🔴

What happens when the wardrobe is full (4/4) and you buy a new hat? The system doesn’t crash. It identifies the ‘Least Recently Used’ item—the old sweater you haven’t worn in months—throws it away, and safely makes room for the hat.

Under the Hood: No Shortcuts

To make this simulation run in O(1) time complexity, I didn’t rely on heavy external libraries. I built the architecture using fundamental Java structures.

I combined a HashMap (for instant memory address lookup) with a custom Doubly Linked List (to seamlessly update the chronological order of the data nodes). Here is a sneak peek at how the data nodes are structured to keep track of the timeline:

// The Doubly Linked List Node Structure
static class Node {
    String key;
    String value;
    Node prev, next;

    public Node(String key, String value) {
        this.key = key;
        this.value = value;
    }
}

Whenever an item is used, it is instantly detached from its current prev and next nodes and moved right next to the head. The item left at the tail is our victim for eviction.

Why It Matters
Without smart eviction policies like LRU, global platforms would require infinite server RAM to function, which is physically and economically impossible.

As software engineers, our job isn’t just about writing code that works; it’s about building robust infrastructures that manage limited resources intelligently. I am not just predicting future system bottlenecks; I am actively learning how to prevent them.

A Beginner’s Guide to Redux in React

Introduction

State management is a fundamental concept in React applications. As applications grow, managing and sharing state between components becomes increasingly complex.

While React provides built-in hooks like useState and useContext, they are often not sufficient for large-scale applications with deeply nested components and complex data flow.

Redux addresses this problem by providing a centralized and predictable way to manage application state.

What is Redux?

Redux is a state management library that maintains the entire application state in a single object called the store.

It follows a strict pattern that ensures:

  • State is predictable
  • Changes are traceable
  • Data flow is controlled

Redux is based on the idea of a single source of truth, meaning all application data is stored in one place.

Why Redux is Needed

In React, data is usually passed from parent to child using props. In large applications, this leads to:

  • Prop drilling (passing data through multiple layers)
  • Difficult debugging
  • Scattered state logic

Redux solves these problems by:

  • Allowing global access to state
  • Making state changes predictable
  • Separating logic from UI components

Core Principles of Redux

Redux follows three fundamental principles:

1. Single Source of Truth

The entire state of the application is stored in one central object (store). This makes debugging and tracking changes easier.

2. State is Read-Only

You cannot directly modify the state. Instead, you must dispatch an action that describes what should change.

3. Changes are Made with Pure Functions

Reducers are pure functions. Given the same input, they always return the same output without side effects.

Core Components of Redux

1. Store

The store holds the complete state of the application.

const store = createStore(reducer);

It provides methods to:

  • Access state (getState)
  • Dispatch actions (dispatch)
  • Subscribe to changes (subscribe)

2. Actions

Actions are plain JavaScript objects that describe what happened.

{ type: "INCREMENT" }

They must have a type property and can optionally include additional data.

3. Reducers

Reducers specify how the state changes in response to an action.

const reducer = (state = 0, action) => {
  switch (action.type) {
    case "INCREMENT":
      return state + 1;
    default:
      return state;
  }
};

Reducers must:

  • Be pure functions
  • Not mutate the existing state
  • Return a new state object

Redux Data Flow

Redux follows a unidirectional data flow:

  1. A component triggers an action
  2. The action is dispatched to the store
  3. The reducer processes the action
  4. The store updates the state
  5. The UI re-renders with new data

This flow ensures consistency and makes the application easier to reason about.

Integration with React

Redux is commonly used with React through the react-redux library.

Key hooks:

  • useSelector — used to read data from the store
  • useDispatch — used to send actions to the store

Example:

import { useSelector, useDispatch } from "react-redux";

function Counter() {
  const count = useSelector((state) => state.count);
  const dispatch = useDispatch();

  return (
    <>
      <h1>{count}</h1>
      <button onClick={() => dispatch({ type: "INCREMENT" })}>
        Increment
      </button>
    </>
  );
}

Limitations of Redux

  • Requires more boilerplate code
  • Adds complexity for small applications
  • Initial learning curve can be high

Redux vs React State

Aspect React State Redux
Scope Local Global
Complexity Low Moderate
Use Case Small components Large applications
Data Sharing Props Direct access via store

When to Use Redux

Use Redux when:

  • Multiple components rely on the same state
  • State logic becomes complex
  • Application size increases

Avoid Redux when:

  • The application is small
  • State is simple and localized

Modern Approach: Redux Toolkit

Redux Toolkit is the recommended way to use Redux today. It simplifies:

  • Store configuration
  • Reducer creation
  • Immutable updates

It reduces boilerplate and improves developer experience while keeping the core Redux concepts intact.

reference

  • React Redux (Official Bindings)
  • Redux Official Website
  • Redux Toolkit

Honor, 600 serisine odaklanan ilginç bir aksesuar hazırladı

Honor

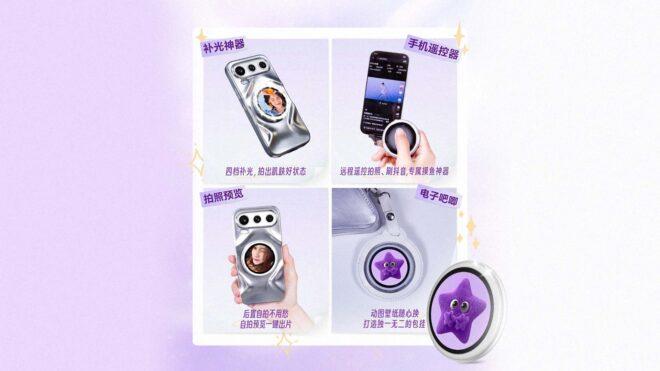
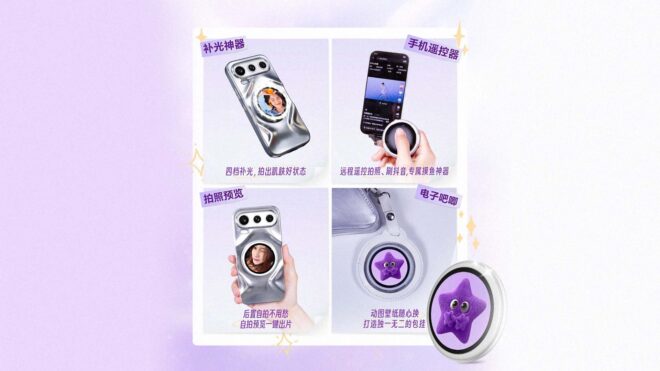
HonorHonor, resmi olarak Türkiye’de satılan 600 serisine odaklanan ilginç bir aksesuar hazırladı. 25 Mayıs’ta detaylandırılacak ürün, temel olarak yuvarlak formda bir dokunmatik ekran ve telefonların arkasına özel bir kılıf aracılığıyla tutturulabiliyor. Aynı zamanda tek başına kullanıma özel bir kılıfı da bulunan ürün, arka kamera ile selfie çekilmesini kolaylaştırıyor (canlı vizör), bir dolgu ışığı olarak kullanılabiliyor veya uzaktan kumanda olarak görev yapabiliyor. Honor 600 serisi ortak olarak 6,57 inç boyutunda 120 Hz AMOLED ekranla geliyor. 600 modeline Snapdragon 7 Gen 4, 600 Pro modeline ise Snapdragon 8 Elite işlemciyle güç veren şirket, her iki telefonda da silikon temelli 7.000 mAh batarya (Avrupa’da 6.400 mAh) kullanıyor. 600 Pro’ya 50W kablosuz şarj desteği ekleyen şirket, ortak kablolu şarj hızını ise 80W olarak açıklıyor. Kamera tarafına geçildiğinde 600 ve 600 Pro’nun arkasında 200 megapiksellik 1/1.4 inç geniş açı ve 12 megapiksellik ultra geniş açı kameralar bir araya getiriliyor. 600 Pro’da bunlara ek olarak CIPA […]
Honor, 600 serisine odaklanan ilginç bir aksesuar hazırladı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Xiaomi Clip-On, Smart Band 10 Pro ve 17 Max resmi olarak tanıtıldı

Xiaomi Clip-On, Smart Band 10 Pro ve 17 Max resmi olarak tanıtıldı

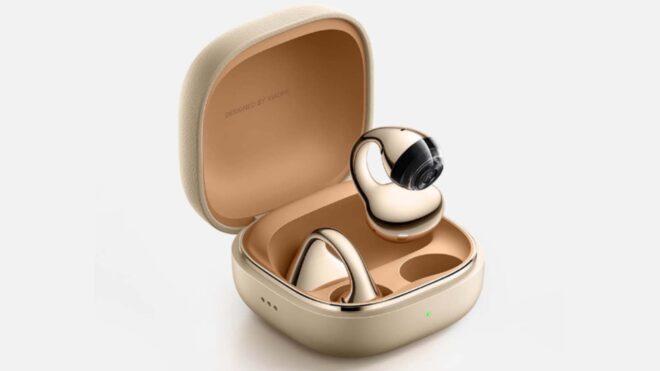
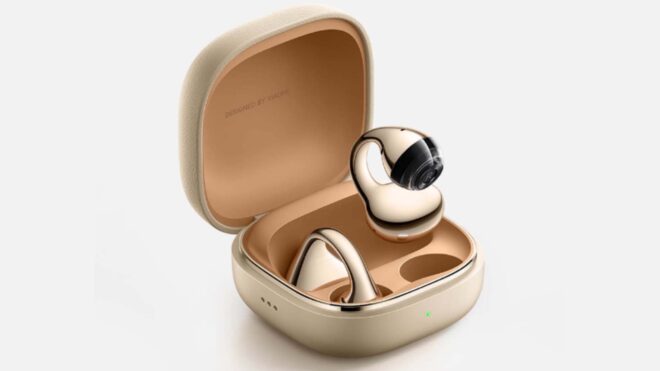
Xiaomi Clip-On, Smart Band 10 Pro ve 17 Max resmi olarak tanıtıldıXiaomi Clip-On kablosuz kulaklık modeli, Smart Band 10 Pro akıllı bileklik ve bataryasıyla dikkat çeken 17 Max bugün resmi olarak tanıtıldı. Yeni ürünlerden “Clip-On”, “açık yapılı” ses deneyimi sunuyor, yani ürün müzik dinlerken çevrenin duyulmasına da imkan tanıyor ve doğrudan kulağın yanına takılarak kullanılıyor. 11 mm dinamik sürücülere ve IP67 sertifikasına sahip olan kulaklık, LHDC 5.0 desteğiyle geliyor. Yapay zeka destekli çeviri özelliğinin de bulunduğu 124 dolarlık model, şarj kutusuyla birlikte 38 saatlik batarya ömrü vadediyor. İlk olarak Çin’de satılacak 630 dolarlık Xiaomi 17 Max ise 100W kablolu / 50W kablosuz şarj destekli 8.000 mAh silikon bataryasıyla dikkat çekiyor. 6,9 inç boyutunda 1-120 Hz OLED ekran taşıyan cihaz, gücünü Snapdragon 8 Elite Gen 5 işlemciden alıyor ve arkasında 200 megapiksellik geniş açı (HP9), 50 megapiksellik ultra geniş açı ile 50 megapiksellik 3x periskop telefoto kameraları bir araya getiriyor. Bugün tanıtılan bir diğer ürün olan Smart Band 10 Pro ise 2024’te […]

Xiaomi Clip-On, Smart Band 10 Pro ve 17 Max resmi olarak tanıtıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.