Real-World Next.js Performance: Moving Beyond standard useEffect and Fetching Hooks

Let’s be honest for a second. When we are first learning React or Next.js, we all do the exact same thing to get data onto a screen: we spin up a useEffect, drop a standard fetch() inside it, point it at an API endpoint, and throw the response into a local useState.

It feels like magic. It works on your local machine (localhost:3000), and your app looks perfect.

But then you push that app into the wild. Real users start clicking around on slow mobile networks, networks drop, users spam the refresh button, and suddenly your clean dashboard turns into a chaotic mess of layout shifts, infinite loading spinners, and redundant API calls that put unnecessary strain on your backend.

When I started transitioning from building simple hobby sites to shipping heavy, production-ready applications, I realized that how you manage data on the frontend is what separates a junior project from an enterprise-grade platform.

If you want to build web apps that feel instantaneous—even on a weak 3G connection—you have to move past basic fetching. Here is how I approached rewriting my frontend architecture to handle data like a pro.

The Silent Killer: Client-Side Fetching Waterfalls

One of the biggest performance bottlenecks on modern web apps is what developers call a fetching waterfall.

Imagine a dashboard with a sidebar, a user profile header, and a main content table. If every single one of those components relies on its own useEffect to fetch data, Component B might wait for Component A to finish loading before it even starts its own API call.

The result? A stuttering, frustrating user experience where elements pop in one by one.

To fix this in modern Next.js, I had to completely re-think my rendering strategies. Instead of forcing the user’s browser to do all the heavy lifting after the page loads, I shifted the heavy data fetching to the server side using Server Components or leveraging Parallel Data Fetching.

By triggering multiple asynchronous requests simultaneously with Promise.all(), you cut down the total loading time to match only the slowest request, rather than stacking them up.

Smart Caching: Stop Pinging the Server for Everything

Another massive wake-up call came when looking at network logs. Why should a user re-download their entire profile information or a static list of options every single time they click back and forth between tabs?

This is where integrating tools like TanStack Query (React Query) or utilizing Next.js’s built-in fetch caching mechanism becomes non-negotiable.

By introducing proper cache validation strategies (like Stale-While-Revalidate), the frontend can instantly display data from the local cache the moment a user clicks a route, while silently fetching the latest updates in the background. If the data hasn’t changed, the UI doesn’t twitch. It feels instantaneous.

+————————————————————-+
| User clicks a tab -> Shows cached data INSTANTLY |
| |
| Simultaneously -> Background sync checks for new updates |
+————————————————————-+

This drastically improves the User Experience (UX) and saves a massive amount of bandwidth on your server infrastructure.

Defeating the “Janky” UI with Optimistic Updates

If you are building an interactive app—like a system where a user can toggle a status, save a bookmark, or check an item off a list—waiting for a server response before showing the visual change feels laggy.

If a user clicks “Like,” and there’s a 500ms delay before the icon turns red, the app feels broken.

To solve this, I started implementing Optimistic Updates.

The concept is simple: when a user triggers an action, you assume the server call will succeed and update the frontend state immediately. If the server comes back with a success, great—everything matches. If the server fails (e.g., a network timeout), you gracefully roll back the UI state to what it was before and show a helpful error toast.

To the end user, your application feels like it’s running locally at 120 frames per second, masking whatever latency is happening behind the scenes on the cloud.

The Takeaway: UX is an Engineering Challenge

As frontend and full-stack engineers, our job isn’t just to look at UI design files and translate them into HTML and CSS. Our true value lies in managing the state of the application across an unpredictable internet.

When you optimize your data-fetching patterns, implement strict caching, and eliminate layout shifts, you aren’t just making the code cleaner. You are directly impacting user retention, keeping conversion rates high, and keeping your server costs under control.

Don’t just settle for code that “works.” Build interfaces that feel alive, predictable, and incredibly fast.

What’s your go-to strategy for keeping your frontend snappy? Are you Team Server Components all the way, or do you heavily rely on client-side state managers? Let’s talk architecture in the comments below! ⚡

Want to see how this fast frontend hooks into a hyper-optimized backend? Keep an eye out for my next post where I talk about ditching Node.js entirely for Bun and ElysiaJS!

How to Build a Human-in-the-Loop AI Agent with LangChain & LangGraph

AI agents are powerful — but sometimes too powerful. What if your agent is about to send an email on your behalf and you want a chance to say “wait, hold on”? That’s exactly what Human-in-the-Loop (HITL) is for.

In this article, we’ll build an AI agent that can send emails, but pauses and asks for your approval before actually doing it. If you approve, it goes through. If you reject, it doesn’t. Simple, safe, and production-ready.

What We’re Building

A LangChain agent powered by an LLM that:

  1. Receives a user request like “Send an email to [email protected]“
  2. Decides to call the send_email tool
  3. Pauses and waits for human approval
  4. Sends the email (or drops it) based on your decision

Prerequisites

pip install langchain langgraph

You’ll also need an LLM. In this article we’ll use OpenAI’s GPT-4o-mini via langchain-openai, but you can swap in any LangChain-compatible model.

pip install langchain-openai

Set your API key:

export OPENAI_API_KEY="your-key-here"

Step 1: Set Up the Model

from langchain_openai import ChatOpenAI

# You can swap this for any LangChain-compatible chat model
model = ChatOpenAI(model="gpt-4o-mini", temperature=0)

Using a different provider? LangChain supports Anthropic, Mistral, Groq, and many others. Just replace ChatOpenAI with the appropriate class and install its package (e.g. langchain-anthropic for Claude).

Step 2: Define the Tool

This is the action the agent will want to take. We keep it simple — just a function that prints the email details.

def send_email(email: str, message: str) -> str:
    """Send email"""

    print(f"nEMAIL SENT TO: {email}")
    print(f"MESSAGE: {message}")

    return "Email sent successfully"

In a real app, you’d integrate this with SendGrid, SES, or your SMTP server.

Step 3: Create the Agent with Human-in-the-Loop Middleware

Here’s where the magic happens. We use:

  • create_agent — builds the agent with tools attached
  • HumanInTheLoopMiddleware — tells the agent to pause before calling specific tools
  • InMemorySaver — a checkpointer that saves agent state so it can be resumed after the pause
import warnings

warnings.filterwarnings("ignore", category=UserWarning)
warnings.filterwarnings("ignore", category=DeprecationWarning)

from langchain.agents import create_agent
from langchain.agents.middleware import HumanInTheLoopMiddleware
from langgraph.checkpoint.memory import InMemorySaver
from langgraph.types import Command

agent = create_agent(
    model=model,
    tools=[send_email],
    middleware=[HumanInTheLoopMiddleware(interrupt_on={"send_email": True})],
    checkpointer=InMemorySaver(),
)

The key line is interrupt_on={"send_email": True}. This tells the middleware: “Before you actually run send_email, freeze and hand control back to the human.”

The InMemorySaver checkpointer is what makes resuming possible — it snapshots the agent’s state at the interruption point so you can pick up exactly where you left off.

Step 4: First Invocation — Let the Agent Plan

We kick things off with the user’s request. The agent will reason about what to do and reach the point of calling send_email — then stop.

config = {"configurable": {"thread_id": "test-thread"}}

response = agent.invoke(
    {
        "messages": [
            {
                "role": "user",
                "content": "Send an email to [email protected] with message 'hello world'",
            }
        ]
    },
    config=config,
)

print("nAGENT PAUSED FOR APPROVALn")

The thread_id in config is how LangGraph tracks this specific conversation. Use the same thread ID when you resume so it picks up the right checkpoint.

Step 5: Ask the Human

Now we prompt the user in the terminal. This is the “human” part of human-in-the-loop.

decision = input("Approve email? (yes/no): ")

Step 6: Resume Based on the Decision

This is where Command(resume=...) comes in. We send the agent’s paused state a signal telling it whether to proceed or abort.

If Approved

if decision.lower() == "yes":
    response = agent.invoke(
        Command(resume={"decisions": [{"type": "approve"}]}),
        config=config,
    )

    print("nFINAL RESPONSE:")
    print(response["messages"][-1].content)

The agent resumes from the checkpoint, actually calls send_email, and continues to completion.

If Rejected

else:
    response = agent.invoke(
        Command(
            resume={
                "decisions": [{"type": "reject", "message": "Human rejected the email"}]
            }
        ),
        config=config,
    )

    print("nEMAIL REJECTED")

The agent is told the action was rejected. It can use the rejection message to inform its final response (e.g., “The email was not sent as per your instruction.”).

Full Code

Here’s everything together:

import warnings

warnings.filterwarnings("ignore", category=UserWarning)
warnings.filterwarnings("ignore", category=DeprecationWarning)

from langchain.agents import create_agent
from langchain.agents.middleware import HumanInTheLoopMiddleware
from langchain_openai import ChatOpenAI
from langgraph.checkpoint.memory import InMemorySaver
from langgraph.types import Command

# ── Model ──────────────────────────────────────────────────────────────────────
model = ChatOpenAI(model="gpt-4o-mini", temperature=0)


# ── Tool ───────────────────────────────────────────────────────────────────────
def send_email(email: str, message: str) -> str:
    """Send email"""
    print(f"nEMAIL SENT TO: {email}")
    print(f"MESSAGE: {message}")
    return "Email sent successfully"


# ── Agent ──────────────────────────────────────────────────────────────────────
agent = create_agent(
    model=model,
    tools=[send_email],
    middleware=[HumanInTheLoopMiddleware(interrupt_on={"send_email": True})],
    checkpointer=InMemorySaver(),
)

config = {"configurable": {"thread_id": "test-thread"}}

# ── First call: agent plans and pauses ─────────────────────────────────────────
response = agent.invoke(
    {
        "messages": [
            {
                "role": "user",
                "content": "Send an email to [email protected] with message 'hello world'",
            }
        ]
    },
    config=config,
)

print("nAGENT PAUSED FOR APPROVALn")

# ── Human decision ─────────────────────────────────────────────────────────────
decision = input("Approve email? (yes/no): ")

if decision.lower() == "yes":
    response = agent.invoke(
        Command(resume={"decisions": [{"type": "approve"}]}),
        config=config,
    )
    print("nFINAL RESPONSE:")
    print(response["messages"][-1].content)

else:
    response = agent.invoke(
        Command(
            resume={
                "decisions": [{"type": "reject", "message": "Human rejected the email"}]
            }
        ),
        config=config,
    )
    print("nEMAIL REJECTED")

Sample Output

When approved:

AGENT PAUSED FOR APPROVAL

Approve email? (yes/no): yes

EMAIL SENT TO: [email protected]
MESSAGE: hello world

FINAL RESPONSE:
The email has been sent to [email protected] with the message "hello world".

When rejected:

AGENT PAUSED FOR APPROVAL

Approve email? (yes/no): no

EMAIL REJECTED

Why This Pattern Matters

Human-in-the-loop isn’t just a safety net — it’s an architectural pattern for building trust between AI and users. Here’s when you’d want it:

Use Case Why HITL Helps
Sending emails / messages Prevents accidental or hallucinated sends
Database writes Confirms destructive operations
API calls with side effects Gives humans a veto before real-world actions
Financial transactions Compliance and audit requirements
Customer-facing responses Quality control before publishing

Taking It Further

  • Async approval: Instead of a terminal input(), send an approval request to Slack, email, or a web dashboard.
  • Timeout handling: Auto-reject if no human responds within N minutes.
  • Audit logs: Persist every approval/rejection to a database for compliance.
  • Multiple tools: Pass multiple tool names to interrupt_on to gate any subset of your agent’s capabilities.

Wrapping Up

LangGraph’s checkpointing + LangChain’s middleware make it surprisingly clean to add human oversight to any AI agent. The agent does the thinking; you keep the final say.

If you found this useful, drop a ❤️ and let me know what kinds of agents you’re building in the comments!

Apple, iPhone 17 Pro kullanarak canlı maç yayını gerçekleştirecek

iPhone 17 Pro

iPhone 17 ProApple, tamamı iPhone 17 Pro ile çekilecek ilk büyük profesyonel canlı spor müsabakasını ekrana taşımaya hazırlanıyor. 23 Mayıs tarihinde Los Angeles Galaxy ile Houston Dynamo’nun karşı karşıya geleceği “Major League Soccer” maçı, resmi duyuruya göre yalnızca iPhone 17 Pro kullanılarak kaydedilecek. Dignity Health Sports Park stadyumunda oynanacak maçı doğrudan Apple TV üzerinden canlı olarak yayımlayacak teknoloji devi, bu konuda önemli bir gösterim yapmış olacak.

Apple, iPhone 17 Pro kullanarak canlı maç yayını gerçekleştirecek yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Off the Grid: How GEMMA 4 Unlocks Private, Local AI

Image displaying the futuristic possibilities of Apache2.0

INTRODUCTION:

We talk about being independently building and developing with the help of AI. But, is it what we are actually doing…? Almost every AI applications we build are one way or the other depend on credentials and API keys that constrain us from being independent in building applications.

But now the solution to this rebellious question is blooming: “WHAT IF WE COULD TAKE FRONTIER-LEVEL INTELLIGENCE OFF THE GRID AND COMPLETELY RUN IT ON THE MACHINE IN FRONT OF US ?”

The Cloud Chain and the Shift to Local AI:

Though we developers write scripts, wire up workflows efficiently, we do it completely dependent on an internet connection and someone else’s server.
We are ready to let our data transmit from our system to a corporate cloud cluster

But this cloud-first approach has its own problems:

  1. Unpredictable Bills
  2. Latency lag
  3. Data vulnerability

LET’S WELCOME GEMMA 4 !!!

This is the exact reason why shift towards local computing is becoming a massive movement.
On April 2,2026. Google DeepMind launched Gemma 4. Unlike commercial APIs, Gemma 4 is a family of open-weight models, meaning Google is transparent about the AI’s decision making prospects.

For the first time in the series, it’s released under APACHE 2.0 License, a completely open license.
This gives absolute developer right: you can run it, distribute it, modify it or build with it without paying a single penny.

GOAL:“take our code completely off the grid and handle high-level logic right on our own machines.”

Image displaying the futuristic possibilities of Apache2.0

MEETING THE FAMILY:

Models in a local AI development aren’t restricted to an single size. As it could lead to mismanagement of hidden potential or over-exploiting of weaker versions

Thus, Gemma 4 is divided into 4 sizes tailored to specific needs: (parameter count-in billions)
E-> Effective Parameter

  • Gemma 4 E2B and Gemma 4 E4B:
    Ultra-lightweight, highly condensed versions engineered specifically to run smoothly on standard laptops, thin notebooks, or even high-end smartphones without draining through your battery.
  • Gemma 4 26B A4B
    Works on the basis of Mixture of Experts (MoE). Though it has around 26 Billion parameters, it only uses around 4 billion each time choosing a suitable model according to our prompts. More like a heavy model with a high speed processing.
  • Gemma 4 31B
    It’s built for complex logical tasks, heavy mathematics, and long form coding. Requires a dedicated modern GPU with plenty of video RAM to host this on your desktop.

Image showcasing different models with the Gemma AI family with respect to their sizes and capabilities

Gemma 4 also introduces an expansive memory layout:

  • Smaller edge models: 128K CONTEXT WINDOW
  • Larger workstation models: 256K CONTEXT WINDOW

The Senses (Local Vision & Audio):

Historically a local AI model is meant to be ran on a text-only environment. Even when there existed very few options, these weren’t the part of the model itself, instead these options were bolted inside the model from a dedicated model for the purpose.

But, Gemma 4 has this problem sorted since the models are trained on text, image and audio, allowing it to understand how words, pixels and sound waves connect in real world.

Image describing the ability of models to take multimedia inputs

ADVANTAGES OF LOCAL SIGHT:

-> UI and Code:
UI and Code generation based on expected visuals given as wireframe or hand-drawn layout, giving us the functional HTML, CSS or Tailwind code corresponding to out expectations.

-> Document and Chart Parsing:
Extracts the required analysis from dense financial charts and scientific graphs without leaking the information to external servers.

-> Handwriting Recognition:
Features OCR (Optical character recognition), meaning it can accurately read and transcribe handwritten notes into markdown text.

ADVANTAGES OF LOCAL HEARING:
Google added highly specialized features to the smaller models like NATIVE AUDIO INPUT.

These lightweight variants can accept direct audio clips that are up to 30 seconds longer, thus could handle cross-language speech translations seamlessly enabling us to create voice-activated interfaces and translational tools.

Spinning It Up and the Sovereign Future:

In the past, setting up a local LLM required struggling with complex Python dependencies, setting up virtual environments, and manually configuring CUDA drivers for our graphics cards.
Today, its incredibly clean. The absolute easiest way to run Gemma 4 locally is through an open-source tool called Ollama, that could manage model weights and handles hardware acceleration behind the scenes.

A SMALL SET OF INSTRUCTIONS TO SET UP OLLAMA AND RUN THE MODELS:

  1. Install Ollama: Download and install the software for your specific operating system (Mac, Windows, or Linux) directly from the official site.

  2. Pick the Model: Open your computer’s terminal or command prompt and run a single command to download the model file. For the highly balanced 4-billion parameter version, you simply type:

Bash
ollama run gemma4:4b

Image displaying the role of OLLAMA in enabling us to use Gemma 4 independently in our system

-> Start Prompting: Once the download completes, the terminal will transform into a direct chat interface. You can unplug your internet cable entirely and start asking questions, debugging code, or parsing text locally at high speeds.

CONCLUSION:

What’s exciting isn’t just Google’s massive engineering milestones or native audio and visual integration. The real victory is the scope it provides to the future of software building.

Stepping away from costly and restricted AI models that run while compromising your prompts and data is itself a huge success towards the Foundation of Building AI applications.

Be it a student exploring software engineering on a regular laptop or a developer building highly secure enterprise tools, the capability to run a frontier-level intelligence entirely off the grid puts the control exactly where it belongs: “Right inside our code, running on our own system…“

References & Technical Credits

Model Creator: Google DeepMind (Released April 2, 2026)

Licensing: Open-weights distributed under the permissive Apache License 2.0

Local Architecture Tools: Powered by the open-source Ollama runtime ecosystem

Behind the Article (Process & Disclosures)

Research & Fact-Checking: Technical data and architectural configurations were cross-verified using official documentation from the Google AI for Developers platform and open community deep-dives on Hugging Face.

Visuals & Art Direction: Imagery throughout this post was custom-designed and generated using Google’s Imagen 3 architecture.

Code Meets Commerce: What Building Websites for Real Businesses Taught Me About Software Engineering

When you’re learning to code, your focus is entirely on the technical stuff. You worry about clean code, component reusability, state management, and picking the coolest looking UI libraries. You live in a perfect bubble where the user always inputs the right data and the requirements never change.

Then, you get your first real-world freelance client.

And suddenly, that perfect bubble bursts.

A while ago, I took on a project to build a travel agency and rental website for Srikandi Trans Purwokerto and Sandita Rent Car. Up until that point, I had been working on structured school applications like an LMS. But stepping into the SME (Small and Medium-sized Enterprises) sector taught me that in the real world, coding is only half the battle.

Here is what building production websites for real businesses taught me about what it actually means to be a software engineer.

1. Clients Don’t Care About Your Tech Stack (And That’s Okay)

When I started the project, I was incredibly excited to use React.js, Next.js, and Tailwind CSS. I wanted to show off fast rendering speeds, server-side capabilities, and optimized build sizes.

But during my first meeting with the owner, I realized something crucial: They didn’t care. They didn’t know what React was, and they didn’t care about Tailwind. What they cared about was simple:

  • “Will this help customers book our travel services easily?”
  • “Will it load fast on a cheap smartphone with a weak internet connection?”
  • “Will it rank on Google so people in Purwokerto can find us?”

This was a massive shift in mindset for me. As developers, we get obsessed with our tools. But for a business, technology is just a tool to solve a commercial problem. Your job isn’t just to write code, it’s to build a solution that drives business results.

2. The Power of UX Optimization over Over-Engineering

When building a commercial site, every second of loading time and every confusing button costs the business money. If a user gets confused trying to find the contact button or the fleet list, they will simply leave and go to a competitor.

Instead of over-engineering complex animations or features the client didn’t ask for, I focused heavily on UI/UX optimization and site speed.

I spent hours ensuring the mobile responsiveness was flawless, because in the transport sector, almost 80% of your traffic comes from people browsing on their phones while on the move. I optimized images, removed heavy scripts, and streamlined the booking flow so a user could go from landing on the homepage to hitting the WhatsApp booking button in less than three clicks.

Seeing the conversion rates and user reach improve after the launch was infinitely more satisfying than just writing a clever piece of JavaScript.

3. Communication is a Hard Skill, Not a Soft Skill

People often call communication a “soft skill,” as if it’s optional. It’s not. When working with freelance clients, clear communication is just as vital as writing bug-free code.

Local business owners know their industry inside out, but they might not know tech jargon. Part of my job as a developer was to play the role of a translator. Instead of saying, “We need to optimize asset delivery and configure DNS zone records for better propagation,” I learned to say, “We are going to make the images load faster and make sure your domain name correctly points to our new server so customers can access it without issues.”

Simplifying complex technical logic into clear, actionable business value saves time, prevents scope creep, and builds massive trust with your clients.

Final Thoughts

Freelancing while navigating my high school years at SMKN 1 Purbalingga and finishing up my internship has been a wild, exhausting ride. But nothing beats the experience of shipping real code that impacts a real business’s bottom line.

If you’re a junior developer looking to level up, stop just building fictional projects for your portfolio. Go out there and find a local business, a café, a laundry service, or a transport agency. Offer to fix their web presence. The technical challenges, the client meetings, and the pressure of pushing a commercial site live will teach you lessons no bootcamp or tutorial video ever could.

Have you ever built a project for a non-technical client? How did you handle the communication gap? Let’s talk in the comments below!

If you want to check out the rest of my development work or collaborate on a project, feel free to visit my Portfolio or see what I’m breaking next on GitHub.

Cheers,
Ibra 🚀

Samsung, yana doğru genişleyen bir telefon için patent aldı

Samsung, yana doğru genişleyen bir telefon için patent aldı

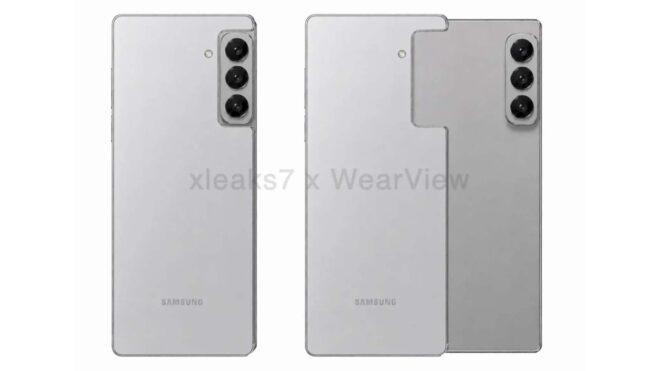
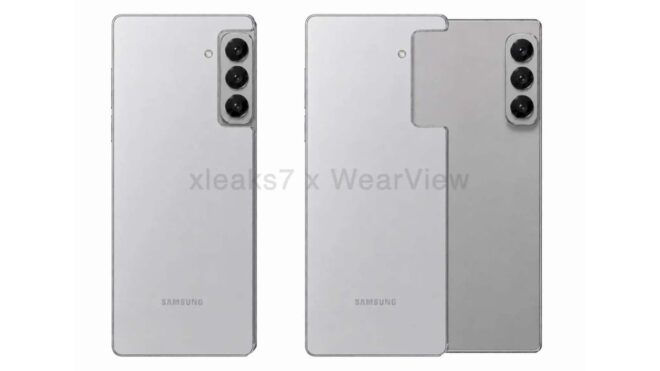
Samsung, yana doğru genişleyen bir telefon için patent aldıSamsung, sektöre öncülük ettiği katlanabilir telefonlar sonrasında pazara genişleyen akıllı telefonlar da çıkarmak istiyor. Bu konuda uzun zamandır çalışmalar yapan şirket, kısa süre önce yana doğru genişleyen bir telefon modeli için patent aldı. Aynı zamanda yukarıya doğru genişleyen cihazlar üzerinde de çalışan teknoloji devi, kullanıcılara rahat taşınabilecek devasa ekranlı telefonlar sunmak istiyor. Bu alanda ilk ticari adımı 2027 ya da 2028’de atması beklenen Samsung, önümüzdeki aylarda geniş yapılı bir katlanabilir telefon modeli de tanıtacak.

Samsung, yana doğru genişleyen bir telefon için patent aldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Building a Global Access Layer that Ignores Geo-Censorship and Favors User Experience

As a frontend engineer, I’ve often found myself wrestling with the complexities of global access. When I worked on a digital products platform targeting creators in emerging markets like Ghana, Nigeria, and Pakistan, I hit a wall. Our users were constantly complaining about the slow load times, frequent disconnections, and impossible-to-debug issues that plagued their experience. What’s worse, they couldn’t even use the platforms we took for granted in the West – PayPal, Google Sheets, or even GitHub.

The Problem We Were Actually Solving

We were building a platform that could sell digital products, but our infrastructure was essentially blocking the very people we wanted to reach. We were optimizing for the 1% of our users who lived in the developed world, while ignoring the 99% who needed access to basic tools. Our infrastructure was built on top of AWS and was heavily reliant on global CDNs, which were great for the majority of our users but disastrous for those living in countries with overzealous geo-censorship.

What We Tried First (And Why It Failed)

We initially tried to work around these issues by whitelisting specific IP ranges and configuring our load balancer to direct traffic to the nearest data center. But it was a short-term fix that only made things worse in the long run. Our developers spent hours tweaking IP ranges, only to realize that the problem would shift to another part of the world. Moreover, it wasn’t a scalable solution, as it required constant monitoring and updates to keep up with the ever-changing landscape of geo-censorship.

The Architecture Decision

So, we decided to take a different approach. We set up a network of edge servers and caching layers that bypassed the main AWS infrastructure altogether. We also implemented a sophisticated network proxy that could automatically redirect traffic from censored regions to less restrictive ones. The edge servers allowed us to cache frequently accessed content, reducing the load on our main infrastructure and making it easier to handle the varying response times and packet loss associated with international traffic.

What The Numbers Said After

The results were nothing short of spectacular. Load times dropped by an average of 30% across the board, with the biggest gains coming from Ghana and Nigeria. Connection failures plummeted by 75%, and our users could finally use the digital tools that we’d taken for granted. We also saw an uptick in engagement metrics like time spent on app and active user count.

What I Would Do Differently

In hindsight, I would prioritize creating a more robust logging and monitoring system to help us troubleshoot issues faster. Geo-censorship can be unpredictable and sometimes seems to change overnight. But more importantly, I would have pushed for a more comprehensive approach to internationalization from day one, considering not just the tech side but also the regulatory and business implications of serving a global market.

Building global access is about more than just technology – it’s about creating a seamless experience for users across the world, regardless of their location or the obstacles they face. Our solution may not be perfect, but it’s taught me that sometimes, the most effective solutions come from rethinking the problem altogether.

MacOS Workers, or how I built my own Mac cloud

mac minis on rack

In Part 1 I laid out the Jenkins-as-a-Code setup — JCasC, Job DSL, ephemeral workers, Packer images, all of it. And I said macOS workers were their own special kind of hell that deserved a separate post. This is that post.

If you’ve never had to run macOS builds in CI, the short version is: everything that’s easy on Linux is hard on macOS, and everything that’s hard on Linux is also hard on macOS but in a different way. Apple’s licensing rules, the fact that you can’t just spin up a Mac in AWS the same way you spin up Ubuntu, the keychain weirdness, the signing tooling, the Xcode versions — all of it adds up. And the answer at most companies is “we have a few Mac minis under someone’s desk that everybody SSHes into”. Which works until it doesn’t.

I wanted the same story I had for Linux and Windows — born for one build, destroyed after, byte-identical state every time — but on macOS. Took me a while to get there. Here’s what actually worked.

mac minis on rack

Why macOS is hard in the first place

Before getting into solutions, it helps to name the problems, because they explain why the architecture ends up looking weird.

1. The cloud Mac story is awkward. EC2 Mac instances do exist. They’re real Mac hardware living in AWS data centers, and you can absolutely rent one. The catch is the shape: they’re dedicated hosts with a 24-hour minimum allocation (Apple’s licensing requirement, not AWS being weird), and the per-hour pricing is brutal compared to Linux. For ephemeral workers that live for 30 minutes per build, paying for 24 hours per allocation makes the per-build economics painful. Cloud Mac exists; it’s just shaped wrong for high-volume ephemeral CI.

2. Apple’s EULA only allows macOS to run on Apple hardware. Which means: no, you cannot legally virtualize macOS on a Linux box. You need real Mac hardware somewhere in the loop. Either you own it, you rent it, or you use a provider that owns it for you.

3. macOS virtualization is its own ecosystem. On Intel Macs the answer used to be VMware (vSphere or Fusion) or VirtualBox. On Apple Silicon, neither of those works the same way — Apple’s Virtualization.framework is what everything is built on top of now, and the tooling around it is much younger.

4. Signing and notarization need credentials that don’t love being ephemeral. Apple Developer ID certificates, app-specific passwords, the keychain — none of these were designed with “fresh VM every build” in mind. They were designed for “a developer’s laptop”. Making them work in CI is a whole sub-problem.

5. macOS images are huge. A baked Packer image with Xcode is 60–80 GB. Spinning that up from cold storage is slow. Caching matters way more than it does for Linux.

Once you understand those five things, the architecture choices below stop looking weird.

What I evaluated and didn’t pick

The macOS CI space is small enough that I can name everything serious in it. Before settling on the approaches below, I did a real evaluation of the commercial options — they exist for a reason, they’re not bad, they just didn’t fit our cost shape.

  • Veertu Anka — the most mature paid platform specifically for macOS CI virtualization. Does roughly what Tart does, with a polished management UI, enterprise support, and a richer feature set. Licensing is per-host or per-VM, and at fleet sizes that matter for a growing engineering org it adds up quickly. If you have the budget and want vendor support, it’s a credible choice.
  • MacStadium — a managed-Mac hosting provider. You rent physical Macs in their data center, optionally bundled with their own orchestration layer (Orka). Solves the “I don’t want to rack Macs myself” problem cleanly. Pricing is per-host per-month — makes sense for a large, steady-state fleet, less so if your volume is spiky or you already have Macs you want to use.
  • AWS EC2 Mac instances — covered above. Useful for very low-volume work where the operational simplicity wins; bad for high-volume ephemeral CI because of the 24-hour minimum.
  • GitHub Actions managed macOS runners — fine for OSS projects and small teams. At any real volume the per-minute pricing gets uncomfortable, and you can’t customize the image — which matters as soon as your build needs anything beyond stock Xcode.

The thing that pushed me toward Tart is the licensing, more than the technology. Tart’s commercial license is structured so that small-scale and personal use is genuinely free, and the paid tier doesn’t scale linearly with fleet size the way per-host licensing does on Anka. For our build volume, that math just works — and at smaller scales (one or two Macs) you pay nothing at all. That’s hard to beat.

And as of April 2026 — when Cirrus Labs joined OpenAI — that licensing got even better: Tart, Vetu and Orchard have been relicensed under a more permissive license and the commercial fees were dropped entirely. If you were on the fence before, the math is even simpler now.

The other thing the Cirrus Labs team gets right is the coherent toolchain around Tart. Tart for VMs, Orchard for fleet orchestration, and the Cirrus CLI for running CI tasks locally — the same .cirrus.yml configs that would run on the the Cirrus CLI runs the same YAML task definitions locally against a Tart VM. The local-reproduction story alone has saved me hours of “wait, why does this fail only in CI” debugging. It’s one of those toolchains where each piece is useful on its own, but the combination is what makes the whole thing pleasant to live with.

Three ways I ended up provisioning macOS workers

There’s no single tool that does everything I needed. So the answer ended up being: three different provisioners for three different shapes of Mac fleet. All three follow the same pattern from Part 1 — a Jenkins job invokes the provisioner, the worker comes up from a Packer-baked image, runs the build, gets destroyed — but the layer underneath is different.

Option A — Tart, for Apple Silicon

Tart is a small open-source CLI built by the Cirrus Labs folks that wraps Apple’s Virtualization.framework. You give it an OCI-compatible image (basically a tarball with the macOS VM disk), it spins up a VM on Apple Silicon hardware in seconds. The image is reusable, you can layer on top of it, and it’s the closest thing to “docker, but for macOS VMs” that exists today.

How it fits:

  • The Mac hardware itself is a fleet of Mac minis (or Mac Studios) — physical machines we own or rent, sitting in a rack.
  • Each Mac has Tart installed at the host level.
  • A dedicated Jenkins job picks an available host, runs tart clone from a known image tag, runs tart run, registers the new VM as a Jenkins agent, and after the build runs tart delete to clean up.
  • Packer has a tart-cli source that builds those images. We bake everything — Xcode, Homebrew, signing tools, languages — into the image at build time.

The good: spin-up is genuinely fast. From tart clone to “agent connected to Jenkins” is under a minute. The image is a snapshot, so every build truly starts from byte-identical state — same as the Linux pod story.

The not-so-good: you still need to own or rent the Mac hardware. You’re not escaping the “real Apple machines in a rack” problem; you’re just orchestrating them better. And the Tart ecosystem is young — expect to write some glue.

Option B — vSphere / VCSA, for the older Intel fleet

Before Apple Silicon, the Mac fleet was a stack of Intel Mac minis hooked into a vSphere cluster. macOS VMs were managed as ESXi guests, exactly like any other VMware VM.

How it fits:

  • Each Mac mini runs ESXi (which is the one OS allowed to be installed on a Mac and host macOS guests, per Apple’s licensing).
  • A “golden” macOS VM template lives in vSphere, baked by Packer’s vSphere ISO builder.
  • A dedicated Jenkins job runs Terraform with the vSphere provider to clone the template (linked clones are faster), bring up the VM, configure it as an agent, and tear it down after.

This setup predates the Apple Silicon transition and it still works — but it’s the heaviest of the three. Linked clones speed up the spawn time, but it’s still slower than Tart, and vSphere itself is a chunky thing to operate.

I’d describe this as the “responsible enterprise” path. If you already have VMware in your org, it slots in cleanly. If you don’t, you’d never start here in 2026.

Option C — Orchard, for pooled / remote Macs

Orchard is also from Cirrus Labs — same family as Tart. The pitch is: instead of you orchestrating individual Mac hosts, Orchard runs as a controller that manages a pool of Mac workers, and you ask it for a VM via an API. It handles scheduling, queuing, and lifecycle.

How it fits:

  • Useful when you have a pool of Macs (could be your own, could be from a managed provider like MacStadium or a similar cloud-Mac vendor), and you don’t want each Jenkins job to know which physical machine to pick.
  • A dedicated Jenkins job calls Orchard’s API to request a VM with a specific image and resource profile, gets a VM back, runs the build, releases it.
  • Useful when capacity is the constraint. You can have 20 builds queued and 5 Macs available, and Orchard does the scheduling for you.

The good: clean separation of concerns. The Jenkins job doesn’t care where the Mac is physically.

The not-so-good: another piece of infrastructure to run. Worth it only at a certain fleet size — for a tiny pool of 2–3 Macs, raw Tart is simpler.

tart vs vSphere vs orchard

What gets baked into the Packer image

Same story as Linux and Windows — we bake everything we can into the image, so the build itself doesn’t pay setup time. The macOS Packer image is the heaviest one in the fleet by a wide margin.

What goes into a typical macOS worker image:

  • OS: a specific macOS version (we pin to specific point releases — Xcode compatibility is brittle, you don’t want to be on “whatever’s latest”).
  • Xcode: a specific Xcode version, plus the command line tools. Xcode alone is 30+ GB.
  • Homebrew + packages: all the brewed tools the build needs, pre-installed and pre-warmed.
  • Language runtimes: Node, Python, Ruby — pinned to specific versions matching what production uses.
  • Build tools: CMake, Ninja, Conan, whatever the project uses.
  • Signing tools: codesign, notarytool, xcrun — these come with Xcode but worth confirming they’re available.
  • Pre-warmed caches: Conan cache, npm cache, brew cache — anything that would otherwise need to be downloaded on first build.

The Packer template itself is short — most of the heavy lifting is in a chain of shell scripts that run after the base macOS install:

source "tart-cli" "macos" {
  vm_base_name = "ghcr.io/cirruslabs/macos-monterey-base:latest"
  vm_name      = "macos-ci-${var.image_version}"
  cpu_count    = 4
  memory_gb    = 8
  disk_size_gb = 120
  ssh_username = "admin"
  ssh_password = "admin"
}

build {
  sources = ["source.tart-cli.macos"]

  provisioner "shell" {
    scripts = [
      "scripts/post-install.sh",
      "scripts/brew-setup.sh",
      "scripts/xcode.sh",
      "scripts/nodejs-setup.sh",
      "scripts/deps.sh",
      "scripts/prewarm-caches.sh",
    ]
  }
}

The whole template is maybe 30 lines. The interesting stuff lives in the shell scripts, which are versioned in the same repo and reviewed in the same PRs as everything else.

A baked image is around 60–80 GB. Storage matters. So does the cache locality — if every Mac in the fleet has to pull a fresh 70 GB image from the registry over the network on first use, you’ve got problems. We pre-cache base images on each host out of band.

The signing-on-ephemeral-VMs problem

This is the one part of the macOS story that genuinely deserves its own section, because it’s where most of the time disappears when you first set this up.

Apple’s signing pipeline assumes a developer machine with a persistent keychain. You unlock your keychain once, you sign apps for the rest of the day, life is good. In CI with ephemeral VMs, none of that holds. Each VM is brand new. There’s no pre-existing keychain. There’s no unlocked state. There’s no “saved password”.

Here’s the contract we ended up with — generic enough that it’ll work for most teams:

  1. Apple Developer ID certificate + private key live in a secrets manager (AWS Secrets Manager, Vault, whatever you use). Never in the image. Never in git.
  2. At job start, the Jenkins pipeline pulls the certificate + key from the secrets manager and imports them into a temporary keychain it creates on the VM.
  3. The temporary keychain gets a random password generated for that build, used for the duration of the build, and discarded with the VM.
  4. Notarization credentials (app-specific password or notarytool API key) come from the same secrets manager and are used directly — they don’t need a keychain.
  5. When the build finishes and the VM dies, the keychain dies with it. Same lifecycle as the rest of the worker.

A simplified version of the keychain-bootstrap script looks like this:

#!/usr/bin/env bash
set -euo pipefail

KEYCHAIN="ci-build.keychain"
KEYCHAIN_PASSWORD="$(openssl rand -base64 24)"

# Create a brand-new keychain just for this build.
security create-keychain -p "$KEYCHAIN_PASSWORD" "$KEYCHAIN"
security set-keychain-settings -lut 21600 "$KEYCHAIN"
security unlock-keychain -p "$KEYCHAIN_PASSWORD" "$KEYCHAIN"

# Add it to the search list so codesign can find it.
security list-keychains -d user -s "$KEYCHAIN" $(security list-keychains -d user | tr -d '"')

# Import the cert + key from the secrets-manager-provided files.
security import "$DEVELOPER_ID_CERT" -k "$KEYCHAIN" -P "$CERT_PASSWORD" -T /usr/bin/codesign

# Grant codesign permission to use the key without prompting.
security set-key-partition-list -S apple-tool:,apple: -s -k "$KEYCHAIN_PASSWORD" "$KEYCHAIN" >/dev/null

Things that will bite you if you don’t know them:

  • set-key-partition-list is mandatory on modern macOS. Without it, codesign prompts for a password from the UI and the build hangs forever.
  • The keychain must be in the search list. A keychain that exists but isn’t searched is invisible to codesign.
  • Notarization is async. notarytool submit --wait does block until done, but be ready for it to take several minutes. Plan for it in build timeouts.
  • Stapling fails silently if you forget it. Notarization succeeds, the artifact ships, end users get a Gatekeeper warning anyway because the ticket isn’t stapled. xcrun stapler staple <artifact> after notarization succeeds.

It’s not deep magic, but every team I’ve seen do macOS CI for the first time burns a week on this. So: budget for that week, and write the keychain bootstrap script before you write the rest of the pipeline.

Trade-offs — which one should you pick?

Honest answer: probably more than one, depending on what fleet you’ve inherited. But if I were starting from a blank slate today, in 2026:

If you have… Pick
A small pool of Apple Silicon Macs you own Tart, directly. Free at this scale, simple, fast, no extra infra.
A larger fleet of Apple Silicon Macs, mixed ownership / remote Tart + Orchard. Same licensing story, but with proper scheduling for a pool.
An existing vSphere installation and Intel Macs vSphere / VCSA path. Keep what works until it stops working.
Need enterprise support + budget isn’t tight Veertu Anka. Paid, polished, vendor backs you up.
Don’t want to rack Macs, want a managed fleet MacStadium (with their orchestration or your own).
No physical Macs, very low volume EC2 Mac. The 24-hour minimum hurts; the operational simplicity sometimes wins anyway.
Open-source project, low volume GitHub-hosted macOS runners. Free for OSS, no infra to manage.
No physical Macs, high volume MacStadium or similar provider. EC2 Mac economics don’t work here.

The thing I’d push back on is “let’s just use Mac minis under someone’s desk”. That’s fine for one team. It’s not fine when it’s the bottleneck for every iOS release.

What I’m still figuring out

A few open problems I haven’t fully solved:

  • Image freshness. Xcode updates land every few weeks. Keeping the Packer image current without breaking everyone’s builds is a constant low-grade tax. We rebuild images on a schedule and pin every job to a specific image version, but the rebuild itself is a 90-minute job and it’s not free.
  • Cost. Mac hardware is expensive whether you own it or rent it. The economics only work above a certain build volume; below that, the per-build cost is uncomfortable.
  • Apple Silicon transition for older code. Some of our older C++ code still has Intel-only dependencies that haven’t been ported. We run those builds on the vSphere/Intel fleet, but that fleet is shrinking, and “rewrite all the legacy build deps for arm64” is its own project.
  • Notarization queue times. Apple’s notarization service has occasional bad days where submissions take 20+ minutes. There’s nothing we can do about it on our side, but it does mean macOS builds have a longer tail than the others.

Closing thought

The macOS CI story doesn’t have a single right answer. There’s no equivalent of “just run a pod in EKS”. You’re going to end up with physical hardware in the loop, a hypervisor (probably more than one), and a signing problem that doesn’t exist on any other platform. The trick is to treat it the same way as everything else: ephemeral, image-baked, orchestrated by a job in git, secrets from a vault. Once the contract is the same as Linux and Windows, the macOS hell becomes a tractable hell.

Next up — Part 3, where I’ll talk about running spot instances as GitHub Actions runners and the cost story behind moving some of this work off Jenkins entirely. Different model, different trade-offs, similar headaches.

Appendix — tools mentioned in this post

Cirrus Labs toolchain (the one I ended up on)

  • Tart — macOS VMs on Apple Silicon via Virtualization.framework. Free for small-scale; licensing.
  • Orchard — controller for pooled Tart hosts.
  • Cirrus CLI — run CI tasks locally against a Tart VM; same .cirrus.yml as Cirrus CI’s SaaS.
  • Packer Tart plugin — Packer builder for Tart images.

Commercial alternatives I evaluated

Other

This is Part 2 of My CI/CD Odyssey. If you want to be pinged when Part 3 drops, follow me here on dev.to. And if you’re doing macOS CI differently — I’d love to hear about it in the comments.

Stop manually stripping Prisma inputs. Generate Zod schemas & guard your DB automatically.

If you use Prisma, you already know it’s a fantastic ORM with excellent developer experience. But there’s a common friction point almost all of us hit when building real-world APIs: input validation and sanitization.

Prisma is strict. If a user passes an unknown field in a .create() or .update() payload (like an injected isAdmin: true), Prisma throws an error. So what do you do? You end up writing tedious mapping functions, picking fields manually, or writing massive Zod schemas by hand to validate and strip out the junk before it reaches Prisma.

What if your Prisma schema could just… do it all for you?

Enter Prisma Guard 🛡️.

What is Prisma Guard?

Prisma Guard is the ultimate Prisma companion designed to bridge the gap between database models and API validation. It does two main things:

  1. Runtime Protection (The Guard): A Prisma Client extension that silently strips unknown fields from your queries at runtime.
  2. Schema Generation (The Magic): Automatically transforms your .prisma models into robust, decorated Zod schemas with complete type-safety.

It’s completely zero-config out of the box (it even manages your .gitignore and Prettier formatting for generated files), but offers immense power for those who need custom validation logic.

✌️ Two Ways to Use It

Depending on your needs, you can use Prisma Guard in two modes.

Mode 1: Runtime Protection Only (The Quick Fix)

If you just want to stop Prisma from throwing errors when random fields are passed from the frontend, just add the extension to your client:

import { PrismaClient } from "@prisma/client";
import { prismaGuard } from "@explita/prisma-guard";

const prisma = new PrismaClient().$extends(prismaGuard());

// Any extra fields passed to 'data' will be silently stripped
await prisma.user.create({
  data: {
    email: "[email protected]",
    poisonField: "will be removed", // Poof! Gone.
  },
});

Mode 2: Full Validation & Schema Generation (Recommended)

This is where the real magic happens. By running npx prisma-guard, it reads your Prisma schema and generates perfect Zod schemas.

Your Prisma Schema:

model User {
  id        String   @id @default(cuid())
  email     String   @unique
  password  String
  createdAt DateTime @default(now())
}

What you get:

export const UserCreateSchema = z.object({
  email: z.string().trim().min(1, { message: "This field is required" }),
  password: z.string().trim().min(1),
  // id and createdAt are managed by Prisma defaults or omitted entirely depending on your config!
});

💎 Advanced Type Ergonomics & Dual Schemas

One of the biggest headaches with schema generation is that a “public” API schema shouldn’t include sensitive internal database fields (like secretApiKey or tenantId).

Prisma Guard handles this beautifully by generating Dual Schemas for every model:

  1. Public Schemas (UserCreateSchema): Respects your omission rules. Perfect for API request validation.
  2. Scalar Schemas (UserCreateScalarSchema): Includes every database field. Perfect for internal services and database operations.

It also exports a suite of ergonomic TypeScript types (UserCreate, UserUpdate, UserCreateRequired) so your service layers are always perfectly typed.

🎨 The Power of Decorators (and the v proxy)

Sometimes z.string() isn’t enough. You need .email(), .min(8), or custom refinement logic. Prisma Guard lets you define this cleanly using triple-slash comments (///).

Instead of polluting your Prisma schema with massive strings of Zod code, Prisma Guard introduces the v proxy in a prisma-guard.config.js file:

// prisma-guard.config.js
import { defineConfig, v } from "@explita/prisma-guard";

export default defineConfig({
  decorators: {
    // Chain validations onto the inferred Prisma type
    email: v.chain.email().trim().toLowerCase(),

    // Completely override a type
    strongPassword: v.string().min(12).regex(/[A-Z]/),
  },
});

Then, you just use them in your Prisma schema!

model User {
  id       String @id

  /// @zod.use(email)
  email    String

  /// @zod.use(strongPassword)
  password String
}

IDE Superpowers 🪄

No one likes typing out decorators from memory. Prisma Guard includes an incredible npx prisma-guard metadata --vscode command that automatically installs VS Code snippets for every Zod method. You literally get autocompletion inside your .prisma files!

⚡ Blazing Fast Performance

You might be thinking: “Doesn’t a runtime guard slow down my queries?”

The answer is no. The runtime guard is designed for ultra-low latency. It uses strict $O(n)$ complexity (looping only over predefined schema fields instead of arbitrary user input), memoized whitelists, and hot-path early exits.

In benchmarks of 100,000 recursive sanitization iterations on a complex payload:

  • Total duration: 221.26ms
  • Average per query: 2.21 microseconds (0.0022ms)

If your database query takes 10-50ms, adding 0.0022ms introduces virtually 0% overhead.

🚀 Get Started in 2 Minutes

Stop wasting time manually maintaining Zod schemas that drift out of sync with your database.

  1. Install the package:
npm install @explita/prisma-guard
  1. Initialize your config:
npx prisma-guard init
  1. Generate the magic:
npx prisma-guard

Check out the full documentation, advanced relation handling, and custom schema generation features on our GitHub Repository.

If Prisma Guard saves you time, I’d deeply appreciate a ⭐ on GitHub! Let me know what you think in the comments below. Happy coding! 🚀

Stop guessing your AI API bill: a quick guide to token cost math

You can ship an LLM feature in an afternoon. Figuring out what it costs to run usually happens later, when the invoice shows up and someone asks why. A few minutes of token math up front avoids most of that.

Here is how the pricing works and how to estimate it.

Tokens, not words

Providers bill per token, not per word or per request. A token is about 4 characters of English, so “Hello world” is roughly 3 tokens and 750 words lands near 1,000 tokens. Input and output are billed separately, and output is almost always the pricier side.

GPT-4o is $2.50 per million input tokens and $10.00 per million output tokens. That 4x gap is the part people underestimate once responses get long.

The formula

Per request, the cost is:

cost = (input_tokens / 1M * input_price) + (output_tokens / 1M * output_price)

Multiply by monthly volume and you have the bill.

Take a support bot: 800 input tokens (system prompt plus the user message) and 400 output tokens per reply, 50,000 requests a month, on GPT-4o.

  • Input: 800 x 50,000 = 40M tokens, so $100
  • Output: 400 x 50,000 = 20M tokens, so $200
  • Total: $300/month

Run the same workload on GPT-4.1 Mini and the number drops by roughly 10x. That one comparison is often what decides the model.

Where it goes wrong

Three things bite people repeatedly:

  1. The system prompt counts every time. A 600-token system prompt isn’t a one-time cost. You pay for it on every single request. Trim it.
  2. Output is the expensive half. Setting max_tokens sensibly is the cheapest optimization there is.
  3. Words lie. Code, JSON, and non-English text tokenize very differently from prose. Count real tokens, don’t eyeball word counts.

Tools that do the math

I got tired of redoing this per model, so I’ve been using Vortenza‘s free AI calculators. The OpenAI API Cost Calculator lets you pick a model and drop in your tokens and monthly volume. There’s a Claude API Cost Calculator for Anthropic models, and an AI Token Counter for when you want the actual token count of an input instead of a guess. No signup, runs in the browser.

The calculator isn’t really the point, though. The point is doing the estimate while you’re still designing the feature. Cost is a design constraint, same as latency. Treat it like one and the invoice stops being a surprise.