
 Mert


The 5 Best OCR APIs for Developers in 2026 (Compared)
Most developers underestimate how painful document processing still is.
Invoices. PDFs. Receipts. Contracts. Financial reports.
A huge amount of business data is still trapped inside documents.
And most teams still solve this problem the same way they did 10 years ago:
- manual copy-paste,
- fragile OCR tools,
- messy spreadsheets,
- broken automations,
- and workflows that collapse the moment a PDF layout changes.
Now combine that with the rise of:
- AI agents,
- RAG systems,
- automation pipelines,
- and LLM workflows.
Suddenly, extracting clean structured data from documents becomes one of the most important layers in the entire AI stack.
That’s why OCR APIs and document parsing platforms are exploding right now.
But not all tools are built the same.
Some are optimized for:
- developer workflows,
- AI-native parsing,
- invoice automation,
- enterprise document ingestion,
- or RAG pipelines.
So after researching the current market, here are 5 OCR/document extraction APIs that stand out the most in 2026.
1. LlamaParse (LlamaIndex)
LlamaParse is probably the most interesting OCR/document parsing platform right now for AI engineers.
Why?
Because it’s not just “OCR”.
It’s built specifically for:
- LLMs,
- AI agents,
- and RAG systems.
The difference matters.
Traditional OCR extracts text. LlamaParse tries to preserve semantic structure and context.
Best For
- RAG systems
- AI agents
- Financial reports
- Complex PDFs
- LLM ingestion pipelines
Key Features
- AI-native parsing
- Markdown and JSON outputs
- Advanced table extraction
- Multi-modal parsing
- Agentic parsing modes
- Complex layout understanding
Pricing
- Free tier available
- Credit-based pricing
- Around 10,000 free credits/pages monthly depending on parsing mode
Pros
- Excellent for complex PDFs
- Built for AI workflows
- Strong parsing quality
- Great ecosystem for developers
Cons
- More expensive at scale
- Overkill for simple OCR use cases
- Requires understanding of RAG/LLM workflows
2. Mindee
Mindee is one of the most developer-friendly OCR APIs available today.
Fast setup. Excellent documentation. Very practical APIs.
This is the kind of tool developers love because you can go from “PDF chaos” to “working automation” in a few hours.
Best For
- Python developers
- OCR automation
- Invoice extraction
- Receipt OCR
- API integrations
Key Features
- Invoice OCR
- Receipt OCR
- Passport/document parsing
- Python SDK
- API-first architecture
- Batch processing
Pricing
- Starter plan: ~€44/month
- 500 pages included
- Usage-based scaling available
Pros
- Extremely developer-friendly
- Great documentation
- Strong API ecosystem
- Fast implementation
Cons
- Less focused on advanced RAG
- Enterprise AI features more limited than some competitors
3. Nanonets
Nanonets sits somewhere between OCR platform, AI workflow engine, and automation suite.
Instead of focusing only on extraction, they focus heavily on business automation.
This makes it attractive for companies that want OCR, approvals, integrations, AI extraction, and workflows together.
Best For
- Business automation
- Finance operations
- Invoice processing
- AI document workflows
Key Features
- AI OCR
- Workflow automation
- Table extraction
- ERP integrations
- Email ingestion
- Approval systems
Pricing
- Free credits available
- Pay-as-you-go model
- Enterprise plans available
Pros
- Strong automation capabilities
- Enterprise-friendly
- Powerful extraction workflows
- Good UI
Cons
- Less developer-focused
- Can become expensive with volume
- More business-oriented than technical
4. Veryfi
Veryfi is heavily specialized in receipts, invoices, bookkeeping, and financial OCR.
And honestly, that focus is a strength.
Instead of trying to solve every OCR problem, they dominate a very specific niche extremely well.
Best For
- Fintech
- Expense management
- Accounting automation
- Receipt scanning
Key Features
- Receipt OCR
- Invoice extraction
- Expense categorization
- Fraud detection
- Mobile OCR
- Financial automation
Pricing
- API-based pricing
- Enterprise-focused plans
- Free trial available
Pros
- Very accurate for receipts/invoices
- Strong financial workflows
- Good mobile support
Cons
- Narrower use cases
- Less useful for general-purpose document parsing
5. Docparser
Docparser is one of those tools you understand in 30 seconds.
Upload a PDF. Extract structured data automatically. Connect it to Zapier, Make, or n8n. And remove hours of manual work.
It doesn’t try to be an “AI operating system.” And honestly, that’s part of the appeal.
It’s extremely focused on solving one problem well: extracting structured data from documents reliably.
Best For
- Business automation
- Invoice extraction
- PDF workflows
- No-code automation
- Operations teams
Key Features
- OCR + PDF parsing
- Table extraction
- Template-based parsing
- Zapier integrations
- Email parsing
- API access
- Export to Excel/CSV/JSON
Pricing
- Starter plan around $39/month
- Professional plans available
- Free trial included
Pros
- Very easy to use
- Great for automations
- Fast setup
- Strong integrations
Cons
- Less AI-native than LlamaParse
- Complex documents may require setup
- More template-driven
Final Comparison
| Tool | Best For | AI-Native | Pricing Model | Developer-Friendly |
|---|---|---|---|---|
| LlamaParse | RAG / LLM pipelines | ✅ Yes | Credits | ✅ High |
| Mindee | Invoice / receipt OCR | Partial | Per page | ✅ Very High |
| Nanonets | Business automation | Partial | Pay-as-you-go | Medium |
| Veryfi | Fintech / expenses | Partial | API-based | Medium |
| Docparser | No-code automation | ❌ No | Monthly plan | ✅ High |
Final Thoughts
The OCR market is no longer just about extracting text.
The real opportunity now is building systems that understand documents.
And the companies that solve this layer well will become critical infrastructure for AI agents, automation, RAG systems, fintech, and enterprise AI workflows.
FAQs
What is the best OCR API for developers?
Mindee is probably the best balance between ease of use, pricing, documentation, and developer experience.
Which OCR tool is best for RAG systems?
LlamaParse and Unstructured are currently among the strongest options for AI-native document pipelines.
Which OCR API is best for invoices and receipts?
Veryfi, Mindee, and Nanonets are excellent for financial documents and expense automation.
Are OCR APIs expensive?
Most platforms now offer free tiers, pay-as-you-go pricing, or credit systems. Costs mainly depend on document volume and complexity.
Can OCR APIs work with Python?
Yes. All the platforms mentioned here provide APIs and Python integrations.
Looking for technical content for your company? I can help — LinkedIn · [email protected]
Write once, post everywhere: automate cross-posting to Twitter, LinkedIn & Facebook with n8n (free JSON)
Every time I finished writing a post, I had the same 10-minute ritual:
- Open Twitter ― paste, trim to 280 chars, add hashtags
- Open LinkedIn ― paste, add professional hashtags, reformat
- Open Facebook ― paste, adjust tone
- Repeat until my soul left my body
For a 3-platform strategy, that’s 30 minutes of copy-pasting per day. 3.5 hours a week. Completely mechanical work.
So I automated it with n8n. Here’s the exact workflow I use — full JSON you can import right now.
What the workflow does
- Web form — you fill in your content and pick platforms (twitter, linkedin, facebook)
- Format per platform — trims Twitter to 280 chars, adds LinkedIn hashtags, keeps Facebook full
- Route & post — splits into parallel branches, hits each platform’s API simultaneously
- Done — all 3 platforms posted in under 2 seconds
No more switching tabs. No more character count anxiety. Just write once.
The full n8n workflow JSON
Copy this, open n8n → Import from JSON:
{
  "name": "Social Media Cross-Poster",
  "nodes": [
    {
      "parameters": {
        "formTitle": "Create Social Post",
        "formFields": { "values": [
          { "fieldLabel": "Content", "fieldType": "textarea", "requiredField": true },
          { "fieldLabel": "Platforms", "fieldType": "text", "placeholder": "twitter,linkedin,facebook" }
        ]}
      },
      "id": "s1", "name": "Post Form", "type": "n8n-nodes-base.formTrigger", "typeVersion": 2.2, "position": [240, 300]
    },
    {
      "parameters": {
        "jsCode": "const content = $input.first().json.Content;nconst platforms = ($input.first().json.Platforms || 'twitter,linkedin').split(',').map(p => p.trim().toLowerCase());nconst posts = [];nif (platforms.includes('twitter')) {n  const t = content.length > 280 ? content.substring(0, 277) + '...' : content;n  posts.push({ platform: 'twitter', text: t, charCount: t.length, maxChars: 280 });n}nif (platforms.includes('linkedin')) {n  posts.push({ platform: 'linkedin', text: content + '\n\n#business #automation #productivity', charCount: content.length, maxChars: 3000 });n}nif (platforms.includes('facebook')) {n  posts.push({ platform: 'facebook', text: content, charCount: content.length, maxChars: 63206 });n}nreturn posts.map(p => ({ json: p }));"
      },
      "id": "s2", "name": "Format Per Platform", "type": "n8n-nodes-base.code", "typeVersion": 2, "position": [480, 300]
    },
    {
      "parameters": {
        "conditions": { "conditions": [
          { "leftValue": "={{ $json.platform }}", "rightValue": "twitter", "operator": { "type": "string", "operation": "equals" } }
        ]}
      },
      "id": "s3", "name": "Route by Platform", "type": "n8n-nodes-base.switch", "typeVersion": 3.2, "position": [700, 300]
    },
    {
      "parameters": { "method": "POST", "url": "https://api.twitter.com/2/tweets", "sendBody": true, "bodyParameters": { "parameters": [{ "name": "text", "value": "={{ $json.text }}" }] } },
      "id": "s4", "name": "Post Twitter", "type": "n8n-nodes-base.httpRequest", "typeVersion": 4.2, "position": [920, 160]
    },
    {
      "parameters": { "method": "POST", "url": "https://api.linkedin.com/v2/ugcPosts", "sendBody": true, "bodyParameters": { "parameters": [{ "name": "text", "value": "={{ $json.text }}" }] } },
      "id": "s5", "name": "Post LinkedIn", "type": "n8n-nodes-base.httpRequest", "typeVersion": 4.2, "position": [920, 340]
    },
    {
      "parameters": { "method": "POST", "url": "https://graph.facebook.com/v18.0/me/feed", "sendBody": true, "bodyParameters": { "parameters": [{ "name": "message", "value": "={{ $json.text }}" }] } },
      "id": "s6", "name": "Post Facebook", "type": "n8n-nodes-base.httpRequest", "typeVersion": 4.2, "position": [920, 520]
    }
  ],
  "connections": {
    "Post Form": { "main": [[{ "node": "Format Per Platform", "type": "main", "index": 0 }]] },
    "Format Per Platform": { "main": [[{ "node": "Route by Platform", "type": "main", "index": 0 }]] },
    "Route by Platform": { "main": [[{ "node": "Post Twitter", "type": "main", "index": 0 }], [{ "node": "Post LinkedIn", "type": "main", "index": 0 }], [{ "node": "Post Facebook", "type": "main", "index": 0 }]] }
  },
  "settings": { "executionOrder": "v1" },
  "tags": [{ "name": "social-media" }]
}
Setup in 5 minutes
Step 1: Get your API credentials
- Twitter/X: Create an app at developer.twitter.com. You need OAuth 1.0a credentials (Consumer Key, Consumer Secret, Access Token, Access Secret). Add them as n8n credentials under “Twitter OAuth1 API”.
- LinkedIn: Go to linkedin.com/developers, create an app, request “Share on LinkedIn” permission. You’ll get a Client ID and Secret for OAuth2. Add as n8n “LinkedIn OAuth2 API” credentials.
-
Facebook: Create a Facebook App, get a Page Access Token with
pages_manage_postspermission. Swap the URL in the Facebook node tohttps://graph.facebook.com/v18.0/{YOUR_PAGE_ID}/feed.
Step 2: Connect credentials to nodes
In n8n, click each HTTP Request node (Post Twitter, Post LinkedIn, Post Facebook) and set the “Authentication” dropdown to your stored credentials.
Step 3: Activate and test
- Click “Activate” to enable the form trigger
- Visit the form URL (n8n shows it after activation)
- Type “This is a test post” — select twitter, linkedin
- Submit and check your profiles
Pro tips I use in production
1. Add scheduling support
Replace the Form Trigger with a Schedule Trigger + a Google Sheets node to read pre-written posts from a spreadsheet. Set the cron to run every day at 9am. One spreadsheet column per platform.
2. Customize hashtags per topic
Add a second Code node before the formatter. Read the post content, extract keywords, look up a hashtag map object in the code. Auto-inject topic-specific hashtags.
3. Engagement tracking
After each platform post, add a Google Sheets append row. Store: post text, platform, timestamp, and the post ID returned by the API. Later you can fetch engagement metrics by ID.
4. Add Instagram
Instagram requires a Facebook Business account and uses the Graph API differently (need to create a media container first, then publish). I left it out of the base version to keep setup simple — but the extra 2 nodes are well-documented in Meta’s API docs.
5. Handle rate limits
Add a Wait node (1-2 seconds) between platform posts if you’re posting at volume. Twitter’s free tier is 1,300 tweets/month — more than enough for one account.
What’s next
This workflow is part of a bigger collection I’ve been building: 15 ready-to-use n8n workflow templates covering email automation, CRM integration, invoice generation, AI support bots, and more.
If you want all 15 workflows pre-built and ready to import (plus setup guides for each), they’re at straipeai.gumrawd.com — each template also sold individually if you only need one.
The cross-poster is $19 standalone. Or grab the complete bundle and get all 15 for $97.
Questions? Drop a comment — happy to help with API setup or customizing the formatter.
Gemma 4 가 갑자기 답을 못 했다 — 외부 협업이 24시간 만에 root cause 찾아낸 이야기
TL;DR (한 문단)
자메스 (PROJECT JAMES, 로컬 Graph-RAG 엔진) 의 4개 인지 단계가 gemma4:e4b 에서 deterministic 하게 빈 응답 을 반환하는 패턴을 2026-05-18 에 fair-witness 보고서로 공개. 며칠 후 Ali Afana (Provia 창업자) 가 본인의 Gemma 4 walk-back article 에서 자메스를 3rd cross-validation context 로 인용. 자메스 측 단일 변수 실험으로 mechanism 확정: 모델이 visible output 첫 token 전에 ~500 token 의 hidden reasoning 을 소비. Cap 이 이 floor 이하면 100% 빈 응답. 4-line code change (PR #399) 머지 완료. 외부 → 내부 cross-validation, mechanism quantification, production fix 모두 24시간 안에.
- 시작: “왜 빈 응답이지?”
자메스 (PROJECT JAMES) 는 로컬에서 돌아가는 Graph-RAG 시스템입니다. Ollama 위에 Gemma 4 의 efficient 변형 (gemma4:e4b, 4B 파라미터) 을 기본 모델로 사용합니다.
v0.3 의 cognitive middleware layer 가 phase 2 를 출하하면서 — query rewriter, planner, reflect, verify, fact-check 같은 단계가 추가되었는데 — 이상한 패턴이 발견됐습니다.
코드
같은 모델인데 어떤 stage 는 잘 작동하고, 어떤 stage 는 무조건 0자 응답. gemma3:12b (12B) 로 바꾸면 9/9 통과. 모델 변경만으로 해결되지만, 왜 그런지가 미궁.
2026-05-18 에 fair-witness 보고서를 dev.to 에 게시: 4 가지 가설을 제시하고 답을 단정하지 않음.
가설 A: 4B 모델의 메타-추론 capacity floor
가설 B: 짧은 구조화 prompt 에서 early stop-token
가설 C: 한국어 지시 + 영어 JSON 키 혼합 confusion
가설 D: JAMES 측 prompt truncation 버그
외부 데이터 환영. 외부 reader 가 어느 가설을 falsify 하든 confirm 하든 보고서에 누적. - Ali Afana 의 walk-back — 다른 deployment context 에서 같은 패턴
며칠 후, Ali Afana 가 dev.to 에서 Gemma 4 의 다른 변형 (31B Dense vs 26B MoE) 에 대해 본인의 분석을 공개했습니다. 첫 주장: “두 architecture 의 동작 차이는 architecture 때문이다.”
그런데 Robin Converse (Triava Labs) 가 본인의 sovereign Ollama 환경에서 단순 검증을 했습니다 — max_tokens cap 을 풀고 같은 시나리오를 돌렸더니 18/18 다 통과. 그녀가 Ali 에게 던진 질문: “managed Gemini 쪽에서 cap 을 풀면 어떻게 되나요?”
Ali 가 단일 변수 재실험: max_tokens 400 → 4096. Dense 12/12, MoE 12/12 — 모두 회복.
그 결과로 Ali 는 본인의 article 을 공개적으로 walk-back: “차이는 architecture 가 아니라 token cap 이었다.”
walk-back article 에서 그는 자메스의 production default 를 3rd cross-validation context 로 명시:
Source
Context
Test
Result
Robin Converse
sovereign Ollama, uncapped
6 시나리오 × 3 온도
18/18
Ali Afana
managed Gemini, 400 → 4096
12 calls
12/12 회복
JAMES (자메스)
local Ollama, default 200/400/400/400
5/6 stages
빈 응답 - 자메스 측 검증: V3′ 단일 변수 실험
자메스 코드를 점검해 보니 충격적인 일치:
Stage
자메스 default
Ali 의 failing cap
query_rewriter.py:46
200
400
planner.py:43
400
400 ← 정확 일치
reflect.py:54 (CRITIQUE)
400
400 ← 정확 일치
verify.py:69 (FACT_CHECK)
400
400 ← 정확 일치
자메스의 production default 가 정확히 Ali 의 failing threshold 였습니다. 우리도 모르고 있었던 일치.
이제 단일 변수로 검증할 차례. V3′ 라고 명명한 사내 실험:
V3′.a — query_rewriter stage (n=10 per cap)
코드
이게 의미하는 바: gemma4:e4b 가 visible output 첫 token 직전까지 ~500 token 의 hidden reasoning 을 소비합니다. Cap 이 이 floor 이하면 모델은 visible byte 하나도 emit 못 함. 100% deterministic empty.
Ali 가 본인 article 에서 “starving the reasoning layer” 라고 비유한 패턴을 토큰 수준에서 정량 측정 한 셈입니다.
V3′.b — planner stage (n=10 per cap)
코드
Cross-stage 진단:
Metric
V3′.a (cap 200)
V3′.b (cap 400)
해석
Default-cap latency
2.1s
4.3s
Cap 의 2배 → 시간도 정확히 2배
4096-cap latency
5.3s
7.1s
+1.8s for planner 의 추가 reasoning
200 cap 의 latency 가 2.1s, 400 cap 이 4.3s — 선형 비례. 즉 ~500 token 의 reasoning floor 가 stage 와 무관한 모델 수준 특성. Cap 만큼의 시간을 선형으로 소진하다가 visible output 1 byte 도 emit 못 한 채 종료.
가설 공간 정리
✅ B (token budget): 확정 — mechanism 까지 측정
❌ A (4B floor): 사실상 기각 — 같은 모델이 cap 만 풀면 정상 작동
🤷 C, D: 변동 없음 (검증 안 됨)
⏸ E (-tag 후처리): cross-stage 일관성으로 약화 - The Fix — 4 line code change
PR #399: 4 개 stage 의 DEFAULT_MAX_TOKENS 상수를 4096 으로 bump.
Diff
각 변경에는 stable-WHY 코멘트 추가 — 미래 maintainer 가 “왜 4096 인가” 를 코드만 보고 이해할 수 있도록.
STEP 7 bench (13개 query 회귀 테스트, gemma3:12b 권장 모델 기준): 13/13 baseline tolerance 내. 변경의 비파괴성 확인.
Squash-merge 머지 완료. - 향후 진행
즉시 (1-3일)
V3′.c (reflect.critique) + V3′.d (verify.fact_check) post-merge validation. 같은 protocol, 같은 모델, 같은 default 400 — 동일 패턴 재현 강한 prior. Unexpected drift 면 single-line revert
synth.web_summary 의 inline max_tokens=300 (core/reasoning/pipeline_synth.py:141) 도 ~500 floor 아래 — 별도 PR 로 fix
중기 (Mid-June)
Ali Afana 의 Gemini backend implementation PR 도착 예정 (Track 1 Provider contract 가 이미 설정해놓은 surface)
Track 3 STEP 7 cross-experiment: 자메스 (Ollama local) + Ali (Gemini API) 의 swap eval — 같은 wiki corpus 에서 두 backend 의 retrieval-conditioning + synthesis layer 비교
장기 (Joint piece, Track 5)
Robin Converse 의 temperature sweep post + 자메스 cross-experiment + Ali Gemini 결과를 3-name joint piece 로 출판
가제: “3 contexts, 2 architectures, 1 mechanism” — 세 운영 환경에서 같은 mechanism 을 관찰한 협업 사례 - 이 이야기에서 배운 것
기술적으로
LLM 의 “빈 응답” 은 종종 모델 capability 가 아니라 budget 부족. Cap 이 hidden reasoning floor 이하면 visible output 전에 cap 도달.
gemma4:e4b 의 hidden-to-visible token ratio 는 약 5-6:1 (단일 stage 측정). 이건 모델 수준 특성으로 보임.
한 prompt 가 require 하는 reasoning budget 을 측정 없이 cap 잡으면 deterministic 실패의 함정. 운영 default 는 모델별로 floor 측정 후 결정해야 함.
협업으로
외부 사람이 본인의 hypothesis 를 honest 하게 walk-back 하는 것 이 협업의 가장 큰 가치. Ali 가 본인 article 을 공개적으로 정정한 결과로, 세 명의 deployment context 가 24시간 안에 cross-validation 완성.
공개 fair-witness 보고서 의 가치 — 외부 사람이 그것을 reference 로 인용하면서 연구의 chain 이 형성됨. 닫힌 연구 노트에서는 불가능한 형식.
Single-variable test 의 힘. Ali 가 본인의 가설을 검증한 방식, 우리가 그것을 자메스에서 검증한 방식, 모두 한 변수만 바꿔서 다른 모든 것 고정. Mechanism 격리에 필수.
링크
자메스 fair-witness 보고서 (2026-05-18): https://dev.to/hashevolution/5-empty-responses-from-gemma4e4b-4-hypotheses-0-root-cause-1ggd
Ali Afana walk-back article: https://dev.to/alimafana/i-raised-gemma-4s-token-cap-the-dense-model-stopped-refusing-2gf3
자메스 GitHub repo: https://github.com/Hashevolution/James-RAG-Evol
PR #399 (cap fix 머지됨): https://github.com/Hashevolution/James-RAG-Evol/pull/399
We Don’t Need More Phones. We Need More Mobile Spaces.
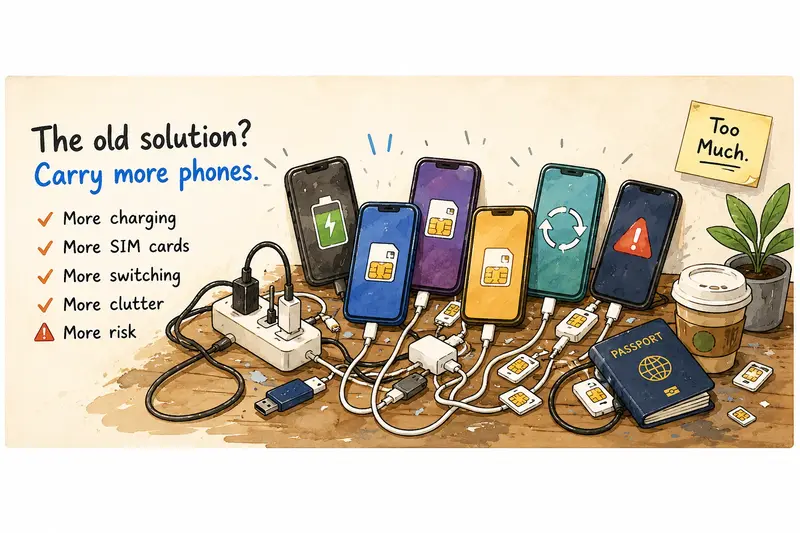
For years, the default solution to digital separation was simple:
Buy another phone.
One for work.
One for travel.
One for testing.
One for side projects.
But the more digital our lives become, the less practical this feels.
• more charging
• more SIM cards
• more switching
• more clutter
• more risk
Eventually, people end up carrying entire pockets of mobile identities.

Most people are not searching for “privacy”
People usually don’t search for:
• “digital identity continuity”
• “privacy infrastructure”
• “cloud mobile environments”
They search for problems.
Things like:
• “Do I really need a second phone?”
• “How do I separate work and personal accounts?”
• “How can I keep apps off my main phone?”
• “Can I open Android inside Telegram?”
Users rarely search for concepts.
They search for friction.
Maybe the future isn’t more phones
Maybe it’s more mobile spaces.
We already accept:
• multiple browser tabs
• multiple cloud workspaces
• multiple online identities
Mobile life may evolve the same way.
Not through carrying more hardware.
But through flexible mobile spaces that exist independently from physical devices.

The importance of separation
A lot of digital stress today comes from overlap.
Too many accounts on one device.
Too many apps mixed into one environment.
Too many identities sharing the same space.
Sometimes the real need is surprisingly simple:
“I don’t want this app on my main phone.”
Or:
“I need another mobile setup, but not another device.”
Separation is becoming infrastructure.
A second phone that behaves more like a link
At QccBot, we’ve been experimenting with a different idea:
What if a second Android phone behaved more like a link?
Not another physical device.
Just another mobile space:
• inside Telegram
• in the cloud
• accessible anywhere
A second mobile environment — available when you need it.
Final thought
Your digital life shouldn’t depend on how many phones you can carry.
Maybe the future is not more devices.
Just more mobile spaces.

I’m Building a Unified Freight Platform at My Part-Time Job and the Architecture Is Genuinely Interesting
Let me tell you about what I have been building at my part time job, because the architecture problem at the center of it is one of the more interesting things I have worked on.
I am a Pricing and Tech Associate at an international freight forwarding company. Part time. And in that capacity I am essentially responsible for the entire tech layer of the business.
Quick Context: What Has Already Shipped
Before I get into the big thing, the smaller deliverables first.
I built the founder’s personal portfolio website with a full blog system backed by Sanity CMS. He can add posts and categories without touching a single line of code. That is live and actively being used.
Multiple pitch and company profile decks. The XGBoost price predictor I wrote about a few weeks back, meant to speed up freight quoting which currently happens manually. And some LinkedIn content strategy and data analytics work which I will get to.
But the project I am most focused on right now is different in scale.
The Platform
A customer facing dashboard. Clients log in, add a booking, compare rates across multiple vendors, track shipments, and manage a wallet.
The CRUD layer and the auth and the wallet are all standard enough. Solvable problems with clear paths.
The genuinely hard part is the vendor integration layer.
The Actual Problem
We work with multiple vendors. Some specialise in specific trade lanes. Some are channel partners of UPS or FedEx, meaning they can offer better rates on certain routes.
Each vendor has their own API. Their own request structure for rates. Their own response shape for booking confirmations. Their own webhook format for tracking updates. Their own error codes and edge cases.
And I need to build one unified platform on top of all of it.
From the customer side: one clean interface. They enter shipment details, see a comparison, book, track. Clean and simple.
From behind the scenes: potentially five different APIs with five completely different structures being called, normalised, and returned in a consistent shape.
This is not a toy project. Real bookings, real money, real shipments. The stakes are not tutorial level.
Why the Adapter Pattern
I have been thinking through the architecture for a while and I keep landing in the same place.
A typed master interface in TypeScript. One canonical shape for everything.
interface FreightVendorAdapter {
  getRates(input: CanonicalRateRequest): Promise<CanonicalRateResponse[]>
  createBooking(input: CanonicalBookingRequest): Promise<CanonicalBookingConfirmation>
  getTracking(trackingNumber: string): Promise<CanonicalTrackingEvent[]>
}
Each vendor gets its own adapter class that implements this interface. The adapter does two things: translates canonical input into whatever that vendor’s API actually expects, and translates whatever comes back into the canonical response shape.
From the platform’s perspective, every vendor behaves identically. You call getRates and you get back CanonicalRateResponse[]. What the adapter does internally is fully encapsulated.
The TypeScript interface is not optional decoration here. It is the contract that holds the whole system together. If an adapter does not satisfy the interface, it does not compile. That is a hard guarantee, not a convention.
Adding a new vendor later becomes a well defined task: implement the interface, write the translation logic, plug it in. The rest of the platform does not change.
How I Am Thinking About the Rollout
Not building everything at once. That is how you build nothing.
Phase one: tracking. Bookings are still made manually on vendor platforms for now. But if I can surface tracking through our own interface, clients see our UI every time they check their shipment. Builds trust. Makes the platform feel real before it is fully real. Also the most self contained piece, I can implement the adapter, wire up one or two vendors, and have something useful without needing the full booking system done.
Phase two: rate comparison. Internal only first. The team uses it to quote faster. Once there is real confidence in accuracy and reliability, it opens to clients. You do not show clients something you have not stress tested yourself.
Phase three: booking and wallet. Later.
The Things I Did Not Expect to Be Doing
I have been doing data analytics in Excel.
I say this with full awareness of what that sounds like coming from a developer. But here is what actually happened.
We exported the founder’s LinkedIn connection data. Thousands of connections. The goal is to segment them for a targeted email campaign. Different message for a logistics professional versus a startup founder versus a procurement manager.
I learned VLOOKUP on the spot. Built filtering logic to create clean segments. And now I am looking into data enrichment tools because the raw LinkedIn export is shallow and a good email campaign needs more context than just name, company, and title.
I also pushed three LinkedIn posts as part of the founder’s personal content strategy. LinkedIn is its own craft. The feed is brutal and if the first line does not stop the scroll nothing else lands. I am learning this by doing it.
Being Inside an Industry vs Building For One
This is the part that is hardest to convey but I think matters most.
There is a real difference between building something because you theorised that a problem might exist, and building something because you watched the problem happen in front of you on a spreadsheet it should not be running on.
I have been going to meetings. Visiting shipment hubs. Sitting in rooms where the operational friction is not hypothetical.
When you are properly calibrated to a real context the engineering instincts feel different. You are not guessing at what matters. You can see it.
Where Things Are
Exams from 26th May through mid June, so there is a pause coming. But the foundation is solid and the thinking is clear.
By the end of June the tracking feature should be live. Rate comparison internals after that.
I will write about the adapter implementation as it comes together. There are some genuinely interesting problems in the data normalisation layer, especially around how different vendors model the same concepts (a trade lane, a weight break, an accessorial charge) in completely different ways.
More on that soon.
If you have built something similar with multiple third party APIs and a unified abstraction layer, I would genuinely love to hear how you structured it. Drop a comment or find me on thesidharth.com.
I built a self-hosted RAG system for Journalism — What Production Retrieval Taught Me
Over the last few months, I built Atlas — a fully self-hosted retrieval system designed for journalism workflows. No paid APIs. No hosted vector databases or AI infrastructure. Just local models, PostgreSQL, pgvector, Celery, and a retrieval pipeline built to survive production traffic.
I originally thought this would mostly be an infrastructure project. It wasn’t. The hardest lessons appeared after deployment — when assumptions broke, retrieval quality drifted, and tiny implementation decisions started affecting reliability.
What does Atlas do?
Atlas ingests live RSS feeds from BBC, Guardian, NYT, NPR, Deutsche Welle and more every 15 minutes, embeds content locally using sentence-transformers, stores vectors in PostgreSQL with pgvector, and answers questions with source-grounded citations.
Beyond search it has:
- Grounded Q&A — every answer maps to an exact source passage
- Claim-level fact-checking — splits text into claims, scores each against evidence
- Story brief generation — key facts, open questions, suggested angles for reporters
- Multi-format repurposing — one topic becomes newsletter, social post, audio script, headline
- A full story workspace — source notebooks, drafts, editorial review, version diff, publish readiness
https://github.com/PreethaRaj/atlas-editorial-intelligence/releases/download/v1.0.0/SearchAnswer.gif

https://github.com/PreethaRaj/atlas-editorial-intelligence/releases/download/v1.0.0/PartnerMode.gif

The retrieval pipeline
Here is the full pipeline before I get into the lessons:
Query string
    │
    ├── embed(query) → vector cosine > 0.30 → top 20 chunks
    ├── websearch_to_tsquery → PostgreSQL FTS → top 20 chunks
    └── Title FTS boost → top 10 articles
              │
              ▼
         RRF merge (k=60)
              │
         recency blend (85% relevance + 15% freshness)
              │
         post-cosine gate > 0.12
              │
         Policy engine (public / partner / paywall)
              │
         Response + inline citations
Lesson 1 — Pure vector search fails for news
This surprised me. I assumed a good embedding model would handle everything. It does not — at least not for current events journalism.
The problem: proper nouns.
Words like Philippines, Kishida, Rafah, Starmer are rare in any model’s training data relative to their importance in daily news. The cosine similarity between "Japan missile exports Philippines" and an article titled "Tokyo defence deal with Manila confirmed" was 0.28 — just below my original threshold of 0.30.
The article was clearly relevant. The vector search missed it completely.
Full-text search caught it immediately because Japan, missile, Philippines all appeared in the article text.
The fix was hybrid search. Vector catches semantic similarity. FTS catches proper nouns and exact terminology. Neither is sufficient alone for a news corpus.
# Three search paths merged with RRF
# Path 1: vector cosine similarity
# Path 2: websearch_to_tsquery (handles "Japan Philippines" as two terms)
# Path 3: title-specific FTS (weighted 0.7x to avoid title-only noise)

# RRF merge — no score normalisation needed because it only uses rank position
# final_score = Σ 1 / (60 + rank_i)
Lesson 2 — Batch embedding is not a micro-optimisation
I was calling embed() once per article for the first two weeks. Here is what that looks like:
17 feeds × 30 articles × embed(1 article) × 100ms = 51 seconds per ingest cycle
After switching to batch embedding — collect all articles, call embed([t1, t2, ..., tN]) once:
17 feeds × 30 articles = 510 articles
embed(510 articles)    = ~3 seconds total
17× faster. The model inference overhead is almost entirely fixed cost per batch, not per item. This is obvious from the PyTorch documentation but I had not read it carefully enough.
# Before — slow
for article in articles:
    vec = embed(article.content)
    insert_embedding(article.id, vec)

# After — fast
contents = [a.content for a in articles]
vecs     = embed(contents)   # single call, returns (N, 384) array
for article, vec in zip(articles, vecs):
    insert_embedding(article.id, vec)
Lesson 3 — The cosine threshold is your precision-recall dial
Atlas has two thresholds:
COSINE_MIN      = 0.30   # SQL WHERE — pre-filter before leaving DB
POST_COSINE_MIN = 0.12   # post-RRF — sanity gate after merge
What I learned tuning these:
| Threshold | Effect |
|---|---|
| 0.45 | Missed “Japan missile Philippines” — too restrictive |
| 0.30 | Good balance for a news corpus |
| 0.20 | Sports results started appearing for political queries |
The intuition: news articles about related topics often use completely different vocabulary than the query. A threshold of 0.30 allows the model to bridge that vocabulary gap. A threshold of 0.45 requires the query and article to use nearly identical language — which defeats the purpose of semantic search.
POST_COSINE_MIN = 0.12 exists only to handle FTS-only hits. When an article is found by keyword search but has no semantic overlap with the query (cosine = 0.0), it means the keyword match was probably accidental. The post-filter removes those.
Lesson 4 — Celery beat scheduling has a startup timing problem
The beat schedule runs ingest_all_feeds every 15 minutes. But there is a subtle issue: on a fresh deploy, the first beat fires at the next :00, :15, :30, or :45 UTC boundary — not 15 minutes from startup.
Deploy at 14:01 → first ingest at 14:15  ✓ fine
Deploy at 14:14 → first ingest at 14:15  ✓ fine
Deploy at 14:00:01 → first ingest at 14:15  ✗ 15 minute corpus gap on first launch
The fix was timedelta(minutes=15) instead of crontab(minute='*/15').
The startup_ingest task also checks corpus article count before honouring the Redis dedup flag. Empty corpus → ingest regardless. This handles docker-compose down -v (fresh database) correctly.
beat_schedule = {
    "ingest-every-15-min": {
        "task":     "tasks.ingest_all_feeds",
        "schedule": timedelta(minutes=15),  # from startup, not clock-aligned
    },
    "startup-ingest-once": {
        "task":     "tasks.startup_ingest",
        "schedule": timedelta(hours=24),    # fires once, Redis dedup prevents repeats
    },
}
Lesson 5 — The Docker healthcheck dependency chain matters
This one took me an embarrassing amount of time.
celery-beat:
  depends_on:
    celery-worker:
      condition: service_healthy   # ← this line is critical
Without service_healthy, beat starts immediately and dispatches tasks before any worker is ready to consume them. The tasks sit in the queue, beat fires again in 15 minutes, tasks pile up.
With service_healthy, beat waits until a worker is confirmed ready. Clean startup every time.
The worker healthcheck uses celery inspect ping which confirms the worker is actually processing — not just that the container started.
What is next
The infrastructure has a warmup_reranker() stub in main.py for a cross-encoder reranker. That is the highest-impact next upgrade — running cross-encoder/ms-marco-MiniLM-L-6-v2 over the top-20 RRF results before returning to the user. Adds ~100ms latency but meaningfully improves ranking for ambiguous queries.
I am also looking at adding a BM25 path via the pg_bm25 extension (ParadeDB) to replace the PostgreSQL FTS path. BM25 handles document length normalisation better than tsvector for longer articles.
The project
Atlas is built to learn and adapt. The README has a two-week tutorial walking through each layer of the system.
GitHub: https://github.com/PreethaRaj/atlas-editorial-intelligence
Stack: FastAPI · PostgreSQL 16 · pgvector · Celery · Redis · sentence-transformers · Next.js 14 · Docker Compose
Happy to answer questions on the retrieval architecture, the pgvector schema, or the Celery configuration in the comments.