This Week In React #282 : Security, Fate, TanStack, Redux, Jotai | Hermes-node, Expo, Rozenite, Harness | TC39, Bun, pnpm, npm, Yarn, Node

banner

Hi everyone, Seb and Jan here 👋!

It looks like security is going to be a hot topic this year! 😅

More packages are being compromised, and blog posts are also covering recent RSC vulnerabilities.

Maybe we’re reaching a tipping point, and better security practices will consolidate this year.

On the React Native side, Hermes-node is quite exciting, although it’s very early.

An exciting TC39 meeting is currently underway, and several proposals have already progressed.

Yarn and npm are improving on the security side.

Bun and pnpm are being ported to Rust.

💡 Subscribe to the official newsletter to receive an email every week!

banner

💸 Sponsor

Ship AI generated code safely with Meticulous.

Ship AI generated code safely with Meticulous.

Claude writes your code. Claude reviews your code. Claude fixes the review comments. And somehow, you’re the one getting paged at 2am when it breaks in prod.

Fortunately, top AI-driven teams like Dropbox, Notion, LaunchDarkly, and Wiz rely on Meticulous to run 1000s of e2e UI tests autonomously, covering every user flow, edge case, role and permutation. Built by ex-Palantir engineers, Meticulous gives you near-exhaustive coverage in weeks, without any developer effort. 

It works like magic in the background:

  • Near-exhaustive coverage on every test run
  • No test creation
  • No maintenance (seriously)
  • Zero flakes (built on a deterministic browser)

Check it out – and see why one engineering leader at Dropbox said that “once we started using Meticulous, we couldn’t imagine working without it.”

⚛️ React

Mini Shai-Hulud worm keeps digging

Mini Shai-Hulud worm keeps digging

Remember last week’s TanStack Router compromise? The dangerous worm from TeamPCP keeps compromising users and maintainers across ecosystems, affecting popular packages such as echarts-for-react and @antv, and GitHub actions such as actions-cool/issues-helper. OpenAI employees got compromised, leading them to regenerate code signing certificates. Grafana has been blackmailed by a ransomware group.The Million.js repository was also briefly compromised, but they seem to have gotten lucky: it apparently didn’t affect anyone.

Rumors also link this worm to the Nx Console VSCode extension compromise, and possibly connected to a major GitHub internal repo breach. This story isn’t over — “Mini” feels like a very questionable name 😅!

💸 Sponsor

Tomorrow Only: Next.js Debugging Workshop

Tomorrow Only: Next.js Debugging Workshop

Most Next.js bugs don’t fail loudly. They fail in a webhook handler at 3am, in a server component nobody touched, in an auth flow that worked yesterday. Sentry’s hands-on workshop shows you how to catch them with high-context logs and distributed tracing.

Last chance to save your spot. Register today.

📱 React-Native

🔀 Other

🤭 Fun

alt

alt

See ya! 👋

AI Copilot vs AI Agent Architecture – What’s Actually Different (And Why It Matters)

Copilot Architecture Explained

You’ve heard both terms thrown around in every product launch this year. AI copilot here, AI agent there. Microsoft slaps “copilot” on everything. Startups call their chatbots “agents.” Half the industry seems confused about where one ends and the other begins.

Let’s fix that.

This isn’t a marketing comparison. This is an architecture breakdown — how these two patterns actually differ under the hood, what tradeoffs each makes, and when you should reach for one over the other.

## What Is an AI Copilot?
An AI copilot is an assistive system that works alongside a human, augmenting their decisions without replacing them. Think of it as a very smart pair programmer who never grabs the keyboard unless you ask.

The core architectural trait: the human stays in the loop for every consequential action.

A copilot receives context (your code, your document, your spreadsheet), generates suggestions, and waits for you to accept, reject, or modify them. It doesn’t execute on its own. It doesn’t chain tasks together. It responds to your immediate intent and makes you faster.

GitHub Copilot is the canonical example. You type a function signature, it suggests the body. You press Tab or you don’t. The copilot never decides to refactor your codebase overnight.
Microsoft’s Copilot products across 365 follow the same pattern — a copilot agent embedded inside Word, Excel, or Teams that drafts, summarizes, and suggests while you retain full control. If you’ve wondered what is an agent in Copilot for Microsoft 365, it’s a scoped AI assistant that operates within a single application’s context, following your explicit instructions rather than pursuing goals independently.

## Copilot Architecture at a Glance

Copilot Architecture Explained

Key characteristics:
Single-turn interaction. You ask, it answers. There’s no multi-step planning.

Narrow context window. The copilot sees what you’re currently working on — the open file, the selected cells, the email thread.
No persistent memory across tasks. Each interaction is largely stateless.

No tool use or external actions. It generates text, code, or suggestions. It doesn’t call APIs, book meetings, or deploy code.

What Is an AI Agent?

An AI agent is an autonomous system that pursues goals over multiple steps, makes decisions about how to achieve those goals, and takes actions in the real world (or a digital environment) with minimal human intervention.

The core architectural trait: the agent decides its own plan of execution.

You give it an objective — “find the three cheapest flights to Tokyo in March, compare layover times, and book the best option” — and it figures out the steps, picks the tools, handles errors, and (ideally) delivers a result. You don’t approve every intermediate step. The agent operates with delegated authority.

This is a fundamentally different trust model from a copilot.

## Agent Architecture at a Glance

Agent Architecture Explained

Key characteristics:
Multi-step reasoning. The agent breaks a goal into subtasks and sequences them.

Tool use. Agents call external APIs, read databases, browse the web, write files, and trigger workflows.

Persistent state. They maintain context across steps and sometimes across sessions.

Self-correction. When a step fails, the agent re-plans rather than crashing.

Delegated autonomy. The human sets boundaries, but the agent navigates within them independently.

The Real Architectural Differences

Let’s get precise. Here’s where the two patterns diverge at the system level.

1. Control Flow

Copilot: Synchronous, human-driven loop. The user initiates every interaction. The system is reactive.

Agent: Asynchronous, goal-driven loop. The agent initiates its own actions after receiving a goal. The system is proactive.
This is the single biggest architectural difference. Everything else flows from it.

## 2. Planning Layer

Copilots don’t plan. They respond. A copilot doesn’t look at your codebase and think, “I should refactor this module first, then update the tests, then modify the API endpoint.” It waits for you to ask about each piece.

Agents plan explicitly. Modern agent frameworks — LangGraph, CrewAI, AutoGen — all include a planning step where the LLM decomposes a goal into ordered subtasks. Some use ReAct (Reason + Act) loops. Others use more structured plan-then-execute pipelines.

# Simplified ReAct loop in an agent
while not task_complete:
    thought = llm.reason(observation, goal, history)
    action = llm.select_action(thought, available_tools)
    observation = execute(action)
    history.append((thought, action, observation))
    task_complete = llm.evaluate(observation, goal)

A copilot never runs this loop. It runs the equivalent of a single llm.generate(context, prompt) call.

3. Tool Integration

Copilots are typically sandboxed. GitHub Copilot can’t open a pull request. Microsoft 365 Copilot can’t publish a SharePoint page without your explicit click.

Agents are defined by their tool access. An agent without tools is just a chatbot with aspirations. The tool layer — APIs, function calling, code execution, browser automation — is what makes an agent agentic. The AI agent Microsoft ecosystem, for instance, is rapidly expanding with Copilot Studio letting teams build agents that connect to Dataverse, Power Automate, and external APIs.

4. Memory Architecture

Copilots use short-term, session-scoped context. Your conversation history, maybe some retrieval-augmented generation (RAG) over your documents. When you close the tab, the context resets.

Agents need persistent memory. They track what they’ve already tried, what worked, what failed, and what’s left to do. This often means:

  • A working memory (current task state)**
  • An episodic memory (past interactions and outcomes)
  • A semantic memory (retrieved knowledge from vector stores or knowledge graphs)

5. Error Handling

Copilot error handling: the user sees a bad suggestion and ignores it. Done.

Agent error handling: the system must detect failures, reason about what went wrong, and either retry with a different approach or escalate to the human. This is where most agent implementations get brittle. Robust error handling is one of the hardest parts of AI agent development services — it’s the difference between a demo and a production system.

## What Are AI Agents, Really? A Taxonomy
Not all agents are created equal. The term gets applied to everything from a glorified chatbot to a fully autonomous research system. Here’s a practical spectrum:

Level 0 — Chatbot. Stateless Q&A. No tools, no memory, no planning. (This is not an agent, despite what some landing pages claim.)

Level 1 — Tool-augmented LLM. Can call functions and APIs, but follows a fixed, developer-defined workflow. Limited autonomy.

Level 2 — ReAct Agent. Reasons about which tools to use and in what order. Can handle novel situations within its tool set. This is what most people mean when they say “AI agent” today.

Level 3 — Multi-Agent System. Multiple specialized agents coordinate on a shared goal. One agent researches, another writes, another reviews. Frameworks like CrewAI and AutoGen target this pattern.

Level 4 — Fully Autonomous Agent. Sets its own subgoals, acquires new capabilities, operates over extended time horizons. We’re not here yet for production use cases, but research is active.

When to Build a Copilot vs an Agent

This is the practical question. Here’s a decision framework.
Build a copilot when:

  • The task requires human judgment that can’t be safely delegated (medical decisions, legal review, financial approvals)
  • The cost of a wrong autonomous action is high
  • Users want to stay in control and learn from the AI’s suggestions
  • The interaction is inherently single-turn: suggest, accept, move on
  • You need to ship quickly — copilots are architecturally simpler

Build an agent when:

  • The task involves multiple steps that are tedious for a human to orchestrate
  • The steps are well-defined enough that failure modes are manageable
  • The cost of a wrong intermediate step is low or recoverable
  • Users care about the outcome, not the process
  • You can define clear guardrails and boundaries for autonomous operation

Build a hybrid when:

  • The workflow has both routine and high-judgment steps
  • You want the agent to handle the boring parts and escalate the hard parts
  • This is increasingly the pattern: an agent that runs autonomously but checkpoints with the human at defined gates

## The Hybrid Pattern: Where the Industry Is Heading

The copilot-vs-agent framing is useful for understanding architecture, but the most practical systems blend both patterns. Microsoft’s own evolution shows this clearly — what started as a pure copilot agent pattern in 365 is steadily gaining agentic capabilities, where Copilot can now execute multi-step workflows in the background while still checkpointing with you.
The hybrid architecture looks like this:

User sets goal
  └─▶ Agent plans subtasks
        ├─▶ Subtask 1: Agent executes autonomously (low risk)
        ├─▶ Subtask 2: Agent executes autonomously (low risk)
        ├─▶ Subtask 3: Copilot mode — presents options, human decides (high risk)
        └─▶ Subtask 4: Agent executes autonomously (low risk)
              └─▶ Agent delivers result

The key design decision isn’t “copilot or agent.” It’s where to draw the autonomy boundary for each step in a workflow.

Practical Implications for Developers

If you’re building AI-powered products today, here’s what this means:

Start with a copilot, graduate to an agent. A copilot is lower risk, faster to build, and teaches you what your users actually want automated. Once you see which suggestions get accepted 95% of the time, those are your candidates for full automation via an agent.

Invest in your tool layer. Whether you’re building a copilot or an agent, the quality of your tool integrations determines the quality of your AI system. Well-typed function definitions with clear descriptions, proper error returns, and idempotent operations make both patterns work better.

Design for observability. Agents are harder to debug because they make their own decisions. Log every step: the plan, the tool calls, the observations, the reasoning. You’ll need this when (not if) something goes wrong.

Treat autonomy as a dial, not a switch. Give users control over how much autonomy the system has. Some users want full agent mode. Others want to approve every step. Build for both.

The Bottom Line

An AI copilot assists. An AI agent acts. The difference isn’t branding — it’s a fundamental architectural choice about who holds the decision-making authority at each step of a workflow.
Copilots are the safer, simpler starting point. Agents are more powerful but harder to build reliably. The future is hybrid systems that flex between both modes based on the risk and complexity of each task.

The question isn’t which one is better. It’s which autonomy level is appropriate for each step in your specific workflow.

Build accordingly.

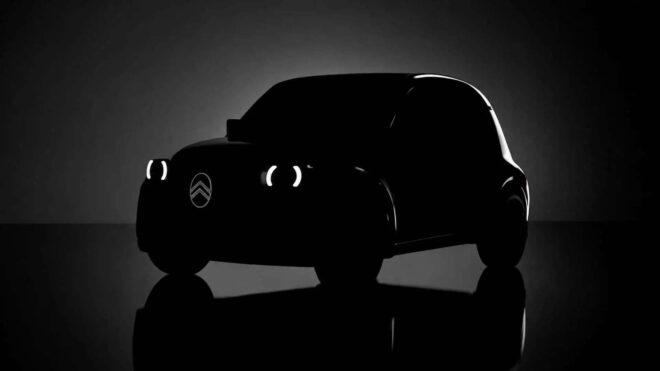
Efsane model Citroën 2CV, elektrikli olarak geri dönüyor

Citroën 2CV

Citroën 2CVBugün resmen yapılan doğrulamaya göre 1948-1990 yılları arasında üretilen efsane otomobil modeli Citroën 2CV, elektrikli olarak geri dönüyor. Gövde yapısı yukarıdaki fotoğraf ile gözler önüne serilen araç, aktarıldığı kadarıyla Avrupa’da 15 bin euro civarında satılacak. Tam olarak ekim ayında düzenlenecek 2026 Paris Otomobil Fuarı’nda görücüye çıkarılacak kompakt elektrikli, teknik olarak neler sunacak henüz bilinmiyor.

Efsane model Citroën 2CV, elektrikli olarak geri dönüyor yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Smart Contract Security: NEAR’s Futures Surge and AI Token Risks

Cover: Analyzing NEAR's Record Futures Open Interest Surge and Smart Contract Risks in AI Token Markets

Analyzing NEAR’s Record Futures Open Interest Surge and Smart Contract Risks in AI Token Markets

Friday’s market action saw AI-oriented tokens NEAR and FET sharply outperform many peers, signaling a pronounced rotation of speculative capital. NEAR’s price jumped by 28.5% accompanied by a surge in its futures open interest (OI) to a record 282.53 million tokens, while FET posted an 11.4% gain in the same timeframe. Meanwhile, privacy-focused coins such as DASH, ZEC, and XMR lost much of their gains from earlier in the week. This abrupt shift highlights the intersection of market dynamics and protocol risk—the steep price moves and elevated derivatives activity in NEAR, an AI ecosystem protagonist, create fertile ground for smart contract vulnerabilities, particularly those tied to oracle manipulation and flash loan exploits.

In this article, we explore the technical challenges developers face building AI-related smart contracts on NEAR and similar platforms amid these market pressures. The elevated futures OI in NEAR and the speculative waves driving tokens like FET demand a thorough look at how typical DeFi security pitfalls can escalate under these exotic conditions.

NEAR’s Futures Boom: What It Means for Developers

The surge to a record high of 282.53 million tokens in NEAR futures OI signals intense market leverage and positioning. On the one hand, rising open interest can reflect trader conviction and liquidity depth—on the other, it heightens systemic fragility. Large-scale derivatives exposure is often accompanied by rapid price moves and increased risk of cascading liquidations, events that adversaries can exploit by attacking oracle price feeds or draining liquidity pools via flash loans.

// Common vulnerable oracle usage pattern
contract VulnerableOracleUser {
    address public oracle;
    uint public price;

    function updatePrice() external {
        uint newPrice = Oracle(oracle).getPrice();
        require(newPrice > 0, "Invalid price");
        price = newPrice;
    }
}

In volatile markets, if a price oracle is manipulated temporarily—like during a flash loan attack—contracts that rely on its price for collateralization or liquidation thresholds can be tricked into executing unintended logic. NEAR’s recent price spike and futures activity underscore the criticality of oracle security and the risks when these oracles lack robustness against price spoofing or manipulation in a high-leverage environment.

Flash Loan Exploits: Amplified Risks in AI Token Ecosystems

Flash loans have become a double-edged sword, enabling composability and leverage but also providing attackers with tools to perform large-scale on-chain exploits in a single transaction. These attacks typically involve:

  • Borrowing huge capital instantly (no collateral)
  • Manipulating on-chain prices via oracle or pool interactions
  • Profiting from erroneous contract logic based on manipulated states

With AI sector tokens like NEAR and FET rallying, the speculative flows and derivatives volume heighten exposure. Flash loan attacks on such tokens can cause catastrophic collateral liquidations, severely amplifying market instability.

// Flash loan guard modifier example—blocks calls that change balances mid-transaction
modifier noReentrantFlashLoan() {
    require(!inFlashLoan, "No flash loan reentry");
    inFlashLoan = true;
    _;
    inFlashLoan = false;
}

Developers should build reentrancy guards and flash loan detection mechanisms, such as restricting asset balance changes mid-transaction or verifying that price updates come from decentralized, aggregated oracles immune to quick price swings.

Oracle Architecture Best Practices Under Market Stress

Oracle manipulation remains the top vector for attacks in fast-moving futures and spot markets. The best approach combines:

  • Multi-source data aggregation with median or trimmed mean pricing to prevent single-source outliers.
  • Time-delayed oracle updates to reduce flash price spike effects.
  • Circuit breakers or sanity checks to suspend trading if prices deviate wildly beyond thresholds.
Oracle Design Pattern Pros Cons
Single centralized oracle Simple, fast Vulnerable to manipulation
Aggregated decentralized feeds More secure, manipulation resistant Increased complexity and latency
Time-delayed feeds Protects against flash attacks Less responsive to real-time market moves

For NEAR and other AI-related protocols, developers must balance between responsiveness and attack surface reduction, especially as futures OI and market speculation intensify.

Altcoin Rotation and Institutional Movements: Impact on Risk Profile

Friday’s market dynamics illustrated clear altcoin rotation: speculative flows moved out of privacy coins DASH, ZEC, XMR, and into AI tokens and high-liquidity altcoins like HYPE (up ~60%) and ATOM (up 5% since midnight UTC). Additionally, institutions increased exposure to crypto-related equities, e.g., Ark Invest purchasing $5 million of Bullish (BLSH) shares over days.

Such rotation pushes developers building AI token smart contracts to continually evaluate the shifting risk landscape: elevated institutional participation often signals increasing derivatives leverage; meanwhile, retail speculation in emergent AI tokens increases volatility and the window for exploits.

Formal Security Pillars for AI Token Smart Contracts

Given the amplified risks illustrated by NEAR’s futures surge and market rotation, developers should emphasize:

// Example of a simplified flash loan resistant collateral update
function updateCollateral(uint256 newAmount) external {
    require(!flashLoanActive(), "Flash loan detected");
    collateral = newAmount;
    emit CollateralUpdated(newAmount);
}
  • Flash Loan Resistance: Detect and prevent flash loan-executed state changes.
  • Oracle Resilience: Use multi-asset oracles with time delay and anomaly detection.
  • Access Control: Restrict critical functions to trusted or multi-signature governance.
  • Emergency Stops: Implement pausable mechanisms to halt trading if anomalies detected.
  • Stress Testing: Simulate high volatility and liquidation cascades during audits.

In the team’s experience serving Web3 developers, surges in futures open interest and volatility—such as those recently observed with NEAR—often unmask latent oracle and composability weaknesses in smart contracts. Proactively addressing these vulnerabilities before market-induced crises arise is key to sustainable protocol security.

The AI token boom, exemplified by NEAR’s record futures open interest and price surge, presents a perfect storm of opportunity and risk for DeFi developers. Smart contract security under such conditions demands rigorous oracle design, flash loan defenses, and adaptive risk controls that can withstand rapid market shifts. The team I work with, Soken, specializes in auditing these complex AI and DeFi ecosystems, helping developers navigate emerging threats in unprecedented market cycles.

If you’re building or maintaining smart contracts in these high-stakes environments, carefully consider the behavioral patterns of futures markets and incorporate attack-resistant oracles and composability safeguards. Vigilance in these technical pillars ultimately shields your protocol against exploit vectors turbocharged by market speculation.

https://soken.dev/

Database Maintenance: Tracing Production Incidents to Their Root Cause

Wait State Triage

Database maintenance fails when it runs on a calendar instead of on signal. Fragmentation, stale statistics, log growth, and lock contention are functions of write workload, not weekly schedules. Scheduled maintenance skips the tables that need it most, and the resulting incident fires before anyone notices the gap.

This article replaces the cron job with a response system. Four observable symptoms (I/O degradation, query plan regression, storage pressure, and lock contention) each trace back to a specific maintenance root cause, with fixes for SQL Server, PostgreSQL, and MySQL. Silent corruption, the one failure mode that produces no precursor signal, gets its own detection-first treatment. A closing scorecard lets you self-assess.

First Response: Wait State Triage Across Engines

When a slow query alert fires, the first diagnostic step is the same regardless of engine: check what the query is waiting on. Wait states are the universal entry point for database incident triage. They tell you whether the problem is I/O bound, lock bound, or CPU bound, and that classification determines which section of this article contains your fix.

Wait State Triage

SQL Server wait types

PAGEIOLATCH_SH means the query is waiting for data pages to be read from disk into the buffer pool. This points to index fragmentation, buffer cache pressure, or storage subsystem saturation. LCK_M_S and LCK_M_X indicate row or table-level lock contention from a concurrent transaction or a maintenance operation holding locks. CXPACKET (visible in sys.dm_exec_requests) signals parallelism skew, which typically traces to stale statistics or a missing index causing the optimizer to choose an expensive parallel plan.

PostgreSQL and MySQL equivalents

PostgreSQL exposes wait diagnostics through pg_stat_activity. The query below is your triage entry point:

-- PostgreSQL: active session wait events
SELECT pid, wait_event_type, wait_event, state, query
FROM pg_stat_activity
WHERE wait_event IS NOT NULL
  AND state != 'idle'
  AND backend_type = 'client backend';

The diagram above maps each value to its target section. One non-obvious case is worth calling out: a NULL wait_event while state = 'active' indicates the query is compute-bound (the PostgreSQL equivalent of CPU pressure), which can point toward stale statistics or a plan regression rather than I/O.

For MySQL, performance_schema.events_waits_current is the source for the values shown in the diagram. Verify performance_schema = ON in my.cnf first, as it is disabled by default in some MySQL 5.x builds and carries non-zero overhead; on MySQL 8.0+ it is enabled by default. SHOW PROCESSLIST gives a quicker but less granular view.

Once you have identified the wait type, the sections below trace each category to its maintenance root cause and prescribe the fix. For hybrid topologies that span on-prem and cloud-managed instances, ManageEngine OpManager Nexus surfaces wait-state and slow-query data across both in a single triage view through its SaaS delivery for managed databases.

Symptom: I/O Degradation and Read Amplification

A buffer cache hit ratio drifting below the 95-99% range that healthy OLTP workloads maintain is the cross-engine signal that the engine is reading more pages from disk than memory can satisfy.

SQL Server practitioners typically treat 90% as a warning and 85% as an action threshold; PostgreSQL and MySQL expose equivalents in pg_statio_user_tables and information_schema.INNODB_BUFFER_POOL_STATS (or SHOW ENGINE INNODB STATUS). The most common cause is index fragmentation: pages split, B-tree leaves scatter across non-contiguous extents, and one logical read becomes several physical I/Os. Read amplification surfaces as PAGEIOLATCH waits on SQL Server, DataFileRead on PostgreSQL, and elevated innodb_data_file waits on MySQL.

On cloud-managed instances where DMV access is restricted (RDS, Azure SQL Managed Instance), OpManager Nexus’s SaaS delivery surfaces the same buffer-pool visibility through its agent.

Diagnosing index bloat

SQL Server: sys.dm_db_index_physical_stats is the authoritative source for fragmentation data. The query below returns indexes above 5% fragmentation with more than 1,000 pages (the page count filter matters because rebuilding very small indexes produces negligible performance improvement):

SELECT
    OBJECT_NAME(ips.object_id) AS tbl_name,
    i.name AS idx_name,
    ips.index_type_desc,
    ips.avg_fragmentation_in_percent,
    ips.page_count
FROM sys.dm_db_index_physical_stats(
    DB_ID(), NULL, NULL, NULL, 'LIMITED') AS ips
JOIN sys.indexes i
    ON ips.object_id = i.object_id
    AND ips.index_id = i.index_id
WHERE ips.avg_fragmentation_in_percent > 5
    AND ips.page_count > 1000
ORDER BY ips.avg_fragmentation_in_percent DESC;

The 'LIMITED' scan mode traverses only the index allocation structure, making it safe and fast on production systems. 'SAMPLED' reads a statistical sample of data pages for more accurate numbers at moderate I/O cost on very large tables or partitioned indexes. 'DETAILED' performs a full scan; reserve it for offline assessment.

PostgreSQL: The pg_stat_user_tables view provides the first signal. A dead_pct above 10-20% on a high-write table is a common trigger for manual VACUUM (this range aligns with practitioner guidance, with the autovacuum default kicking in at 20%):

SELECT schemaname, relname,
       n_dead_tup,
       n_live_tup,
       round(n_dead_tup::numeric / NULLIF(n_live_tup + n_dead_tup, 0) * 100, 2) AS dead_pct,
       last_vacuum,
       last_autovacuum
FROM pg_stat_user_tables
WHERE n_live_tup > 10000
ORDER BY n_dead_tup DESC
LIMIT 20;

For index-level bloat (physical B-tree bloat that VACUUM does not reclaim), the pgstattuple extension exposes two functions. pgstattuple() returns free_percent, the wasted-space ratio that is the PostgreSQL equivalent of avg_fragmentation_in_percent:

CREATE EXTENSION IF NOT EXISTS pgstattuple;
SELECT * FROM pgstattuple('orders_created_at_idx');

pgstatindex() returns the B-tree-specific metrics: leaf_fragmentation (percentage of leaf pages not in logical order, indicating physical scatter) and avg_leaf_density (below 50% suggests the index has many near-empty pages):

SELECT * FROM pgstatindex('orders_created_at_idx');

Both functions perform a full scan of the target relation, so on a multi-hundred-GB index expect runtime and I/O comparable to a sequential read of the entire object — schedule them like any other heavy diagnostic, not in a hot loop.

High free_percent with low leaf_fragmentation may indicate space reclaimable by VACUUM rather than a full rebuild. Values of free_percent in the 20-30% range are a widely used trigger for REINDEX; consult your workload and current community guidance to calibrate the threshold.

MySQL: Query information_schema.TABLES for InnoDB tablespace fragmentation:

SELECT table_schema, table_name,
       round(data_length / 1024 / 1024, 2) AS data_mb,
       round(data_free / 1024 / 1024, 2) AS free_mb,
       round(data_free / (data_length + index_length + data_free) * 100, 2) AS frag_pct
FROM information_schema.TABLES
WHERE engine = 'InnoDB'
  AND data_free > 0
ORDER BY data_free DESC
LIMIT 10;

This metric is meaningful only with per-table tablespaces (innodb_file_per_table = ON, the default since MySQL 5.6); on shared-tablespace deployments, data_free reflects unused space in the global ibdata file and is repeated identically across every InnoDB row.

Tables with frag_pct above 20% are commonly treated as candidates for OPTIMIZE TABLE or pt-online-schema-change (this threshold is a practitioner guideline rather than a MySQL-documented limit).

Remediation by engine and downtime tolerance

Microsoft’s documentation on index reorganization and rebuild maps fragmentation levels to two SQL Server operations:

  • 5-30% fragmentation: ALTER INDEX idx_name ON tbl_name REORGANIZE compacts leaf-level pages incrementally as an online operation. It can be interrupted mid-run without corrupting the index.
  • Above 30%: ALTER INDEX idx_name ON tbl_name REBUILD recreates the index. Offline by default (acquires a schema modification lock that blocks concurrent access). Add WITH (ONLINE = ON) on Enterprise edition to keep the index available during the rebuild. Note that even online rebuilds acquire a brief Schema Modification (Sch-M) lock at the beginning and end of the operation, typically milliseconds, but long enough to cause noticeable waits on extremely high-concurrency workloads.

On SQL Server 2017+, combine ONLINE = ON with RESUMABLE = ON and a configurable MAX_DURATION to pause and resume long rebuilds: ALTER INDEX idx_name ON tbl_name REBUILD WITH (ONLINE = ON, RESUMABLE = ON, MAX_DURATION = 60). Resume with ALTER INDEX idx_name ON tbl_name REBUILD WITH (RESUME). RESUMABLE = ON requires ONLINE = ON and is Enterprise-edition-only on SQL Server 2017; SQL Server 2019+ also enables it on Standard and Web editions, so verify your edition before scripting against this syntax.

The 5% floor matters equally. Running REORGANIZE on a 3% fragmented index generates log activity, consumes I/O, and produces no measurable query improvement.

For PostgreSQL, VACUUM reclaims dead tuple storage and updates the visibility map. ANALYZE updates planner statistics. REINDEX rebuilds the B-tree structure when physical index bloat is confirmed:

VACUUM VERBOSE ANALYZE transactions;

-- Blocking rebuild (requires maintenance window):
REINDEX INDEX transactions_created_at_idx;

-- Non-blocking rebuild (PostgreSQL 12+):
REINDEX INDEX CONCURRENTLY transactions_created_at_idx;

REINDEX CONCURRENTLY cannot run inside a transaction block and takes longer than the standard form, but it allows writes to continue during the rebuild. Beyond immediate remediation, VACUUM VERBOSE output is worth reviewing regularly on your heaviest-write tables. It provides dead tuple counts, page recycling data, and cleanup statistics that give indirect signals of table health. PostgreSQL’s autovacuum handles routine dead tuple cleanup automatically, but under high-velocity delete workloads it can fall behind. The official PostgreSQL documentation on routine vacuuming covers tuning autovacuum_vacuum_scale_factor and autovacuum_vacuum_threshold for tables where the defaults prove too conservative.

For MySQL, OPTIMIZE TABLE defragments the tablespace and rebuilds statistics in a single operation. In MySQL 8.0+, this runs online for regular InnoDB tables with only brief metadata locks at prepare and commit phases, but the full copy can take significant time on large tables:

OPTIMIZE TABLE events;
ANALYZE TABLE events;

Internally, InnoDB maps OPTIMIZE TABLE to ALTER TABLE ... FORCE, rebuilding the clustered index and all secondary indexes. For zero-downtime execution on large tables, pt-online-schema-change from Percona Toolkit performs the same rebuild while keeping the original table live:

pt-online-schema-change 
  --alter "ENGINE=InnoDB" 
  --execute 
  D=app_prod,t=events,h=127.0.0.1,F=$HOME/.my.cnf

This maintains a shadow copy and replays writes via triggers throughout the rebuild. The --execute flag is required; without it the tool runs in dry-run mode only.

Remediation lookup by symptom severity:

Symptom Severity Engine Downtime Tolerance Recommended Action
Mild (frag < 5% / dead_pct < 10%) All N/A None
Moderate (5-30%) SQL Server Any ALTER INDEX … REORGANIZE
Severe (> 30%) SQL Server Required ALTER INDEX … REBUILD WITH (ONLINE=ON) [Enterprise]
Severe (> 30%) SQL Server Available ALTER INDEX … REBUILD
Elevated (dead_pct > 10%) PostgreSQL Any VACUUM ANALYZE
High bloat (free_percent > 30%) PostgreSQL Required REINDEX CONCURRENTLY
Elevated (frag_pct > 20%) MySQL Available OPTIMIZE TABLE
Elevated (frag_pct > 20%) MySQL Required pt-online-schema-change

With fragmentation addressed, the next failure category that produces slow queries is stale statistics, which causes the optimizer to choose a scan where an index seek would be orders of magnitude faster.

Symptom: Query Plan Regression

The execution plan shows a table scan where an index seek ran yesterday. The optimizer has not changed; the data it relies on has. This is a statistics problem.

Diagnosing stale statistics

The SQL Server optimizer uses row count estimates and data distribution histograms to choose between index seeks and table scans. When those statistics are weeks out of date on a fast-growing table, the optimizer picks a scan where a seek would be dramatically faster. Run UPDATE STATISTICS table_name WITH FULLSCAN on any table that receives large batch loads. The WITH SAMPLE variant uses a row sampling percentage that can miss skewed distributions on large tables, producing statistics that look current but reflect an unrepresentative subset.

To detect indexes suffering from stale statistics or poor plan choices, query sys.dm_db_index_usage_stats:

SELECT OBJECT_NAME(object_id) AS tbl_name,
       index_id,
       user_seeks,
       user_scans,
       user_lookups
FROM sys.dm_db_index_usage_stats
WHERE database_id = DB_ID()
ORDER BY user_scans DESC;

Indexes with zero seeks but high scans are candidates for statistics updates or missing index evaluation.

PostgreSQL’s ANALYZE command and MySQL’s ANALYZE TABLE update planner statistics independently from VACUUM and OPTIMIZE TABLE respectively. On PostgreSQL, autovacuum runs ANALYZE automatically after a configurable percentage of rows change (controlled by autovacuum_analyze_scale_factor, default 0.1 or 10%), but that default is too high for large tables. A 200-million-row table would need 20 million row changes to trigger autovacuum’s ANALYZE pass, by which point the query plan may have been wrong for hours. Lowering autovacuum_analyze_scale_factor to 0.01 or using autovacuum_analyze_threshold with per-table overrides addresses this.

Updating statistics without disruption

On SQL Server, UPDATE STATISTICS generally does not block queries (it runs with NOLOCK semantics on data reads), though asynchronous statistics updates can cause brief schema lock contention during query compilation in high-workload scenarios. It does invalidate cached execution plans for the affected table: immediately after, SQL Server will recompile plans on next execution, which can briefly spike CPU on systems with many concurrent queries against the updated table. Run during low-traffic windows on heavily queried tables. The choice between FULLSCAN and SAMPLE depends on table size and distribution skew.

For tables in the small-to-medium range, FULLSCAN typically completes quickly enough to run during off-peak hours (the practical upper bound depends on hardware, but many teams use roughly 100M rows as a rule-of-thumb cutoff). For larger tables, a higher sample percentage (such as SAMPLE 20 PERCENT or SAMPLE 30 PERCENT) typically provides a better tradeoff between accuracy and duration than the default sample, though the optimal percentage varies by workload.

On PostgreSQL, ANALYZE reads a configurable sample (default default_statistics_target = 100, meaning 30,000 rows per column) and does not lock the table. Run it manually after any bulk load or partition swap.

On MySQL, ANALYZE TABLE is a lightweight operation on InnoDB that reads the index tree’s random dive samples. It is a fast operation: in MySQL 8.0+, ANALYZE TABLE uses online DDL semantics, avoiding the full read lock that earlier versions required. Capture EXPLAIN for representative queries before and after to confirm the planner picked up the new statistics.

OpManager Nexus automates detection of query plan regression on-prem through historical baseline comparison and anomaly flagging. The same capability extends to cloud-managed databases through its SaaS delivery, where slow query log analysis drills into queries exceeding a configurable execution-time threshold. The Automated Remediation section below covers how to wire that detection into corrective workflows.

Statistics failures are invisible until the query plan degrades. Storage failures are equally silent, until a disk fills and takes the database offline.

Symptom: Storage Pressure and Runaway Growth

A disk usage alert fires at 85% capacity. The database server has been running for months without anyone checking how fast the log files or tablespaces are growing. The root cause splits into two categories: unmanaged transaction log growth and missing archiving strategy. Both are maintenance failures that monitoring should have caught weeks earlier.

Transaction log and WAL management

SQL Server: A full recovery model database without regular transaction log backups will grow its log file until the disk fills, and a full data volume is an immediate production outage. To check current log space usage across all databases, run DBCC SQLPERF(LOGSPACE);, which returns log size, space used percentage, and status for every database. For a single database, query sys.databases for the log_reuse_wait_desc column, which tells you exactly why the log cannot be truncated (e.g., LOG_BACKUP, ACTIVE_TRANSACTION). Schedule log backups at an interval matching your Recovery Point Objective (RPO): for most OLTP workloads, intervals in the range of 5-30 minutes are commonly used, with tighter intervals for high-transaction systems, though the right frequency is workload-specific.

DBCC SHRINKFILE on the log file is a last resort for reclaiming space after an unexpected log growth event. The reason it is a last resort, rather than a routine cleanup tool, is the side effect on Virtual Log Files (VLFs), the internal segments SQL Server divides the transaction log into. Each shrink-then-regrow cycle adds a new VLF, so a log that has been shrunk repeatedly ends up fragmented into many small VLFs instead of a few large ones. That fragmentation degrades sequential log write throughput and increases recovery time. The fix is to address the root cause (missing log backups, long-running transactions) rather than shrinking on a schedule.

PostgreSQL: WAL (Write-Ahead Log) management serves the same function as SQL Server’s transaction log. The archive_mode and archive_command settings control whether completed WAL segments are shipped to archive storage. Without archiving enabled, WAL segments accumulate in pg_wal/ until disk fills. The wal_keep_size parameter (PostgreSQL 13+, replacing wal_keep_segments) sets a floor for retained WAL data, but does not cap growth. For production systems, configure continuous archiving with archive_mode = on and point archive_command to your backup infrastructure (pgBackRest, Barman, or cloud-native equivalents).

To verify archiving is active and current: SELECT * FROM pg_stat_archiver; Check last_archived_wal timestamp and failed_count. A non-zero failed_count or a stale last_archived_time means WAL segments are accumulating. Also: SELECT count(*), pg_size_pretty(sum(size)) FROM pg_ls_waldir(); (PostgreSQL 10+) shows total WAL directory size.

MySQL: Binary logs (binlogs) serve replication and point-in-time recovery. Without rotation, they grow indefinitely. expire_logs_days (deprecated in MySQL 8.0.3) or binlog_expire_logs_seconds (MySQL 8.0+) controls automatic purge. Setting binlog_expire_logs_seconds = 604800 retains seven days of binary logs, which is sufficient for most replication topologies. Run PURGE BINARY LOGS BEFORE NOW() - INTERVAL 7 DAY for one-time cleanup.

Capacity forecasting with OpManager Nexus

Reacting to a disk alert at 85% leaves little room for planned action. OpManager Nexus’s AI/ML-based storage forecasting uses up to 14 days of history to predict when storage will hit 80%, 90%, and 100%, giving your team a “disk full in N days” signal once it has at least 3 days of data. Its adaptive thresholds learn baseline behavior so alerts fire on genuine anomalies rather than every batch job, and the Database Tab surfaces individual database size, data and log file utilization, and growth trends.

Note: OpManager Nexus’s own monitoring data retention (configured under Settings > General Settings > Database Maintenance) is independent of your production database storage. Defaults are 7, 30, and 365 days for detailed, hourly, and daily statistics.

Use OpManager Nexus’s forecast reports to verify your archiving cadence keeps pace with growth: if the forecast shows 80% capacity in 30 days but your archive job runs monthly, increase frequency or provision more storage.

Storage pressure is a passive failure that accumulates over time. Lock contention is an active failure: the maintenance operation meant to fix the database becomes the source of the incident.

Symptom: Lock Contention from Maintenance Operations

A spike in blocked sessions immediately after a scheduled maintenance run is direct evidence that the REBUILD or REORGANIZE collided with production traffic and created lock contention. The maintenance job is supposed to fix performance, but index REBUILDs running without ONLINE = ON during peak traffic or without a maintenance window hold locks that block concurrent queries, turning the fix into the incident.

Identifying maintenance-induced blocking

Correlating maintenance timing with OpManager Nexus’s Sessions Tab is how you distinguish maintenance-induced blocking from application-level contention. If blocked session counts spike within minutes of a maintenance window opening, the maintenance job is the cause. On SQL Server, check sys.dm_exec_requests for sessions with wait_type values starting with LCK_M_*, then look up the head-of-chain blocker and inspect its command column for ALTER INDEX or DBCC operations.

On PostgreSQL, pg_stat_activity shows Lock wait events with wait_event values like relation or transactionid. If the blocking PID is running REINDEX or VACUUM FULL, that is maintenance-induced contention. For cloud-managed instances where Sessions Tab access is unavailable, OpManager Nexus’s SaaS delivery surfaces lock contention and blocking session counts on its database performance dashboard for the same triage signal.

Online and resumable operations

The fix is operational: use online operations and schedule them outside peak traffic windows.

SQL Server: Use ALTER INDEX ... REBUILD WITH (ONLINE = ON, RESUMABLE = ON, MAX_DURATION = 60) as described in the I/O Degradation section. The duration is any positive integer in minutes; set it based on your maintenance window. REORGANIZE is always online and interruptible.

PostgreSQL: REINDEX INDEX CONCURRENTLY (introduced in the I/O Degradation section) avoids exclusive locks. VACUUM without FULL does not block reads or writes.

MySQL: Standard OPTIMIZE TABLE already runs as online DDL on MySQL 8.0+ (introduced in the I/O Degradation section). Reach for pt-online-schema-change when you need finer control over lock duration on very large tables, or when you want triggered shadow-copy semantics that OPTIMIZE TABLE does not offer.

The four symptom categories above all produce observable performance signals before they become outages. Corruption is different: it produces no signal until it surfaces as query failures or data loss.

Symptom: Silent Corruption and Integrity Failures

Because corruption produces no precursor wait events or latency drift, detection is a deliberate scheduled act, not an alert response. Regular integrity checks are the primary detection mechanism, supplemented by storage-level checksums, page verification, and reliable backups.

SQL Server: DBCC CHECKDB catches page corruption, allocation errors, and consistency violations.

-- Recommended production form: suppresses informational messages, shows only errors
DBCC CHECKDB('ProductionDB') WITH NO_INFOMSGS, ALL_ERRORMSGS;

For large databases where a full DBCC CHECKDB is too slow for a maintenance window, DBCC CHECKDB ... WITH PHYSICAL_ONLY checks page and record header integrity without logical consistency checks and completes significantly faster. Corruption surfaces in the SQL Server error log as messages Msg 823, 824, or 825. To proactively check for known corruption events, query the suspect pages table:

SELECT db_id, file_id, page_id, event_type, error_count, last_update_date
FROM msdb.dbo.suspect_pages
WHERE event_type IN (1, 2, 3);

Event_type 1 = 823/824 errors, 2 = bad checksum, 3 = torn page. A non-empty result requires immediate DBCC CHECKDB and restore planning.

Running DBCC CHECKDB as frequently as your maintenance windows allow is the safe path. Many experts recommend daily on all databases; if that is impractical, prioritize critical databases and shorten the interval on large ones using WITH PHYSICAL_ONLY.

PostgreSQL: The pg_amcheck utility (PostgreSQL 14+) verifies B-tree index integrity by checking that every heap tuple referenced by an index entry actually exists and that index entries are in the correct sort order. The default invocation is fast enough for routine scheduled checks and catches most corruption:

pg_amcheck mydb

After an unexpected crash, storage event, or replication failure, run the thorough variant on critical tables:

pg_amcheck --heapallindexed --parent-check mydb

--heapallindexed performs a deeper check that every heap tuple has a corresponding index entry; --parent-check verifies cross-level B-tree invariants. Both flags increase runtime substantially, so reserve them for incident response or post-event verification rather than the routine schedule.

MySQL: mysqlcheck provides table-level integrity verification:

mysqlcheck --check --all-databases -u root -p

For individual tables, CHECK TABLE table_name within the MySQL client performs the same operation. InnoDB tables benefit from CHECK TABLE ... FOR UPGRADE after major version upgrades to verify storage format compatibility.

Running these checks manually is the safety net. The next section shows how to automate the response so the platform acts before the on-call engineer logs in.

From Alert to Fix: Automated Remediation Across Engines

When the alert fires at 3 AM, having the platform execute the remediation automatically matters far more than knowing the fix. OpManager Nexus’s IT Workflow Automation triggers a custom monitoring script when an alert threshold is breached: the script queries the symptom’s diagnostic surface (fragmentation, dead tuples, log space), evaluates severity, and runs the remediation.

SQL Server: wiring remediation into OpManager Nexus

OpManager Nexus accepts PowerShell or shell scripts as custom monitors (Custom Script Monitors require build 12.7 or later). The integration pattern matches the PostgreSQL and MySQL examples below: query sys.dm_db_index_physical_stats for fragmentation, branch on the threshold, issue ALTER INDEX REORGANIZE or REBUILD WITH (ONLINE = ON) accordingly, and emit one log line per action so the run shows up in the monitor’s history. Run the script under a service account with at least db_ddladmin on the target database; for SQL authentication or cross-domain setups, pull credentials from a secrets store rather than embedding them.

PostgreSQL and MySQL shell automation

For PostgreSQL, a cron-driven shell script can query pg_stat_user_tables for bloated tables and trigger remediation:

#!/usr/bin/env bash
# PostgreSQL automated vacuum/reindex for tables exceeding dead tuple threshold.
# Credentials sourced from ~/.pgpass (chmod 600); export PGPASSFILE if non-default.
PGHOST="localhost"
PGPORT="5432"
PGDATABASE="app_prod"
PGUSER="maintenance_user"
export PGPASSFILE="${PGPASSFILE:-$HOME/.pgpass}"

DEAD_THRESHOLD=15
BLOAT_THRESHOLD=30

# VACUUM tables with high dead tuple ratio
psql -h "$PGHOST" -p "$PGPORT" -U "$PGUSER" -d "$PGDATABASE" -t -A -F'|' -c "
  SELECT schemaname, relname, round(n_dead_tup::numeric / NULLIF(n_live_tup + n_dead_tup, 0) * 100, 2)
  FROM pg_stat_user_tables
  WHERE n_live_tup > 10000
    AND round(n_dead_tup::numeric / NULLIF(n_live_tup + n_dead_tup, 0) * 100, 2) > $DEAD_THRESHOLD
" | while IFS='|' read -r schema table dead_pct; do
  echo "$(date '+%Y-%m-%d %H:%M:%S') | VACUUM ANALYZE ${schema}.${table} | dead_pct=${dead_pct}%"
  psql -h "$PGHOST" -p "$PGPORT" -U "$PGUSER" -d "$PGDATABASE" -c "VACUUM ANALYZE ${schema}.${table};"
done

For MySQL, a similar approach queries information_schema.TABLES and triggers OPTIMIZE TABLE. Use a MySQL option file instead of embedding credentials in the script (create ~/.my.cnf with [client] credentials and restrict permissions to 600):

#!/usr/bin/env bash
# MySQL automated optimize for InnoDB tables exceeding fragmentation threshold
MYSQL_HOST="localhost"
MYSQL_DB="app_prod"

FRAG_THRESHOLD=20

mysql --defaults-extra-file="$HOME/.my.cnf" -h "$MYSQL_HOST" -N -B -e "
  SELECT table_name, round(data_free / (data_length + index_length + data_free) * 100, 2) AS frag_pct
  FROM information_schema.TABLES
  WHERE table_schema = '${MYSQL_DB}'
    AND engine = 'InnoDB'
    AND data_free > 0
    AND round(data_free / (data_length + index_length + data_free) * 100, 2) > ${FRAG_THRESHOLD}
" | while read -r table frag_pct; do
  echo "$(date '+%Y-%m-%d %H:%M:%S') | OPTIMIZE TABLE ${table} | frag_pct=${frag_pct}%"
  mysql --defaults-extra-file="$HOME/.my.cnf" -h "$MYSQL_HOST" "$MYSQL_DB" -e "OPTIMIZE TABLE ${table};"
done

Schedule either script via cron (e.g., 0 3 * * * /opt/scripts/pg_maintenance.sh >> /var/log/db_maintenance.log 2>&1) and monitor the log output through OpManager Nexus’s custom monitor integration.

Cloud-managed database automation

For databases running on Amazon RDS, Aurora, or Azure SQL, OpManager Nexus’s SaaS delivery provides the cloud-side counterpart of the PowerShell and shell automation patterns above. Its IT Automation module triggers corrective actions from threshold breaches and anomaly detections, and AI-powered baselines replace the manual threshold tuning that self-managed instances require. For RDS specifically, service actions like start, stop, and reboot with failover are surfaced directly. Engine-specific monitor setup for SQL Server, PostgreSQL, and MySQL is documented separately. Threshold profiles let you apply equivalent alert configurations across dev, staging, and production monitors, so a query that fragments an index under realistic staging load surfaces in slow query detection before it reaches production scale.

Maintenance Health Scorecard: Assessing Your Current Posture

Instead of running through the diagnostic queries from scratch, use this scorecard to assess your maintenance posture. Each item references the diagnostic approach covered in its corresponding section above.

I/O health (see: I/O Degradation section)

  • [ ] SQL Server: Run the sys.dm_db_index_physical_stats query (filter the results at 30% fragmentation). Count of indexes returned: ___
  • [ ] PostgreSQL: Run the pg_stat_user_tables dead tuple query. Tables with dead_pct above 10-20% are candidates for immediate attention: ___
  • [ ] MySQL: Run the information_schema.TABLES fragmentation query. Tables with frag_pct above 20%: ___

Statistics freshness (see: Query Plan Regression section)

  • [ ] SQL Server: Check sys.dm_db_index_usage_stats for indexes with zero seeks but high scans (plan regression or poorly matched index)
  • [ ] PostgreSQL: Verify autovacuum_analyze_scale_factor is set below 0.1 for tables above 100 million rows
  • [ ] MySQL: Run ANALYZE TABLE on your top 10 tables by write volume; capture EXPLAIN output for representative queries before and after to confirm planner statistics changed as expected

Storage trajectory (see: Storage Pressure section)

  • [ ] OpManager Nexus forecast report confirms sufficient capacity runway before any threshold crossing: Yes / No
  • [ ] Transaction log backup job (SQL Server) or WAL archiving (PostgreSQL) is confirmed running and last backup verified: Yes / No
  • [ ] Binary log rotation (MySQL) is configured with binlog_expire_logs_seconds set to an explicit value: Yes / No

Integrity baseline (see: Silent Corruption section)

  • [ ] SQL Server: DBCC CHECKDB last run date on critical databases: ___
  • [ ] PostgreSQL: pg_amcheck last run date (or equivalent manual check): ___
  • [ ] MySQL: mysqlcheck --check last run date: ___

Automation coverage (see: Automated Remediation section)

  • [ ] At least one automated remediation script is deployed, scheduled, and confirmed to be producing output logs: Yes / No
  • [ ] OpManager Nexus alert thresholds are configured and tested for key database health metrics (BCHR, disk utilization, blocked sessions): Yes / No
  • [ ] Maintenance windows are scheduled based on monitoring signals, not calendar dates: Yes / No

Cross-reference those results against OpManager Nexus’s slow query and session data (on-prem Performance Tab or SaaS Database Metrics dashboard). If a table in the top results by size also appears as a source of slow query detections, that is your highest-priority maintenance target.

Stop juggling AI SDKs in PHP — meet Prisma

If you’ve ever integrated an AI provider into a PHP application, you know the drill. You pull in the OpenAI SDK. Then the client wants image generation, so you add StabilityAI — different SDK, different request format, different error handling. Then they want audio transcription — enter Deepgram, yet another integration. Before you know it, you’re maintaining three separate API integrations, each with their own quirks, response formats, and retry logic.

Prisma fixes this. One package. One API. 25+ providers. Text, image, audio, and video.

composer require aimeos/prisma

What is Prisma?

Prisma is a light-weight, MIT-licensed PHP package that provides a unified interface for working with AI providers across four media domains. No framework coupling. Just Guzzle under the hood, PHP 8.2+, and a clean fluent API.

Here’s the core idea — every provider works through the same interface:

use AimeosPrismaPrisma;

// Generate text with OpenAI
$text = Prisma::text()
    ->using('openai', ['api_key' => '...'])
    ->write('Summarize the benefits of renewable energy')
    ->text();

// Generate an image with StabilityAI
$image = Prisma::image()
    ->using('stabilityai', ['api_key' => '...'])
    ->imagine('a mountain landscape at sunset')
    ->binary();

// Transcribe audio with Deepgram
$transcript = Prisma::audio()
    ->using('deepgram', ['api_key' => '...'])
    ->transcribe($audioFile)
    ->text();

// Describe a video with Gemini
$description = Prisma::video()
    ->using('gemini', ['api_key' => '...'])
    ->describe($videoFile)
    ->text();

Same pattern everywhere: Prisma::{domain}()->using(provider, config)->{method}(). Switch providers by changing a single string. Your application code stays the same.

Why this matters in practice

Imagine you’re building a product listing tool. You need to:

  1. Generate product descriptions from images
  2. Extract structured data (name, price, category) from the descriptions
  3. Generate marketing images for missing

Without Prisma, that’s three different SDK integrations. With Prisma:

use AimeosPrismaPrisma;
use AimeosPrismaSchemaSchema;

// 1. Describe a product image
$description = Prisma::image()
    ->using('openai', ['api_key' => '...'])
    ->describe($productPhoto)
    ->text();

// 2. Extract structured data
$schema = Schema::for('product', [
    'name' => Schema::string()->required(),
    'price' => Schema::number(),
    'category' => Schema::string()->enum(['electronics', 'clothing', 'food', 'other']),
]);

$product = Prisma::text()
    ->using('gemini', ['api_key' => '...'])
    ->structured("Extract product info from: {$description}", $schema)
    ->structured();
// ['name' => 'Wireless Headphones', 'price' => 79.99, 'category' => 'electronics']

// 3. Generate a product image
$image = Prisma::image()
    ->using('stabilityai', ['api_key' => '...'])
    ->imagine("Professional illustration of {$product['name']}")
    ->binary();

Three providers, three media types, one consistent API. And if tomorrow you want to swap Gemini for Anthropic, you change one line.

You can also check provider capabilities at runtime:

$provider = Prisma::image()->using('clipdrop', ['api_key' => '...']);

if ($provider->has('upscale')) {
    $image = $provider->upscale($lowResImage)->binary();
}

// Or throw if the capability is missing
$provider->ensure('upscale'); // throws NotImplementedException if not supported

What’s new in 0.4

Version 0.4 is a major release that adds text generation, structured output, tool calling, and a lot more. Here’s what landed.

Text generation across 14 providers

The write() method brings text generation to Prisma with support for OpenAI, Anthropic, Gemini, Bedrock, Mistral, Groq, Cohere, Deepseek, Alibaba, xAI, Perplexity, OpenRouter, Ollama, and Deepseek. All multimodal — pass images, audio, or documents alongside your prompt:

use AimeosPrismaBaseFile;

$response = Prisma::text()
    ->using('anthropic', ['api_key' => '...'])
    ->withSystemPrompt('You are a helpful assistant')
    ->write('Describe this image', [File::from('photo.jpg')]);

echo $response->text();

Structured output

Get typed JSON responses from LLMs using a fluent Schema builder. Prisma uses each provider’s native structured output API — no prompt engineering hacks:

use AimeosPrismaSchemaSchema;

$schema = Schema::for('event', [
    'title' => Schema::string()->required(),
    'date' => Schema::string()->format('date')->required(),
    'attendees' => Schema::array()->items(Schema::string()),
    'location' => Schema::object([
        'city' => Schema::string()->required(),
        'country' => Schema::string(),
    ]),
]);

$response = Prisma::text()
    ->using('openai', ['api_key' => '...'])
    ->structured('Parse: Team meetup on June 15 in Berlin with Alice and Bob', $schema);

$event = $response->structured();
// [
//     'title' => 'Team meetup',
//     'date' => '2026-06-15',
//     'attendees' => ['Alice', 'Bob'],
//     'location' => ['city' => 'Berlin', 'country' => 'Germany'],
// ]

The Schema builder supports strings, integers, numbers, booleans, arrays, objects, enums (including PHP BackedEnum), nested objects, required(), nullable(), min()/max(), regex pattern(), and more. You can also pass raw JSON Schema arrays via Schema::fromArray().

Tool calling with auto-execution

This is where things get interesting. Prisma supports full agentic tool calling with an automatic execution loop. You define tools, the model calls them, Prisma executes the handlers and feeds results back — all automatically:

use AimeosPrismaTools;
use AimeosPrismaSchemaSchema;

$searchTool = Tools::make(
    'search_products',
    'Search the product database',
    Schema::for('search', [
        'query' => Schema::string()->description('Search query')->required(),
        'limit' => Schema::integer()->description('Max results')->min(1)->max(50),
    ]),
    function(array $args): string {
        $results = ProductSearch::query($args['query'], $args['limit'] ?? 10);
        return json_encode($results);
    }
);

$response = Prisma::text()
    ->using('openai', ['api_key' => '...'])
    ->withTools([$searchTool])
    ->withMaxSteps(5)
    ->write('Find me the top 3 wireless headphones under $100');

echo $response->text();
// The model searched, got results, and wrote a summary

You can inspect what happened during the tool loop:

foreach ($response->steps() as $step) {
    echo $step->name();      // 'search_products'
    echo $step->arguments(); // ['query' => 'wireless headphones', 'limit' => 3]
    echo $step->result();    // '[ ... search results ... ]'
}

Tools also support:

  • Per-tool call limits: Tools::make(...)->max(3) — the tool can only be called 3 times
  • Custom error handlers: ->failed(fn($e, $args) => 'Fallback message') — catch exceptions gracefully
  • Concurrent execution: ->concurrent() — tools run in parallel via pcntl_fork
  • Decorators: wrap tools with logging, caching, or any custom behavior
  • Tool choice: ->withToolChoice(Provider::REQ) to force tool use

Provider tools

Some providers offer built-in server-side tools like web search and code execution. Prisma normalizes these too:

use AimeosPrismaTools;

$response = Prisma::text()
    ->using('anthropic', ['api_key' => '...'])
    ->withTools([
        Tools::provider('web_search'),
        Tools::provider('code_execution'),
    ])
    ->write('Search for the latest PHP version and verify it');

Available provider tools include web_search, code_execution, file_search, web_fetch, image_generation, and document_library — each mapped to the providers that support them. You can mix custom and provider tools in the same request.

Framework tool adapters

Already have tools built for Laravel AI or Symfony? Reuse them directly:

// Laravel AI / Prism tools
$tool = Tools::laravel(new MyLaravelTool());

// Symfony #[AsTool] classes
$tool = Tools::symfony(MySymfonyTool::class);

Thinking budgets

Enable extended reasoning for models that support it. Prisma automatically maps token counts to each provider’s native format:

$response = Prisma::text()
    ->using('anthropic', ['api_key' => '...'])
    ->withThinkingBudget(5000)
    ->withMaxTokens(4096)
    ->write('Solve this step by step: ...');

// Access the model's reasoning
$thinking = $response->meta()['thinking'] ?? null;

Citations

Normalized citation objects across providers that support them (Anthropic, OpenAI, Gemini, Perplexity, xAI):

foreach ($response->citations() as $citation) {
    $citation->title();  // source title
    $citation->url();    // source URL
    $citation->text();   // output text that cites this source
    $citation->source(); // verbatim quote from the source
}

Rate limits and retry handling

// Automatic retry with exponential backoff
$response = Prisma::text()
    ->using('openai', ['api_key' => '...'])
    ->withClientRetry(3, fn($attempt, $resp) => 100 * pow(2, $attempt))
    ->write('...');

// Inspect rate limit headers
$limit = $response->rateLimit();
$limit->remaining();  // requests left
$limit->retryAfter(); // seconds until reset

Provider coverage

Here’s what’s supported for text providers in 0.4:

Provider structured translate write citations custom tools provider tools thinking budget
Alibaba yes yes – yes yes –
Anthropic yes yes yes yes yes yes
Bedrock yes yes – yes yes
Cohere yes yes – yes –
Deepseek yes yes – yes –
DeepL yes
Gemini yes yes yes yes yes yes
Google yes
Groq yes yes – yes –
Mistral yes yes – yes yes –
Ollama beta beta – yes –
OpenAI yes yes yes yes yes yes
Openrouter yes yes – yes yes –
Perplexity beta beta yes yes –
xAI beta beta yes yes yes yes

And that’s just text. Prisma also covers 9 audio providers (speak, transcribe, demix, denoise, revoice, describe), 14 image providers (imagine, inpaint, upscale, vectorize, background, erase, and more), and video description via Gemini.

Getting started

composer require aimeos/prisma

Minimal example:

<?php

use AimeosPrismaPrisma;

// Text
echo Prisma::text()
    ->using('openai', ['api_key' => getenv('OPENAI_API_KEY')])
    ->write('What makes PHP great?')
    ->text();

// Image
$binary = Prisma::image()
    ->using('openai', ['api_key' => getenv('OPENAI_API_KEY')])
    ->imagine('a PHP elephant wearing sunglasses')
    ->binary();

file_put_contents('elephant.png', $binary);

No service providers, no config files, no framework dependencies. Just require and use.

Prisma is MIT-licensed and open source. Check it out:

If you’ve been looking for a unified way to work with AI providers in PHP — especially beyond just text — give it a try. Feedback, issues, and stars are all welcome.

In case you like Prisma, leave a star in the Github repo 🙂

Google Quietly Changed What “Apps” Mean at I/O 2026

Last year, I thought Google was building better AI tools. After watching the event from Google I/O 2024 to 2026, I don’t think that anymore. I think Google is slowly redefining what an “app” even is.

And the shift is much bigger than Gemini.

For years, software followed a predictable structure.

You open an app, navigate interfaces, click buttons, fill forms, search menus, and manually orchestrate workflows yourself. AI usually sat on top of that experience as an enhancement layer. A chatbot in the corner. An autocomplete feature. A smarter search bar.

But across the last three Google I/Os, something quietly changed.

The interface itself started disappearing.

The Shift Started Earlier Than Most People Noticed

Back in Google I/O 2024, the focus still looked heavily model-centric.

Most headlines revolved around:

  • bigger context windows
  • multimodality
  • reasoning improvements
  • Gemini integrations everywhere

At first glance, it felt like the same race the entire industry was already running:
better models, faster outputs, larger benchmarks.

But hidden inside many of those demos was a different idea entirely.

Not:

“How do we improve apps with AI?”

But:

“What if the app is no longer the center of the experience?”

That distinction matters more than it initially sounds.

A lot more.

The First Clue Was Ask Photos

One of the most overlooked demos from I/O 2024 was actually Google Photos.

Not because of image generation.
Not because of editing.

Because of how interaction itself changed.

Instead of navigating folders, albums, timestamps, and filters manually, users could simply ask:

“When did Lucia learn to swim?”

Gemini would:

  • analyze images
  • identify progression over time
  • connect contexts
  • summarize memories
  • return a narrative answer

Traditional software required users to adapt to interface structures.

This interaction reversed the relationship completely.

The system adapts to human intent instead.

That’s a fundamentally different computing model.

Search Was Quietly Changing Too

Google Search evolved in a similar direction.

Throughout the keynotes, Google repeatedly emphasized that people were beginning to search differently:

  • longer queries
  • conversational prompts
  • multimodal inputs
  • exploratory reasoning

That may sound obvious now, but it fundamentally changes the architecture of interaction design.

Classic search focused on:

  • keyword retrieval
  • indexed ranking
  • explicit query matching

AI-native search focuses on:

  • intent interpretation
  • contextual understanding
  • synthesized responses
  • adaptive interaction

The UI becomes secondary.

The conversation becomes primary.

Then Google Started Removing Workflow Friction Entirely

By I/O 2025, the transition became much harder to ignore.

Especially with:

  • Project Astra
  • Project Mariner
  • Agent Mode
  • Personal Context
  • Gemini Live

At this point, Google wasn’t just augmenting interfaces anymore.

It was experimenting with replacing manual orchestration itself.

And that’s where things became genuinely interesting.

Agent Mode Is Not Just “AI Automation”

The apartment-hunting demo from I/O 2025 looked simple on the surface.

Gemini:

  • searched listings
  • applied filters
  • checked requirements
  • scheduled tours
  • continued monitoring results in the background

But the important part wasn’t the demo itself.

It was the interaction model behind it.

The user no longer operated the software step-by-step.

Instead, they defined:

  • goals
  • constraints
  • preferences
  • outcomes

The system handled execution.

That’s not traditional software interaction anymore.

That’s delegated intent.

And honestly, I think that phrase explains almost the entire direction of modern AI products right now.

We’re Moving From “Using Software” to “Directing Systems”

This became the biggest pattern I noticed across all three I/O events.

The old software model looked like this:

users execute workflows manually

The emerging model increasingly looks like this:

users describe objectives

The software layer doesn’t disappear entirely.

It just becomes abstracted away.

In many ways, this feels similar to earlier shifts in computing history:

  • command line → GUI
  • desktop → mobile
  • navigation → feed-based computing

Now we may be entering:

interface → intent

And Google seems fully committed to accelerating that transition.

Infinite Scaler Accidentally Revealed the Future

Oddly enough, one of the clearest examples came from a demo that looked almost unserious.

Infinite Scaler at Google I/O 2026.

A browser-based multiplayer climbing game where players generated live game worlds using prompts.

At first, it looked like a fun crowd experiment.

But underneath the spectacle was something much more important.

Players weren’t selecting predefined assets or environments anymore.

They were generating worlds dynamically through language.

The game itself became:

  • partially procedural
  • partially collaborative
  • partially generative
  • partially conversational

That’s a completely different relationship between humans and software systems.

And I honestly think this demo was far more important than most people realized.

The Interface Is Becoming Adaptive Instead of Static

Traditional apps are designed around fixed structures:

  • menus
  • screens
  • navigation trees
  • predefined workflows

AI-native systems behave differently.

The interaction layer becomes:

  • contextual
  • reactive
  • generative
  • personalized
  • stateful

NotebookLM demonstrated this surprisingly early.

Users could upload huge amounts of material and receive dynamically generated:

  • summaries
  • conversations
  • quizzes
  • audio discussions
  • contextual explanations

Not fixed outputs.

Adaptive outputs.

The experience changes depending on:

  • context
  • memory
  • history
  • user behavior
  • modality
  • intent

That feels much closer to an operating layer than a traditional app.

Personal Context Changes the Entire Equation

I think the most important long-term concept Google introduced wasn’t multimodality.

It was Personal Context.

Because once AI systems can securely access:

  • emails
  • documents
  • preferences
  • schedules
  • workflows
  • browsing behavior
  • writing patterns

the interface no longer needs constant explicit instruction.

The system already understands situational context.

That’s incredibly powerful.

And honestly, slightly uncomfortable too.

Google’s personalized Smart Reply demo showed Gemini analyzing:

  • past emails
  • Drive notes
  • itineraries
  • tone preferences
  • vocabulary patterns

to generate responses that sounded personally authentic.

This goes far beyond autocomplete.

The software is beginning to model behavior itself.

Apps Are Starting to Behave More Like Collaborators

One thing became increasingly clear across these I/O presentations:

Google wants software to feel less like tools
and more like active participants.

Not assistants waiting passively for commands.

Systems continuously reasoning in the background.

That changes:

  • UX design
  • frontend architecture
  • state management
  • workflow assumptions
  • interaction patterns
  • even product thinking itself

Because if AI handles orchestration dynamically, many traditional interface decisions suddenly become less important.

Why design deeply nested navigation systems if users can simply express intent directly?

That question alone could reshape huge parts of frontend development over the next few years.

This Creates New Problems Too

I don’t think this transition will be smooth.

Actually, I think it introduces difficult questions the industry still hasn’t solved:

  • trust
  • transparency
  • hallucinations
  • over-delegation
  • permission boundaries
  • cognitive dependency
  • interface predictability
  • behavioral modeling

The more invisible software becomes,
the more important reliability becomes.

A broken button is annoying.

A misaligned autonomous workflow is something else entirely.

And I think the industry still underestimates how difficult that challenge is going to be.

Developers May Need to Rethink Product Design Entirely

A lot of current frontend development assumes:

  • deterministic flows
  • predictable navigation
  • explicit user actions

But AI-native systems are probabilistic.

The interface may no longer be fully predefined.

Instead of designing:

  • screens
  • menus
  • static pathways

developers may increasingly design:

  • constraints
  • orchestration layers
  • memory systems
  • context boundaries
  • fallback behaviors
  • guardrails

That’s a major conceptual shift.

And honestly, I don’t think we fully understand its implications yet.

Google I/O 2026 Didn’t Feel Like a Product Event

It felt like Google slowly exposing a new computing model.

One where:

  • software becomes conversational
  • interfaces become adaptive
  • workflows become delegated
  • apps become increasingly invisible

The strange part is that this transition isn’t happening through one massive breakthrough.

It’s happening gradually.

One feature at a time.
One workflow at a time.
One interaction at a time.

And I think that’s why many people still see these announcements as isolated AI demos.

But viewed together across multiple years, the pattern becomes difficult to ignore.

We may be watching the early stages of the post-app era.

The Infrastructure Team Is the Real Single Point of Failure

Rack2Cloud - Authority Layer Series

Rack2Cloud - Authority Layer Series

Every serious infrastructure investment goes into redundant hardware, distributed systems, and multi-region failover. Almost none goes into the one dependency that sits above all of it — the small number of engineers whose departure, unavailability, or burnout makes the environment unrecoverable.

The infrastructure bus factor is the organizational single point of failure that no architecture review catches. It doesn’t appear in the system diagram. It doesn’t show up on a monitoring dashboard. It lives in a person. In most organizations, the real infrastructure control plane is not Terraform, not Kubernetes, not vCenter. It is the senior engineer carrying operational context in their head — the undocumented governance layer that fills every gap the formal systems leave.

That is not a staffing problem. It is an architectural one.

infrastructure bus factor — human control plane sitting above system diagram with operational authority artifacts concentrated in individuals

The Bus Factor No One Models

The infrastructure bus factor is the number of engineers who would need to be simultaneously unavailable before the environment becomes unrecoverable. The question isn’t how many people are on the team. It’s how many of them carry operational authority artifacts that exist nowhere else.

Operational authority artifacts are not documentation gaps. They are the execution authority, recovery judgment, exception context, and institutional pattern recognition that accumulate in specific engineers over time — and that the formal systems were never designed to hold. Break-glass credentials held in one person’s vault. Recovery sequencing judgment that exists only in the engineer who has actually invoked DR. Vendor escalation relationships that are personal, not organizational. IaC exception context that explains why a specific drift state was accepted and what would break if it were reverted.

Most enterprise infrastructure teams have a bus factor of one. Not because they are understaffed, but because operational authority was never treated as an architectural dependency that required the same redundancy discipline applied to hardware.

The Operational Memory Gap: the distance between what the infrastructure documentation describes and what the people who actually operate the environment know — not as information, but as authority.

Why Redundancy Stops at the Human Layer

infrastructure redundancy stops at human layer — fault tolerance increases downward into hardware, decreases upward into operations

Organizations build HA clusters, multi-region failover, replicated storage, redundant networking, and distributed control planes. But the infrastructure stack becomes progressively more fault tolerant moving downward into hardware and software — and progressively less fault tolerant moving upward into operations and governance.

Most enterprises eliminated hardware single points of failure years ago. Many still operate with human single points of failure embedded directly in the recovery layer — the layer that is supposed to be invoked when everything else has failed.

The fault tolerance investment ends exactly where operational authority begins. Hardware redundancy was an architectural decision. Operational authority distribution was never made a decision at all — it accumulated by default.

⚠ The architectural contradiction: Organizations design redundancy into every layer of infrastructure hardware and software. They never design redundancy into operational authority. The most fault-tolerant layer in most enterprises is the storage fabric. The least fault-tolerant layer is the team member who knows how to recover it.

How the Infrastructure Bus Factor Gets Built

The bus factor doesn’t arrive by design. It accumulates through normal operational patterns of a mature infrastructure environment.

The senior engineer who resolves incidents faster than anyone else creates a gravity well. The on-call rotation that everyone nominally participates in gradually becomes one person’s responsibility. Console changes get made during incidents and never land in code. Runbooks don’t get written because the person who owns the procedure is always reachable.

The most significant pattern is The Engineer Who Became the Exception Layer. Systems grow complex. Governance processes slow change velocity. One senior engineer becomes the fast path around operational friction. The organization optimizes around them operationally. All undocumented exceptions begin routing through them. They become human middleware: the execution layer filling the gap between what formal systems enforce and what production operations actually requires.

Mature environments rarely centralize authority intentionally. They centralize it operationally — around the person who can bypass friction fastest.

What the Infrastructure Bus Factor Actually Controls

operational authority artifacts — break-glass credentials recovery sequencing vendor escalation IaC exception context concentrated in single engineers

Authority Artifact Single-Person Concentration Consequence of Absence
Break-glass credentials Held in one engineer’s personal vault Environment unrecoverable during IAM/IdP failure
Undocumented network topology Lives in one person’s mental model Incident diagnosis requires their presence
Vendor escalation paths Personal relationships, not organizational P1 escalation stalls without them
IaC exception context One person knows why drift was accepted Revert risk unknown — remediation blocked
Recovery sequencing authority One person knows the dependency restart order DR invocation produces cascading failures
Certificate and secrets rotation One person owns the schedule and method Expiry events undetected or mishandled
Incident judgment authority One person calibrates alert signal vs. noise False escalations or missed real signals
DR invocation procedure One person has executed it and knows what the runbook omits Documented procedure fails at the first undocumented step

The most critical row is recovery sequencing authority. The DR runbook says “restore services.” One engineer knows the actual dependency order required to avoid a continuity cascade on restart. That judgment — built from direct experience — is not a procedure. It is pattern recognition that cannot be transferred through documentation alone.

This is Recovery Authority Concentration: the degree to which recovery execution depends on the presence of specific individuals rather than documented, system-enforced procedures.

The Human Control Plane

In most enterprise infrastructure environments, there is a third control plane layer that no architecture diagram includes: the informal layer of operational authority carried by the senior engineers who understand how the environment actually behaves.

This is the Human Control Plane — the undocumented governance layer that fills every gap the formal systems leave. It operates through informal authority, exception accumulation, and recovery concentration.

The Knowledge Authority Collapse is what happens when this informal control plane fails. A personnel change removes the informal governance layer that was doing real operational work. The formal systems remain intact. The documentation remains in place. But the actual recovery paths, exception contexts, and judgment calls the formal systems depended on are no longer accessible.

knowledge authority collapse — personnel change triggering infrastructure control plane failure when operational authority was concentrated in individuals

The authority trilogy:

  • Part 1 — Pipeline bypass: infrastructure state changes without passing through the mandatory execution path
  • Part 2 — Shadow control plane: console mutations accumulate as undocumented state outside the governance model
  • Part 3 — Human Control Plane: operational authority concentrates in individuals, making personnel availability a control plane dependency

Bus Factor Audit: Five Diagnostic Questions

  1. If your two most senior infrastructure engineers were simultaneously unavailable for 72 hours, which systems could not be recovered from an incident?
  2. Which recovery procedures exist only as tribal authority — documented in name but only executable by the engineer who wrote them?
  3. Which credentials exist in one engineer’s personal vault rather than a secrets management system with rotation policy?
  4. Which vendor escalation relationships are personal rather than organizational?
  5. Which IaC exceptions or console changes exist because one engineer made a judgment call that was never encoded into policy?

Diagnostic question: “If every runbook in your environment were executed by someone who has never met the engineer who wrote it, how many would fail at the first undocumented step?”

Reducing the Infrastructure Bus Factor Is an Architecture Problem

Documentation preserves procedures. It does not automatically preserve operational judgment under failure conditions. The goal is not comprehensive documentation. The goal is reducing human-exclusive authority — moving operational authority artifacts from people into systems.

Four architectural moves:

  • Automation reduces decision variance — fewer execution paths require human judgment in the first place
  • Pipelines reduce hidden execution paths — the fast path is the pipeline path, not the engineer path
  • Policy systems reduce memory dependencies — compliance enforced by code, not recalled by engineers
  • Reconciliation systems reduce exception entropy — drift detected and remediated by systems, not remembered by the person who introduced it

None of these moves eliminate the need for experienced engineers. They eliminate the condition where the environment is unrecoverable without specific ones.

Architect’s Verdict

The infrastructure bus factor is the failure mode every post-incident review finds and every capacity plan ignores. Organizations invest in redundant hardware, distributed systems, and failover architecture. They treat the team running it as a staffing concern rather than an architectural dependency.

The Human Control Plane accumulates by default in every mature infrastructure environment. It is not designed. It grows. By the time the Knowledge Authority Collapse is visible, a personnel event has already made it operational.

The infrastructure survives hardware failure because redundancy was designed into the system. It fails operationally because redundancy was never designed into authority.

Additional Resources

Originally published at rack2cloud.com