
🤔 The Problem
As a developer in Korea, I was spending way too much time every morning visiting:
- Korean tech blogs (Kakao, Toss, Woowa Brothers, Naver, Line)
- IT news sites (ZDNet Korea, IT Donga, Digital Times)
- International tech outlets
- YouTube tech channels
I wanted one place to read everything. So I built it.
🚀 Introducing 한눈IT (HanunIT)
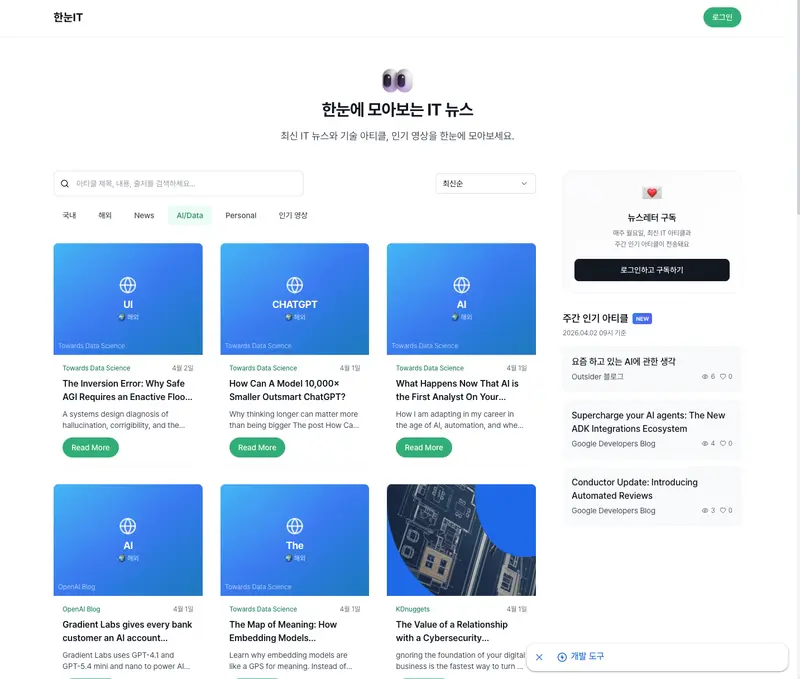
한눈IT means “IT at a glance” in Korean. It’s a content aggregation platform that collects, summarizes, and serves the latest IT articles and videos in a clean reading experience.
✨ Key Features
📰 Article Aggregation
Continuously collects articles from 30+ sources via RSS feeds. New content flows in throughout the day — no manual curation needed.
📝 AI-Powered Summaries
Every article comes with a concise summary. Scan dozens of articles in minutes and deep-dive only into what matters to you.
🌐 Translated Articles
International tech articles are auto-translated into Korean, bridging the language gap for Korean-speaking developers.
🎬 Tech Video Curation
Not just text — curated YouTube tech videos are collected alongside written articles. Switch between reading and watching depending on your mood.
💬 Community Features
Comment on articles, like your favorites, and join discussions with other developers.
📧 Newsletter
Subscribe to a weekly digest and get the best articles delivered to your inbox.
🛠️ Tech Stack
Here’s what’s under the hood:
| Layer | Tech |
|---|---|
| Framework | Next.js 15 (App Router, Turbopack) |
| Language | TypeScript |
| Database | Supabase (PostgreSQL + RLS) |
| Auth | Supabase Auth |
| State | TanStack Query + Zustand |
| Styling | Tailwind CSS + Shadcn UI |
| Deployment | Vercel |
| Analytics | Vercel Analytics |
📐 Architecture Highlights
A few technical decisions I’m happy with:
Server-side rendering with caching — Article pages use revalidate = 300 for ISR. API routes return s-maxage=300, stale-while-revalidate=600 headers. Fast initial loads without hitting the DB every time.
Parallel data fetching — Article detail pages fire multiple Supabase queries with Promise.allSettled instead of sequential awaits. Shaved ~40% off load times.
Smart client caching — TanStack Query with 5-minute stale time and 30-minute GC. Users navigating between pages almost never see a loading spinner.
Per-request deduplication — Used React.cache() for article fetches in server components, so generateMetadata and the page component share the same data without duplicate DB calls.
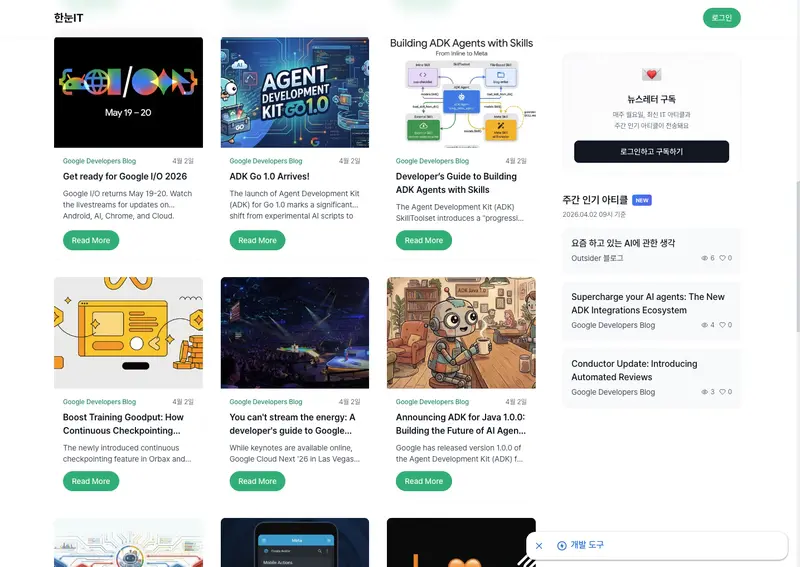
📸 Screenshots
🤷 What I Learned
- RSS feeds are messy — Every source has a slightly different format. Spent more time on parsing edge cases than I expected.
- Supabase RLS is powerful but tricky — Row Level Security policies need careful planning upfront. Debugging permission errors is not fun.
- Next.js 15 App Router is great — Server components + streaming + ISR is a solid combo for content-heavy sites.
🙏 Feedback Welcome
I’d love to hear:
- What IT sources would you want to see added?
- Any UX improvements you’d suggest?
- Would you use something like this for your local tech ecosystem?
Thanks for reading! Drop a comment or visit hanun-it.com to check it out.